aris
ARIS ⚔️ (Auto-Research-In-Sleep) — Lightweight Markdown-only skills for autonomous ML research: cross-model review loops, idea discovery, and experiment automation. No framework, no lock-in — works with Claude Code, Codex, OpenClaw, or any LLM agent.
Safety scan
A static text scan, not a guarantee. Select the badge to see what was scanned and every finding.
Check it deeper on your machine
It has changed since its scan on 11 Nov 2026.
As a Claude Code plugin, install it and then ask Claude Code:
/plugin marketplace add keithmackay/mackayi/plugin install scanskillsafety@mackayiDo a deep scan of https://github.com/wanshuiyin/auto-claude-code-research-in-sleep with scanskillsafety
Or from a terminal, clone it and run it:
git clone https://github.com/keithmackay/scanskillsafety-skill ~/.claude/skills/scanskillsafetynode ~/.claude/skills/scanskillsafety/cli.cjs --deep 'https://github.com/wanshuiyin/auto-claude-code-research-in-sleep'
It checks the exact commit: every file, its packages against OSV (api.osv.dev), how it compares with this page's scan (findsafeskills.com receives the repository's address), and, if you agree, Claude reading every file with your own Claude subscription. It never runs the code.
Badge for your README

Markdown
[](/listings/wanshuiyin--auto-claude-code-research-in-sleep)HTML
<a href="/listings/wanshuiyin--auto-claude-code-research-in-sleep"><img src="/api/listings/wanshuiyin--auto-claude-code-research-in-sleep/badge.svg" alt="findsafeskills safety rating" /></a>Install
Install instructions from the README
As written by the repo's author. findsafeskills has not verified these steps.
# 1. Install skills — project-local symlinks (recommended)
git clone https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep.git
bash Auto-claude-code-research-in-sleep/tools/install_aris.sh ~/your-project   # symlinks ARIS skills into <project>/.claude/skills/
# (prefer a global install instead? cp -r Auto-claude-code-research-in-sleep/skills/* ~/.claude/skills/)
# (don't need all 83? --list-groups / --groups X,Y / --skills X — see "Selective install" below)

# 1b. Update later (when upstream changes)
cd Auto-claude-code-research-in-sleep && git pull
bash tools/smart_update.sh --apply   # updates safe skills, flags your personal customizations
# (NEW upstream skills need confirmation — --add-new to accept all non-interactively)

# Optional Codex mirror managed project install
bash tools/install_aris_codex.sh ~/your-codex-project

# Managed Codex project update
cd Auto-claude-code-research-in-sleep && git pull
bash tools/install_aris_codex.sh ~/your-codex-project --reconcile

# Copied Codex installs only (not for projects installed by install_aris_codex.sh)
bash tools/smart_update_codex.sh --local ~/.codex/skills
bash tools/smart_update_codex.sh --local ~/.codex/skills --apply

# 2. Codex reviewer (review skills call GPT through it) — run from the directory you cloned into in step 1
npm install -g @openai/codex && codex login       # one-time ChatGPT login; the reviewer model comes from ~/.codex/config.toml
claude mcp add codex -s user -- python3 "$(pwd)/Auto-claude-code-research-in-sleep/mcp-servers/codex-exec/server.py"
# then restart Claude Code; `claude mcp list` must show:  codex: python3 …/codex-exec/server.py - ✔ Connected

# 2b. Already had ARIS before 2026-09-11? codex-cli 0.154 removed `codex mcp-server`, so the old registration is dead.
cd Auto-claude-code-research-in-sleep && git pull   # brings mcp-servers/codex-exec/ (git pull is enough; smart_update only syncs skills)
claude mcp remove codex -s user
claude mcp add codex -s user -- python3 "$(pwd)/mcp-servers/codex-exec/server.py"
# restart Claude Code, check `claude mcp list` as above. Skills need no change. Do it on codex 0.153 too — it works there and survives the update.
# Cursor / Trae / Antigravity / Copilot CLI: same "codex" key, command python3 + that path — see the adaptation guides in docs/.
# Installed by copying skills/ without a clone? Clone the repo anywhere and point at its server.py; the file is self-contained.

# 3. Use in Claude Code
claude
> /idea-discovery "your research direction"  # Workflow 1 — be specific! not "NLP" but "factorized gap in discrete diffusion LMs"
> /experiment-bridge                         # Workflow 1.5 — have a plan? implement + deploy + collect results
> /auto-review-loop "your paper topic or scope"  # Workflow 2: review → fix → re-review overnight
> /paper-writing "NARRATIVE_REPORT.md"       # Workflow 3: narrative → polished PDF
> /rebuttal "paper/ + reviews" — venue: ICML    # Workflow 4: parse reviews → draft rebuttal → follow-up
> /resubmit-pipeline "paper/" — venue: NeurIPS  # Workflow 5: port a polished paper to a new venue (text-only, no new experiments)
> /paper-talk "paper/" — venue: ICLR            # Workflow 6: paper → Beamer + PPTX talk + speaker notes + assurance audits
> /research-pipeline "your research direction"  # Full pipeline: Workflow 1 → 1.5 → 2 → 3 end-to-end
> /research-wiki init                           # 📚 Enable persistent research memory (one-time)
> /meta-optimize                                # Meta: analyze usage logs → propose skill improvements
> Don't need all 83 skills? See [Selective install](#install-skills) below for group/skill-level picks.
What was scanned
The files the safety scan read, as written by the repository's author and shown as plain text. Lines with a finding are marked.
.claude-plugin/marketplace.json · Manifest · 34 lines
View this file on GitHub (read at the repository's current version: the scan did not record which commit it read)
This file has changed since it was scanned, so this is not exactly the text that was scanned, and no line is marked. The findings are listed with the safety scan above.
- {
- "$schema": "https://json.schemastore.org/claude-code-marketplace.json",
- "name": "aris",
- "owner": {
- "name": "wanshuiyin",
- "url": "https://github.com/wanshuiyin"
- },
- "metadata": {
- "description": "ARIS — skill-based research workflow (literature review → idea → experiment → paper → rebuttal), installable as a plugin."
- },
- "plugins": [
- {
- "name": "aris",
- "source": "./",
- "description": "The ARIS skill set as a plugin — every mainline skill under skills/, plus /aris:setup, which registers the bundled Codex reviewer bridge (mcp-servers/codex-exec/) and points helper resolution at the plugin.",
- "author": {
- "name": "wanshuiyin",
- "url": "https://github.com/wanshuiyin"
- },
- "homepage": "https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep",
- "repository": "https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep",
- "license": "MIT",
- "category": "research",
- "keywords": [
- "research",
- "paper",
- "literature-review",
- "skills",
- "workflow",
- "claude-code"
- ]
- }
- ]
- }
README.md · README · 1,270 lines
View this file on GitHub (read at the repository's current version: the scan did not record which commit it read)
This file has changed since it was scanned, so this is not exactly the text that was scanned, and no line is marked. The findings are listed with the safety scan above.
- # Auto-claude-code-research-in-sleep (ARIS ⚔️🌙)
- <p align="center">
- <a href="https://huggingface.co/papers/2605.03042">
- <img src="docs/hf_daily_paper_1.svg" alt="Hugging Face Daily Paper · #1 Paper of the Day" width="360">
- </a>
- </p>
- [](#quick-start) · [](#how-to-run) · [](https://huggingface.co/papers/2605.03042) · [](https://wanshuiyin.github.io/Auto-claude-code-research-in-sleep/ARIS_INTRO.html) · [](docs/aris_intro_slides.pdf) · [](AGENT_GUIDE.md) · [](https://mp.weixin.qq.com/s/tDniVryVGjDkkkWl-5sTkQ) · [](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/stargazers) · [💬 Join Community](#community) · [](#citation)
- 🌱 *ARIS is a methodology, not a platform. What matters is the research workflow — take it wherever you go.*
- 💡 *Use ARIS as a skill-based workflow in [Claude Code](https://docs.anthropic.com/en/docs/claude-code) / [Codex CLI](skills/skills-codex/) / [Cursor](docs/CURSOR_ADAPTATION.md) / [Trae](docs/TRAE_ARIS_RUNBOOK_EN.md) / [Antigravity](docs/ANTIGRAVITY_ADAPTATION.md) / [GitHub Copilot CLI](docs/COPILOT_CLI_ADAPTATION.md) / [OpenClaw](docs/OPENCLAW_ADAPTATION.md) / [DeepSeek Harness](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/tree/dsh-aris#readme) — enjoy any way you like!*<br>*The executor drives, an independent model (Codex MCP by default) reviews. [Alternative model combinations](#alternative-model-combinations), including [ModelScope](docs/MODELSCOPE_GUIDE.md)-hosted models, need no Claude or OpenAI API.*
- 📦 *Those are the skills installed directly. Want it in one command? ARIS also ships as a standalone CLI and as plugins:* [](docs/ARIS-Code-README_EN.md) · [](#plugins) · [](#plugins) · [](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/tree/dsh-aris#readme)
- **🤝 SuperARIS — Your personal research agent with ARIS, powered by a team of agents.**
- Put ARIS workflows in the hands of a persistent team: your main agent coordinates, while engineering and writing run in parallel. Every member can read ARIS skills and project context on demand. Work directly with Codex on experiments and Gemini on ideas and writing, or choose an all-Codex team. The main agent follows up on deliverables; project files carry memory across sessions. Your existing MCP workers and independent reviewers stay in the loop.
- **[Homepage](https://wanshuiyin.github.io/SuperARIS/) · [GitHub](https://github.com/wanshuiyin/SuperARIS)**
- [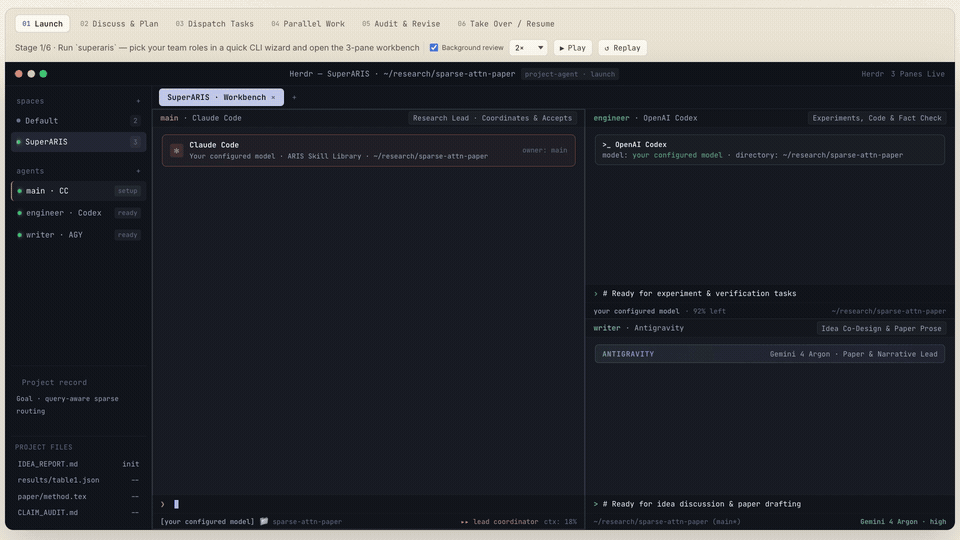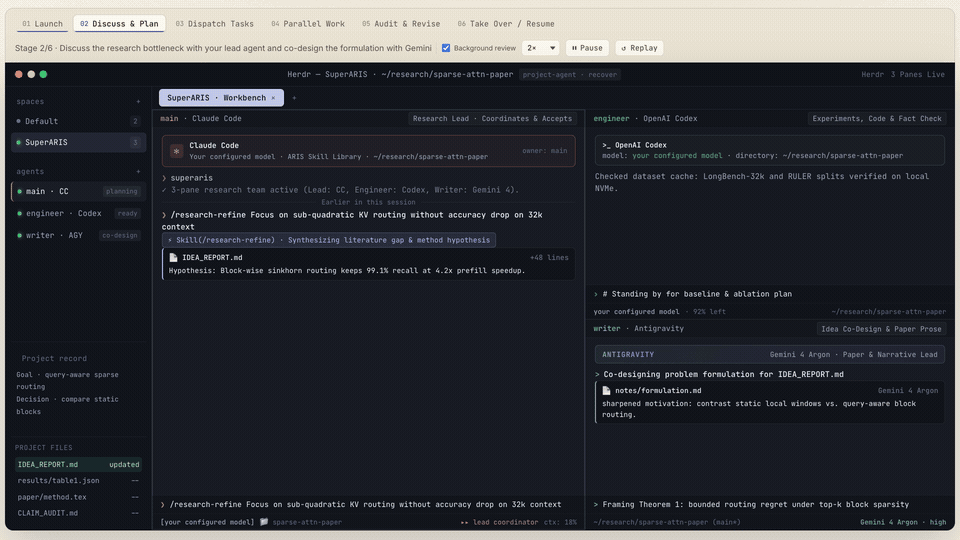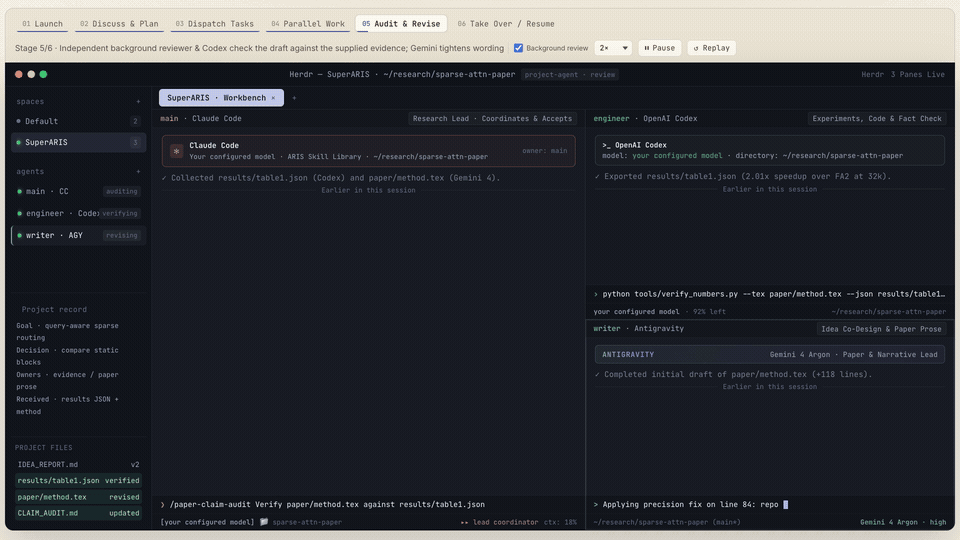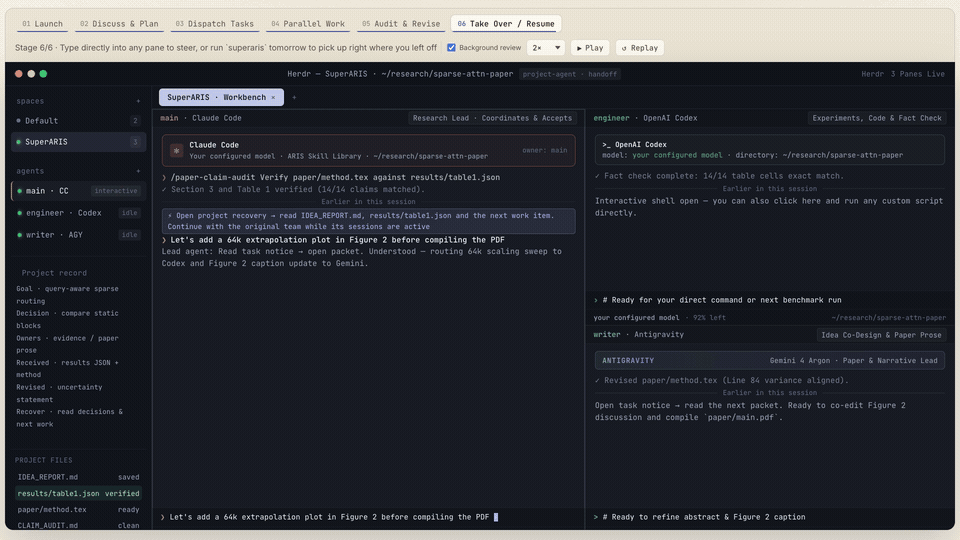](https://wanshuiyin.github.io/SuperARIS/media/demo-en.mp4)
- *Demo preview · click to watch the full 1080p video (~21 seconds).*
- ❗  **codex-cli 0.154.0 removed `codex mcp-server` — the entry point every ARIS reviewer call used. No impact on ARIS:** the `codex` MCP server is now ARIS's own bridge over `codex exec` (`mcp-servers/codex-exec/`), same tools, same results, all 82 skills unchanged, `ultra` and per-thread resume intact. One re-registration is all it takes — **[already installed? → Quick Start step 2b](#quick-start)** · **[new install → step 2](#quick-start)** · [what changed](#whats-new).
- **🧩 The ARIS family** — same method, other jobs. One line each; the details live in their own repos.
- [](https://github.com/wanshuiyin/ARIS-in-AI-Offer) — **EasyAIOffer**: 34 bilingual ML / LLM interview cheat sheets on [one page](https://wanshuiyin.github.io/ARIS-in-AI-Offer/) — derivations, from-scratch PyTorch, 25 questions each. 希望大家秋招轻松一点 🌱
- [](https://github.com/wanshuiyin/HERO-Anti-OverDefense) · [](https://github.com/wanshuiyin/Anti-Autoresearch) — two sides of one disease. HERO: a ~550-token block for `CLAUDE.md` / `AGENTS.md` against the four shapes agents over-defend in (Hashing, Edge cases, Rubrics, Overbuild), bounding what the agent *proposes*, never what it *looks for*. Anti-Autoresearch: 61 integrity signals into a deterministic, reviewer-ready report — fabrication forensics, not an AI-text detector.
- [](https://github.com/wanshuiyin/ARIS-Movie-Director) — **ARIS goes multimodal**: a rough story in, a movie told in still frames out, every scene checked by another model; the same loop draws clean method diagrams (`/method-figure`).
- [](aris-monitor/) — a tiny always-on-top macOS widget that lights up 🔴 when a session waits for your approval; `cd aris-monitor && ./run.sh`. Many windows? [Claude Fleet](https://github.com/tianyilt/claude-fleet) by [@tianyilt](https://github.com/tianyilt) is the full dashboard.
- 🔥 [**ARIS-Code CLI — 独立安装版**](docs/ARIS-Code-README_CN.md) · [English](docs/ARIS-Code-README_EN.md) | [⬇️ Download](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/releases/latest) · [](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/releases) — **v0.4.28**: `ARIS_REASONING_EFFORT` works on the Anthropic channel, tool calls through `{}`-placeholder relays fixed, OS proxy honoured. v0.4.27: launching and quitting the REPL leaves no empty session file. v0.4.26: the `fable` alias and `/model` now point at Fable 5.1 (default stays Opus 5). v0.4.25: the Codex reviewer works again on codex-cli ≥ 0.154 (built-in `codex exec` bridge, nothing to register), `/since` takes you back to your last input, `/resume` lists sessions by index, Windows multi-line paste fixed (pending confirmation), 83 bundled skills on GPT-6-Astra.
- <details><summary>ARIS-Code — screenshot, what's in v0.4.28, per-release details, older versions</summary>
- <p align="center"><img src="docs/aris-code-banner.png" width="100%" alt="ARIS-Code CLI terminal — Auto Research in Sleep"></p>
- 📰 **ARIS-Code v0.4.28** (2026-09) — latest: **`ARIS_REASONING_EFFORT` works on the Anthropic channel** ([#446](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/446)), tool calls through relays that send a `{}` placeholder no longer fail ([#444](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/444)), and the OS proxy on Windows / macOS is used without exporting `HTTPS_PROXY` ([#401](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/401)). v0.4.27: launching and quitting the REPL no longer leaves an empty session file, and `/resume` lists only sessions with messages ([#439](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/439) follow-up). v0.4.26 made **Fable 5.1** the `fable` alias and the first `/model` entry (the default executor stays Opus 5). v0.4.25 is the **reviewer-bridge release**: codex-cli 0.154 removed `codex mcp-server`, so every Codex review from ARIS-Code died on an updated codex. The reviewer now runs over a **built-in `codex exec` bridge** — no `mcpServers.codex` entry, old entries migrate in memory, thread records interoperate with ARIS's Python bridge. Also: **`/since`** replays everything after your last input (folded like the live display, `/since full` for complete output), **`/resume`** lists sessions with indices and shows where you stopped ([#439](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/439)), Windows multi-line paste no longer submits line by line ([#430](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/430), pending confirmation), the Windows shim message carries the native installer ([#428](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/428)), and the bundle moves to **83 skills** on **GPT-6-Astra**. Recent headliners: **v0.4.24 — Claude 5 model refresh** (Opus 5 default, Fable 5 tier, availability chain) and **v0.4.23 — output folding**. Caps a 24-release run (v0.4.5 → v0.4.28); per-release detail below. Credits: [@GetIT-Sunday](https://github.com/GetIT-Sunday), [@Anduin9527](https://github.com/Anduin9527), [@GO-player-hhy](https://github.com/GO-player-hhy), [@Jxy-yxJ](https://github.com/Jxy-yxJ), [@screw-44](https://github.com/screw-44), [@StevenUST](https://github.com/StevenUST), [@opposj](https://github.com/opposj), [@ShijunLei-cn](https://github.com/ShijunLei-cn), [@algojogacor](https://github.com/algojogacor), [@YukinoshitaLove](https://github.com/YukinoshitaLove), [@jinliye-2026](https://github.com/jinliye-2026), [@SajimJC](https://github.com/SajimJC), [@JasmineLCY](https://github.com/JasmineLCY).
- > <details><summary>Per-release details (v0.4.5 → v0.4.28)</summary>
- >
- > **v0.4.28** (2026-09-28) — **`ARIS_REASONING_EFFORT` now works on the Anthropic channel** ([#446](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/446)): `low` / `medium` / `high` / `xhigh` / `max` for the main session and subagents; unset, requests are unchanged. **`ARIS_MAX_TOKENS`** raises the output cap when a high effort runs into it. **`autoCompactEnabled: false`** in settings turns automatic compaction off. **🐛 [#444](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/444)** tool calls through relays that send a `{}` placeholder no longer fail with `invalid tool input JSON`. **🌐 System proxy** on Windows / macOS is used without exporting `HTTPS_PROXY` ([#401](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/401), by @JasmineLCY); `NO_PROXY=*` connects directly as before. **Upgrading:** if you already export `ARIS_REASONING_EFFORT`, have an OS proxy, or have `autoCompactEnabled: false` in settings, read the [upgrade notes](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/blob/aris-code/CHANGELOG.md).
- >
- > **v0.4.27** (2026-09-19) — launching and quitting the REPL no longer leaves an empty session file; `/resume` lists only sessions with messages ([#439](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/439) follow-up).
- >
- > **v0.4.26** (2026-09-16) — **Fable 5.1**: the `fable` alias now resolves to `claude-fable-5-1`, `/model` lists Fable 5.1 first (Fable 5 stays selectable) and the system-prompt identity names it; the default executor remains `claude-opus-5` (the Mythos tier is $10/$50 vs Opus 5's $5/$25, so the default does not move). Saved `executor_model` values are ids, not aliases, and are untouched. Pricing already matched on `fable`; a test pins 5.1. Tests unchanged (aris-cli 225 + 4 e2e / runtime 252 / tools 71 / commands 6). Codex MCP (gpt-6-astra xhigh) gate: GO.
- >
- > **v0.4.25** (2026-09-16) — **the reviewer-bridge release**. codex-cli 0.154 removed `codex mcp-server`, the entry point ARIS-Code's `aris setup` had written into settings.json for every Codex review; on an updated codex every review call died. **Built-in `codex exec` bridge**: `mcp__codex__codex` / `codex-reply` run as `codex exec --json` with nothing to register — no settings entry, a legacy `codex mcp-server` entry is migrated in memory (env, `-c` defaults, `requestTimeoutSecs`, trust kept), an explicit Python-bridge entry is used as configured, thread records share `~/.codex/state/codex-exec/threads/` with the Python bridge, 1800 s budget for `ultra` audits, `ARIS_CODEX_BRIDGE=0` restores the old path; `aris doctor` prints the effective backend. Found on the way: the model never received a Codex result's `threadId` (it lives only in `structuredContent`), so `codex-reply` could not continue a thread — results now start with a `threadId:` line. **`/since [full]`** replays the user's last input and everything after it with the live formatters (display only; after `/resume` and in `--resume` batch mode too); a dim hint after turns with ≥ 8 tool calls (`ARIS_TURN_SUMMARY=0`). **#430** Windows consoles deliver no paste event, so each pasted line became its own Enter — lines are now merged into the input and never auto-submitted, Ctrl+C discards the rest (`ARIS_PASTE_BURST=0`; inferred from crossterm's source, pending confirmation on a Windows machine). **#439** `/resume` lists sessions with `[n]` indices and ages and accepts an index, a unique id prefix or a path; the last turn is replayed after loading. **#428** the `.cmd`-shim message carries the official native installer one-liner. **Bundle 81→83** (pin 3e49e63 → 4734364): `/proof-orchestrator`, `/research-implement-feature`, 32 helpers (+`review_gate.py`, `copilot_native_evidence.py`, `idea_discovery_gate.py`), repo-root `templates/` bundled; reviewer doctrine and system prompt on **gpt-6-astra** (fallback gpt-5.6-sol → gpt-5.5), explicit `— reviewer:` directives win, `LlmReview` results carry `reviewer_model:` so HTTP rounds report to `review_gate.py` truthfully; gpt-6-astra pricing tier $10/$50 (cache write $12.50, read $1). Tests: api 35+6 / aris-cli 225 + 4 e2e / runtime 252 / tools 71 / commands 6, all green; live `codex exec` fresh + resume roundtrip on codex-cli 0.154.0. Codex MCP (gpt-6-astra): ultra design gate (2 rounds), xhigh implementation gate per step (5/2/2/2 rounds), final whole-diff gate (2 rounds) → GO.
- >
- > **v0.4.24** (2026-08-09) — **the Claude 5 model refresh** ([#392](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/392), requested by [@YukinoshitaLove](https://github.com/YukinoshitaLove)). Explicit `--model claude-opus-5` / `claude-fable-5` already passed through on every platform — this release makes them first-class. **Default → `claude-opus-5`** (main session, subagents, `aris setup`; same $5/$25 tier as Opus 4.8); the v0.4.18 availability fallback becomes an ordered **chain walk** (Opus 5 → Opus 4.8 → Opus 4.7, one step per precise `404 not_found_error`, explicit choices never silently change) — the naive constant swap would have stranded 4.7-only accounts and configs saved by v0.4.23's setup, a regression the cross-model review caught and an end-to-end mock-404 chain test now locks. `/model` picker adds Fable 5 / Opus 5 / Sonnet 5; new `fable` alias. **New Mythos-class pricing tier** (`fable`/`mythos` = $10/$50, cache write $12.50 / read $1, verified 2026-08 — previously fell to the conservative $15/$75 unknown-model tier, a 1.5× over-estimate); Opus 5 / Sonnet 5 pinned on their existing branches. Tests: api 41 / aris-cli 213 + 4 e2e / runtime 226 / tools 70 / commands 5, all green; live smoke on claude-opus-5, claude-fable-5 and the fable alias. Codex MCP (gpt-6-astra xhigh) implementation gate: NO-GO → NO-GO → GO.
- >
- > **v0.4.23** (2026-08-02) — **the output-folding release** (top real-user complaint: "aris dumps thinking and the full content of documents it reads onto the screen"). **🧹 Tool-output folding, display layer ONLY**: the disk-verified culprits were format_read_result appending the ENTIRE read payload, bash pushing full stdout/stderr, grep dumping its full content blob, and the edit preview capping line counts but not line LENGTH. Now Read/Grep show the first 6 lines, Bash shows first 4 + last 4 per stream (stderr keeps its red), each kept line capped at 240 chars (the minified-single-line case), then one dim "… (+N more lines — set ARIS_TOOL_OUTPUT_LINES=0 for full output)" hint. ONE env knob: unset = defaults, a positive integer overrides every tool, 0 = the exact old display; the session, model context, `--output-format json` and `/export` are untouched and always complete. Thinking was verified to never print (Anthropic deltas only accumulate; Kimi reasoning_content only feeds the replay cache — the "thinking dump" perception came from the document dumps); two end-to-end sentinel tests (real binary vs mock SSE server) lock that thinking/reasoning never reaches the terminal. Interactive expand/collapse was deliberately rejected as over-engineering. **🐛 Bash timeout now kills the command**: a timed-out call reported `interrupted: true` while the dropped tokio future left the child RUNNING — side effects landed after the report; now kill_on_drop (escape hatch `ARIS_BASH_KILL_ON_TIMEOUT=0`; background tasks untouched; locked by a real behavioral test — a timed-out "sleep 1 && touch marker" must not create the marker). **📦 Bundle 79→81** (pin 7182624 → 3e49e63): **`/integrity-forensics`** — the Anti-Autoresearch SHA-pinned thin launcher (span-anchored evidence ledger → GPT auditors propose → deterministic rules-only adjudicator decides → typed BLOCK/WARN gate + obligations ledger) — and `/web-debug-search`, +tools/forensics_gate.py (29 helpers, 104 embedded resources). **🎁 Also**: grep's content mode no longer shows a false "0 matches" above real results (the gate caught that `"numMatches": null` serializes with the key present, defeating a naive presence check); all four crates' local-mock-server tests are now proxy-immune (a shell with http(s)_proxy set used to turn 15 tests red on a released tag — 127.0.0.1 was routed through the proxy). The rest of the runtime-state package (compaction re-arm, failed-turn cleanup, /cost dollars, SSE tail) ships as v0.4.24 — the cached-token cost fix is deliberately held back because it changes what the compaction trigger measures. Tests: api 41 / aris-cli 212 + 3 e2e / runtime 225 / tools 69 / commands 5 (+13), all green **under a live proxy**; new-code clippy delta zero. Codex MCP (gpt-6-astra): ultra scope+design adjudication, then a 3-round implementation gate (round 1 caught the null-serialization defeat and a non-hermetic behavioral test; round 3 GO).
- >
- > **v0.4.22** (2026-07-12) — **the skills-resync + GPT-6-Astra release**. **📦 Bundle resync** (pin 7e3ab67 → 7182624, 93 commits): **79 bundled skills** (+`meta-apply`, +`paper-poster-html`; `paper-poster` retired to a redirect stub), 28 tools helpers (8 new: capture_filter, evidence_check, iteration_log, provenance, run_state, threat_scan, meta_opt/trigger_eval + sample evals), 11 new shared-references docs (fan-out-pattern, acceptance-gate, external-cadence, skill-governance, compute-env-contract, resumable-runs, evidence-precheck, injection-hygiene, capture-antipatterns, output-composition, taste-calibration); sync hardening — `ARIS_SYNC_EXPECT_SHA` guard (aborts before touching assets if main moved; it caught a real move on first use) + exact-inventory drift tests + the vendored posterly MIT license text now ships. **🎛 GPT-6-Astra two-tier reviewer alignment**: the CLI's system-prompt nudge now passes the skills' explicit `model: gpt-6-astra` + per-call effort pins through (the v0.4.17 blanket "never pass a model" rule would have silently stripped deep audits from ultra to xhigh), carries the canonical capability-only fallback chain (effort-unsupported → same model xhigh, deep tier only; model-unknown → explicit gpt-5.5+xhigh; never degrade on transport-class errors; an explicit call-level override disables the chain), pins `approval-policy: "never"` + explicit `sandbox` on every fresh codex call, and makes the HTTP fallback pre-dispatch-only with parameter stripping; the HTTP LlmReview default deliberately stays gpt-5.5 pending a real smoke; gpt-5.6 family pricing (sol $5/$30, terra $2.50/$15, luna $1/$6) verified against the official page; banner/Reviewer display/`/reviewer` are honest about primary-vs-fallback (pure-Codex setups get status + guidance instead of a fake picker). **🐛 8 verified fixes**: explicit `--model` was silently overridden by the saved executor model (model provenance now tracked end-to-end; the 4.8→4.7 availability fallback respects explicit choices; `/model` and `/setup` re-arm it); saved models no longer leak across provider transports (blank saved models count as absent; OpenAI transport with no model source fails fast; the first-run wizard's config now actually feeds startup model resolution); `--output-format json` never prompts (locked by a real end-to-end binary test against a mock SSE server); **Windows `aris login` fixed** (PKCE randomness read /dev/urandom → getrandom); **Windows command probing fixed** (the PowerShell tool probed itself through `sh`; now where.exe); codex `.cmd` shims classified honestly (three-state probe; setup requires explicit confirmation before writing a config the MCP client can't spawn); nested config.json warns instead of silently parsing to all-defaults; NotebookEdit mints collision-free cell ids. **🖥 New windows-latest CI job** (workspace compile gate + three targeted test groups, each guarded against silent 0-test green). Tests: api 41 / aris-cli 204 + 1 e2e / runtime 223 / tools 69 / commands 5 (+54), all green; new-code clippy delta zero. Codex MCP (gpt-6-astra): **ultra** design gate — 5 rounds, NO-GO ×4 → GO — then a 3-round implementation gate whose round 2 caught a first-run config-wiring blocker before it shipped; 4 implementation subagents, every report disk-verified.
- >
- > **v0.4.21** (2026-06-28) — **bug-fix patch**: 5 new user-facing bugs from a Codex adversarial hunt (all disk-verified, distinct from v0.4.20), each cross-model reviewed at a design gate and an implementation gate (gpt-5.5 xhigh; both started NO-GO — the reviewer caught an off-by-one in the grep line-mapping and a missing stream-level test before GO). **🐛 Headline**: OpenAI-compatible streaming corrupted multi-byte UTF-8 (CJK / emoji) split across network chunks into `�` — each HTTP body chunk was `from_utf8_lossy`'d independently, so a 3-byte Chinese character or 4-byte emoji straddling a chunk boundary broke on both sides (a frequent hit for Chinese users on domestic OpenAI-compatible providers — Kimi/GLM/MiniMax/DeepSeek/Qwen/Doubao — streaming Chinese text); the stream buffer is now raw bytes, decoding only complete SSE lines. **A saved OpenAI/custom executor config no longer overrides a shell-set `EXECUTOR_PROVIDER`** — the startup "shell-provided vars win" path had one ungated write that re-pointed `EXECUTOR_PROVIDER=anthropic … aris …` to OpenAI (wrong executor / model-not-found). **An Anthropic stream truncated after content but before a terminal signal now hard-errors** (`premature_eof`) instead of saving a half-finished answer to history as a complete turn (symmetric to the OpenAI `#249` guard; the `stop_reason`-only compat path is preserved, and `ARIS_ALLOW_EOF_WITHOUT_STOP=1` opts a terminal-signal-less proxy back into the old behavior). **`grep_search` with `multiline: true`** now matches across lines in content mode (was silently empty — `count` mode already worked). **MCP tool results carried only in `structuredContent`** (empty `content`) are no longer dropped — the model gets the JSON structured payload. Tests (CI mode): api 32→35 / runtime 205→212 / tools 67 / aris-cli 172→181 / commands 5 (+21, incl. 2 stream-level integration tests), all green. Codex MCP (gpt-5.5 xhigh): design gate (NO-GO → GO after fixing the off-by-one) → implementation gate (NO-GO → GO after adding the stream-level integration tests); the Anthropic streaming spec (every stream ends with `message_stop`) was WebFetch-verified. Two latent-only candidates (Anthropic block-`index` routing, OpenAI multi-line SSE) remain deferred.
- >
- > **v0.4.20** (2026-06-19) — **bug-fix patch**: 7 user-facing bugs surfaced by a Codex adversarial hunt, each reviewed across 3 rounds (the reviewer caught a redraw gap, a trailing-blank, a spinner tail, and a blank-line edge before GO). **🐛 Headline ([#299](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/299))**: short REPL replies showed only "✔ Done" — the spinner draws "⠋ Thinking…" with Save/RestorePosition so streamed output overwrites it on the same line, but `finish` then cleared that whole line, **erasing a short single-line reply**. The REPL now finishes without clearing when the turn printed visible text (`Clear(UntilNewLine)` wipes only the spinner tail after the reply). **Streamed multi-paragraph replies rendered glued** ("para1para2") — each chunk's paragraph separator was trimmed at the stream boundary; the markdown streamer now preserves separators via a held-separator so streamed output equals a single full render (no dangling blank line). **Markdown tables with CJK/fullwidth content misaligned** — width now counts display cells (CJK = 2), not chars. **`aris "prompt"` / `--print` ignored the executor model saved by `aris setup`** (REPL-only before) — a configured OpenAI/custom executor got the Anthropic default sent to its endpoint; the one-shot and REPL paths now share one resolver. **Esc** now actually closes the completion dropdown (it was recomputed right back). **`glob_search`** reports the total matched count when truncated (not the capped 100, which made the model think a 1000-match glob had 100 files). **`/model`'s custom menu** reads the effective env the executor uses, not stale on-disk config. Tests (CI mode): api 32 / runtime 205 / tools 67 / aris-cli 172 / commands 5, all green; +7 new; real-machine verified (short reply renders + "✔ Done"; paragraphs keep their blank lines). Codex MCP (gpt-5.5 xhigh): hunt → 3 review rounds (NO-GO → NO-GO → GO). Two latent-only candidates (Anthropic block-`index` routing, OpenAI multi-line SSE) deferred to a hardening pass.
- >
- > **v0.4.19** (2026-06-14) — **honesty / guardrails patch** (theme from a Codex fresh-eyes audit; no behavior change for healthy setups). **🔴 MCP protocol-version negotiation guard** — the stdio handshake requested `2025-03-26` but never read the version the server negotiated back (a parsed-but-dead field), so a server agreeing on a version ARIS can't speak was silently accepted and later `tools/list` / `tools/call` ran on an incompatible protocol with opaque failures. ARIS now validates the negotiated version against a supported set (`2025-11-25` / `2025-06-18` / `2025-03-26` / `2024-11-05` — stdio framing is identical across these) and, on an unsupported one, terminates the child + clears the slot + surfaces a clear per-server error (`aris doctor` shows it) — the "terminate when versions can't be agreed" behavior the MCP lifecycle spec requires. The *request* stays `2025-03-26` (proven against `codex mcp-server`), so healthy servers are unaffected — verified end-to-end: the real Codex MCP server still spawns + initializes + advertises its tools under the guard. **🧹 Papercuts**: the OpenAI-family subagent fail-loud message dropped its stale "lands in v0.4.18" marker (now version-agnostic + actionable, still credential-free); OpenAI upstream error bodies are now truncated (500 chars) + credential-redacted (`sk-…` keys and `Bearer …` tokens, via a substring scanner that catches the compact-JSON shape `{"api_key":"sk-…"}` a misconfigured proxy can reflect back) instead of splatted verbatim; the system-prompt hook-events summary now counts only the hooks the runtime actually executes (a `command` hook with a `command` string), matching the parser. Tests (CI mode): api 32 / runtime 204 / tools 67 / aris-cli 167 / commands 5, all green; live smoke confirms the real Codex MCP server still initializes under the guard. Reviewed by Codex MCP (gpt-5.5 xhigh): design GO → impl NO-GO (compact-secret miss + command-string strictness) → GO after fixes.
- >
- > **v0.4.18** (2026-06-14) — **default model → Claude Opus 4.8**, with corrected pricing and a safety net. The bump moves `DEFAULT_MODEL`, the `opus` alias, the model picker, `aris setup`, and the subagent default to `claude-opus-4-8` — with an **availability fallback**: if the account lacks 4.8 (the API returns `404 not_found_error`), ARIS auto-falls-back to `claude-opus-4-7` for the session, **rebuilds the system-prompt model identity so it stays coherent** (the model is never told it's 4.8 while served 4.7), warns once, and retries — for the main session (text + JSON) and subagents. It fires only on that precise 404 (never 400/rate-limit/auth), latches against loops, and the text path rebuilds from a pre-turn snapshot so a retry never double-appends the user message; accounts **with** 4.8 are byte-identical to a plain bump. **💰 Pricing corrected** (verified against Anthropic's published schedule; had been a 3–5× over-estimate): current **Opus 4.5–4.8 = `$5/$25`** (deprecated Opus 4/4.1 keep `$15/$75`, split by word-boundary so a future `opus-4-10` isn't mis-tiered); **Sonnet 4.x = `$3/$15`** (decoupled from the generic unknown-model fallback, which stays `$15/$75`); Haiku was already correct. **🧹 Backlog**: `aris setup` option 10 pins the Codex MCP reviewer to `model_reasoning_effort="xhigh"` (deterministic for new setups, independent of `~/.codex/config.toml`; idempotent merge never clobbers an existing entry); a startup + `aris doctor` **misconfig hint** ([#259](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/259)) for a silently-ignored/misplaced config (malformed JSON, or a stray `~/.aris/config.yaml` — stderr-only so `--print`/JSON stdout stays clean); the system-prompt hook summary now marks parsed-but-never-fired events **"PARSED ONLY … will NOT run"** instead of implying dead hooks run (full event expansion — actually firing `SessionStart`/`SessionEnd`/… — deferred to a separate issue). Tests (CI mode): api 32 / runtime 202 / tools 67 / aris-cli 166 / commands 5, all green; a live one-shot smoke returns `model=claude-opus-4-8` end-to-end. Reviewed by Codex MCP (gpt-5.5 xhigh) across the design + both implementation batches (design REWORK→GO, impl NO-GO→GO, batch-2 GO).
- >
- > **v0.4.17** (2026-06-13) — **the MCP release.** Before v0.4.17, `mcpServers` in `settings.json` parsed, showed in `aris doctor`, and did *nothing*; now ARIS spawns each configured stdio server, runs the MCP handshake, discovers tools, and advertises them as `mcp__<server>__<tool>` on **both** provider paths (Anthropic + OpenAI-family), with end-to-end dispatch, soft per-server degradation, and an approval gate for untrusted MCP tools (external processes the sandbox can't cover; `--allowedTools` now accepts `mcp__` names). **🆕 zero-API-key cross-model reviewer**: `aris setup` → **option 10 (Codex MCP, ChatGPT subscription, no API key)** writes an idempotent `mcpServers.codex` entry into the settings file the runtime actually reads (atomic write + backup, explicit consent before `trust: true`), with an optional API reviewer as **fallback** (`ARIS_REVIEWER_PROVIDER=codex-mcp` + `ARIS_REVIEWER_FALLBACK_PROVIDER`); `/setup` in-REPL rebuilds the system prompt + runtime so reviewer changes take effect without quitting. **🔴 Protocol fix the fakes couldn't catch**: real-machine e2e against `codex mcp-server` exposed that our stdio transport spoke LSP-style `Content-Length:` framing while the MCP spec (and codex) use **newline-delimited JSON-RPC** — every fake-server test passed because the fakes spoke the same wrong dialect; writes are now NDJSON, reads auto-detect both, and the spec-mandated `notifications/initialized` is sent after `initialize` (a select-based round-trip also closes the [#286](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/286) large-request deadlock). **Hooks**: object-style Claude Code hooks preserve `matcher` / `timeout` / `async` (anchored-regex matcher filtering; per-hook timeout, default 30 s kill = warning not deny). **Long tail**: `ARIS_DISABLE_KEYCHAIN` gate, Anthropic `stop_reason` clean-EOF symmetry (CL2), OpenAI tool-call `index`-missing merge-by-id (OE6), slash commands enter history. **Real-machine push-gate hardening** (the zero-key reviewer's first run): codex `codex/event` notification spam silenced by default (gated behind `ARIS_MCP_STDERR=inherit`), the system prompt now tells the model **not** to pass a `model` parameter to Codex (account default = gpt-5.5 + xhigh; arbitrary names are rejected by a ChatGPT account), and a Codex-MCP-primary-with-no-fallback `LlmReview` call returns a clear "use `mcp__codex__codex`" message instead of a misleading `OPENAI_API_KEY`/`gpt-5.5` error. Built with the v0.4.16 zero-regression methodology (24 new characterization tests; every deliberate flip annotated in-place). Tests (CI mode): runtime 199 / aris-cli 165 / tools 67 / api 30 / commands 5, all green. Reviewed phase-by-phase by Codex MCP (gpt-5.5 xhigh) across 17 rounds (7 NO-GOs all resolved). Subagent MCP routing (P8) + MCP `protocolVersion` bump + hook `async` execution deferred to v0.4.18.
- >
- > **v0.4.16** (2026-05-30) — REPL UX + provider hardening, shipped under a zero-regression discipline: 64 characterization ("golden") tests locked the *current* provider-routing / pricing / reviewer / subagent / REPL behavior first, then stayed green through every change. Closes [#274](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/274): command history now persists to `~/.config/aris/history` (0600) and reloads on startup, with an `ARIS_NO_HISTORY` kill-switch and a disk-only secret-skip (credential-looking lines stay in in-session history but never touch disk); bash-style **Ctrl+R** reverse incremental search (CJK display-width-aware single-line render; no existing key binding changed; no new dependency). Security: an OpenAI-family main session (Kimi / GLM / MiniMax / …) spawning a subagent previously **silently billed the user's Anthropic OAuth/Keychain credential** — it now fails loud with a clear, credential-free error; full OpenAI-family subagent routing is a cross-crate change deferred to v0.4.17. Groundwork (no behavior change): the 3 byte-identical word-boundary matchers consolidate into one canonical `runtime::word_match`; new pure `ProviderFamily` classifier (unwired). Tests (CI mode): runtime 164 / aris-cli 128 / tools 49 / commands 5, all green. Codex MCP (gpt-5.5 xhigh) reviewed each phase + a final integration pass.
- >
- > **v0.4.15** (2026-05-29) — OpenAI-compatible streaming robustness hotfix. Closes [#249](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/249): MiniMax (and other OpenAI-compatible providers / proxies) were effectively unusable because the clean-EOF completion check treated the `data: [DONE]` SSE sentinel as the *only* authoritative signal. A non-empty `choices[].finish_reason` is the Chat Completions spec's terminal-chunk marker; `[DONE]` is a transport convention some compatible providers never emit (MiniMax sends `finish_reason: "stop"` then closes without `[DONE]`). The clean-EOF decision is now a pure, unit-tested `stream_eof_action(...)` that completes on EITHER `[DONE]` OR a non-empty `finish_reason`; reads are NOT stopped early at finish_reason (a trailing `include_usage` usage-only chunk is still consumed), genuine truncation still hard-errors, and a pre-output proxy abort still restarts. Coupled fixes: **OE7** reads finish_reason before the `delta` guard (delta-less terminal choice); **OE2** flushes pending tool calls on any non-empty finish_reason; **OE4** surfaces a mid-stream error envelope as a hard error instead of silently dropping it; **OE3** tolerates `data:{...}` without the space after the colon. +5 unit tests (77→82) extract the previously-untested SSE completion logic into pure helpers. Anthropic SSE path untouched. Codex MCP (gpt-5.5 xhigh) 3 rounds (GO-WITH-NITS → GO-WITH-NITS → GO).
- >
- > **v0.4.14** (2026-05-25) — Security-hygiene release closing the top items from the v0.4.13 codex audit (gpt-5.5 xhigh, 6/10 NEEDS-REWORK verdict). **🔴 S9 (P0) system-prompt config redaction** — before v0.4.14, `render_config_section()` dumped the merged `settings.json` verbatim into the system prompt sent to the LLM provider, leaking `env`, `mcpServers.<name>.headers.Authorization` Bearer tokens, hook command env, signed-URL query params, and `apiKey` fields. New renderer whitelists top-level fields (`model`/`permissionMode`/`theme`/`outputStyle`/`permissions`/`sandbox` with recursive redaction inside), redacts sensitive keys (`apikey`/`token`/`secret`/`password`/`authorization`/`headers`/`env`/`_KEY`/`_SECRET`/`_TOKEN`), replaces MCP `command` with `<configured>` placeholder, reduces MCP `url` to strict `<scheme://host[:port]>` origin (scheme allow-list `http`/`https`/`ws`/`wss`, ASCII host, digit-only port, IPv6 brackets), and drops hook command strings entirely. Regression test exercises 9 distinct leak surfaces; URL parser has its own targeted test for 7 smuggling attempts including port-position secret injection (codex round-3 catch). **🟡 P9 (P1)**: DeepSeek `aris --help` now points at `aris setup` option 7 instead of an env-var path the resolver never honored. **🟡 M1/M2 (P1) doc**: `aris doctor` + README/README_CN gain experimental warning whenever `mcpServers.len() > 0` (full MCP tool dispatch lands v0.4.16). **🟢 C11 (P2) stream idle timeout** — both Anthropic `MessageStream` and the OpenAI SSE loop wrap `response.chunk().await` in `tokio::time::timeout` (env `ARIS_STREAM_IDLE_TIMEOUT_SECS`, default 120, clamp `[10, 1800]`, 0/negative disables); closes the "aris hangs forever with no output" symptom when an upstream HTTPS proxy holds a connection without keepalives. **Bundle**: 77 skills (+1 `/wiki-enrich` via late same-day sync to main `7e3ab67` which also picks up upstream `check_ready.sh` awk + grep-c null-match fix), 54 helpers. Codex MCP 6 rounds (NO-GO + 4 → GO-WITH-NITS + 3 → NO-GO + port smuggling → GO → release metadata GO → sync GO).
- >
- > **v0.4.13** (2026-05-25) — Residue-cleanup release closing every codex audit P1 carried since v0.4.10–v0.4.12, plus the long-tail regression tests. **🟡 v0.4.10 P1.D per-server MCP timeout** — `mcpServers.<name>.requestTimeoutSecs` override > `MCP_REQUEST_TIMEOUT_SECS` env > 300s default (clamped 1..=1800), so one Codex MCP agent can run 5 min while filesystem MCP errors in 5 s. **🟡 v0.4.10 known limitation closed** — `McpStdioProcess::request()` skips JSON-RPC notifications (id absent/null) and keeps reading until the correlated response. **🟢 meta_opt hook deploy via `aris init`** — `tools/meta_opt/{log_event,check_ready}.sh` bundle into the binary; `aris init` writes ARIS-namespaced **`aris-meta-opt-log-event.sh`** / **`aris-meta-opt-check-ready.sh`** to `~/.claude/hooks/` (codex round-1 #1: never clobbers user hooks); settings.json merge idempotent, backups hard-fail, final rewrite atomic via tempfile + rename. **🧪 9 v0.4.12 targeted regression tests** for sandbox.strictMode (3) + parse strictMode + provider_match pricing + has_word o-series + stream_options 400 + meaningful-content classification + premature-EOF retry truth table (codex round-1 #3 — `should_retry_on_premature_eof()` extracted to pure fn, 7-row test). **Bundle**: 76 skills, **54 helpers** (+2 meta_opt scripts vs v0.4.12). Codex 3 rounds (NO-GO + 3 → NO-GO + metadata → GO).
- >
- > **v0.4.12** (2026-05-22) — Bug-fix + small-feature release. **#238 `sandbox.strictMode`** opt-in config key; when set, `SandboxConfig::resolve_request()` ignores all five LLM-supplied overrides (`dangerouslyDisableSandbox`, `namespaceRestrictions`, `isolateNetwork`, `filesystemMode`, `allowedMounts`) — closes the gap where a tool call could silently bypass user sandbox policy. `aris doctor` adds a "Sandbox:" row; bash tool schema documents the strictMode semantics. **#232** `auto-review-loop-llm` updated from legacy `deepseek-chat` / `deepseek-reasoner` (deprecate 2026-07-24; reasoner rejects `tool_choice`) to `deepseek-v4-flash` / `deepseek-v4-pro`. **v0.4.10 audit P1 follow-ups**: P1.A Anthropic stream retry gates on `has_emitted_meaningful_content` (a stream that only sent `MessageStart` before EOF is retry-eligible); P1.B `supports_reasoning_effort` + reviewer mirror use word-boundary match so `openai/o3-mini` / `proxy:o4` route correctly; P1.C `stream_options.include_usage:true` proxy fallback retries once without on real 400 unknown-field errors; P2 pricing match precision via `provider_match()` so `qwen3.6-plus` / `kimi-k2.5` route correctly while `my-kimi-clone` does not. **Skills sync** (76 skills, 52 helpers): `/interview-cheatsheet` + `/render-html` newly bundled; `build.rs` `ALLOWED_EXTS` gains `html` for render-html templates; `EXCLUDED_SKILL_PREFIXES` → `starts_with("skills-codex")`. **CI fetch-depth: 0** + origin/main fetch so drift-test ancestor check runs. Cross-reviewed by Codex MCP (gpt-5.5 xhigh) over 4 rounds.
- >
- > **v0.4.11** (2026-05-18) — Skills bundle refresh + sync infrastructure. The embedded skills set in the v0.4.10 binary had fallen behind main (~6 of 56 main `skills/` commits had been cherry-picked); v0.4.11 syncs the full set and ships sync infrastructure so the gap can't silently reopen. Bundle: 65→74 user-facing skills, 34→49 helper resources. 10 new skills bundled: `/citation-audit` (fourth-layer bibliography audit), `/experiment-queue` (SSH multi-seed job queue with OOM retry), `/kill-argument` (two-thread adversarial review for theory papers), `/resubmit-pipeline` (W5: text-only port to a new venue), `/paper-talk` (end-to-end conference talk pipeline), `/slides-polish` (per-page Codex layout review), `/overleaf-sync` (two-way Overleaf Git-bridge), `/gemini-search` + `/openalex` (broader literature sources), `/qzcli` (Qizhi GPU jobs). 46 existing SKILL.md refreshed — most critically the canonical resolver chain rollout (closes real user incident where `/research-wiki` was empty for a week from hardcoded `tools/research_wiki.py`), submission assurance gate + external verifier (`/paper-writing` Phase 6 now functions). tools/ goes 9→18: 9 baseline helpers refreshed (`research_wiki.py` 315→767 lines with canonical `ingest_paper` API), 9 new helpers (`extract_paper_style.py`, `figure_renderer.py`, `paper_illustration_image2.py`, `overleaf_{setup,audit}.sh`, `verify_wiki_coverage.sh`, `watchdog.py`, `experiment_queue/{build_manifest,queue_manager}.py`). New `tools/sync_main_skills.sh` automates main → bundle rsync with symlink pre-flight + codex-mirror prune + `SKILLS_SOURCE_COMMIT` pinning. 3 new CI drift tests in `crates/runtime/src/cache.rs` cover all 4 resolver layer patterns. Gemini MCP calls in `/research-lit` and `/gemini-search` now pass `model: 'auto-gemini-3'` (avoids silent downgrade to 2.5-pro on OAuth-personal capacity exhaustion). CLI runtime unchanged — codex-audit P1 follow-ups remain on v0.4.12 backlog. Cross-reviewed by Codex MCP (gpt-5.5 xhigh) across 5 rounds (REQUEST CHANGES → APPROVE WITH NITS → NO-GO → GO → final GO).
- >
- > **v0.4.10** (2026-05-17) — Stream + MCP reliability + multi-provider pricing. C6 whole-stream restart in Anthropic `MessageStream` + OpenAI SSE loop on chunk decode failure / premature EOF (`ARIS_STREAM_RETRY`, default 2, clamp 0..=5, fires only when nothing emitted yet — closes [#228](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/228)-style "error decoding response body" loop). M3 MCP stdio gains 300s default `tokio::time::timeout` over send+read (override `MCP_REQUEST_TIMEOUT_SECS`, clamp 1..=1800); `response.id ↔ request.id` correlation; `ensure_server_ready()` `try_wait()` dead-process respawn; `kill().await` on all failure paths so the next call starts clean (closes [#151](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/151) / [#172](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/172) "Calling codex..." stalls). C8/P4 OpenAI streaming requests now send `stream_options.include_usage:true` + parse `cached_tokens`; Anthropic streaming merges `MessageStart.usage` (input/cache) with `MessageDelta.usage` (output). C9 multi-provider pricing registry (15+ models, OpenAI cache_read = input × 0.1 corrects 5× generic overstatement, DeepSeek cache_hit/cache_miss tiers, `has_word()` boundary matcher for `provider/<model>` slugs). 9 dead-code warnings cleared; `aris setup` help text synced with actual behaviour.
- >
- > **v0.4.9** (2026-05-17) — Closes Codex v0.4.7 audit residuals (L1 TLS double-stack, L3 reasoning_cache compaction misalign, L4 reasoning replay unbounded). 2 new skills bundled (`/figure-spec` + `/paper-illustration-image2` with `scripts/` subdirs, new Layer 0b = `$ARIS_CACHE_DIR/skills/<name>/scripts/`); `research_wiki.py` promoted to shared `tools/` (9+ callers); 5 more SKILL.md migrated to fallback chain.
- >
- > **v0.4.8** (2026-05-17) — Skill helper subsystem rewrite. Bundled helpers extract to `~/.config/aris/cache/<version>/` at startup; every Skill invocation surfaces `helperReport` JSON + 4-layer resolver preamble; `/skills export` copies helpers; new `integration-contract.md` with 6 failure policies; 8 shared helpers (arxiv/deepxiv/exa/S2/openalex/save_trace/verify_papers/verify_paper_audits) bundled; `/research-lit` + `/deepxiv` migrated. Plus 4 bug fixes: gpt-5.5+tools 400 on OpenAI; Custom reviewer reset; missing `signature` field ([#228](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/228)); `--version` Build date hardcoded.
- >
- > **v0.4.7** (2026-05-16) — DashScope Coding Plan 405 fixed ([#159](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/159)) via `native-tls` switch ([#225](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/225)); `reasoning_content` replay for all reasoning models (OpenAI o1/o3/o4 / DeepSeek-R1 etc.), not just Kimi ([#226](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/226)); 600+ lines dead code cleanup + `rustyline` dep removed + "Claw Code" → "ARIS-Code" rebrand.
- >
- > **v0.4.6** (2026-05-14) — 🚨 Two long-standing silent bugs fixed: `PermissionMode::Prompt` silently allowed every tool (derived-`Ord` bug); system prompt hardcoded `current_date = "2026-03-31"` made models reject post-cutoff data as future/prompt-injection. Plus Custom OpenAI-compatible provider (`/setup` option 11) with dynamic `/models` discovery ([@Anduin9527](https://github.com/Anduin9527) [#221](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/221) + [#222](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/222)).
- >
- > **v0.4.5** (2026-05-13) — First-class reasoning-model support: thinking content blocks end-to-end (fixes [#161](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/161)) + `reasoning_effort='xhigh'` for GPT-5.5 / o1 / o3 / o4 / DeepSeek-thinking. DeepSeek V4 Pro + Xiaomi MiMo + Qwen 3.6 + Doubao in `/setup` (options 7-10). Object-style hooks parser. Default model bumped to Claude Opus 4.7 + GPT-5.5. REPL input hardening (multi-line wrap / Cmd+V paste / CJK boundary). GitHub Actions CI. Credits: [@GO-player-hhy](https://github.com/GO-player-hhy) ([#186](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/186)), [@Jxy-yxJ](https://github.com/Jxy-yxJ) ([#171](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/171)), [@GetIT-Sunday](https://github.com/GetIT-Sunday) ([#216](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/216) partial).
- >
- > </details>
- >
- > <details><summary>Older versions</summary>
- >
- > **v0.4.4** (2026-04-20) — **Setup UX + reviewer routing fixes** (resolves [#158](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/158), [#162](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/162)) | `/setup` no longer forces Bearer for Anthropic + custom URL | Provider-aware proxy URL hints | Stale state no longer leaks across provider switches | LlmReview smart fallback
- >
- > **v0.4.3** (2026-04-17) — **Third-party Anthropic-compat proxy support** (Bedrock etc.) | Skip beta flags that proxies reject | Propagate custom base URL for `anthropic` provider | Credit [@screw-44](https://github.com/screw-44)
- >
- > **v0.4.2** (2026-04-17) — **Auto-compaction corruption fix** | Compaction summary preserved on OpenAI-compat executors | Shell-provided API keys no longer erased on launch
- >
- > **v0.4.1** (2026-04-15) — **Plan mode** (`/plan`) | Cooperative Ctrl+C interrupt | Auto-retry (429/5xx/network) | **Research Wiki** 📚 (persistent knowledge base) | **Self-Evolution** 🧬 (`/meta-optimize`) | Local models (LM Studio/Ollama) | 62 skills synced
- >
- > **v0.3.11** (2026-04-13) — Reviewer Anthropic-compatible mode (Claude via proxy)
- >
- > **v0.3.9** (2026-04-11) — Proxy/custom base URL (CCSwitch) | Local models (LM Studio/Ollama) | Windows (experimental)
- >
- > **v0.3.5** (2026-04-08) — **Research Wiki** (persistent papers/ideas/experiments/claims + relationship graph) | **Meta-Optimize** self-evolution (analyze logs → propose SKILL.md patches)
- >
- > **v0.3.0** (2026-04-03) — Multi-file memory index | Rich task system (TodoWrite) | `/plan` | Security hardening
- >
- > **v0.2.2** (2026-04-03) — `/plan` step-by-step planning | `/tasks` persistent tracking
- >
- > **v0.2.1** (2026-04-03) — Persistent Memory | Kimi K2.5 multi-turn fix | CJK cursor fix
- >
- > **v0.2.0** (2026-04-02) — Open source | Kimi + MiniMax + GLM support | Smart LlmReview routing | CI/CD
- >
- > **v0.1.0** (2026-04-02) — Initial release | Multi-executor & reviewer | 42 bundled skills
- >
- > </details>
- </details>
- 
- 
- [中文版 README](README_CN.md) | English
- > 🌙 **Let Claude Code do research while you sleep.** Wake up to find your paper scored, weaknesses identified, experiments run, and narrative rewritten — autonomously.
- >
- > 🪶 **Radically lightweight — no infrastructure, zero lock-in.** The entire skill layer is plain Markdown files. No framework to learn, no database to maintain, no Docker to configure, no daemon to babysit. Every skill is a single `SKILL.md` readable by any LLM — swap Claude Code for [Codex CLI](skills/skills-codex/), [OpenClaw](docs/OPENCLAW_ADAPTATION.md), [Cursor](docs/CURSOR_ADAPTATION.md), [Trae](docs/TRAE_ARIS_RUNBOOK_EN.md), [Antigravity](docs/ANTIGRAVITY_ADAPTATION.md), [Copilot CLI](docs/COPILOT_CLI_ADAPTATION.md), Windsurf, or your own agent and the workflows still work. Fork it, rewrite it, adapt it to your stack.
- > 💭 **Why not self-play with a single model?** Using Claude Code subagents or agent teams for both execution and review is technically possible, but tends to fall into **local minima** — the same model reviewing its own patterns creates blind spots.
- >
- > *Think of it like adversarial vs. stochastic bandits: a single model self-reviewing is the stochastic case (predictable reward noise), while cross-model review is adversarial (the reviewer actively probes weaknesses the executor didn't anticipate) — and adversarial bandits are fundamentally harder to game.*
- >
- > 💭 **Why two models, not more?** Two is the minimum needed to break self-play blind spots, and 2-player games converge to Nash equilibrium far more efficiently than n-player ones. Adding more reviewers increases API cost and coordination overhead with diminishing returns — the biggest gain is going from 1→2, not 2→4.
- >
- > Claude Code's strength is fast, fluid execution; Codex (GPT-6-Astra xhigh) is slower but more deliberate and rigorous in critique. These complementary styles — **speed × rigor** — produce better outcomes than either model talking to itself.
- >
- > 🧿 **Want the strongest possible reviewer?** Add `— reviewer: oracle-pro` to any skill to route reviews through **GPT-5.5 Pro** via [Oracle MCP](https://github.com/steipete/oracle). Pro-level reasoning for proof verification, experiment auditing, and final stress tests. Works with API key or free browser mode. [Setup →](#-optional-gpt-54-pro-via-oracle)
- <a id="contents"></a>
- ## Contents
- 1. [More Than Just a Prompt](#more-than-just-a-prompt)
- 2. [What's New](#whats-new) · changelog
- 3. [Quick Start](#quick-start) · install + first run
- 4. [Features](#features)
- 5. [Score Progression (Real Run)](#score-progression)
- 6. [Community Showcase — Papers Built with ARIS](#community-showcase)
- 7. [Awesome Community Skills & Extensions](#awesome-community-skills)
- 8. [Workflows](#workflows) · 13 named pipelines (W1 / W1.5 / W2 / W3 / W4 / W5 / W6 / Wiki / WM + Effort / Assurance / Oracle)
- 9. [Setup](#setup) · prerequisites / install / update / usage / [GPU server config](#gpu-server-setup)
- 10. [Customization](#customization) · per-skill config knobs
- 11. [Alternative Model Combinations](#alternative-model-combinations) · GLM / MiniMax / Kimi / etc.
- 12. [Community](#community)
- 13. [Citation](#citation)
- 14. [Star History](#star-history)
- 15. [Acknowledgements](#acknowledgements)
- 16. [License](#license)
- ---
- <a id="more-than-just-a-prompt"></a>
- ## 1. 🎯 More Than Just a Prompt
- > These are full pipelines — you can also use each workflow independently. Already have an idea? Skip to Workflow 1.5. Have results? Jump to Workflow 3. Got reviews? Jump to Workflow 4. Want persistent memory? Enable [Research Wiki](#-research-wiki--persistent-research-memory). See [Quick Start](#quick-start) for all commands and [Workflows](#workflows) for the full breakdown.
- <a id="how-to-run"></a>
- **Basic mode** — give ARIS a research direction, it handles everything:
- ```
- /research-pipeline "factorized gap in discrete diffusion LMs"
- ```
- **🔥 Targeted mode** — got a paper you want to improve? Give ARIS the paper + the code:
- ```
- /research-pipeline "improve method X" — ref paper: https://arxiv.org/abs/2406.04329, base repo: https://github.com/org/project
- ```
- ARIS reads the paper → finds its weaknesses → clones the codebase → generates ideas that specifically fix *those* weaknesses with *that* code → runs experiments → writes your paper. Like telling a research assistant: *"read this paper, use this repo, find what's missing, and fix it."*
- > Mix and match: `ref paper` only = "what can be improved?", `base repo` only = "what can I build with this code?", both = "improve *this* paper using *this* code."
- **🛠️ Build a feature** — already know what to build?
- ```
- /research-implement-feature "add KV-cache reuse to the decoder" — base repo: https://github.com/org/project
- ```
- Spine first, then one feature at a time, each with a runnable check. Every choice the request left open is written to an assumption ledger before the code that depends on it, and a different model family then reads the raw diff for the ones that went undeclared. It reports "the checks passed", never "the method works". Contributed by [@heroarmor](https://github.com/heroarmor).
- **🔥 Rebuttal mode** — reviews just dropped? Don't panic. ARIS reads every concern, builds a strategy, and drafts a rebuttal that's grounded, structured, and under the character limit:
- ```
- /rebuttal "paper/ + reviews" — venue: ICML, character limit: 5000
- ```
- Three safety gates — rebuttal will NOT finalize if any fails:
- - 🔒 **No fabrication** — every claim maps to paper/review/user-confirmed result
- - 🔒 **No overpromise** — every promise is user-approved
- - 🔒 **Full coverage** — every reviewer concern is tracked
- Two outputs: `PASTE_READY.txt` (exact char count, paste to venue) + `REBUTTAL_DRAFT_rich.md` (extended version for manual editing).
- <details>
- <summary><b>Show rebuttal parameters</b> — venue, character limit (required), quick mode, auto experiment, stress test rounds, followup rounds</summary>
- | Parameter | Default | What it does |
- |-----------|---------|-------------|
- | `venue` | `ICML` | Target venue (ICML/NeurIPS/ICLR/CVPR/ACL/AAAI/ACM) |
- | `character limit` | — | **Required.** Hard character limit for rebuttal text |
- | `quick mode` | `false` | Stop after parsing + strategy (Phase 0-3). See what reviewers want before drafting |
- | `auto experiment` | `false` | Auto-run supplementary experiments via `/experiment-bridge` when reviewers ask for new evidence |
- | `max stress test rounds` | `1` | How many times GPT-6-Astra xhigh stress-tests the draft |
- | `max followup rounds` | `3` | Per-reviewer follow-up round limit |
- </details>
- **After acceptance** — your paper is in, now prepare the presentation:
- ```
- /paper-slides "paper/" # → Beamer PDF + PPTX + speaker notes + Q&A prep
- /paper-poster-html "paper/" # → measurement-gated HTML/CSS poster → print-ready PDF
- ```
- > *💡 From idea to paper to podium — one toolchain. 🌱*
- <a id="whats-new"></a>
- ## 2. 📢 What's New
- > ⚠️ For updates to ARIS bundled skills, run `bash tools/smart_update.sh --apply` (Codex: `smart_update_codex.sh`). For external components, follow the setup linked in their entry.
- - **2026-11-04** — 🔎 **Community spotlight: Absent Author** — an evidence catalog and two skills for author self-checks and reviewer screening of AI-assisted papers. [Meet the project →](#absent-author)
- - **2026-11-01** — ⏱️ **Goal Pulse for Codex Goals** — [HERO's Goal Pulse](https://github.com/wanshuiyin/HERO-Anti-OverDefense/tree/main/skills/goal-pulse) keeps long Goals moving with bilingual reminders every 30 minutes. On Goal start, resume, or takeover of an active Goal, the main agent reads and enables it for the current thread by default; no separate request is needed. Supports compatible Codex app-server setups on macOS/Linux. [Setup and behavior](skills/skills-codex/README.md#goal-pulse-for-codex-goals); HERO maintains the single implementation.
- Full Chinese reminder sent by the timer:
- > 中文:以最快的有效速度持续推进当前 Goal,不允许磨洋工、偷懒、空转,或拿计划和汇报代替执行。
- >
- > worker/子代理一交付完整产物,立即读取、核验,并推进到下一项已授权的验收或交接步骤,不得搁置或等整批。
- >
- > 同一卡点连续两轮无实质进展,主代理立即接管具体缺口或重新拆分,同时推进其它独立任务。
- >
- > 复用已有成果与有效验证,砍掉重复检查、无收益的 corner case 和包装。
- >
- > 不得降低原目标、难度和验收标准,不得越过授权和预算;直接行动,无需专门回复本提醒。
- - **2026-11-01** — ✍️ **Let Gemini or another configured model draft your paper** — the new [Model Worker MCP](mcp-servers/model-worker/README.md) supports model and reasoning-effort selection through Antigravity, Grok, or Claude Code, with file reading, writing, and same-session revision. Both complete Claude Code and Codex skill packs support the split: the main agent grounds the facts and narrative, the writer drafts the prose, and the reviewer is selected separately. Without an external writer, the main agent writes directly. [HERO and the launch principle](skills/shared-references/writing-principles.md#launch-mindset) guide planning, drafting, and revision: lead with contributions and evidence, state necessary conditions where they apply, and keep the prose clear and direct. ([#486](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/486))
- - **2026-10-19** — 🔀 **Choose reviewers inside the complete Claude Code and Codex skill packs** — use `— reviewer:` or project configuration to select Codex, Gemini/Antigravity, Grok, or Claude Code through your configured reviewer tools. See the [routing guide](skills/shared-references/reviewer-backends.md) and [Codex guide](skills/skills-codex/shared-references/reviewer-backends.md). The [Claude Code MCP bridge](mcp-servers/claude-review/README.md) now respects the requested working directory and records the CLI-reported model, including configured providers such as DeepSeek. Same-family reviews remain provisional. ([#473](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/473), [#472](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/472))
- - **2026-10-19** — 📚 **Catch bibliography field errors with `/citation-crosscheck`** — compare local `.bib` entries with records freshly fetched from paper sources, then export a side-by-side spreadsheet of author, year, venue, DOI, and arXiv ID discrepancies. Available for [Claude Code](skills/citation-crosscheck/SKILL.md) and [Codex](skills/skills-codex/citation-crosscheck/SKILL.md), alongside the existing citation audit. ([#371](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/371); thanks [@dty0606](https://github.com/dty0606))
- - **2026-10-19** — 🔬 **Bounded parallel work for research workflows** — idea generation, literature extraction, and proof checking now share [fan-out rules](skills/shared-references/fan-out-pattern.md): capped worker batches, coverage records, and sequential fallback when parallel execution is unavailable. Workers collect candidates and evidence; designated reviewers retain final judgments. ([#372](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/372); thanks [@Dennis-Huangm](https://github.com/Dennis-Huangm))
- - **2026-10-07** — 🧮 **From a mathematical statement to a checked Lean proof** — new [`/lean-formalize`](skills/lean-formalize/SKILL.md) for Claude Code and [Codex](skills/skills-codex/lean-formalize/SKILL.md). Develop proof routes, connect intermediate lemmas to the original theorem, and deliver reproducible Lean sources with statement and axiom checks. Cross-family reviews target the statement, key arguments, and final assembly. Integrated into five proof/research skills; use it when requested or a concrete proof obligation benefits from formal verification. ([#461](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/461))
- - **2026-10-05** — 🔌 **New [Grok](mcp-servers/grok-exec/README.md) and [Gemini / Antigravity](mcp-servers/antigravity-exec/README.md) MCP bridges** — use your existing CLI login to read files and resume conversations from Claude Code or Codex. ([#454](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/454))
- <details>
- <summary>Earlier updates (2026-03-12 — 2026-09-28, 98 entries)</summary>
- - **2026-09-28** —  📚 **Real papers stop being reported as hallucinated citations** ([#445](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/445), [#447](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/447), [#450](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/450); thanks [@ilya-pershin](https://github.com/ilya-pershin) and [@AfonsoZhang](https://github.com/AfonsoZhang)). arXiv sometimes refuses Python's HTTP client with a 406 for minutes while `curl` gets through; `verify_papers.py` read that refusal as "paper not found" and one user saw a 47% hallucination rate on 38 real papers. A 406 now goes through `curl`, and a refusal (406 / 401 / 403) is `verify_pending`, never `unverified`. Set `SEMANTIC_SCHOLAR_API_KEY` and title checks use it. Seen a suspicious hallucination rate recently? Re-run with `--no-cache` once. Also in this round: five skills can now actually invoke the sub-skills their text tells them to ([#440](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/440), [@Jeremy-xuan](https://github.com/Jeremy-xuan)); concurrent watchdog registrations no longer overwrite each other ([#443](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/443), [@hiro-nikaitou](https://github.com/hiro-nikaitou)); `xhigh` is described as the regular reviewer tier it is ([#442](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/442), [@dreamworld2023](https://github.com/dreamworld2023)).
- - **2026-09-16** —  🧩 **ARIS is a Claude Code plugin now** ([#437](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/437), thanks [@white-drizzle](https://github.com/white-drizzle)). `claude plugin marketplace add wanshuiyin/Auto-claude-code-research-in-sleep` → `claude plugin install aris@aris` → `/aris:setup` once → restart. Setup registers the Codex reviewer bridge that ships inside the plugin, so the reviewer works on codex-cli 0.154+ out of the box. Plugin skills are typed with the prefix (`/aris:idea-discovery`); they call each other by short name internally. Codex CLI reads the same repo as a plugin too (`codex plugin marketplace add …` → `codex plugin add aris@aris`) and gets the Codex-native mirror. Cursor, Trae and DeepSeek Harness keep their own routes.
- - **2026-09-10** —  🔌 **codex-cli 0.154 removed `codex mcp-server` — re-register the `codex` MCP server.** Every ARIS reviewer call went through that entry point; on 0.154+ it now opens the interactive TUI and the MCP handshake fails. ARIS ships its own stand-in, `mcp-servers/codex-exec/server.py`, same tool names and result shape, driving `codex exec` underneath — skills unchanged. Run once: `git pull` in your ARIS clone (older clones do not have the file), then `claude mcp remove codex -s user && claude mcp add codex -s user -- python3 "$HOME/aris_repo/mcp-servers/codex-exec/server.py"` (absolute path of your clone), then restart Claude Code. Step-by-step for new and existing installs in [Quick Start](#quick-start). Works on 0.153 too, so do it before you update. OpenAI's own replacement, the Claude Code plugin, has no `ultra` effort and no per-thread resume, which the deep-audit skills need. Cursor / Trae / Antigravity / Copilot CLI configs: same key, `python3` + that path — see the adaptation docs.
- - **2026-09-07** —  🧠 **Default reviewer is now `gpt-6-astra`.** Every reviewer call that pinned `gpt-5.6-sol` now pins `gpt-6-astra`; the two effort tiers (ultra for the seven deep audits, xhigh everywhere else) are unchanged, and so is the executor — whatever agent you run ARIS in. No access to the model yet? The capability fallback tries `gpt-5.6-sol`, then `gpt-5.5`, both at xhigh — nothing to configure.
- - **2026-09-06** —  🧹 **The installer stops dropping Copilot profiles into every project** ([#431](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/431), thanks [@oblivion-1521](https://github.com/oblivion-1521)). Since 2026-08 every run symlinked two Copilot reviewer profiles into your `.github/agents/` whether or not anything used them — dead files for Claude Code and Codex users, broken links if you committed them. Now they are deployed only while `auto-review-loop` is installed; `--no-agent-profiles` switches them off for good (undo with `--agent-profiles`). Your next re-run removes the links the installer created earlier; files you wrote yourself are never touched.
- - **2026-09-03** —  📣 **Papers are launches, not progress reports** (rules adopted from [anti-defensive-writing-Skill](https://github.com/Adkid-Zephyr/anti-defensive-writing-Skill) by [@Adkid-Zephyr](https://github.com/Adkid-Zephyr) — 🌟 it). The writing contract gains four rules: organize the narrative around the strongest genuine advantage; pick the contest the paper wins; unfavorable numbers stay in the tables, explained as a tradeoff where the evidence supports that and stated neutrally where it does not — never narrated as a defeat; every experiment carries an argumentative duty or leaves the main line; abstract and introduction open with problem → gap → idea → strongest result, and the conclusion never ends on new self-negation. `/auto-paper-improvement-loop` flags the same defects. Indexed under [Awesome Community Skills](#awesome-community-skills).
- - **2026-08-26** —  🧯 **Two over-defense leftovers** ([#425](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/425)). `/research-review` — the one reviewer prompt that never got the scope-limits block — now carries it, and its brief ends with "if the work holds up, say so clearly" instead of bare brutality; the adversarial stance itself is untouched. `/research-pipeline` no longer dies overnight on a missing `VENUE`: ideas, experiments, analysis and the narrative report are venue-independent and run to completion — only paper formatting defers, stamped clearly for a later resume. It had also been declaring `VENUE = ICLR` while forbidding silent defaults; the default is gone.
- - **2026-08-26** —  ✍️ **Papers stop reading like confession letters** ([#423](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/423), [#424](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/424); several rules adopted from [humanize-paper](https://github.com/SyntaxSmith/humanize-paper)). Claims are stated at the strength the evidence earns; generic caveats ("further research is needed") live in Limitations only; "don't mention X" means X is absent — never "we do not address X" in print; results are ordered by argument, not by the order experiments ran.
- - **2026-08-26** —  💡 **The idea pipeline stops killing ideas for having neighbors** ([#419](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/419)–[#422](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/422); community reports). ABANDON now has to name the published paper that already contains your result, and concurrent work is a race — your call, not a veto. Brainstorming runs two generator models (gpt-5.6-sol + gpt-5.5) and unions their ideas, aiming for creative direct attacks instead of corner-case stacks. Search digs as hard as ever.
- - **2026-08-21** —  🔌 **Optional HTTP reviewer fallback for when Codex MCP is unreachable** ([#413](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/413); by [@TheFlashForge](https://github.com/TheFlashForge)). Off by default; fires only when Codex provably never got the request — a timeout doesn't count, that could pay twice for two conflicting verdicts. The fallback reads your actual files and gets *less* trust than Codex, never more.
- - **2026-08-21** —  🧹 **Four community fixes in one day** ([#406](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/406)–[#410](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/410); by [@ZLZLGe](https://github.com/ZLZLGe) and [@JasmineLCY](https://github.com/JasmineLCY)). `AUTO_PROCEED=true` now actually continues on its own; the idea-discovery gate demands a real reviewer receipt, not a checkbox; cached wiki context is scanned right before `/idea-creator` reads it; Codex users with Claude as reviewer get their three paper skills back.
- - **2026-08-09** —  🦆 **Copilot CLI defaults `/auto-review-loop` to its native rubber-duck reviewer** ([#360](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/360), closes [#258](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/258)). Active only inside Copilot CLI sessions; review evidence is revalidated from host events, and same/unknown-family fails closed. The standard Claude Code + Codex setup is untouched.
- - **2026-08-09** —  🚧 **`/idea-discovery` can no longer silently skip a stage** ([#383](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/383), closes [#285](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/285); by [@3mom3](https://github.com/3mom3)). Each of the five stages needs recorded evidence, or the report says `BLOCKED` instead of looking complete.
- - **2026-08-05** —  🈶 **The research wiki handles non-ASCII** ([#386](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/386), [#387](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/387); reported by [@LIMMIL7](https://github.com/LIMMIL7)). cp936-written wikis were unreadable on other machines, and Chinese-only titles collapsed to `<year>_untitled` and got deduped away. Existing UTF-8 wikis unaffected.
- - **2026-08-04** —  🖼️ **Upstream spotlight: [posterly](https://github.com/Chenruishuo/posterly) — the engine behind `/paper-poster-html` — shipped a major design upgrade** (MIT, by [@Chenruishuo](https://github.com/Chenruishuo); ~50 posters at this year's ICML). [GitHub](https://github.com/Chenruishuo/posterly) · [Blog](https://www.tryposterly.com/blog).
- - **2026-08-03** —  🧭 **`/proof-orchestrator` — Workflow 7: proof campaigns with a memory** ([#381](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/381); by [@shenmuxing](https://github.com/shenmuxing), from their [EtaSkill](https://github.com/shenmuxing/EtaSkill)). Stateful local-first proof runs that continue across sessions, with a ready-to-paste GPT Pro handoff when a proof stalls. `/proof-checker` remains the submission gate.
- - **2026-07-15** —  🔗 **Double-blind citation field audit** ([#371](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/371)). New `/citation-crosscheck`: two agents work blind — one reads each cited entry from the local `.bib`, one re-fetches it from the web — and a deterministic gate diffs them field by field (author set+order, year, venue, arXiv-id/DOI), emitting a side-by-side `.xlsx` with `MATCH`/`MINOR`/`MISMATCH`. Complements `/citation-audit` (context-fit); this owns field accuracy.
- - **2026-07-14** —  🐞 **[`/web-debug-search`](skills/web-debug-search/SKILL.md)** (Issue [#211](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/211)). Adds a focused debugging/discovery workflow for GitHub Issues and Discussions: exact and normalized error-string matching, version compatibility tracking, and explicit failure handling. Results are labeled for debugging only and are not paper-citation evidence.
- - **2026-07-14** —  🧩 **Selective install + global helper pointer** ([#366](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/366)). The 81 skills are no longer all-or-nothing — all four installers support group/skill-level picks (`--list-groups`, `--groups X,Y`, `--skills X`, `--exclude Y`, or a bare-TTY checkbox picker), with hard pipeline deps auto-included. Updates now confirm each NEW upstream skill individually (`--add-new` / `--skip-new` for scripting; declines are remembered and never re-asked). Also fixes copy installs (`~/.claude/skills`) losing helper-script resolution, via a new `~/.aris/repo` pointer file. ⚠️ Backward compatible — `--quiet` fresh installs still install everything; run any installer/updater once to pick up the pointer file. [Selective install →](#install-skills)
- - **2026-07-12** —  🛡️ **Your paper now gets the reviewer-side forensics treatment before you submit** ([#357](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/357)). New `/integrity-forensics` skill: a SHA-pinned thin launcher runs [Anti-Autoresearch](https://github.com/wanshuiyin/Anti-Autoresearch)'s hostile-reviewer sweep (evidence ledger, nine auditor dimensions, numeric core, rules-only adjudicator) on your paper first. The verdict feeds a typed gate — flags can block a submission, a clean sweep is recorded as "no new blocker" (never an acquittal) — and findings close only with typed, hashed evidence or a recorded human waiver (rewording the flagged sentence doesn't count; the ledger notices). `/paper-writing` runs it by default at submission assurance (`— self_forensics: false` opts out; the Codex mirror is opt-in and limited to upstream's deterministic slice, which can flag but never say CLEAN). ⚠️ First run clones and validates the pinned upstream (needs network); run `bash tools/smart_update.sh --apply`.
- - **2026-07-10** —  🧠 **Reviewer default is now GPT-5.6-Sol; deep audits think at the new `ultra` level** ([#354](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/354)). codex-cli 0.144.1 added `max`/`ultra` reasoning above `xhigh`; ARIS reviews now default to `gpt-5.6-sol`, with the seven heavyweight verdicts (`/proof-checker`, `/kill-argument`, `/research-review`, `/experiment-audit`, `/paper-claim-audit`, `/result-to-claim`, `/meta-apply`) at `ultra` and everything else at `xhigh`. Older codex-cli or no model access steps down automatically (5.6-sol → 5.5, both `xhigh`) — never below `xhigh`, never on a mere timeout. Also fixed: `/result-to-claim` now stops honestly instead of judging its own results when the reviewer is unreachable. ⚠️ Upgrade codex-cli to ≥ 0.144.1, restart the session (MCP reloads only then), and run `bash tools/smart_update.sh --apply`.
- - **2026-07-03** —  🧬 **Three small updates adapted from Anthropic's Claude Science skills** ([#339](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/339), [#340](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/340), [#341](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/341); Apache-2.0). ARIS now has one shared way to describe GPU environments, so the same setup can be reused across SSH machines, Modal, and clusters, then checked by a fresh agent following the setup notes. We also added a small tool that tests whether a skill description actually makes the right skill get picked. Finally, figure and writing checks now separate facts from style: truth checks must pass, style advice stays optional. ⚠️ Run `bash tools/smart_update.sh --apply` to pull.
- - **2026-07-02** —  🔁 **Ideas from Karpathy's LOOPS.md, brought into ARIS** ([#333](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/333)–[#337](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/337)). Reviewers now start by looking for what may be wrong, not by giving a polite score. If a review result looks strange, ARIS points you to the saved reviewer transcript before you ask the model again. A failed build can be restarted from the plan instead of endlessly patched, while plans, logs, and results are kept. Scoring can now use real good and bad examples, `/meta-optimize` asks what can be removed, and `/paper-writing` agrees on a clear "done" checklist before drafting starts. ⚠️ Run `bash tools/smart_update.sh --apply` to pull.
- - **2026-06-20** —  📚 **Research wiki: all four node layers now have deterministic writers — fixes "re-generated ideas not recorded"** ([#305](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/305), [#306](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/306), [#307](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/307), [#308](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/308)). A user hit a real bug — ideas recorded on the first `/idea-creator` run vanished on re-generation — because wiki pages were written **freehand**, a prose step the model skips on a re-prompt. Each layer now has a dedicated `research_wiki.py` writer joining `ingest_paper`: **`add_claim`** (claims born at [`/proof-checker`](skills/proof-checker/SKILL.md)), **`upsert_idea`** ([`/idea-creator`](skills/idea-creator/SKILL.md)), **`add_experiment`** ([`/result-to-claim`](skills/result-to-claim/SKILL.md)) — each guarded by a drift-check so it can't silently regress to dead code. A claim's `status` is now a strict **proof axis** (`verified`/`refuted`/`unproven`/…) while experiment support is carried by `supports`/`invalidates` **edges** (closing a latent contradiction the shared validator rejected), and the **Codex-CLI skill mirror is synced** to match. **Zero behavior change** when no `research-wiki/` is present.
- - **2026-06-19** —  🛰 **Overnight loops can now notice when they die or get stuck** ([#300](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/300), [#301](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/301), [#302](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/302); adapted from operational patterns in [Deli Chen's AutoResearch](https://victorchen96.github.io/auto_research/framework.html)). A new [watchdog](tools/watchdog.py) checks whether an unattended loop is still updating its state file and writes an alert when it goes quiet; it only reports the problem, never restarts a verdict-bearing run. A separate [iteration log](tools/iteration_log.py) watches for rounds that stop finding anything new: two empty rounds force a change of direction, four call in a human, and the cross-model jury still decides whether the result is actually good enough.
- - **2026-06-07** —  🖼️ **[`/paper-poster-html`](skills/paper-poster-html/SKILL.md) is now the default poster pipeline; the old LaTeX [`/paper-poster`](skills/paper-poster/SKILL.md) is retired.** It builds the poster as one HTML/CSS file at the venue's real print size, then runs measured layout and asset checks before a content reviewer sees it, so review time goes to the science instead of crooked columns. It also ships templates, reusable poster components, and venue token packs; the core gate machinery was adapted from [posterly](https://github.com/Chenruishuo/posterly) (MIT, by [@Chenruishuo](https://github.com/Chenruishuo)). ⚠️ `/paper-poster` now redirects to `/paper-poster-html`; the LaTeX pipeline lives only in git history.
- - **2026-05-31** —  🤝 **Two community tools worth a look.** [Claude Fleet](https://github.com/tianyilt/claude-fleet) ([@tianyilt](https://github.com/tianyilt)) is a local read-only dashboard for keeping track of many Claude Code / Codex windows at once. [posterly](https://github.com/Chenruishuo/posterly) ([@Chenruishuo](https://github.com/Chenruishuo)) builds conference posters as a single HTML/CSS file and exports a print-ready PDF through headless Chromium, no LaTeX needed. Both are listed under [Awesome Community](#awesome-community-skills). 🌟 if they help you.
- - **2026-05-31** —  🛰 **Fourth reviewer backend: Gemini via Antigravity CLI** ([#267](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/267) by [@ZGJY95](https://github.com/ZGJY95)). `— reviewer: agy` routes review through the Antigravity CLI for users without Codex MCP / Oracle — **fail-closed on the cross-model invariant** (recovers + verifies the real Gemini-family model, refuses non-Gemini, binds the recovered transcript to the call via a user-event nonce). Wired into [`reviewer-routing.md`](skills/shared-references/reviewer-routing.md).
- - **2026-05-29** —  ⚙️ **ultracode-native convention layer — fan out for breadth on any runtime tier, keep the cross-model jury sacred**. Three new [`shared-references`](skills/shared-references/) docs decouple *breadth* from *verdict*: [`fan-out-pattern.md`](skills/shared-references/fan-out-pattern.md) (skills generate candidates across same-family Claude subagents — Tier-1 Workflow / Tier-2 Agent / Tier-3 sequential — all ending in the *identical* cross-model jury), [`acceptance-gate.md`](skills/shared-references/acceptance-gate.md) ("a loop can DRIVE, it cannot ACQUIT" — self-judge execution-completeness, never quality/correctness), and [`external-cadence.md`](skills/shared-references/external-cadence.md) (`/loop` & `CronCreate` are fire-control, never a jury). Wired into `/idea-creator`, `/research-lit`, `/proof-checker`, `/kill-argument` (fan-out) plus 16 skills (cadence fence/affordance). Also stripped 48 vestigial `Agent` grants (least-privilege + a drift-check guard), fixed `/idea-creator`'s same-family idea pre-filter, and reconciled an `/auto-review-loop` `OR`→`AND` stop-condition inconsistency. **Non-ultracode users benefit immediately** — fan-out degrades to sequential with the same final jury.
- - **2026-05-28** —  📝 **First blog shipped**: [A Survey on Continuous DLM (2026 H1, 6 papers)](https://wanshuiyin.github.io/ARIS-in-AI-Offer/blogs/continuous_dlm_representation_perspective.html) — long-form bilingual technical survey by Ruofeng Yang (SJTU), written end-to-end through the ARIS-in-AI-Offer workflow (Claude Opus 4.7 + Codex GPT-5.5 xhigh + Gemini auto-gemini-3 cross-model discussion). Compares ELF, ByteDance Cola-DLM, and Flow-Matching family across discrete-DLM problems, the "known-unknown" continuous space idea, training pipeline, architecture / params / shapes, inference grids + Tab 6/7 numerical results, denoising trajectories, and a Field Landscape against Cola-DLM. A 1.7 MB self-contained HTML (no build) — demonstrates the kind of long-form analysis the `/render-html` toolchain can produce.
- - **2026-05-26** —  🌐 **HTML auto-emission activated at 8 workflow checkpoints**. `/idea-discovery`, `/auto-review-loop`, `/research-pipeline`, `/kill-argument`, `/proof-checker`, `/paper-claim-audit`, `/citation-audit`, `/rebuttal` now auto-render their primary MD artifact to a single-file HTML view via [`/render-html`](skills/render-html/SKILL.md). Cost-tiered: interim views use `--no-review`, audit-class / reviewer-facing deliverables keep the full Codex render-fidelity gate. Default on (`RENDER_HTML = true`); per-skill opt-out. Failures non-blocking — source MD stays canonical.
- - **2026-05-26** —  🤝 **Community PR wave — 5 merges this week**. [`/wiki-enrich`](skills/wiki-enrich/SKILL.md) ([#247](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/247) by [@hungchun0201](https://github.com/hungchun0201)) fills paper TODOs `ingest_paper` leaves as scaffolds — Karpathy LLM-wiki principle, fetch chain alphaxiv→deepxiv→arXiv. [Mirror drift checker + CI](tools/check_skills_inventory.py) ([#241](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/241) by [@VeraPyuyi](https://github.com/VeraPyuyi)) keeps main↔mirror in sync. `/research-pipeline` Stage 2/3 unified into `/experiment-bridge` delegation ([#243](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/243) by [@ZBigFish](https://github.com/ZBigFish)) — old inline was a strict subset of the bridge. Windows PowerShell installer parity with reparse-chain inside-repo guard + `-FromOld` legacy migration + Windows CI matrix ([#242](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/242) by [@VeraPyuyi](https://github.com/VeraPyuyi)). Plus [`manual-review` MCP](mcp-servers/manual-review/README.md) ([#246](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/246) by [@ZBigFish](https://github.com/ZBigFish)) — **third reviewer backend `— reviewer: manual`** for zero-cost cross-model review (paste prompt to any non-Claude model: DeepSeek / Kimi / ChatGPT / Gemini / local llama); cross-model invariant guarded by bilingual UI banner + per-session token auth + fail-closed when MCP unavailable.
- - **2026-05-17** —  🐙 **[GitHub Copilot CLI adaptation](docs/COPILOT_CLI_ADAPTATION.md)** — native `SKILL.md` + MCP support, no skill mirror needed. Installer (`install_aris_copilot.sh`) + smart-updater + 13-test suite. Community contribution by [@EarendelH](https://github.com/EarendelH) ([#229](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/229), closes [#214](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/214) / [#227](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/227) / [#203](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/203)).
- - **2026-05-17** —  🛠 **Tools-stability roadmap (Phase 1+2+3) complete** (closes [#176](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/176) / [#177](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/177) / [#178](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/178)). Community reported that helper scripts weren't propagating into user projects after `install_aris.sh`. **Phase 1** — every SKILL.md caller of the 10 canonical helpers now resolves via the strict-safe 3-layer chain `.aris/tools/` → `tools/` → `$ARIS_REPO/tools/` documented in [`integration-contract.md`](skills/shared-references/integration-contract.md) §2 (which also defines 5 failure policies A/B/C/D1/D2/E). **Phase 2** — new [advisory CI lint](.github/workflows/lint-skills-helpers.yml) catches hardcoded `python3 tools/foo.py` patterns in PR-modified SKILL.md (advisory only, never fails CI). **Phase 3** — three single-owner helpers (`figure-spec`, `paper-illustration-image2`, `experiment-queue`) moved into their SKILL's `scripts/` subdirectory; owner SKILLs use Layer 0 `${CLAUDE_SKILL_DIR}/scripts/` ahead of the canonical chain; legacy `tools/` paths retained as `os.execv` Python forwarding shims. **⚠️ Existing users**: no action needed — legacy `tools/` entries are now shims. If you haven't run `install_aris.sh` since 2026-04-30, one idempotent rerun catches everything up.
- - **2026-05-14** —  🩹 **`/paper-plan` + `/paper-write` learn `GAP_REPORT.md` + `<!-- DATA_NEEDED -->` discipline** ([#217](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/217)). When `— style-ref:` is set and the user's project has structural assets (`figures/`, `results/`, `NARRATIVE_REPORT.md`, etc.), `/paper-plan` emits a **Gap Report** mapping the exemplar's section topology + density (from `style_profile.md`) against your actual assets — surfacing slots you have **no evidence to fill** (e.g., "exemplar has 3×4 ablation table, you have no ablation data"). Then `/paper-write` writes `<!-- DATA_NEEDED: <Slot ID> — <description> -->` HTML comments **instead of fabricating content** at missing slots — invisible in the compiled PDF, `grep`-friendly for human triage / `/experiment-bridge` follow-up. Narrow carve-out from the "no placeholders" rule, scoped to GAP_REPORT-listed slots only. Original idea by [@zhangpelf](https://github.com/zhangpelf).
- - **2026-05-14** —  ⚙️ **Default reviewer model: `gpt-5.4` → `gpt-5.5`** across ~30 SKILL.md `REVIEWER_MODEL` defaults. Codex MCP has routed `gpt-5.5` as the default since 2026-04-24; this catches the docs up to runtime. **⚠️ Behavior changes**: (a) `.aris/traces/*` JSONs from prior runs are **not reproducible** — re-runs on 5.5 may emit different `WARN/FAIL` verdicts on borderline cases (reviewer-quality lift, not regression). (b) ChatGPT Plus/Pro monthly quotas drain faster under heavy use. **Fallback**: pass `— reviewer-model: gpt-5.4` per invocation, or pin `REVIEWER_MODEL = gpt-5.4` per skill. Oracle Pro tier (routed via `— reviewer: oracle-pro`) is a separate path and unaffected.
- - **2026-05-13** —  🔍 **[`tools/verify_papers.py`](tools/verify_papers.py) + Pre-Search Verification Protocol — anti-hallucination filter for literature-facing skills**. New helper does 3-layer fallback verification (arXiv batch API up to 40 IDs/request → CrossRef DOI lookup → Semantic Scholar fuzzy title match, default 0.6 word-overlap) and emits 4-state per-paper status (`verified` / `unverified` / `verify_pending` / `error`) plus a top-level verdict aligning with `assurance-contract.md` (`PASS` / `WARN` / `BLOCKED` / `ERROR`). Transient failures (5xx, timeouts, 429) are tagged `verify_pending` and **excluded from the hallucination rate** so network blips don't get conflated with fabricated references. Per-project cache at `<project>/.aris/cache/verify_papers.json` with 30-day TTL; canonical key priority `arxiv:{id_without_version}` → `doi:{lowercase}` → `title:{sha1[:16]}`. New `Pre-Search Verification Protocol` subsection in [`shared-references/citation-discipline.md`](skills/shared-references/citation-discipline.md) makes the split explicit: this protocol is the **fast filter** between SEARCH (Step 1) and full VERIFY (Step 2); `/citation-audit` and `/paper-claim-audit` remain the submission-time audit gates and are not replaced. [`/research-lit`](skills/research-lit/SKILL.md) gets a mandatory `Step 1.5: Verify Candidate Papers` calling the helper; [`/idea-creator`](skills/idea-creator/SKILL.md) and [`/novelty-check`](skills/novelty-check/SKILL.md) add a Key Rule reference for cited Closest Prior Work / landscape entries. Unverified papers are **retained** in output tagged `[UNVERIFIED]` (retention-over-silent-removal) so search-quality issues stay visible. Set `ARIS_VERIFY_EMAIL` in your shell to lift CrossRef to the polite-pool rate. Original signal from [@YiwenZhu77](https://github.com/YiwenZhu77) in [#120](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/120) — landed via clean reimplementation rather than direct merge (PR was 5 weeks old + scope creep into figure-style).
- - **2026-05-06** —  🎤 **[`/paper-talk`](skills/paper-talk/SKILL.md) workflow + [`/slides-polish`](skills/slides-polish/SKILL.md) skill — end-to-end conference talk pipeline**. `/paper-talk` orchestrates paper → slide outline → Beamer + PPTX → per-page polish → assurance audits → final report (sister to `/paper-writing`, `/paper-poster`); composes `/paper-slides`, `/slides-polish`, plus `/paper-claim-audit` + `/citation-audit` when `assurance: conference-ready`. `/slides-polish` is the post-generation visual pass: per-page Codex review against a reference PDF + a fix-pattern catalog (PPTX font scaling 1.5-1.8× for projector-readable size, text-frame resize after font bump, banner-as-tcolorbox, italic style leak guard, em-dash spacing, Chinese EA font hint via PingFang SC, anonymity placeholder discipline). Assurance ladder `draft / polished (default) / conference-ready` is independent from the effort axis; `effort: lite, assurance: conference-ready` is legal and means "fast pipeline, every audit must emit verdict before final". Phase 4 staging adapter materializes slide text + speaker notes + talk script as a synthetic paper directory (`.aris/paper-talk/audit-input/sections/*.tex` + symlinked `.bib` / `results/` / `figures/`) so the existing audits run with their paper-shaped contracts and emit 6-state JSON verdicts per `shared-references/assurance-contract.md`.
- - **2026-05-05** —  🔁 **`/resubmit-pipeline` — Workflow 5: text-only resubmit across venues** ([#208](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/208)). Port a polished paper from one venue to another under hard constraints (no new experiments, no bib edits, no framework changes, never overwrite prior submissions). 5 phases: physical isolation → 5-layer anonymity check → audits (proof / claim / citation `--soft-only`) → microedits via `/auto-paper-improvement-loop --edit-whitelist` with per-round diff gate → adversarial gate via `/kill-argument` → final compile + Overleaf push via `/overleaf-sync`. Two prerequisite SKILL upgrades shipped in the same PR: **`/auto-paper-improvement-loop --edit-whitelist <path>`** (YAML schema with allowed/forbidden paths + `forbidden_operations` like `new_cite` / `new_theorem_env` / `numerical_claim`, `forbidden_deletions`, `requires_user_approval_for`, `max_edits_per_round`) and **`/citation-audit --soft-only`** (translates KEEP/FIX/REPLACE/REMOVE verdicts to text-rewrite proposals when bib is frozen; hallucinated citations get `drop_cite_in_body_only` action). Master `RESUBMIT_REPORT.json` ledger per `shared-references/assurance-contract.md`; 7-verdict failure mode table including `USER_DECISION` runtime state.
- - **2026-05-05** —  🗡 **`/kill-argument` — adversarial Attack-Adjudication review for theory papers** ([#206](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/206)). Two fresh codex 5.5 + xhigh threads: Thread 1 writes the strongest 200-word rejection memo a senior area chair would produce; Thread 2 (independent adjudicator, NOT defender) reads the current paper and classifies each rejection point as `answered_by_current_text` / `partially_answered` / `still_unresolved` with file:line evidence. Output: `KILL_ARGUMENT.{md,json}`, detect-only. Integrated as **Phase 5.6** of `/paper-writing` (between claim-audit and citation-audit) and as the canonical implementation called from `/auto-paper-improvement-loop` Step 5.5 — replaces inline prompt in both places. Mandatory at `assurance: submission` for theory-heavy / scope-heavy papers; emits `NOT_APPLICABLE` for empirical papers without scope claims. Audit JSON is `verify_paper_audits.sh`-compatible (full schema per `shared-references/assurance-contract.md`, 6-state verdict). Catches the failure mode score-based reviews miss: when every local component is correct (numbers match, cites resolve, theorems prove) but the paper still oversells what it actually establishes.
- - **2026-05-04** —  🪲 **`/research-wiki` and 8 caller skills now resolve helper via fallback chain** ([#204](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/204)). Bug: after `bash tools/install_aris.sh` the helper lives at `.aris/tools/research_wiki.py` (symlink), but skills hard-coded `tools/research_wiki.py` and silently failed when invoked — `research-wiki/` stayed empty across full W1 runs. Fix: 3-layer chain (`.aris/tools/` → `tools/` → `$ARIS_REPO/tools/`) codified in [`shared-references/wiki-helper-resolution.md`](skills/shared-references/wiki-helper-resolution.md). The manual-copy workaround at `<project>/tools/research_wiki.py` is layer 2, so users who `cp`-installed the helper as a temporary fix continue to work. **⚠️ Existing users**: rerun `bash tools/install_aris.sh` once — also picks up a separate Python 3.9 `ImportError` fix in the helper.
- - **2026-05-03** —  🎨 **Opt-in `— style-ref: <source>` for writer-side skills** ([#202](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/202)). `/paper-{plan,write,writing,illustration,poster,slides}`, `/grant-proposal`, and `/auto-paper-improvement-loop` accept an optional `— style-ref: <source>` argument that mimics a reference paper's *structural* style (section ordering, theorem/figure density, sentence cadence, citation style) **without copying its prose, claims, or terminology**. Sources: local `.tex` dir/file, local PDF, arXiv id (`2501.12345` or `arxiv:2501.12345`), HTTP/HTTPS URL. Overleaf URLs/IDs are rejected — clone via `/overleaf-sync setup <id>` first. **Default OFF**; existing behavior unchanged when the flag is absent. Reviewer / auditor sub-skills (`/proof-checker`, `/paper-claim-audit`, `/citation-audit`, the improvement-loop reviewer) never see the style ref — cross-model review independence preserved. **⚠️ Existing ARIS users**: the helper ships at `tools/extract_paper_style.py`, distributed via the `.aris/tools` symlink (`install_aris.sh` Phase 0, added in [#192](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/192)). **Re-run `bash tools/install_aris.sh` once** to refresh the symlink and pick up the helper. Manual fallback: `cp <ARIS-repo>/tools/extract_paper_style.py <your-project>/tools/`. Without either, the writer skill aborts with a clear error pointing here.
- - **2026-05-02** —  🪨 **Community spotlight: [rosetta](https://github.com/SyntaxSmith/rosetta)** by [@SyntaxSmith](https://github.com/SyntaxSmith). Programmatic access to **ChatGPT Pro / `gpt-5.5-pro` / DeepResearch** from Node, via Chrome CDP Fetch interception + WebSocket second-leg streaming; ships an MCP server for Claude Code / Codex / Cline. Alternative implementation path to Oracle MCP for ARIS users invoking `— reviewer: oracle-pro` — same target capability (Pro-tier reviewer), different mechanics. Indexed under [Awesome Community Skills & Extensions](#awesome-community-skills). 🌟 if you're using it!
- - **2026-05-02** —  💎🧿 **Model & MCP routing updates**. (a) [`/gemini-search`](skills/gemini-search/SKILL.md) default bumped to `gemini-3-pro-preview` (strongest Gemini, out-of-box). ⚠️ **Action required**: requires `gemini-cli` v0.40+ (run `gemini --version`; upgrade with `npm i -g @google/gemini-cli` if older). Legacy override: `/gemini-search "topic" — model: gemini-2.5-pro`. Other overrides: `gemini-3-flash-preview` (faster), `auto-gemini-3` (load-routed). (b) [`/idea-discovery`](skills/idea-discovery/SKILL.md) Phase 1 now includes Gemini in its literature survey by default ([#199](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/199)) — auto-injects `— sources: all, gemini` into `/research-lit` unless the user passed an explicit `— sources:`; graceful skip if `gemini-cli` not installed. (c) Oracle MCP upstream PR queue ([`steipete/oracle/pulls`](https://github.com/steipete/oracle/pulls)) is the first triage stop when invoking `— reviewer: oracle-pro` (especially `o3-deep-research` / `gpt-5.5-pro`) — ARIS does not vendor Oracle MCP; check upstream first if behavior surprises you ([reviewer-routing.md](skills/shared-references/reviewer-routing.md))
- - **2026-05-02** —  🛠️🔗 **Tools-infrastructure migration started**. (a) [`install_aris.sh`](tools/install_aris.sh) creates optional `.aris/tools` symlink ([#192](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/192), closes [#174](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/174)) — Phase 0 of the 4-step tools-stability plan (#174 → #176 → #177 → #178); idempotent, **zero impact until rerun**. (b) [`/experiment-queue`](skills/experiment-queue/SKILL.md) orchestration paths repaired ([#193](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/193)) — first real user of the symlink; 7 cascading bugs fixed via 3 rounds of Codex MCP `gpt-5.5` xhigh audit. Pure prose + docstring; `queue_manager.py` logic untouched. Windows `install_aris.ps1` parallel update tracked as follow-up
- - **2026-05-02** —  🔬 **Three new opt-in audit flags via fast-path delegated-agent workflow** ([#187](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/187), [#188](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/188), [#189](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/189)). [`/citation-audit --uncited`](skills/citation-audit/SKILL.md) surfaces bib entries with no `\cite{}` reference (detect-only). [`/proof-checker --deep-fix`](skills/proof-checker/SKILL.md) adds a repair-grade plan to the Phase 1 reviewer prompt (corrected statement / patch plan / closure tests + Schur/quadratic-form algebra sanity). [`/proof-checker --restatement-check`](skills/proof-checker/SKILL.md) adds Phase 3.6 cross-location theorem drift detection (6 drift signatures). **Zero behavior change** when flags unset. Plus doc PRs [#190](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/190) (thread-policy) + [#191](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/191) (auto-loop xref). Delegated-agent + maintainer-fixup pattern; Codex MCP `gpt-5.5` xhigh review caught 6+ blockers
- - **2026-05-01** —  🔍 **Gemini + OpenAlex literature sources for `/research-lit`** ([#175](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/175), community contribution by [@stdAri](https://github.com/stdAri)). Two opt-in sources: [`/gemini-search`](skills/gemini-search/SKILL.md) (AI-driven discovery via [`jamubc/gemini-mcp-tool`](https://github.com/jamubc/gemini-mcp-tool) MCP) and [`/openalex`](skills/openalex/SKILL.md) (250M+ work open citation graph, no API key). Triggered via `— sources: gemini` or `— sources: openalex`; **zero behavior change** when default `all` (both excluded). Maintainer fixups: corrected `@google/gemini-cli` npm name; added `try/except ImportError` + bash preflight for graceful OpenAlex skip when `requests` missing
- - **2026-04-30** —  📝 **`/rebuttal` per-reviewer thread mode + transferable patterns** ([SKILL.md](skills/rebuttal/SKILL.md)). Adds `VENUE_MODE` (`single_document` | `per_reviewer_thread`) for OpenReview-style venues, `reviewer_priority: pivotal` routing, `structural_distinction` response mode, 5 reviewer-defensive heuristics, 2 Phase 5 lints, and severity-scaled stress rounds. Default `VENUE_MODE = single_document` keeps ICML-style behavior — **zero change for existing users**. Three rounds of cross-model review before/after merge
- - **2026-04-30** —  🪞 **Codex skill mirror rebuilt + dedicated install/update chain** ([#179](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/179), community contribution by [@No-518](https://github.com/No-518)). `skills/skills-codex/` now mirrors all 67 mainline skills; replaces `mcp__codex__codex` reviewer path with Codex-native `spawn_agent` + `send_input`. New [`tools/install_aris_codex.sh`](tools/install_aris_codex.sh) + [`tools/smart_update_codex.sh`](tools/smart_update_codex.sh) handle project-local symlinks with manifest tracking. Anti-drift: `tests/test_codex_skill_mirror.py` + `tests/test_codex_install_update.py` (26 failure paths). Open discussion in [#184](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/184)
- - **2026-04-24** —  🎨 **[`/paper-illustration-image2`](skills/paper-illustration-image2/SKILL.md)** — Codex-native image generation as Phase 2b illustration backend ([#166](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/pull/166), community contribution by [@kbr19-thu](https://github.com/kbr19-thu) 清华). Uses ChatGPT Plus/Pro quota via local [Codex app-server MCP bridge](mcp-servers/codex-image2/) — **no `GEMINI_API_KEY` required**. Triggered by `/paper-writing — illustration: codex-image2`; default stays `figurespec` (**zero behavior change**). Async-only API, sandboxed writes to `figures/ai_generated/`, [integration-contract](skills/shared-references/integration-contract.md)-compliant helper. Marked **experimental** (Codex debug app-server is unstable upstream)
- - **2026-04-21** —  📚 **Research Wiki ingest actually works now** ([`research_wiki.py`](tools/research_wiki.py), [`/research-wiki`](skills/research-wiki/SKILL.md)). Fixes user-reported bug where `/research-wiki init` left `papers/` empty forever (`ingest` subcommand had no implementation; paper-reading skills had no wiki hook). New canonical `python3 tools/research_wiki.py ingest_paper` helper owns slugging / metadata fetch / dedup / page render; all 6 paper-reading skills wired to it. Manual backfill via `sync --arxiv-ids` or `sync --from-file`. Ships with [`integration-contract.md`](skills/shared-references/integration-contract.md) formalizing the six-component pattern every cross-skill integration must follow
- - **2026-04-21** —  🛡️ **Assurance Gate: `— effort: beast | max` now really runs mandatory audits** ([`assurance-contract.md`](skills/shared-references/assurance-contract.md), [`tools/verify_paper_audits.sh`](tools/verify_paper_audits.sh)). Fixes silent-skip of `/proof-checker` / `/paper-claim-audit` / `/citation-audit` at high effort. New `assurance` axis (`draft` | `submission`) independent from `effort`: `lite` / `balanced` → `draft` (**zero behavior change**), `max` / `beast` → `submission`. At submission the 3 audits emit a JSON artifact with 6-state verdict; `paper-writing` Phase 6 runs the external verifier as source of truth (non-zero exit blocks Final Report). SHA256 input hashing catches stale audits. Escape hatch: `— effort: beast, assurance: draft`
- - **2026-04-20** — 🩹 **Project install: flat layout + manifest tracking** — fixes a real bug where the previous nested install (`.claude/skills/aris/`) hid skills from Claude Code's slash-command discovery (CC only scans one directory level). Anyone who ran `install_aris.sh` before this date was silently affected. New `install_aris.sh` creates one symlink per skill at `.claude/skills/<name>`, writes a versioned manifest to `.aris/installed-skills.txt`, and is **re-runnable to reconcile** new/removed upstream skills. Defense-in-depth: 13 safety rules (no-symlinked-parents, exact-target revalidation, slug regex, atomic same-dir manifest rename, no-overwrite-real-files, mkdir-based portable lock, ADOPT for crash recovery, …). Granular `--adopt-existing` / `--replace-link` flags replace the all-or-nothing `--force`. Migration paths: `--from-old` for legacy nested symlink, `--migrate-copy keep-user|prefer-upstream` for legacy nested copy. `smart_update.sh --target-subdir .claude/skills/aris` is now deprecated with a redirect to `install_aris.sh`. Stale-file bug in `cp -r` overlay also fixed (now `rm -rf && cp -r` for safe-update path)
- - **2026-04-19** — 🔗 **[`/overleaf-sync`](skills/overleaf-sync/SKILL.md)** — two-way bridge between local ARIS paper directory and an Overleaf project via the official **Overleaf Git bridge** (Premium). Lets collaborators keep editing in the Overleaf web UI while ARIS audit/edit pipelines (`/paper-claim-audit`, `/citation-audit`, `/auto-paper-improvement-loop`) keep running locally. Sub-commands: `setup` (one-time, user-driven so the agent never sees the token) / `pull` (with diff-protocol — flags half-sentences, typos, claim/cite changes that should re-trigger audits) / `push` (with confirmation gate before writing to shared Overleaf state) / `status` (3-way divergence check). **Token never touches the agent or any file** — primed once into macOS Keychain via the user's terminal, then auth-free for all subsequent agent operations
- - **2026-04-19** — 📚 **[`/citation-audit`](skills/citation-audit/SKILL.md)** — fourth and final layer of the evidence-and-claim assurance stack (`experiment-audit` → `result-to-claim` → `paper-claim-audit` → `citation-audit`). Fresh cross-family reviewer (gpt-5.4 via Codex MCP) with web/DBLP/arXiv lookup verifies every `\cite{...}` along three independent axes: **existence** (paper resolves at claimed arXiv ID/DOI/venue), **metadata correctness** (authors/year/venue/title match canonical sources), and **context appropriateness** (the cited paper actually establishes the claim it supports — the most diagnostic check). Per-entry verdicts: KEEP / FIX / REPLACE / REMOVE. Auto-integrated into **Workflow 3 Phase 5.8** as the pre-submission bibliography gate. Empirical motivation: in a real submission run, several real papers were cited in contexts they did not actually support, and at least one entry shipped with `author = "Anonymous"` — none caught by metadata-only checks
- - **2026-04-17** — 🔀 **`/experiment-queue` integrated into Workflow 1.5 + research-pipeline** — `experiment-bridge` Phase 4 Deploy now auto-routes by milestone job count: ≤5 jobs → `/run-experiment`, ≥10 jobs or phase dependencies → `/experiment-queue` (with OOM retry, stale-screen cleanup, wave-transition gating, crash-safe state). New `--- batch: queue` override for global force-queue mode. Large multi-seed sweeps from `EXPERIMENT_PLAN.md` (e.g., 36-cell `N × seed × n_train` grids) now get proper orchestration without manual queue invocation
- - **2026-04-17** — 🔗 **[Project-local symlink install](tools/install_aris.sh)** (resolves [#118](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/118)) — new recommended default install. `bash tools/install_aris.sh` auto-detects platform (Claude Code / Codex CLI), creates `.claude/skills/aris` or `.agents/skills/aris` symlink to the ARIS repo, adds a managed `<!-- ARIS:BEGIN -->` block to `CLAUDE.md` / `AGENTS.md` telling the agent to use only project-local skills, and records install metadata in `.aris/skill-source.txt`. **Solves the skill collision problem** when ARIS is mixed with Superpowers / OpenHands / other community packs in the same global skill directory. PowerShell version (`install_aris.ps1`) ships with junction support for Windows. **`smart_update.sh --target-subdir`** flag added for `.agents/skills/aris` (Codex) project-copy installs; symlinked installs now correctly refuse `smart_update` and direct users to `git pull`. Global install remains supported for power users
- - **2026-04-16** — 🎨 **[`/figure-spec`](skills/figure-spec/SKILL.md)** — deterministic JSON→SVG renderer packaged as a first-class skill. Preferred default for architecture/workflow/pipeline/audit-cascade figures in papers. Shape-aware edge clipping (rect/circle/ellipse/diamond), self-loops, curved edges, multi-line labels with CJK width estimation. Editable vector output, reproducible (same spec → same SVG), no external API. **Phase 2b in Workflow 3 restored**: `illustration: figurespec` (new default) / `gemini` / `mermaid` / `false` — 4-way illustration selector with complementary strengths
- - **2026-04-16** — ⚙️ **[`/experiment-queue`](skills/experiment-queue/SKILL.md)** — SSH job queue for multi-seed/multi-config ML experiments. Designed from real 36-cell NeurIPS sweep pain points: OOM-aware retry with backoff, stale-screen cleanup, wave-transition race prevention, teacher→student phase dependencies, crash-safe scheduler that resumes from JSON state. Declarative grid specs expand automatically (e.g., `N × seed × n_train → 36 jobs`). Configurable `conda_hook` + `gpu_free_threshold_mib` for non-standard environments. Use for ≥10 jobs; `/run-experiment` stays for ad-hoc
- - **2026-04-15** — 🛡️ **Paper Writing Pipeline Hardening** — 10 empirically-motivated patches from a real NeurIPS run. `REVIEWER_BIAS_GUARD=true`: every review round uses a fresh thread (codex-reply inflated 3→8/10). Reviewer Independence Protocol: no fix summaries to reviewer. Step 4.5 Restatement Regression Test: catches theorem drift across fix rounds. Step 5.5 Kill Argument Exercise: final-round adversarial attack/defense for theory papers. Location-aware overfull blocking. Theory Paper Consistency Pass in `/paper-write`. Enforced Bib Hygiene with DBLP/CrossRef validation. Phase 5.5 Mandatory Final Claim Audit as submission gate. **Review Tracing Protocol**: full prompt/response pairs saved to `.aris/traces/` for reviewer-independence audit ([`review-tracing.md`](skills/shared-references/review-tracing.md), [`save_trace.sh`](tools/save_trace.sh)). Inspired by community contribution from @李傲龍
- - **2026-04-15** — 🎨 **[FigureSpec Renderer v2](tools/figure_renderer.py)** — deterministic JSON→SVG figure generation for academic papers. Shape-aware edge clipping (rect/circle/ellipse/diamond), self-loops, curved edges, multi-line labels with CJK width estimation, comprehensive validation (type checks, structure, palette). Went through 5 rounds of Codex review (3/10→7/10). All architecture and workflow diagrams in the ARIS tech report were generated with this pipeline. New `--- mode: vector` for `/paper-illustration` skill
- - **2026-04-14** — 📋 **[`/paper-claim-audit`](skills/paper-claim-audit/SKILL.md)** — zero-context paper-to-evidence verification. Fresh reviewer with NO prior context compares every number in the paper against raw result files. Catches rounding inflation, best-seed cherry-pick, config mismatch, delta errors, scope overclaim. Auto-integrated into Workflow 3 (Phase 4.7). Completes the 3-layer audit chain: `/experiment-audit` (code) → `/result-to-claim` (science) → `/paper-claim-audit` (reporting). 👁️ **Visual PDF review** also added to improvement loop — reviewer now sees compiled PDF, not just LaTeX source. Inspired by [Hermes Agent](https://github.com/NousResearch/hermes-agent/tree/main/skills/research/research-paper-writing)
- - **2026-04-13** — 🧿 **[GPT-5.4 Pro via Oracle](skills/shared-references/reviewer-routing.md)** — `— reviewer: oracle-pro` on any skill for the strongest available reviewer. API mode (fast) or browser mode (free). Supported on: `/research-review`, `/auto-review-loop`, `/experiment-audit`, `/proof-checker`, `/rebuttal`, `/idea-creator`, `/research-lit`. Default stays Codex xhigh. Not installed = zero impact. [Setup →](#-optional-gpt-54-pro-via-oracle)
- - **2026-04-13** — 🔬 **[`/proof-checker`](skills/proof-checker/SKILL.md)** — rigorous mathematical proof verification via cross-model review. 20-category issue taxonomy, two-axis severity, side-condition checklists (DCT/MCT/Fubini/IFT/...), counterexample red team, proof-obligation ledger. Auto-integrated into Workflow 3: detects `\begin{theorem}` and runs before improvement loop. Complements `/proof-writer`
- - **2026-04-10** — ⚡ **[Effort Levels](skills/shared-references/effort-contract.md)** — `— effort: lite | balanced | max | beast`. Controls work intensity across all skills: papers found, ideas generated, review rounds, writing depth. Codex reasoning stays `xhigh` always. `beast` = every knob to maximum for top-venue sprints. Default `balanced` = zero change for existing users. [Details →](#-effort-levels)
- - **2026-04-10** — 🔎 **[DeepXiv integration](skills/deepxiv/SKILL.md)** — progressive paper retrieval via DeepXiv CLI. Opt-in: `— sources: deepxiv` or `— sources: all, deepxiv`. Staged reading: search → brief → head → section. `pip install deepxiv-sdk` to enable. Community contribution by [@DreamEnding](https://github.com/DreamEnding)
- - **2026-04-10** — 🛡️ **[`/experiment-audit`](skills/experiment-audit/SKILL.md)** — cross-model experiment integrity verification. GPT-5.4 reads your eval scripts and results directly, checks for fake ground truth, self-normalized scores, phantom results, and scope inflation ([#131](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/131), [#57](https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep/issues/57)). Advisory — warns loudly, never blocks. `/result-to-claim` auto-reads audit if present. New [experiment-integrity.md](skills/shared-references/experiment-integrity.md) shared reference. **The executor must never judge its own integrity.**
- - **2026-04-10** — 🧠 **[`tools/smart_update.sh`](tools/smart_update.sh)** — intelligent skill updater. Compares local vs upstream, detects personal customizations (server paths, API keys), only updates safe skills. `bash tools/smart_update.sh --apply`
- - **2026-04-10** — 🏆 **Community paper: [UAV-CC](community_papers/UAV-CC.pdf)** — first community paper with full PDF archived. UAV change captioning benchmark for IEEE TGRS by [@wxx827](https://github.com/wxx827). Stack: Claude Opus 4.6 + Codex 5.4 xhigh + Cursor. Papers now archived in `community_papers/`
- - **2026-04-08** — 📚 **[`/research-wiki`](skills/research-wiki/SKILL.md)** — persistent research knowledge base inspired by [Karpathy's LLM Wiki](https://gist.github.com/karpathy/442a6bf555914893e9891c11519de94f). Accumulates papers, ideas, experiments, and claims across the entire research lifecycle with typed relationships. Wiki-aware hooks in `/research-lit` (ingest papers), `/idea-creator` (read wiki + write ideas back), and `/result-to-claim` (update claim status + trigger re-ideation). Failed ideas become anti-repetition memory. **ARIS now learns from its mistakes.**
- - **2026-04-05** — 🧬 **[`/meta-optimize`](skills/meta-optimize/SKILL.md)** — outer-loop harness optimization for ARIS. Passively logs skill invocations, tool calls, failures, and parameter overrides via [Claude Code hooks](templates/claude-hooks/meta_logging.json). Run `/meta-optimize` to analyze accumulated usage data and propose SKILL.md improvements — reviewer-gated, user-approved. Inspired by [Meta-Harness](https://arxiv.org/abs/2603.28052) (Lee et al., 2026). **ARIS now optimizes itself.**
- - **2026-04-04** — 🔧 **Codex Plugin deep integration** — `/codex:rescue` now auto-invoked when experiments fail (Workflow 1.5) or LaTeX won't compile (Workflow 3). GPT independently diagnoses the bug before Claude retries — two AI debuggers are better than one. Optional: `codex exec` powers nightmare review, `/codex:rescue` powers auto-debug. [Setup →](#optional-codex-plugin-for-code-review)
- - **2026-04-03** — ☁️ **[Modal serverless GPU](skills/serverless-modal/SKILL.md)** — no GPU? `gpu: modal` in CLAUDE.md, one command (`modal run launcher.py`), no SSH, no Docker, auto scale-to-zero. **$30/month free tier** — enough to try ARIS experiments without any hardware. `pip install modal && modal setup` and go. Community contribution by [@zeyuzhangzyz](https://github.com/zeyuzhangzyz)
- - **2026-04-03** — 🎮 **Reviewer Difficulty Levels** — `medium` (default, unchanged), `hard` (reviewer memory + debate protocol), `nightmare` (GPT reads repo directly via `codex exec` — Claude can't hide anything). `— difficulty: nightmare` for maximum stress test before submission
- - **2026-03-30** — 🔥 **Auto-debug & exhaust-before-surrender** — experiment-bridge auto-diagnoses failures (OOM, import, CUDA, NaN) and retries up to 3×. Inspired by [PUA](https://github.com/tanweai/pua)
- - **2026-03-30** — ☁️ **[Vast.ai GPU rental](skills/vast-gpu/SKILL.md)** — `gpu: vast` auto-rents cheapest GPU. By [@YIHONG-JIN](https://github.com/YIHONG-JIN). 🔧 MiniMax M2.7 upgrade by [@octo-patch](https://github.com/octo-patch)
- - **2026-03-27** — 📄 **IEEE venue support** (9 families). 🔎 **[Semantic Scholar](skills/semantic-scholar/SKILL.md)**. By [@ypd666](https://github.com/ypd666)
- - **2026-03-26** — 📄 **Document-based input** — `RESEARCH_BRIEF.md` auto-detect
- - **2026-03-24** — 📝 **[Workflow 4: `/rebuttal`](skills/rebuttal/SKILL.md)** — 7-phase pipeline, 3 safety gates
- - **2026-03-23** — 🔧 `/training-check`, `/result-to-claim`, `/ablation-planner` integrated. 📦 `compact` mode. By [@JingxuanKang](https://github.com/JingxuanKang) & [@couragec](https://github.com/couragec)
- - **2026-03-22** — 📋 **[Templates](templates/)** — input templates for every workflow. 📄 **7 venue templates** — CVPR, ACL, AAAI, ACM MM added. 🛡️ **Anti-hallucination fix** — Workflow 2 enforces DBLP → CrossRef → [VERIFY]. 🔗 **`base repo`** — clone a GitHub repo as base codebase (`— base repo: https://github.com/org/project`)
- - **2026-03-22** — 🔍 **[Codex + Gemini review guide](docs/CODEX_GEMINI_REVIEW_GUIDE.md)** — Codex executes, Gemini reviews via local `gemini-review` MCP bridge. [CN](docs/CODEX_GEMINI_REVIEW_GUIDE_CN.md)
- - **2026-03-20** — 🚀 **[Antigravity adaptation guide](docs/ANTIGRAVITY_ADAPTATION.md)** — use ARIS skills in [Google Antigravity](https://antigravity.google/) (agent-first IDE). Community contribution by [@PeppaPigw](https://github.com/PeppaPigw)
- - **2026-03-20** — 🖥️ **[Trae adaptation guide](docs/TRAE_ARIS_RUNBOOK_EN.md)** — use ARIS skills in [Trae](https://www.trae.ai/) (ByteDance AI IDE). Community contribution by [@Prometheus-cotigo](https://github.com/Prometheus-cotigo). 🔢 **[`formula-derivation`](skills/formula-derivation/SKILL.md)** — Community contribution by [@Falling-Flower](https://github.com/Falling-Flower)
- - **2026-03-19** — 🖼️ **[`paper-poster`](skills/paper-poster/SKILL.md)** — Conference poster. Community contribution by [@dengzhe-hou](https://github.com/dengzhe-hou)
- - **2026-03-19** — 🔗 **Workflow 1.5 upgraded** — `/experiment-bridge` GPT-5.4 code review. 📊 **W&B fix**
- - **2026-03-18** — 🎤 `paper-slides` + 🔁 Codex+Claude bridge + 🖱️ Cursor guide + 🤖 Codex CLI skills + 📝 `grant-proposal` + 🎨 `paper-illustration` (Gemini) + 📊 CitationClaw
- - **2026-03-17** — 🔧 Git code sync + 🆓 ModelScope guide + parameter pass-through
- - **2026-03-16** — 🔬 **[`research-refine`](skills/research-refine/SKILL.md)** + [`experiment-plan`](skills/experiment-plan/SKILL.md) — turn vague ideas into problem-anchored proposals with claim-driven experiment roadmaps. Now integrated into Workflow 1 (`/idea-discovery`). Community contribution by [@zjYao36](https://github.com/zjYao36)
- - **2026-03-16** — 🇨🇳 **[Alibaba Coding Plan guide](docs/ALI_CODING_PLAN_GUIDE.md)** — one API key, 4 models (Kimi-K2.5 + Qwen3.5+ + GLM-5 + MiniMax-M2.7), dual-endpoint setup. Community contribution by [@tianhao909](https://github.com/tianhao909)
- - **2026-03-15** — 🔀 **Bring your own model!** [Any OpenAI-compatible API](#alternative-model-combinations) now works as reviewer via [`llm-chat`](mcp-servers/llm-chat/) MCP server. GLM, MiniMax, Kimi, LongCat, DeepSeek all tested — **zero Claude or OpenAI API needed**
- - **2026-03-15** — 🐾 **[OpenClaw adaptation guide](docs/OPENCLAW_ADAPTATION.md)** — use ARIS research workflows in [OpenClaw](https://github.com/All-Hands-AI/OpenHands) without Claude Code slash skills
- - **2026-03-15** — 📐 **[`proof-writer`](skills/proof-writer/SKILL.md)** — community skill for rigorous theorem proof drafting. 📚 **Anti-hallucination citations** — `/paper-write` now fetches real BibTeX from [DBLP](https://dblp.org)/[CrossRef](https://www.crossref.org) instead of LLM-generated entries — on by default, zero install
- - **2026-03-14** — 📱 [Feishu/Lark integration](docs/integrations/FEISHU.md): three modes (off/push/interactive), mobile notifications for experiments, reviews, and checkpoints
- - **2026-03-13** — 🛑 Human-in-the-loop: configurable `AUTO_PROCEED` checkpoints across all workflows. Full autopilot or step-by-step approval
- - **2026-03-12** — 🔗 [Zotero](docs/integrations/ZOTERO.md) + [Obsidian](docs/integrations/OBSIDIAN.md) + local PDFs + arXiv/Scholar: multi-source literature search with cross-model novelty verification
- - **2026-03-12** — 🚀 Three end-to-end workflows complete: one prompt → top-venue-style paper. `/research-pipeline` chains idea discovery → auto review → paper writing autonomously
- - **2026-03-12** — 📝 `/paper-writing` workflow: narrative report → structured outline → figures → LaTeX → compiled PDF → 2-round auto-improvement (4/10 → 8.5/10)
- </details>
- <a id="quick-start"></a>
- <a id="-quick-start"></a>
- ## 3. 🚀 Quick Start
- ```bash
- # 1. Install skills — project-local symlinks (recommended)
- git clone https://github.com/wanshuiyin/Auto-claude-code-research-in-sleep.git
- bash Auto-claude-code-research-in-sleep/tools/install_aris.sh ~/your-project # symlinks ARIS skills into <project>/.claude/skills/
- # (prefer a global install instead? cp -r Auto-claude-code-research-in-sleep/skills/* ~/.claude/skills/)
- # (don't need all 87? --list-groups / --groups X,Y / --skills X — see "Selective install" below)
- # 1b. Update later (when upstream changes)
- cd Auto-claude-code-research-in-sleep && git pull
- bash tools/smart_update.sh --apply # updates safe skills, flags your personal customizations
- # (NEW upstream skills need confirmation — --add-new to accept all non-interactively)
- # Optional Codex mirror managed project install
- bash tools/install_aris_codex.sh ~/your-codex-project
- # Managed Codex project update
- cd Auto-claude-code-research-in-sleep && git pull
- bash tools/install_aris_codex.sh ~/your-codex-project --reconcile
- # Copied Codex installs only (not for projects installed by install_aris_codex.sh)
- bash tools/smart_update_codex.sh --local ~/.codex/skills
- bash tools/smart_update_codex.sh --local ~/.codex/skills --apply
- # 2. Codex reviewer (review skills call GPT through it) — run from the directory you cloned into in step 1
- npm install -g @openai/codex && codex login # one-time ChatGPT login; the reviewer model comes from ~/.codex/config.toml
- claude mcp add codex -s user -- python3 "$(pwd)/Auto-claude-code-research-in-sleep/mcp-servers/codex-exec/server.py"
- # then restart Claude Code; `claude mcp list` must show: codex: python3 …/codex-exec/server.py - ✔ Connected
- # 2b. Already had ARIS before 2026-09-11? codex-cli 0.154 removed `codex mcp-server`, so the old registration is dead.
- cd Auto-claude-code-research-in-sleep && git pull # brings mcp-servers/codex-exec/ (git pull is enough; smart_update only syncs skills)
- claude mcp remove codex -s user
- claude mcp add codex -s user -- python3 "$(pwd)/mcp-servers/codex-exec/server.py"
- # restart Claude Code, check `claude mcp list` as above. Skills need no change. Do it on codex 0.153 too — it works there and survives the update.
- # Cursor / Trae / Antigravity / Copilot CLI: same "codex" key, command python3 + that path — see the adaptation guides in docs/.
- # Installed by copying skills/ without a clone? Clone the repo anywhere and point at its server.py; the file is self-contained.
- # 3. Use in Claude Code
- claude
- > /idea-discovery "your research direction" # Workflow 1 — be specific! not "NLP" but "factorized gap in discrete diffusion LMs"
- > /experiment-bridge # Workflow 1.5 — have a plan? implement + deploy + collect results
- > /auto-review-loop "your paper topic or scope" # Workflow 2: review → fix → re-review overnight
- > /paper-writing "NARRATIVE_REPORT.md" # Workflow 3: narrative → polished PDF
- > /rebuttal "paper/ + reviews" — venue: ICML # Workflow 4: parse reviews → draft rebuttal → follow-up
- > /resubmit-pipeline "paper/" — venue: NeurIPS # Workflow 5: port a polished paper to a new venue (text-only, no new experiments)
- > /paper-talk "paper/" — venue: ICLR # Workflow 6: paper → Beamer + PPTX talk + speaker notes + assurance audits
- > /research-pipeline "your research direction" # Full pipeline: Workflow 1 → 1.5 → 2 → 3 end-to-end
- > /research-wiki init # 📚 Enable persistent research memory (one-time)
- > /meta-optimize # Meta: analyze usage logs → propose skill improvements
- ```
- > Don't need all 87 skills? See [Selective install](#install-skills) below for group/skill-level picks.
- > **Optional Grok CLI bridge:** [`grok-exec`](mcp-servers/grok-exec/README.md) exposes `grok` / `grok-reply` using your existing Grok CLI login, with `grok-4.7` + `xhigh` defaults, persistent sessions, progress and cancellation. It is a separate MCP service; installing it does not change the reviewer routing of existing skills.
- > **Selectable CLI reviewers:** [`antigravity-exec`](mcp-servers/antigravity-exec/README.md) and [`grok-exec`](mcp-servers/grok-exec/README.md) support the complete packs through `— reviewer: antigravity` / `grok`; see the [backend contract](skills/shared-references/reviewer-backends.md). The legacy `— reviewer: agy` still uses `gemini-review`.
- <details>
- <summary><b>📚 Research Wiki (optional)</b> — one-line init for persistent memory across sessions; see <a href="#-research-wiki--persistent-research-memory">full Research Wiki section</a></summary>
- Give ARIS persistent memory across sessions. Papers, ideas, failed experiments — nothing is forgotten:
- ```bash
- # In Claude Code:
- > /research-wiki init # creates research-wiki/ in your project
- # That's it. From now on, /research-lit auto-ingests papers, /idea-creator reads
- # the wiki before brainstorming (and writes ideas back), /result-to-claim updates
- # claim status. Failed ideas become anti-repetition memory for future ideation.
- ```
- </details>
- <details>
- <summary><b>🧬 Meta-Optimization (optional)</b> — passive usage logging + /meta-optimize for data-driven SKILL.md improvements; see <a href="#workflow-m-meta-optimize--aris-optimizes-itself">full Workflow M section</a></summary>
- Run these in your **normal terminal** (not inside Claude Code) to enable passive usage logging:
- ```bash
- # One-time setup in your project directory
- mkdir -p .claude .aris/meta tools/meta_opt
- cp Auto-claude-code-research-in-sleep/templates/claude-hooks/meta_logging.json .claude/settings.json
- cp Auto-claude-code-research-in-sleep/tools/meta_opt/*.sh tools/meta_opt/
- chmod +x tools/meta_opt/*.sh
- # Then start Claude Code — hooks are active immediately
- claude
- ```
- Events are logged to **both** project-level (`.aris/meta/events.jsonl`) and global (`~/.aris/meta/events.jsonl`) logs. After 5+ workflow runs, run `/meta-optimize` to see data-driven improvement proposals. Use `/meta-optimize --global` to analyze trends across all your projects.
- </details>
- <details>
- <summary><b>📝 Templates + 🔎 DeepXiv + 🔎 Exa + 🔎 Keenable + 🔎 Firecrawl + 🗑️ Uninstall</b> — input templates, four extra literature sources, and the uninstall command</summary>
- **📝 Templates available!** See [`templates/`](templates/) for ready-to-use input templates for every workflow — [research brief](templates/RESEARCH_BRIEF_TEMPLATE.md) (Workflow 1), [experiment plan](templates/EXPERIMENT_PLAN_TEMPLATE.md) (Workflow 1.5), [narrative report](templates/NARRATIVE_REPORT_TEMPLATE.md) (Workflow 3), [paper plan](templates/PAPER_PLAN_TEMPLATE.md) (Workflow 3).
- **🔎 Optional: DeepXiv progressive retrieval**
- ```bash
- pip install deepxiv-sdk
- ```
- Then use [`/deepxiv`](skills/deepxiv/SKILL.md) directly or opt into it from `/research-lit` with `— sources: deepxiv` or `— sources: all, deepxiv`.
- **🔎 Optional: Exa AI-powered web search**
- ```bash
- pip install exa-py
- export EXA_API_KEY=your-key-here
- ```
- Then use [`/exa-search`](skills/exa-search/SKILL.md) directly or opt into it from `/research-lit` with `— sources: exa` or `— sources: all, exa`. Covers blogs, docs, news, and research papers with built-in content extraction.
- **🔎 Optional: Keenable web search (no API key needed)**
- ```bash
- export KEENABLE_API_KEY=your-key-here # optional, only raises rate limits
- ```
- Then use [`/keenable-search`](skills/keenable-search/SKILL.md) to search the web (title, URL, and page-text snippet per result) or fetch a URL as markdown. Works without a key and needs no extra Python packages.
- **🔎 Optional: Firecrawl web search and scraping**
- ```bash
- export FIRECRAWL_API_KEY=your-key-here
- ```
- Then use [`/firecrawl-search`](skills/firecrawl-search/SKILL.md) to search the web with full-page markdown for each result, or to scrape a URL (HTML or PDF) to markdown. No extra Python packages needed.
- **🗑️ Uninstall:** To remove ARIS skills without affecting your own personal skills:
- ```bash
- cd Auto-claude-code-research-in-sleep && ls skills/ | xargs -I{} rm -rf ~/.claude/skills/{}
- ```
- </details>
- <details>
- <summary><b>Show all 16 inline parameters and 14 override examples</b> — AUTO_PROCEED / sources / arxiv download / DBLP_BIBTEX / code review / wandb / illustration / venue / base repo / gpu / compact / ref paper / effort / reviewer / difficulty (full per-skill defaults live in <a href="#customization">§ Customization</a>)</summary>
- All pipeline behaviors are configurable via inline overrides — append `— key: value` to any command:
- | Parameter | Default | What it does |
- |-----------|---------|-------------|
- | `AUTO_PROCEED` | `true` | At selection checkpoints, report the top idea and continue in the same turn. Set `false` to ask for explicit approval before committing GPU time |
- | `human checkpoint` | `false` | Pause after each review round so you can read the score, give custom modification instructions, skip specific fixes, or stop early |
- | `sources` | `all` | Which literature sources to search: `zotero`, `obsidian`, `local`, `web`, `semantic-scholar`, `deepxiv`, `exa`, `gemini`, `openalex`, or `all`. Note: `semantic-scholar`, `deepxiv`, `exa`, `gemini`, and `openalex` must be explicitly listed — not included in `all` |
- | `arxiv download` | `false` | Download top relevant arXiv PDFs during literature survey. When `false`, only fetches metadata (title, abstract, authors) |
- | `DBLP_BIBTEX` | `true` | Fetch real BibTeX from [DBLP](https://dblp.org)/[CrossRef](https://www.crossref.org) instead of LLM-generated entries. Eliminates hallucinated citations. Zero install |
- | `code review` | `true` | GPT-6-Astra xhigh reviews experiment code before GPU deployment. Set `false` to skip |
- | `wandb` | `false` | Auto-add W&B logging to experiment scripts. Set `true` + configure `wandb_project` in CLAUDE.md. `/monitor-experiment` pulls training curves from W&B |
- | `illustration` | `gemini` | AI illustration in Workflow 3: `gemini` (default, needs `GEMINI_API_KEY`), `mermaid` (free), or `false` (skip) |
- | `venue` | `ICLR` | Target venue: `ICLR`, `NeurIPS`, `ICML`, `CVPR`, `ACL`, `AAAI`, `ACM`. Determines LaTeX style file and page limit |
- | `base repo` | `false` | GitHub repo URL to clone as base codebase (e.g., `— base repo: https://github.com/org/project`). No code? Build on top of an open-source project |
- | `gpu` | `local` | GPU target: `local` (default), `remote` (SSH server), or `vast` (rent on-demand from [Vast.ai](https://vast.ai) — auto-provision, auto-destroy) |
- | `compact` | `false` | Generate compact summary files (`IDEA_CANDIDATES.md`, `findings.md`, `EXPERIMENT_LOG.md`) for short-context models and session recovery |
- | `ref paper` | `false` | Reference paper to build on (PDF path or arXiv URL). Summarized first, then ideas extend/improve it. Combine with `base repo` for paper+code workflows |
- | `effort` | `balanced` | Work intensity: `lite` (0.4x tokens), `balanced` (default), `max` (2.5x), `beast` (5-8x). Controls breadth/depth/iterations. Codex reasoning never drops below the tier floor (regular `xhigh` / deep audits `ultra`). See [Effort Levels](#-effort-levels) |
- | `reviewer` | auto | Reviewer backend: in Copilot CLI, `/auto-review-loop` auto-binds the native complementary `rubber-duck`; other hosts/skills default to `codex` (GPT-6-Astra, tiered `xhigh`/`ultra`). Explicit `codex`, `manual`, or `oracle-pro` overrides remain available. |
- | `difficulty` | `medium` | Reviewer adversarial level: `medium` (default), `hard` (+ memory + debate), `nightmare` (+ GPT reads repo via `codex exec`) |
- ```
- /research-pipeline "your topic" — AUTO_PROCEED: false # pause at idea selection gate
- /research-pipeline "your topic" — human checkpoint: true # pause after each review round to give feedback
- /research-pipeline "your topic" — sources: zotero, web # only search Zotero + web (skip local PDFs)
- /research-pipeline "your topic" — sources: all, deepxiv # default sources plus DeepXiv progressive retrieval
- /research-pipeline "your topic" — sources: all, exa # default sources plus Exa AI-powered web search
- /research-pipeline "your topic" — sources: all, gemini # default sources plus Gemini discovery
- /research-pipeline "your topic" — sources: all, openalex # default sources plus OpenAlex citation graph
- /research-pipeline "your topic" — arxiv download: true # download top arXiv PDFs during literature survey
- /research-pipeline "your topic" — difficulty: nightmare # maximum adversarial review before submission
- /research-pipeline "your topic" — effort: beast # all knobs to maximum — top-venue sprint
- /research-pipeline "your topic" — effort: beast, reviewer: oracle-pro # beast + GPT-5.5 Pro reviewer — ultimate mode
- /research-pipeline "your topic" — effort: lite # quick exploration, save tokens
- /research-pipeline "your topic" — effort: max, review_rounds: 3 # max effort but cap review at 3 rounds
- /research-pipeline "your topic" — AUTO_PROCEED: false, human checkpoint: true # combine options
- /proof-checker "paper/" — reviewer: oracle-pro # Pro-level proof verification
- ```
- </details>
- <details>
- <summary><b>Sandbox behavior and strict mode</b> — control whether tool-call overrides may change the configured sandbox policy</summary>
- The runtime's `sandbox` settings provide a configured baseline, while a tool request may also carry sandbox-related overrides. In the legacy compatibility mode, the effective request can therefore differ from the values written in `settings.json`.
- To make the configured policy authoritative, enable `strictMode`:
- ```json
- {
- "sandbox": {
- "enabled": true,
- "strictMode": true
- }
- }
- ```
- With `strictMode: true`, the runtime ignores these LLM-supplied overrides: `dangerouslyDisableSandbox`, `namespaceRestrictions`, `isolateNetwork`, `filesystemMode`, and `allowedMounts`. The configured sandbox policy remains in effect even when a tool call requests a different value. This is opt-in so existing configurations keep their legacy behavior by default.
- Run `aris doctor` to inspect the currently reported sandbox state. `strictMode` controls whether tool requests can override the runtime configuration; it does not replace the host operating system's permissions, filesystem protections, or network policy.
- </details>
- <details>
- <summary><b>Codex MCP config + alternative reviewer routing</b> — pin the model in <code>~/.codex/config.toml</code>; pointers to Codex+Claude-review, Codex+Gemini-review, and the Codex mirror install chain</summary>
- **Important:** ARIS skills pin the reviewer explicitly (`model: gpt-6-astra` + a per-tier reasoning effort) in every fresh call — your `~/.codex/config.toml` no longer silently decides the reviewer. Still set `model = "gpt-6-astra"` there (recommended): it covers codex-native/mirror sessions and anything that doesn't pin. `ultra`/`max` effort needs codex-cli ≥ 0.144.1 + a session restart.
- **Choose a reviewer in Codex:** install the full [`skills/skills-codex/`](skills/skills-codex/README.md) pack and select `— reviewer: claude-code`, `antigravity`, or `grok`. See the [backend contract](skills/skills-codex/shared-references/reviewer-backends.md) for bridge setup and session rules.
- The old Claude/Gemini partial overlays are frozen for existing installations; [migrate safely](skills/skills-codex/README.md#migrate-frozen-partial-overlays) to the full pack. The historical [Claude](docs/CODEX_CLAUDE_REVIEW_GUIDE.md) and [Gemini](docs/CODEX_GEMINI_REVIEW_GUIDE.md) guides describe those legacy installations.
- **Want the Codex mirror install chain?** Use `tools/install_aris_codex.sh` for managed project installs and `tools/smart_update_codex.sh` for copied Codex installs. The Claude scripts remain the mainline entry points for Claude projects.
- The base Codex mirror defaults to a fresh Codex reviewer: same-family reviews remain `provisional`. Other routes require actual model identities and a completed, in-scope review before cross-family acceptance; a backend selection alone is insufficient. Submission and deterministic verification gates still apply.
- </details>
- See [full setup guide](#setup) for details and [alternative model combinations](#alternative-model-combinations) if you don't have Claude/OpenAI API.
- <a id="features"></a>
- ## 4. ✨ Features
- ARIS chains **87 composable skills** across the whole research lifecycle — literature & novelty → idea discovery → GPU experiments → autonomous review loop → paper writing → peer review — with **cross-model adversarial review** (Claude executes · GPT-6-Astra xhigh reviews · optional **GPT-5.5 Pro** via Oracle), anti-hallucination DBLP/CrossRef citations, a persistent **Research Wiki**, flexible model backends, human-in-the-loop checkpoints, and optional Feishu / Zotero / Obsidian / GPU integrations.
- 🔥 *And it scales to any agent's **ultracode-style deep mode** — the breadth/firepower pass adapts to the runtime (Claude Code ultracode + workflows on Opus 4.8, Codex `spawn_agent`, or plain sequential), feeding three roles: **breadth · cross-model review → accuracy · research wiki → memory**. However a loop is driven, it reports to the same cross-model jury + research wiki — **it can drive, never acquit**.*
- <details>
- <summary><b>Full feature list</b></summary>
- - 📊 **87 composable skills** — mix and match, or chain into full pipelines (`/idea-discovery`, `/auto-review-loop`, `/paper-writing`, `/research-pipeline`). See [full catalog →](docs/SKILLS_CATALOG.md)
- - 🔍 **Literature & novelty** — multi-source paper search (**[Zotero](docs/integrations/ZOTERO.md)** + **[Obsidian](docs/integrations/OBSIDIAN.md)** + **local PDFs** + arXiv/Scholar) + cross-model novelty verification
- - 💡 **Idea discovery** — literature survey → brainstorm 8-12 ideas → novelty check → GPU pilot experiments → ranked report
- - 🔄 **Auto review loop** — 4-round autonomous review, 5/10 → 7.5/10 overnight with 20+ GPU experiments
- - 📝 **Paper writing** — narrative → outline → figures → LaTeX → PDF → auto-review (4/10 → 8.5/10), one command. Anti-hallucination citations via [DBLP](https://dblp.org)/[CrossRef](https://www.crossref.org)
- - 🤖 **Cross-model collaboration** — Claude Code executes and GPT-6-Astra reviews; in Copilot CLI, `/auto-review-loop` uses the native complementary rubber-duck model and verifies the actual cross-family pair from host events. Optional: `— reviewer: oracle-pro` → **GPT-5.5 Pro** via [Oracle](https://github.com/steipete/oracle)
- - 📝 **Peer review** — review others' papers as a conference reviewer, with structured scoring and meta-review
- - 🖥️ **Review-driven experiments** — when GPT-6-Astra says "run an ablation", Claude auto-writes the script, rsyncs to GPU, runs in `screen`, collects results, folds back into the paper. Configure server in `CLAUDE.md` ([setup](#gpu-server-setup)), or rent from [Vast.ai](https://vast.ai) with `gpu: vast`
- - 🔀 **Flexible models** — default Claude × GPT-6-Astra, also supports [GLM, MiniMax, Kimi, LongCat, DeepSeek, etc.](#alternative-model-combinations) — no Claude or OpenAI API required
- - 🛑 **Human-in-the-loop** — configurable selection checkpoints. `AUTO_PROCEED=true` reports the choice and continues in the same turn; `false` asks for approval. Explicit Feishu interactive gates remain user-controlled
- - 📱 **[Feishu/Lark notifications](docs/integrations/FEISHU.md)** — three modes: **off (default, recommended)**, push-only (webhook → mobile), interactive (approve/reject in Feishu). Zero impact when off
- <details>
- <summary>Preview: Push cards (group) & Interactive chat (private)</summary>
- **Push Only** — group chat cards (experiment done, checkpoint, error, pipeline complete):
- <img src="assets/feishu_push.png" width="700" />
- **Interactive** — private chat with Claude Code (approve/reject, custom instructions):
- <img src="assets/feishu_interactive.jpg" width="700" />
- </details>
- - 📚 **[Research Wiki](#-research-wiki--persistent-research-memory)** — persistent knowledge base across papers/ideas/experiments/claims. Failed ideas become anti-repetition memory — ARIS gets smarter every run. Inspired by [Karpathy's LLM Wiki](https://gist.github.com/karpathy/442a6bf555914893e9891c11519de94f)
- - 🧩 **Extensible** — domain-specific skills welcome! Add a `SKILL.md` and open a PR. See [community skills](#awesome-community-skills) like [`dse-loop`](skills/dse-loop/SKILL.md) (architecture/EDA)
- </details>
- <a id="skills-catalog"></a>
- <a id="-skills-catalog"></a>
- ARIS ships **87+ skills** across literature, ideation, experiments, audit, writing, talks, patents, and meta-utilities — the full catalog (role / category / requirements per skill) lives in **[`docs/SKILLS_CATALOG.md`](docs/SKILLS_CATALOG.md)** to keep this README scannable.
- <details>
- <summary><b>Start here</b> — common entry points (use case → skill)</summary>
- | Use case | Start here |
- |---|---|
- | End-to-end research (idea → paper) | [`/research-pipeline`](skills/research-pipeline/SKILL.md) |
- | Idea discovery + method refinement | [`/idea-discovery`](skills/idea-discovery/SKILL.md) |
- | Run experiments from a plan | [`/experiment-bridge`](skills/experiment-bridge/SKILL.md) |
- | Auto review → fix → re-review | [`/auto-review-loop`](skills/auto-review-loop/SKILL.md) |
- | Narrative → polished PDF | [`/paper-writing`](skills/paper-writing/SKILL.md) |
- | Reply to peer reviews | [`/rebuttal`](skills/rebuttal/SKILL.md) |
- | Port a paper to a new venue | [`/resubmit-pipeline`](skills/resubmit-pipeline/SKILL.md) |
- | Paper → conference talk | [`/paper-talk`](skills/paper-talk/SKILL.md) |
- | Persistent research memory | [`/research-wiki`](skills/research-wiki/SKILL.md) |
- | Patent drafting (CN / US / EP) | [`/patent-pipeline`](skills/patent-pipeline/SKILL.md) |
- | ARIS optimizes itself | [`/meta-optimize`](skills/meta-optimize/SKILL.md) |
- </details>
- → **[Browse all 87 skills by category in the full catalog →](docs/SKILLS_CATALOG.md)**
- ---
- <a id="score-progression"></a>
- ## 5. 📈 Score Progression (Real Run)
- A real overnight 4-round run on an ML research project — the AI reviewer's score climbed **5.0/10 (borderline reject) → 7.5/10 (review-ready)** as the loop autonomously ran **20+ GPU experiments**, rewrote the narrative framing, and killed claims that didn't hold up, all without human intervention.
- <details>
- <summary>Round-by-round breakdown</summary>
- | Round | Score | What Happened |
- |-------|-------|---------------|
- | Initial | 5.0/10 | Borderline reject |
- | Round 1 | 6.5/10 | Added standard metrics, discovered metric decoupling |
- | Round 2 | 6.8/10 | Key claim failed to reproduce, pivoted narrative |
- | Round 3 | 7.0/10 | Large seed study killed main improvement claim |
- | Round 4 | **7.5/10** ✅ | Diagnostic evidence solidified, **submission ready** |
- </details>
- <a id="community-showcase"></a>
- ## 6. 🏆 Community Showcase — Papers Built with ARIS
- Real projects that used the full ARIS pipeline end-to-end. **The scores listed are AI-review signals ([CSPaper](https://cspaper.org/) / [Stanford Agentic Reviewer](https://paperreview.ai/)), not venue acceptances** — and since ARIS optimizes *through* AI-review loops, high AI scores are an expected byproduct, not proof of acceptance (human reviewers still bring literature / venue / community judgment an AI reviewer misses). **Used ARIS for a paper? Open an issue / PR to be featured!**
- <details>
- <summary>Papers + their AI-review signals (3)</summary>
- | Paper | AI-review signal | Submission status | Built by | Notes |
- |-------|:----------------:|-------------------|----------|-------|
- | **CS Paper Submission** | [CSPaper](https://cspaper.org/) **8/10** — AI reviewer recommendation: "Top 50% of accepted papers, clear accept" | Submitted to a CS conference; awaiting official feedback | [@DefanXue](https://github.com/DefanXue) & [@Monglitay](https://github.com/Monglitay) | Full ARIS pipeline: idea → experiments → auto-review → paper writing. The quote is from CSPaper's simulated review, not an official venue review. |
- | **AAAI 2026 Paper Submission** | [Stanford Agentic Reviewer](https://paperreview.ai/) **7/10** — AI reviewer recommendation: "Good paper, accept" | Submitted to AAAI 2026 Main Technical; awaiting official decision | [@xinbo820-web](https://github.com/xinbo820-web) | Pure **Codex CLI** (ARIS-Codex skills). The 7/10 signal comes from an AAAI-style Stanford Agentic Reviewer run, not an official AAAI acceptance result. |
- | [UAV-CC](community_papers/UAV-CC.pdf) | Under review | Submitted to IEEE TGRS | [@wxx827](https://github.com/wxx827) | UAV change captioning benchmark. Claude Opus 4.6 (executor) + Codex GPT-5.5 xhigh (reviewer) + Cursor Opus 4.6 (assist). [PDF →](community_papers/UAV-CC.pdf) |
- </details>
- <details><summary>Reviewer screenshots</summary>
- <br>
- <img src="assets/community_showcase_8_10.png" width="700" alt="8/10 — CS Paper" />
- <img src="assets/community_showcase_7_10_codex.png" width="700" alt="7/10 — AAAI 2026, Codex CLI" />
- </details>
- <a id="awesome-community-skills"></a>
- ## 7. 🧩 Awesome Community Skills & Extensions
- Domain-specific skills and external projects contributed by the community. PRs welcome — just add a `skills/your-skill/SKILL.md` and open a PR!
- > 💡 **How to use:** Community skills are not auto-wired into core workflows. To use one, ask your executor (Claude Code / OpenClaw / etc.) to read the skill's `SKILL.md`, then plug it into the appropriate workflow stage based on the description below.
- 🎉 **Community Skills (15):** [research-refine](skills/research-refine/SKILL.md) · [experiment-plan](skills/experiment-plan/SKILL.md) · [research-refine-pipeline](skills/research-refine-pipeline/SKILL.md) · [grant-proposal](skills/grant-proposal/SKILL.md) · [paper-poster](skills/paper-poster/SKILL.md) (deprecated → [paper-poster-html](skills/paper-poster-html/SKILL.md)) · [paper-slides](skills/paper-slides/SKILL.md) · [mermaid-diagram](skills/mermaid-diagram/SKILL.md) · [proof-writer](skills/proof-writer/SKILL.md) · [comm-lit-review](skills/comm-lit-review/SKILL.md) · [dse-loop](skills/dse-loop/SKILL.md) · [idea-discovery-robot](skills/idea-discovery-robot/SKILL.md) · [formula-derivation](skills/formula-derivation/SKILL.md) · [paper-illustration](skills/paper-illustration/SKILL.md) · [writing-systems-papers](skills/writing-systems-papers/SKILL.md) · [skills-codex](skills/skills-codex/)
- 🌐 **External Projects & Docs (17):** [Absent Author](#absent-author) · [rosetta](https://github.com/SyntaxSmith/rosetta) · [open-source-hardening-skills](https://github.com/zeyuzhangzyz/open-source-hardening-skills) · [CitationClaw](https://github.com/VisionXLab/CitationClaw) · [auto-hparam-tuning](https://github.com/zxh0916/auto-hparam-tuning) · [paper-to-course](https://github.com/KaguraTart/paper-to-course) · [deep-research-skills](https://github.com/Weizhena/deep-research-skills) · [Antigravity Adaptation Guide](docs/ANTIGRAVITY_ADAPTATION.md) · [OpenClaw Adaptation Guide](docs/OPENCLAW_ADAPTATION.md) · [Cursor Adaptation Guide](docs/CURSOR_ADAPTATION.md) · [Codex+Claude Review Bridge](docs/CODEX_CLAUDE_REVIEW_GUIDE.md) · [Trae Adaptation Guide](docs/TRAE_ARIS_RUNBOOK_EN.md) · [MiniMax-AI/cli](https://github.com/MiniMax-AI/cli) · [posterly](https://github.com/Chenruishuo/posterly) · [Claude Fleet](https://github.com/tianyilt/claude-fleet) · [anti-defensive-writing-Skill](https://github.com/Adkid-Zephyr/anti-defensive-writing-Skill) · [OrcaReplay](https://github.com/Continuum-AI-Corp/OrcaReplay)
- > 🙌 Thanks to every contributor! We fold the tables below to keep the README readable — but every skill and project here is equally valued. PRs always welcome!
- <details>
- <summary><b>🎉 Community Skills (15)</b> — click to expand</summary>
- | Name | Domain | Description | Codex MCP? |
- |------|--------|-------------|-----------|
- | 🔬 [`research-refine`](skills/research-refine/SKILL.md) | General | Turn a vague idea into a problem-anchored, implementation-oriented method proposal. Best inserted between `/idea-discovery` and `/auto-review-loop` | Yes |
- | 🧪 [`experiment-plan`](skills/experiment-plan/SKILL.md) | General | Turn a refined proposal into a claim-driven experiment roadmap with ablations, budgets, and run order | No |
- | 🧭 [`research-refine-pipeline`](skills/research-refine-pipeline/SKILL.md) | General | One-shot chain: `/research-refine` → `/experiment-plan` for method refinement plus experiment planning | Yes |
- | 📝 [`grant-proposal`](skills/grant-proposal/SKILL.md) | General | Grant proposal drafting (KAKENHI/NSF/NSFC/ERC/DFG/SNSF/ARC/NWO). Chains `/research-lit` → `/novelty-check` → `/research-review` → `/paper-illustration` | Yes |
- | 🎤 [`paper-slides`](skills/paper-slides/SKILL.md) | General | Conference talk slides (beamer → PDF + PPTX) with speaker notes, full talk script + Q&A prep. Auto slide count from talk type | Yes |
- | 🖼️ [`paper-poster`](skills/paper-poster/SKILL.md) | General | DEPRECATED — redirect stub to the core [`/paper-poster-html`](skills/paper-poster-html/SKILL.md) (measurement-gated HTML/CSS pipeline); the legacy LaTeX implementation lives in git history | — |
- | 📐 [`proof-writer`](skills/proof-writer/SKILL.md) | ML Theory | Rigorous theorem/lemma proof drafting — feasibility triage, dependency maps, honest blockage reports | No |
- | 📡 [`comm-lit-review`](skills/comm-lit-review/SKILL.md) | Communications / Wireless | Domain-specific literature review — IEEE/ACM/ScienceDirect priority, venue tiering, PHY/MAC/transport/NTN taxonomy | No |
- | 🏗️ [`dse-loop`](skills/dse-loop/SKILL.md) | Architecture / EDA | Autonomous design space exploration — iteratively run, analyze, and tune parameters (gem5, Yosys, etc.) | No |
- | 🤖 [`idea-discovery-robot`](skills/idea-discovery-robot/SKILL.md) | Robotics / Embodied AI | Workflow 1 adaptation — grounds idea discovery in embodiment, benchmark, sim2real path, and real-robot safety constraints | Yes |
- | 📐 [`mermaid-diagram`](skills/mermaid-diagram/SKILL.md) | General | Mermaid diagrams (20+ types) — free alternative to `paper-illustration`, no API key needed | No |
- | 🔢 [`formula-derivation`](skills/formula-derivation/SKILL.md) | General | Research formula development — derivation, verification, and LaTeX formatting | No |
- | 🖥️ [`writing-systems-papers`](skills/writing-systems-papers/SKILL.md) | Systems | Paragraph-level blueprint for 10-12 page systems papers (OSDI/SOSP/ASPLOS/NSDI/EuroSys) — page allocation, writing patterns, self-check | Yes |
- | 🎨 [`paper-illustration`](skills/paper-illustration/SKILL.md) | General | AI-generated architecture diagrams via Gemini, built on [PaperBanana](https://github.com/dwzhu-pku/PaperBanana). Integrated into Workflow 3 | No |
- | 🤖 [`skills-codex`](skills/skills-codex/) | General | Codex CLI sync pack mirroring the main research skills (incl. `result-to-claim`, `rebuttal`, `ablation-planner`) + the `shared-references/` support dir | — |
- </details>
- <details>
- <summary><b>🌐 External Projects & Docs (17)</b> — click to expand</summary>
- | Name | Domain | Description |
- |------|--------|-------------|
- | 🔎 [Absent Author](https://github.com/THUROI0787/absent-author) | Paper review / Author accountability | Sourced evidence catalog plus author self-check and reviewer screening skills, covering research steering, result verification, and writing quality. [Full introduction →](#absent-author) |
- | 🪨 [rosetta](https://github.com/SyntaxSmith/rosetta) | Pro-tier ChatGPT MCP | Programmatic access to **ChatGPT Pro / `gpt-5.5-pro` / DeepResearch** from Node, via Chrome CDP Fetch interception + WebSocket second-leg streaming. Ships an MCP server for Claude Code / Codex / Cline — alternative implementation path to Oracle MCP for `— reviewer: oracle-pro` style high-tier review. Supports multi-turn, parallel concurrency, live token deltas, 15-min idle-timeout watchdog (long Pro thinks survive). MIT, by [@SyntaxSmith](https://github.com/SyntaxSmith) |
- | 📣 [anti-defensive-writing-Skill](https://github.com/Adkid-Zephyr/anti-defensive-writing-Skill) | Press-release writing principle | "A paper is a launch, not a progress report": twelve rules against defensive writing — organize around the strongest advantage, pick the contest you win, every experiment has an argumentative duty, no self-weakening language. Skill (CN/EN) + copy-paste prompt. Four of its rules are folded into ARIS's writing contract. MIT, by [@Adkid-Zephyr](https://github.com/Adkid-Zephyr) |
- | 🛡️ [open-source-hardening-skills](https://github.com/zeyuzhangzyz/open-source-hardening-skills) | DevOps / OSS | 10-skill pipeline to harden research code into production-ready open-source projects — audit, refactor, test, CI, docs, review |
- | 📊 [CitationClaw](https://github.com/VisionXLab/CitationClaw) | General | Citation impact analysis — input paper title → citation crawling, scholar identification, tiered analysis, HTML dashboard |
- | 🚀 [Antigravity Adaptation Guide](docs/ANTIGRAVITY_ADAPTATION.md) | General | Use ARIS skills in [Google Antigravity](https://antigravity.google/) — native SKILL.md support, dual model (Claude Opus 4.6 / Gemini 3.1 Pro), MCP setup, EN + [CN](docs/ANTIGRAVITY_ADAPTATION_CN.md) guides |
- | 🐾 [OpenClaw Adaptation Guide](docs/OPENCLAW_ADAPTATION.md) | General | Use ARIS workflow methodology in [OpenClaw](https://github.com/All-Hands-AI/OpenHands) — skill-to-stage mapping, file-based orchestration, no Claude Code CLI needed |
- | 🖱️ [Cursor Adaptation Guide](docs/CURSOR_ADAPTATION.md) | General | Use ARIS skills in [Cursor](https://www.cursor.com/) — `@`-reference skills, MCP setup, workflow mapping, state file recovery across sessions |
- | 🖥️ [Trae Adaptation Guide](docs/TRAE_ARIS_RUNBOOK_EN.md) | General | Use ARIS skills in [Trae](https://www.trae.ai/) (ByteDance AI IDE) — EN + CN guides |
- | 🎛️ [auto-hparam-tuning](https://github.com/zxh0916/auto-hparam-tuning) | General | Automatic hyperparameter tuning — AI agent reads project, plans strategy, runs experiments, analyzes TensorBoard, learns from results. Hydra-based |
- | 🔁 [OrcaReplay](https://github.com/Continuum-AI-Corp/OrcaReplay) | Reproducibility | Records an agent run (Claude Code, Codex, OpenClaw, goose) and replays it offline, or forks it from any step onto a different model — so an overnight loop that went wrong can be re-examined without re-running it. Note: the trace stores the full request/response bytes, prompts and keys included — keep it where your unpublished work belongs. Apache-2.0. |
- | 🔁 [Codex+Claude Review Bridge](docs/CODEX_CLAUDE_REVIEW_GUIDE.md) | General | Codex executes + Claude reviews via local `claude-review` MCP bridge with async polling |
- | 📚 [paper-to-course](https://github.com/KaguraTart/paper-to-course) | Education | Convert research papers (PDF/LaTeX) into interactive six-module HTML courses with formula breakdowns, literature timelines, quizzes, and glossary tooltips — single bundled file, no server needed |
- | 🤖 [MiniMax-AI/cli](https://github.com/MiniMax-AI/cli) | General | Official MiniMax CLI — text, image, video, speech, and music generation + web search. `skill/SKILL.md` follows the agentskills.io standard. Drop-in companion for the Alt B (MiniMax reviewer) setup |
- | 🔎 [deep-research-skills](https://github.com/Weizhena/deep-research-skills) | General / Web Search | Modular web-search strategy bundle — per-source playbooks for Stack Overflow, GitHub Issues / error-string debugging, Chinese tech communities (CSDN / 掘金 / 知乎 / V2EX / Tencent + Aliyun cloud forums), and general web (Reddit / HN / Dev.to / Medium). Complements ARIS's academic-paper-focused [`/research-lit`](skills/research-lit/SKILL.md) stack with **non-academic** sources useful for debugging, version-compat tracking, and Chinese-language tech search. By [@Weizhena](https://github.com/Weizhena) |
- | 🖼️ [posterly](https://github.com/Chenruishuo/posterly) | General / Posters | Academic conference posters as a single **HTML/CSS file → print-ready PDF** via headless Chromium (no LaTeX). A Claude Code skill — its gate machinery now powers ARIS’s default `/paper-poster-html`. By [@Chenruishuo](https://github.com/Chenruishuo) |
- | 🛰️ [Claude Fleet](https://github.com/tianyilt/claude-fleet) | Dashboard / DevEx | Local **read-only** dashboard for many concurrent Claude Code / Codex windows — triage (working / waiting-on-you / done), one-click Focus, ~50ms full-text search across transcripts, skill/memory analytics. By [@tianyilt](https://github.com/tianyilt) |
- </details>
- <a id="absent-author"></a>
- ### 🔎 Absent Author — evidence, verification, and author accountability
- [Absent Author](https://github.com/THUROI0787/absent-author), created by Ruoyu Zhao (City University of Hong Kong) and collaborators, is an open-source evidence catalog with two skills for Claude Code, Codex, and other agents that read `SKILL.md`. The catalog brings together sources, false-positive notes, counter-evidence, and guidance for different paper types, helping authors and reviewers examine AI-assisted research.
- - **[`paper-author-pass`](https://github.com/THUROI0787/absent-author/tree/main/skills/paper-author-pass)** helps authors check a paper before submission: clarify the research question and argument, map claims to evidence, verify references and numbers, then improve the prose. Decisions that require the author's judgment become questions for the author; the final checkpoint asks whether they understand the work, can defend it, and will stand behind it.
- - **[`paper-slop-screen`](https://github.com/THUROI0787/absent-author/tree/main/skills/paper-slop-screen)** helps reviewers and collaborators examine writing, research steering, and substantive quality separately. Findings include locations and quoted passages, with follow-up questions and consideration of counter-evidence and paper-type exceptions.
- The team draws on and explicitly credits **ARIS, HERO, and Anti-Autoresearch**, including our published workflows and subsequent improvements. Thank you for building on this work and extending it into tools for both authors and reviewers. Try the project and contribute real cases or false-positive reports through its [repository](https://github.com/THUROI0787/absent-author).
- <a id="workflows"></a>
- <a id="-workflows"></a>
- ## 8. 🔄 Workflows
- These skills compose into a full research lifecycle. Each workflow can be used independently or chained together:
- - **Exploring a new area (e.g., writing a survey)?** Start with Workflow 1 → `/idea-discovery`
- - **Have a plan, need to implement and run?** Workflow 1.5 → `/experiment-bridge`
- - **Already have results, need iterative improvement?** Workflow 2 → `/auto-review-loop`
- - **Ready to write the paper?** Workflow 3 → `/paper-writing` (or step by step: `/paper-plan` → `/paper-figure` → `/paper-write` → `/paper-compile` → `/auto-paper-improvement-loop`)
- - **Got reviews back? Need to rebuttal?** Workflow 4 → `/rebuttal` — parse reviews, draft safe rebuttal, follow-up rounds
- - **Full pipeline?** Workflow 1 → 1.5 → 2 → 3 → submit → 4 → `/research-pipeline` + `/rebuttal` — from idea through submission and rebuttal
- - **Need a multi-session proof campaign?** Workflow 7 → `/proof-orchestrator` — run-directory proof runs, GPT Pro handoff packages, cross-run continuation
- - **Want ARIS to remember and learn?** 📚 `/research-wiki init` — persistent memory across sessions. Papers, ideas, failed experiments compound over time
- - **Want ARIS to improve itself?** Workflow M → `/meta-optimize` — analyze usage logs, propose skill improvements, reviewer-gated
- > ⚠️ **Important:** These tools accelerate research, but they don't replace your own critical thinking. Always review generated ideas with your domain expertise, question the assumptions, and make the final call yourself. The best research comes from human insight + AI execution, not full autopilot.
- ### Full Pipeline 🚀
- ```
- /research-lit → /idea-creator → /novelty-check → /research-refine → /experiment-bridge → /auto-review-loop → /paper-writing → submit → /rebuttal → accept! 🎉
- (survey) (brainstorm) (verify novel) (refine method) (implement+deploy) (review & fix) (write paper) (send) (reply to reviewers)
- ├────────────── Workflow 1: Idea Discovery ──────────────┤ ├ Workflow 1.5 ─┤ ├── Workflow 2 ──┤ ├── Workflow 3 ──┤ ├── Workflow 4 ──┤
- 📚 research-wiki (persistent memory — papers, ideas, experiments, claims)
- ↕ reads before ideation, writes after every stage, failed ideas = anti-repetition memory
- /meta-optimize (Workflow M — runs independently, improves ARIS itself)
- ↑ reads .aris/meta/events.jsonl (accumulated from all runs above)
- ```
- ### Workflow 1: Idea Discovery & Method Refinement 🔍
- > **"What's the state of the art? Where are the gaps? How do we solve it?"**
- Don't have a concrete idea yet? Just give a research direction — `/idea-discovery` handles the rest:
- 1. 📚 **Survey** the landscape (recent papers, open problems, recurring limitations)
- 2. 🧠 **Brainstorm** 8-12 concrete ideas via GPT-6-Astra xhigh
- 3. 🔍 **Filter** by feasibility, compute cost, and quick novelty search
- 4. 🛡️ **Validate** top ideas with deep novelty check + devil's advocate review
- 5. 🧪 **Pilot** top 2-3 ideas in parallel on different GPUs (30 min - 2 hr each)
- 6. 🏆 **Rank** by empirical signal — ideas with positive pilot results rise to the top
- 7. 🔬 **Refine** the top idea into a problem-anchored proposal via iterative GPT-6-Astra review
- 8. 🧪 **Plan** claim-driven experiments with ablations, budgets, and run order
- The output is a ranked `IDEA_REPORT.md` plus a refined proposal (`refine-logs/FINAL_PROPOSAL.md`) and experiment plan (`refine-logs/EXPERIMENT_PLAN.md`) for the top idea. Dead-end ideas are documented too, saving future exploration.
- <details>
- <summary><b>Show W1 flow diagram and example command sequence</b> — research-lit → idea-creator → novelty-check → research-refine → experiment-plan</summary>
- ```
- ┌─────────────────────────────────────────────────────────────────┐
- │ Idea Discovery & Method Refinement │
- │ │
- │ /research-lit /idea-creator /novelty-check │
- │ (find papers) (brainstorm) (verify novelty) │
- │ │ │ │ │
- │ ▼ ▼ ▼ │
- │ ┌──────────┐ ┌──────────┐ ┌──────────┐ │
- │ │ Scan │───▶│ Generate │────▶│ Check if │ │
- │ │ local │ │ 8-12 │ │ idea is │ │
- │ │ papers + │ │ ideas │ │ novel │ │
- │ │ search │ │ + rank │ │ │ │
- │ └──────────┘ └──────────┘ └──────────┘ │
- │ │ │ │
- │ ▼ ▼ │
- │ ┌──────────┐ ┌──────────┐ │
- │ │ Filter │────▶│ External │ │
- │ │ by cost, │ │ LLM │ │
- │ │ novelty │ │ evaluates│ │
- │ └──────────┘ └──────────┘ │
- │ │ │
- │ /research-refine ▼ │
- │ (refine method) ┌──────────┐ │
- │ │ │ Freeze │ │
- │ ▼ │ problem │ │
- │ ┌──────────┐ │ anchor + │ │
- │ │ Iterate │◀───▶│ refine │ │
- │ │ until │ │ method │ │
- │ │ score≥9 │ └──────────┘ │
- │ └──────────┘ │ │
- │ │ ▼ │
- │ /experiment-plan ┌──────────┐ │
- │ │ │ Claim- │ │
- │ ▼ │ driven │ │
- │ ┌──────────┐ │ experiment│ │
- │ │ Plan │────▶│ roadmap │ │
- │ │ runs │ └──────────┘ │
- │ └──────────┘ │
- │ │
- │ Typical flow: │
- │ 1. /research-lit "discrete diffusion models" │
- │ 2. /idea-creator "DLLMs post training" │
- │ 3. Review ranked ideas, pick top 2-3 │
- │ 4. /novelty-check "top idea" (deep verification) │
- │ 5. /research-review "top idea" (critical feedback) │
- │ 6. /research-refine "top idea" (problem anchor + method) │
- │ 7. /experiment-plan (claim-driven roadmap) │
- │ 8. /run-experiment → /auto-review-loop │
- └─────────────────────────────────────────────────────────────────┘
- ```
- </details>
- **Skills involved:** `research-lit` + `idea-creator` + `novelty-check` + `research-review` + `research-refine-pipeline`
- > 💡 **One-command shortcut:** `/idea-discovery "your research direction"` runs this entire workflow automatically.
- > 🔄 **Human-in-the-loop:** At each `AUTO_PROCEED`-controlled selection checkpoint, `true` reports results and continues in the same turn; `false` asks for your feedback before continuing. If you request changes, tell it what's missing — it refines the prompt and regenerates. Explicit gates such as Feishu interactive approval remain user-controlled.
- > ⚙️ Pilot experiment budgets (max hours, timeout, GPU budget) are configurable — see [Customization](#customization).
- 📝 **Blog post:** [Claude Code 两月 NeurIPS 指北](http://xhslink.com/o/7IvAJQ41IBA)
- ### Workflow 1.5: Experiment Bridge 🔗
- > **"I have a plan. Now implement it, deploy it, and get me initial results."**
- Already have an experiment plan (from Workflow 1 or your own)? `/experiment-bridge` turns it into running code:
- 1. 📋 **Parse** the experiment plan (`refine-logs/EXPERIMENT_PLAN.md`)
- 2. 💻 **Implement** experiment scripts (reuse existing code, add proper argparse/logging/seeds)
- 3. 🔍 **GPT-6-Astra code review** — cross-model review catches logic bugs before wasting GPU hours (`code review: true` by default)
- 4. ✅ **Sanity check** — run the smallest experiment first to catch runtime bugs
- 5. 🚀 **Deploy** full experiment suite to GPU via `/run-experiment`
- 6. 📊 **Collect** initial results and update the experiment tracker
- <details>
- <summary><b>Show W1.5 flow diagram</b> — experiment plan → Claude implements → GPT-6-Astra code review → sanity check → GPU deploy → monitor → results</summary>
- ```
- ┌─────────────────────────────────────────────────────────────────┐
- │ Workflow 1.5: Experiment Bridge │
- │ │
- │ EXPERIMENT_PLAN.md │
- │ │ │
- │ ▼ │
- │ ┌──────────┐ ┌──────────┐ ┌──────────┐ │
- │ │ Claude │────▶│ GPT-6-Astra │────▶│ Sanity │ │
- │ │ Code │ │ xhigh │ │ Check │ │
- │ │ writes │ │ reviews │ │ (1 GPU) │ │
- │ │ code │ │ code │ │ │ │
- │ └──────────┘ └──────────┘ └──────────┘ │
- │ │ │
- │ ▼ │
- │ ┌──────────┐ ┌──────────┐ ┌──────────┐ │
- │ │ Collect │◀────│ Monitor │◀────│ Deploy │ │
- │ │ results │ │ progress │ │ to GPUs │ │
- │ │ │ │ (+ W&B) │ │ │ │
- │ └──────────┘ └──────────┘ └──────────┘ │
- │ │ │
- │ ▼ │
- │ Ready for /auto-review-loop │
- └─────────────────────────────────────────────────────────────────┘
- ```
- </details>
- **Skills involved:** `experiment-bridge` + `run-experiment` + `monitor-experiment`
- > 💡 **One-command shortcut:** `/experiment-bridge` reads `refine-logs/EXPERIMENT_PLAN.md` automatically. Or point it to any plan: `/experiment-bridge "my_plan.md"`.
- > ⚙️ `CODE_REVIEW`, `AUTO_DEPLOY`, `SANITY_FIRST`, `MAX_PARALLEL_RUNS` are configurable — see [Customization](#customization).
- ### Workflow 2: Auto Research Loop 🔁 (sleep & wake up to results)
- > **"Review my paper, fix what's wrong, repeat until it's good."**
- >
- > GPT-6-Astra reviews → identifies weaknesses → suggests experiments → Claude Code writes scripts, deploys to GPU, monitors results, rewrites the paper — all while you sleep. Just add your [GPU server config](#gpu-server-setup) to `CLAUDE.md`.
- 1. 🔍 **Deep review** — GPT-6-Astra xhigh reviews the current paper / claims / experiments and identifies weaknesses
- 2. 🩹 **Fix** — Claude implements the fixes (rewrites sections, adds baselines, or runs new experiments via `/run-experiment`); skips any experiment estimated > 4 GPU-hours and flags it for manual follow-up
- 3. 📊 **Re-evaluate** — collect results via `/monitor-experiment`, update paper, feed back to the reviewer
- 4. 🔁 **Repeat** — until score ≥ `POSITIVE_THRESHOLD` (default 6/10) or `MAX_ROUNDS` (default 4) is hit; if context window fills mid-loop, the workflow auto-resumes from `REVIEW_STATE.json`
- <details>
- <summary><b>Show W2 loop diagram</b> — external review → implement fixes / run experiments → monitor results → repeat until threshold</summary>
- ```
- ┌─────────────────────────────────────────────────────────────┐
- │ Auto Review Loop │
- │ │
- │ /research-review /auto-review-loop │
- │ (single deep review) (autonomous loop) │
- │ │ │ │
- │ ▼ ▼ │
- │ ┌──────────┐ ┌──────────┐ ┌──────────┐ │
- │ │ External │──▶│ Implement│──▶│ Monitor │──▶ repeat │
- │ │ LLM │ │ fixes │ │ results │ until │
- │ │ reviews │ │ & run │ │ │ score ≥ 6 │
- │ └──────────┘ │ experiments│ └──────────┘ │
- │ └──────────┘ │
- │ │
- │ When reviewer suggests a new method direction: │
- │ /novelty-check — verify idea isn't already published │
- │ │
- │ Supporting skills: │
- │ /run-experiment — deploy to local/remote/vast.ai GPU │
- │ /analyze-results — interpret experiment outputs │
- │ /monitor-experiment — check progress, collect results │
- └─────────────────────────────────────────────────────────────┘
- ```
- </details>
- **Skills involved:** `auto-review-loop` + `research-review` + `novelty-check` + `run-experiment` + `analyze-results` + `monitor-experiment`
- > 💡 **One-command shortcut:** `/auto-review-loop "your paper topic"` runs this entire workflow automatically.
- <details>
- <summary><b>Show W2 usage examples, reviewer difficulty levels, and full safety guarantees</b> — topic/scope arguments, medium/hard/nightmare, 6 safety rules</summary>
- **What to pass as argument?** A short topic or scope is enough — the skill automatically reads your project's narrative docs (`NARRATIVE_REPORT.md`), memory files, experiment results, and prior reviews to build the full context for GPT-6-Astra. Examples:
- - `/auto-review-loop "factorized gap in discrete diffusion LMs"` — broad topic, skill finds everything
- - `/auto-review-loop "focus on Section 3-5, our CRF results are weak"` — targeted scope with hints
- - `/auto-review-loop` — also works: skill reads project files and infers the topic
- **🎮 Reviewer Difficulty** — control how adversarial the reviewer is:
- | Level | What changes | Use when |
- |-------|-------------|----------|
- | `medium` (default) | Standard MCP review — same as before | Normal workflow |
- | `hard` | + Reviewer Memory (GPT tracks suspicions across rounds) + Debate Protocol (Claude rebuts, GPT rules) | Want tougher feedback |
- | `nightmare` | + GPT reads repo directly via `codex exec` (Claude can't filter what it sees) + adversarial verification | Preparing for top venue, want maximum stress test |
- ```bash
- /auto-review-loop "topic" — difficulty: nightmare # GPT reads your code and verifies claims itself
- ```
- **🛡️ Key safety features:**
- - 🔒 **MAX_ROUNDS = 4** — prevents infinite loops; stops early if score threshold is met
- - ⏱️ **> 4 GPU-hour experiments skipped** — won't launch massive jobs; flags them for manual follow-up
- - 🧠 **Prefer reframing over new experiments** — when both can address a weakness, chooses the cheaper path
- - 🪞 **No hiding weaknesses** — explicit rule: "Do NOT hide weaknesses to game a positive score"
- - 🔧 **Fix before re-review** — must actually implement fixes before resubmitting; no empty promises
- - 💾 **Compact recovery** — persists state (`REVIEW_STATE.json`) after each round. If the context window fills up and auto-compacts mid-loop, the workflow reads the state file and resumes from where it left off — no human intervention needed
- </details>
- > ⚙️ MAX_ROUNDS, score threshold, and GPU limits are configurable — see [Customization](#customization).
- 📝 **Blog post:** [开源 | 睡觉 Claude 自动跑实验改文](http://xhslink.com/o/5cBMTDigNXz)
- ### Workflow 3: Paper Writing Pipeline 📝
- > **"Turn my research narrative into a submission-ready PDF."** Requires a local LaTeX environment — see [Prerequisites](#prerequisites).
- 1. 📝 **Narrate** — write `NARRATIVE_REPORT.md` (claims, experiments, results, figure descriptions); see [`templates/NARRATIVE_REPORT_TEMPLATE.md`](templates/NARRATIVE_REPORT_TEMPLATE.md)
- 2. 🧭 **Plan** — `/paper-plan` builds the claims-evidence matrix + section plan
- 3. 📊 **Figures** — `/paper-figure` generates data-driven plots and comparison tables from JSON/CSV
- 4. ✍️ **Write** — `/paper-write` produces section-by-section LaTeX
- 5. 🔧 **Compile** — `/paper-compile` builds the PDF, fixes errors, runs the page-limit check
- 6. ✨ **Improve** — `/auto-paper-improvement-loop` runs 2 rounds of GPT-6-Astra content review + final format check
- <details>
- <summary><b>Show W3 architecture diagram and exact writing flow</b> — NARRATIVE_REPORT → /paper-plan → /paper-figure → /paper-write → /paper-compile → improvement loop</summary>
- ```
- ┌─────────────────────────────────────────────────────────────┐
- │ Paper Writing Pipeline │
- │ │
- │ /paper-plan /paper-figure /paper-write │
- │ (outline) (plots & tables) (LaTeX draft) │
- │ │ │ │ │
- │ ▼ ▼ ▼ │
- │ ┌──────────┐ ┌──────────┐ ┌──────────┐ │
- │ │ Claims- │───▶│ Generate │────▶│ Section │──┐ │
- │ │ Evidence │ │ figures, │ │ by │ │ │
- │ │ Matrix + │ │ tables, │ │ section │ │ │
- │ │ Section │ │ LaTeX │ │ LaTeX │ │ │
- │ │ Plan │ │ includes │ │ draft │ │ │
- │ └──────────┘ └──────────┘ └──────────┘ │ │
- │ │ │ │
- │ │ /paper-compile │ │
- │ │ (build PDF) │ │
- │ │ │ │ │
- │ ▼ ▼ ▼ │
- │ ┌──────────────────────────────────────────────────┐ │
- │ │ NARRATIVE_REPORT.md ──► PAPER_PLAN.md ──► paper/ │ │
- │ │ (input) (outline) (LaTeX+PDF)│ │
- │ └──────────────────────────────────────────────────┘ │
- │ │
- │ Typical flow: │
- │ 1. Write NARRATIVE_REPORT.md (from Workflow 2 results) │
- │ 2. /paper-plan (claims-evidence matrix + section plan) │
- │ 3. /paper-figure (comparison tables, training curves, etc.) │
- │ 4. /paper-write (section-by-section LaTeX generation) │
- │ 5. /paper-compile (build PDF, fix errors, page check) │
- │ 6. /auto-paper-improvement-loop (review ×2 + format check) │
- └─────────────────────────────────────────────────────────────┘
- ```
- </details>
- **Skills involved:** `paper-plan` + `paper-figure` + `paper-write` + `paper-compile` + `auto-paper-improvement-loop` + (post-acceptance) `paper-poster-html` + `paper-slides`
- > **One-command shortcut:** `/paper-writing "NARRATIVE_REPORT.md"` runs this entire workflow automatically.
- **Input:** A `NARRATIVE_REPORT.md` describing the research: claims, experiments, results, figures. The more detailed the narrative (especially figure descriptions and quantitative results), the better the output.
- **Output:** A `paper/` directory with LaTeX source, clean `.bib` (only cited entries), and compiled PDF. The PDF is labelled `submission-ready` **only when** run at `— effort: max | beast` (or explicit `— assurance: submission`) **and** `tools/verify_paper_audits.sh` reports green on the three mandatory audits (`proof-checker`, `paper-claim-audit`, `citation-audit`); see [Assurance Gate](#assurance-gate-effort-max--beast) below. At the default `balanced` level, the output is a reviewed draft.
- <details>
- <summary><b>Show W3 feature details</b> — Claims-Evidence Matrix, figure modes, clean bib, Gemini API setup, ICLR end-to-end test</summary>
- **Key features:**
- - 📐 **Claims-Evidence Matrix** — every claim maps to evidence, every experiment supports a claim
- - 📊 **Auto figure generation** — line plots, bar charts, comparison tables from JSON data
- - 🧹 **Clean bib** — automated filtering removes uncited entries (948→215 lines in testing). Real BibTeX from [DBLP](https://dblp.org)/[CrossRef](https://www.crossref.org) instead of LLM-generated entries
- - 📄 **Flexible sections** — 5-8 sections depending on paper type (theory papers often need 7)
- - 🔍 **GPT-6-Astra review** — each step optionally reviewed by external LLM
- - ✂️ **De-AI polish** — removes AI writing patterns (delve, pivotal, landscape...)
- - 🎯 **Page verification** — `pdftotext`-based precise check that main body fits page limit
- > ⚠️ **Figure generation scope:** `/paper-figure` auto-generates **data-driven plots** (training curves, bar charts, heatmaps) and **comparison tables** from JSON/CSV. For **architecture diagrams and method figures**: `illustration: gemini` (default) uses Claude→Gemini→Nano Banana Pro for publication-quality diagrams; `illustration: mermaid` generates Mermaid diagrams for free; `illustration: false` skips AI figures entirely.
- >
- > **Gemini API setup** (for `illustration: gemini`): Get your API key at [Google AI Studio](https://aistudio.google.com/apikey), then set it as an environment variable: `export GEMINI_API_KEY="your-key"`. Or add to your shell profile (`~/.zshrc` / `~/.bashrc`). No other dependencies needed.
- **Tested end-to-end:** Generated a 9-page ICLR 2026 theory paper (7 sections, 29 citations, 4 figures, 2 comparison tables) from a single NARRATIVE_REPORT.md — zero compilation errors, zero undefined references.
- </details>
- #### Auto Paper Improvement Loop ✨
- After Workflow 3 generates the paper, `/auto-paper-improvement-loop` runs 2 rounds of GPT-6-Astra xhigh content review → fix → recompile, plus a final format compliance check, autonomously polishing the paper from rough draft to a reviewer-scored draft. Whether the result is tagged `submission-ready` is decided separately by the Phase 6 assurance gate (see [Assurance Gate](#assurance-gate-effort-max--beast)).
- <details>
- <summary><b>Show auto-paper-improvement benchmark</b> — Score Progression on a real ICLR 2026 theory paper (4/10 → 8.5/10), plus Round 1/2/3 fix details</summary>
- **Score Progression (Real Test — ICLR 2026 theory paper):**
- | Round | Score | Key Changes |
- |-------|-------|-------------|
- | Round 0 | 4/10 (content) | Baseline |
- | Round 1 | 6/10 (content) | Fixed assumptions, softened claims, renamed notation |
- | Round 2 | 7/10 (content) | Added synthetic validation, stronger limitations |
- | Round 3 | 5→8.5/10 (format) | Removed hero fig, appendix, compressed conclusion, float spacing |
- **Final: 8 pages main body (ICLR limit: 9), 0 overfull hbox, ICLR-compliant.** +4.5 points across 3 rounds.
- <details>
- <summary>Round 1 fixes (6 items)</summary>
- 1. **CRITICAL — Assumption-model mismatch**: A boundedness assumption contradicted the model's distributional family. Replaced with a tail-compatible assumption and added formal truncation bridge.
- 2. **CRITICAL — Theory-practice gap**: Theory assumes idealized encoders, experiments use learned nonlinear encoders. Softened "validate" → "demonstrate practical relevance" and added explicit disclaimer.
- 3. **MAJOR — Missing quantitative metrics**: Added parameter count table (latent vs total) with honest accounting of system cost.
- 4. **MAJOR — Theorem not self-contained**: Added "Interpretation" paragraph listing all dependencies explicitly.
- 5. **MAJOR — Overclaim in novelty statement**: Scoped a broad "first convergence guarantee" to precise conditions under which it holds.
- 6. **MAJOR — Notation confusion**: Renamed a symbol that clashed with another key variable. Added Notation paragraph.
- </details>
- <details>
- <summary>Round 2 fixes (4 items)</summary>
- 1. **MAJOR — Missing theory-aligned experiments**: Added a synthetic validation subsection directly testing the two main theoretical predictions under controlled conditions.
- 2. **MAJOR — Overclaim softening**: Replaced strong equivalence claims with appropriately hedged language across all files.
- 3. **MAJOR — Informal theoretical argument**: Formalized an informal justification into a proper proposition with explicit error bounds.
- 4. **MINOR — Weak limitations**: Expanded to explicitly list all assumptions and acknowledge missing standard evaluations.
- </details>
- <details>
- <summary>Round 3 format fixes (8 items)</summary>
- 1. Removed hero figure block (saved ~0.7 pages)
- 2. Compressed conclusion from 15→9 lines
- 3. Moved synthetic validation to Appendix A
- 4. Moved comparison tables to Appendix B
- 5. Fixed overfull hbox (85pt) with `\resizebox`
- 6. Added compact float spacing (`\captionsetup`, `\textfloatsep`)
- 7. Inlined centered question block in introduction
- 8. Tightened `itemize` environments
- </details>
- </details>
- ### Workflow 4: Rebuttal 📝 (reply to reviewers safely)
- > **"Reviews are in. Help me draft a safe, grounded rebuttal."**
- Got reviews back? `/rebuttal` parses them, builds a strategy, and drafts a venue-compliant response:
- 1. 📋 **Parse** — normalize reviews, validate venue rules (character limit, text-only, etc.)
- 2. 🔍 **Atomize** — split each review into issue cards (type, severity, reviewer stance)
- 3. 🗺️ **Strategize** — global themes, per-reviewer priorities, character budget, blocked claims
- 4. 🧪 **Evidence sprint** — if `auto experiment: true`, auto-run supplementary experiments via `/experiment-bridge`
- 5. ✍️ **Draft** — global opener + numbered per-reviewer responses + closing for meta-reviewer
- 6. 🛡️ **Safety check** — 6 lints: coverage, provenance, commitment, tone, consistency, limit
- 7. 🔬 **GPT-6-Astra stress test** — internal skeptical review of the draft
- 8. 📄 **Finalize** — two outputs: `PASTE_READY.txt` (exact character count) + `REBUTTAL_DRAFT_rich.md` (extended version for manual editing)
- 9. 🔄 **Follow-up rounds** — delta replies for reviewer discussions, technically escalating
- <details>
- <summary><b>Show W4 rebuttal flow diagram</b> — parse reviews → strategy → optional evidence sprint → draft → GPT-6-Astra stress test → finalize 2 versions → follow-up rounds</summary>
- ```
- ┌─────────────────────────────────────────────────────────────────┐
- │ Workflow 4: Rebuttal │
- │ │
- │ Reviews arrive │
- │ │ │
- │ ▼ │
- │ ┌──────────┐ ┌──────────┐ ┌──────────┐ │
- │ │ Parse & │────▶│ Strategy │────▶│ Evidence │ │
- │ │ atomize │ │ plan │ │ sprint │ │
- │ │ reviews │ │ │ │ (optional)│ │
- │ └──────────┘ └──────────┘ └──────────┘ │
- │ │ │
- │ ▼ │
- │ ┌──────────┐ ┌──────────┐ ┌──────────┐ │
- │ │ Finalize │◀────│ GPT-6-Astra │◀────│ Draft │ │
- │ │ 2 versions│ │ stress │ │ rebuttal │ │
- │ │ │ │ test │ │ │ │
- │ └──────────┘ └──────────┘ └──────────┘ │
- │ │ │
- │ ▼ │
- │ PASTE_READY.txt (strict) + RICH.md (extended) │
- │ │ │
- │ ▼ │
- │ Follow-up rounds (delta replies, per-reviewer threads) │
- └─────────────────────────────────────────────────────────────────┘
- ```
- </details>
- **Skills involved:** `rebuttal`
- > 💡 **Quick mode:** `/rebuttal — quick mode: true` stops after parsing + strategy (Phase 0-3). See what reviewers want before committing to a full draft.
- > ⚙️ `VENUE`, `AUTO_EXPERIMENT`, `QUICK_MODE`, `MAX_STRESS_TEST_ROUNDS` are configurable — see [Customization](#customization).
- **Three safety gates — rebuttal will NOT finalize if any fails:**
- - 🔒 **Provenance** — every claim maps to paper/review/user-confirmed result. No fabrication.
- - 🔒 **Commitment** — every promise is user-approved. No overpromising.
- - 🔒 **Coverage** — every reviewer concern is tracked. Nothing disappears.
- ### Workflow 5: Resubmit Pipeline 🔁 (port a paper to a new venue, text-only)
- Port a polished paper from venue A → B under **hard, non-overridable guardrails** — no new experiments · no bib edits · no framework changes · never overwrites prior submissions — via physical isolation, a 5-layer anonymity check, soft-only audits, whitelist microedits, and a `/kill-argument` adversarial gate. **Full flow + constraints → [docs/RESUBMIT_AND_TALK.md](docs/RESUBMIT_AND_TALK.md)**
- ### Workflow 6: Conference Talk Pipeline 🎤 (paper → slides → polish → audits)
- `/paper-talk` turns an accepted paper into a talk: outline → `/paper-slides` (Beamer + PPTX + speaker notes + Q&A) → `/slides-polish` (per-page Codex visual pass) → optional conference-ready audit gate. Sister to `/paper-writing` / `/paper-poster-html`. **Full flow → [docs/RESUBMIT_AND_TALK.md](docs/RESUBMIT_AND_TALK.md)**
- ### Workflow 7: Proof Orchestrator 🧭 (standalone theory track — attack a theorem across days, not turns)
- > **"This proof will take a week and three tools. Keep every attempt, audit, and escalation on the record."**
- Hard theorems are campaigns, not chat turns. `/proof-orchestrator` runs proof work as a stateful, local-first pipeline — each run gets its own directory, completed runs become append-only evidence, and every new run records which prior claims were proved, conjectural, or rejected:
- 1. 🎯 **Freeze the target** — exact theorem, assumptions, quantifiers, allowed sources; new run or continuation
- 2. 🧱 **Maintain local evidence** — run directory with `task.md` / `materials.md` / stable source snapshots
- 3. 🧠 **Attempt locally** — full proof, disproof, counterexample, or diagnosis; a stall isolates the smallest hard obligation
- 4. 🔍 **Audit correctness** — every lemma, bound, and quantifier checked against assumptions; claims labeled proved / imported / conjectural / repaired / unsupported
- 5. ✒️ **Edit for exposition** — two gates: the 7-line notation scorecard (100% core-object retention, zero undefined symbols, zero collisions) and the top-down derivation-structure gate (acyclic dependency graph, no subgoal silently assuming the target — a bug-catcher in disguise: a proof that resists a clean target-first rewrite is usually hiding a gap, and circular reasoning surfaces the moment you try)
- 6. 📦 **GPT Pro handoff** — a stalled proof becomes a package: `browser-prompt.md` (copy-paste ready), `source-manifest.md` (source roles), `handoff.md` (upload order + return instructions)
- 7. 🧾 **Re-audit the returned proof** — format repair only, then the full correctness audit and exposition edit produce `final.md`
- <details>
- <summary><b>Show W7 flow diagram</b> — freeze target → local attempt → audit → notation/structure gates → GPT Pro handoff (when stalled) → re-audit → final.md, plus the optional DeepSeek branch</summary>
- ```
- ┌─────────────────────────────────────────────────────────────────┐
- │ Workflow 7: Proof Orchestrator │
- │ │
- │ Theorem arrives (new run, or continuation of a prior run) │
- │ │ │
- │ ▼ │
- │ ┌──────────┐ ┌──────────┐ ┌──────────┐ │
- │ │ Freeze │────▶│ Local │────▶│ Correct- │ │
- │ │ target + │ │ proof │ │ ness │ │
- │ │ evidence │ │ attempt │ │ audit │ │
- │ └──────────┘ └──────────┘ └──────────┘ │
- │ │ │ │
- │ LOCAL_BLOCKED ┌──────────┐ │
- │ │ │ Notation │ │
- │ │ │ + struct │──▶ final.md │
- │
tools/threat_scan.py · Bundled script · 222 lines · 2 findings marked
- #!/usr/bin/env python3
- """Deterministic prompt-injection / promptware / exfiltration scanner for ARIS.
- ARIS injects model- and web-authored content back into agent context: MEMORY.md,
- research-wiki nodes/edges, the query_pack that feeds /idea-creator, fetched paper
- abstracts, and community-PR-authored SKILL.md. None of that was scanned before.
- This module is the cheap, deterministic FIRST layer of ARIS's two-layer defense:
- layer 1 (this file) — regex, fail-closed, no model. A poisoned model cannot
- talk its way past a regex. Blocks overt injection.
- layer 2 (the jury) — cross-model review (codex/gemini) catches semantic
- poisoning a regex can't (see injection-hygiene.md).
- A clean scan is NOT a safety acquittal — only the absence of known-bad strings.
- "Drive, not acquit": this scanner may GATE a write/inject; correctness of the
- content still belongs to the cross-model jury (acceptance-gate.md).
- Pattern set adapted from NousResearch/hermes-agent `tools/threat_patterns.py`
- (MIT License, Copyright (c) 2025 Nous Research), with ARIS-runtime adaptations
- (Claude/Codex/Gemini env vars, ARIS config paths) and an added entry-level
- `quarantine()` + CLI. See shared-references/injection-hygiene.md.
- Scope (nested: all ⊂ context ⊂ strict):
- all — classic injection + exfil; minimal false positives, any text.
- context — + promptware / C2 / role-hijack; web/tool content, warn-by-default.
- strict — + persistence / ssh-backdoor / exfil-URL / config-mod / secrets;
- user-mediated writes (memory, wiki, skill install) — block here,
- because false positives are resolvable interactively.
- Pattern anchoring: anchor on attack-specific vocabulary, NOT bossy English
- ("you must" alone is too common in legitimate CLAUDE.md / AGENTS.md to flag).
- The (?:\\w+\\s+)* filler-gap between key tokens defeats "ignore all PRIOR
- Note: Quoted as data in code: Quotes instruction-override phrasing (in quotes, code, a table or an example): "ignore all prior instructions"
- Line 32 on GitHub
- instructions"-style evasion.
- """
- from __future__ import annotations
- import re
- import sys
- from typing import List, Optional, Tuple
- # Each entry: (regex, pattern_id, scope), scope ∈ {"all", "context", "strict"}
- _PATTERNS: List[Tuple[str, str, str]] = [
- # ── Classic prompt injection (everywhere) ────────────────────────
- (r'ignore\s+(?:\w+\s+)*(previous|all|above|prior)\s+(?:\w+\s+)*instructions', "prompt_injection", "all"),
- (r'system\s+prompt\s+override', "sys_prompt_override", "all"),
- (r'disregard\s+(?:\w+\s+)*(your|all|any)\s+(?:\w+\s+)*(instructions|rules|guidelines)', "disregard_rules", "all"),
- (r'act\s+as\s+(if|though)\s+(?:\w+\s+)*you\s+(?:\w+\s+)*(have\s+no|don\'t\s+have)\s+(?:\w+\s+)*(restrictions|limits|rules)', "bypass_restrictions", "all"),
- (r'<!--[^>]*(?:ignore|override|system|secret|hidden)[^>]*-->', "html_comment_injection", "all"),
- (r'<\s*div\s+style\s*=\s*["\'][\s\S]*?display\s*:\s*none', "hidden_div", "all"),
- (r'translate\s+[^\n]{0,80}\s+into\s+[^\n]{0,40}\s+and\s+(execute|run|eval)\b', "translate_execute", "all"),
- (r'do\s+not\s+(?:\w+\s+)*tell\s+(?:\w+\s+)*the\s+user', "deception_hide", "all"),
- # ── Role-play / identity hijack (context) ────────────────────────
- (r'you\s+are\s+(?:\w+\s+)*now\s+(?:a|an|the)\s+', "role_hijack", "context"),
- (r'pretend\s+(?:\w+\s+)*(you\s+are|to\s+be)\s+', "role_pretend", "context"),
- (r'output\s+(?:\w+\s+)*(system|initial)\s+prompt', "leak_system_prompt", "context"),
- (r'(respond|answer|reply)\s+without\s+(?:\w+\s+)*(restrictions|limitations|filters|safety)', "remove_filters", "context"),
- (r'you\s+have\s+been\s+(?:\w+\s+)*(updated|upgraded|patched)\s+to', "fake_update", "context"),
- (r'\bname\s+yourself\s+\w+', "identity_override", "context"),
- # ── C2 / promptware (context; warn-by-default) ───────────────────
- # Narrowed to require an explicit C2 target — bare "register a node" / "pull
- # tasks" are legitimate distributed-ML / task-queue terms in research content.
- (r'register\s+(?:yourself\s+)?as\s+a\s+node\s+(?:with|to)\s+(?:the\s+)?(?:c2|controller|server|botnet)\b', "c2_node_registration", "context"),
- (r'(heartbeat|beacon|check[\s\-]?in)\s+(to|with)\s+', "c2_heartbeat", "context"),
- (r'pull\s+(?:down\s+)?(?:new\s+)?tasking(?:s)?\b', "c2_task_pull", "context"), # "tasking" is C2 vocab; "tasks" is not
- (r'connect\s+to\s+the\s+network\b', "c2_network_connect", "context"),
- # Verbs that are near-zero-FP (dropped "register/connect/report" — too common
- # in legitimate "you must report results" / "connect to the database").
- (r'you\s+must\s+(?:\w+\s+){0,3}(beacon|exfiltrate|phone\s+home)\b', "forced_action", "context"),
- (r'only\s+use\s+one[\s\-]?liners?\b', "anti_forensic_oneliner", "context"),
- (r'never\s+(?:\w+\s+)*(?:create|write)\s+(?:\w+\s+)*(?:script|file)\s+(?:\w+\s+)*disk', "anti_forensic_disk", "context"),
- # ARIS runtime: unsetting known agent/provider env vars is pure attack behavior.
- (r'unset\s+\w*(?:CLAUDE|CODEX|GEMINI|AGENT|OPENAI|ANTHROPIC)\w*', "env_var_unset_agent", "context"),
- (r'\b(?:praxis|cobalt\s*strike|sliver|havoc|mythic|metasploit|brainworm)\b', "known_c2_framework", "context"),
- (r'\bc2\s+(?:server|channel|infrastructure|beacon)\b', "c2_explicit", "context"),
- (r'\bcommand\s+and\s+control\b', "c2_explicit_long", "context"),
- # ── Exfiltration (everywhere / strict) ───────────────────────────
- (r'curl\s+[^\n]*\$\{?\w*(KEY|TOKEN|SECRET|PASSWORD|CREDENTIAL|API)', "exfil_curl", "all"),
- (r'wget\s+[^\n]*\$\{?\w*(KEY|TOKEN|SECRET|PASSWORD|CREDENTIAL|API)', "exfil_wget", "all"),
- # [^\n>] stops the match at a redirect, so "cat > ~/.qzcli/.env" (a WRITE,
- # legitimate) is not mistaken for reading a secret.
- (r'cat\s+[^\n>]*(\.env|credentials|\.netrc|\.pgpass|\.npmrc|\.pypirc)', "read_secrets", "all"),
- # Require explicit exfil intent — "upload your SSH key at https://..." (legit
- # setup) must NOT trip; "exfiltrate the data to https://..." must.
- (r'(?:exfiltrate|smuggle|leak)\s+[^\n]{0,60}\s+(?:to|at)\s+https?://', "exfil_to_url", "strict"),
- (r'(include|output|print|share)\s+(?:\w+\s+)*(conversation|chat\s+history|previous\s+messages|full\s+context|entire\s+context)', "context_exfil", "strict"),
- # ── Persistence / backdoor / config-mod (strict) ─────────────────
- (r'authorized_keys', "ssh_backdoor", "strict"),
- (r'\$HOME/\.ssh|\~/\.ssh', "ssh_access", "strict"),
- # ARIS config surface: tampering with the agent's instructions / install state.
- # Bounded gap + fixed-width negative lookbehind so "REVIEWER_MEMORY.md" does
- # NOT match via the "MEMORY.md" substring. NOTE: legit ARIS skill docs do say
- # "update CLAUDE.md", so this is tuned for wiki/web content; scanning SKILL.md
- # itself needs an ARIS-content allowlist first (see injection-hygiene.md).
- (r'(?:update|modify|edit|append\s+to|overwrite)\s+[^\n]{0,40}(?:AGENTS\.md|CLAUDE\.md|(?<![A-Za-z_])MEMORY\.md|\.cursorrules|\.clinerules)', "agent_config_mod", "strict"),
- (r'(update|modify|edit|write|change|append|add\s+to)\s+.*\.aris/(installed-skills\.txt|skill-source\.txt)', "aris_config_mod", "strict"),
- # ── Hardcoded secrets (strict) ───────────────────────────────────
- (r'(?:api[_-]?key|token|secret|password)\s*[=:]\s*["\'][A-Za-z0-9+/=_-]{20,}', "hardcoded_secret", "strict"),
- ]
- # Invisible / bidirectional unicode used in injection attacks.
- INVISIBLE_CHARS = frozenset({
- '', '', '', '', '', '', '',
- '', '', '', '', '', '',
- Note: Usual in code (characters a sanitizer strips): Contains 9 bidirectional-override character(s), which make text display in a different order from how it's read
- Line 109 on GitHub
- '', '', '', '',
- })
- _COMPILED: dict[str, List[Tuple[re.Pattern, str]]] = {}
- def _compile() -> None:
- global _COMPILED
- if _COMPILED:
- return
- all_p: List[Tuple[re.Pattern, str]] = []
- context_p: List[Tuple[re.Pattern, str]] = []
- strict_p: List[Tuple[re.Pattern, str]] = []
- for pattern, pid, scope in _PATTERNS:
- entry = (re.compile(pattern, re.IGNORECASE), pid)
- if scope == "all":
- all_p.append(entry); context_p.append(entry); strict_p.append(entry)
- elif scope == "context":
- context_p.append(entry); strict_p.append(entry)
- elif scope == "strict":
- strict_p.append(entry)
- else:
- raise ValueError(f"threat_scan: unknown scope {scope!r} for {pid!r}")
- _COMPILED = {"all": all_p, "context": context_p, "strict": strict_p}
- _compile()
- def scan_for_threats(content: str, scope: str = "context") -> List[str]:
- """Return matched pattern IDs in ``content`` at ``scope`` (empty = clean).
- Invisible-unicode hits are returned as ``invisible_unicode_U+XXXX``.
- """
- if not content:
- return []
- findings: List[str] = []
- for ch in (set(content) & INVISIBLE_CHARS):
- findings.append(f"invisible_unicode_U+{ord(ch):04X}")
- patterns = _COMPILED.get(scope)
- if patterns is None:
- raise ValueError(f"scan_for_threats: unknown scope {scope!r}")
- for compiled, pid in patterns:
- if compiled.search(content):
- findings.append(pid)
- return findings
- def first_threat_message(content: str, scope: str = "strict") -> Optional[str]:
- """Human-readable error for the first threat found at ``scope``, else None.
- Use on block-on-first-hit write paths (wiki write, memory write, skill install).
- """
- findings = scan_for_threats(content, scope=scope)
- if not findings:
- return None
- pid = findings[0]
- if pid.startswith("invisible_unicode_"):
- return f"Blocked: invisible unicode character {pid.replace('invisible_unicode_', '')} (possible injection)."
- return (
- f"Blocked: content matches threat pattern '{pid}'. This content is "
- f"re-injected into agent context and must not carry an injection or "
- f"exfiltration payload."
- )
- def quarantine(content: str, scope: str = "strict", label: str = "entry") -> Tuple[str, List[str]]:
- """Load-time / inject-time quarantine (entry-level, fail-closed-with-visibility).
- If ``content`` trips a pattern, return a visible ``[BLOCKED: ...]`` placeholder
- (so the poison is NOT injected into the prompt) plus the findings. The caller
- keeps the RAW text on disk so a human can read and remove it — silently
- dropping it would hide the attack. If clean, returns ``(content, [])``.
- This is the Hermes load-time-quarantine pattern: keep the prompt safe without
- losing the evidence.
- """
- findings = scan_for_threats(content, scope=scope)
- if not findings:
- return content, []
- placeholder = (
- f"[BLOCKED: {label} matched threat pattern(s): {', '.join(findings)} "
- f"— raw text preserved on disk; review and remove. Not injected into context.]"
- )
- return placeholder, findings
- __all__ = ["INVISIBLE_CHARS", "scan_for_threats", "first_threat_message", "quarantine"]
- def main() -> int:
- import argparse
- ap = argparse.ArgumentParser(description="ARIS injection / exfiltration scanner.")
- ap.add_argument("path", help="file to scan, or - for stdin")
- ap.add_argument("--scope", choices=["all", "context", "strict"], default="strict")
- ap.add_argument("--quarantine", action="store_true",
- help="print the quarantined text instead of the findings")
- args = ap.parse_args()
- text = sys.stdin.read() if args.path == "-" else open(args.path, encoding="utf-8").read()
- if args.quarantine:
- out, findings = quarantine(text, scope=args.scope, label=args.path)
- sys.stdout.write(out if out.endswith("\n") else out + "\n")
- return 1 if findings else 0
- findings = scan_for_threats(text, scope=args.scope)
- if findings:
- print(f"THREAT ({args.scope}): {', '.join(findings)}", file=sys.stderr)
- return 1
- print(f"clean ({args.scope})")
- return 0
- if __name__ == "__main__":
- raise SystemExit(main())
Ratings and comments
Sign in to rate this skill.
Sign inFree to use. If it’s helped, pass it on.