ShinkaEvolve
ShinkaEvolve: Towards Open-Ended and Sample-Efficient Program Evolution 🧬
Safety scan
A static text scan, not a guarantee. Select the badge to see what was scanned and every finding.
Check it deeper on your machine
It has changed since its scan on 11 Nov 2026.
As a Claude Code plugin, install it and then ask Claude Code:
/plugin marketplace add keithmackay/mackayi/plugin install scanskillsafety@mackayiDo a deep scan of https://github.com/SakanaAI/ShinkaEvolve with scanskillsafety
Or from a terminal, clone it and run it:
git clone https://github.com/keithmackay/scanskillsafety-skill ~/.claude/skills/scanskillsafetynode ~/.claude/skills/scanskillsafety/cli.cjs --deep 'https://github.com/SakanaAI/ShinkaEvolve'
It checks the exact commit: every file, its packages against OSV (api.osv.dev), how it compares with this page's scan (findsafeskills.com receives the repository's address), and, if you agree, Claude reading every file with your own Claude subscription. It never runs the code.
Badge for your README

Markdown
[](/listings/sakanaai--shinkaevolve)HTML
<a href="/listings/sakanaai--shinkaevolve"><img src="/api/listings/sakanaai--shinkaevolve/badge.svg" alt="findsafeskills safety rating" /></a>Install
Install instructions from the README
As written by the repo's author. findsafeskills has not verified these steps.
# Install from PyPI
pip install shinka-evolve

# Or with uv
uv pip install shinka-evolve

# Run your first evolution experiment
shinka_launch variant=circle_packing_example
The distribution name is `shinka-evolve`; Python imports stay `import shinka`.
`shinka_launch` still supports the original shorthand group overrides:
shinka_launch variant=circle_packing_example
shinka_launch task=novelty_generator database=island_small
Built-in Hydra presets ship inside the package under `shinka/configs/`. To add your own presets from a PyPI install without cloning the repo, place them in your own config directory and pass `--config-dir`:
mkdir -p ~/my-shinka-configs/variant
$EDITOR ~/my-shinka-configs/variant/my_variant.yaml
shinka_launch --config-dir ~/my-shinka-configs variant=my_variant
For development installs from source:
git clone https://github.com/SakanaAI/ShinkaEvolve
cd ShinkaEvolve
uv venv --python 3.11
source .venv/bin/activate  # On Windows: .venv\Scripts\activate
uv pip install -e .
For detailed installation instructions and usage examples, see the [Getting Started Guide](https://sakanaai.github.io/ShinkaEvolve/getting_started/).
What was scanned
The files the safety scan read, as written by the repository's author and shown as plain text. Lines with a finding are marked.
README.md · README · 581 lines
View this file on GitHub (read at the repository's current version: the scan did not record which commit it read)
- <h1 align="center">
- <a href="https://github.com/SakanaAI/ShinkaEvolve"><img src="https://raw.githubusercontent.com/SakanaAI/ShinkaEvolve/main/shinka/favicon.png" width="180" /></a><br>
- <b><code>ShinkaEvolve</code>: Towards Open-Ended and Sample-Efficient Program Evolution 🧬</b><br>
- </h1>
- <p align="center">
- <img src="https://img.shields.io/badge/python-%3E%3D3.10-blue" />
- <a href="https://pypi.org/project/shinka-evolve/"><img src="https://img.shields.io/pypi/v/shinka-evolve.svg" /></a>
- <a href="https://github.com/SakanaAI/ShinkaEvolve/blob/main/LICENSE"><img src="https://img.shields.io/badge/license-Apache2.0-blue.svg" /></a>
- <a href="https://github.com/astral-sh/ruff"><img src="https://img.shields.io/endpoint?url=https://raw.githubusercontent.com/astral-sh/ruff/main/assets/badge/v2.json" /></a>
- <a href="https://arxiv.org/abs/2509.19349"><img src="http://img.shields.io/badge/paper-arxiv.2509.19349-B31B1B.svg" /></a>
- <a href="https://sakana.ai/shinka-evolve/"><img src="https://img.shields.io/badge/Blog%20%7C%20Sakana-0A66C2.svg" /></a>
- <a href="https://colab.research.google.com/github/SakanaAI/ShinkaEvolve/blob/main/examples/shinka_tutorial.ipynb"><img src="https://colab.research.google.com/assets/colab-badge.svg" /></a>
- </p>
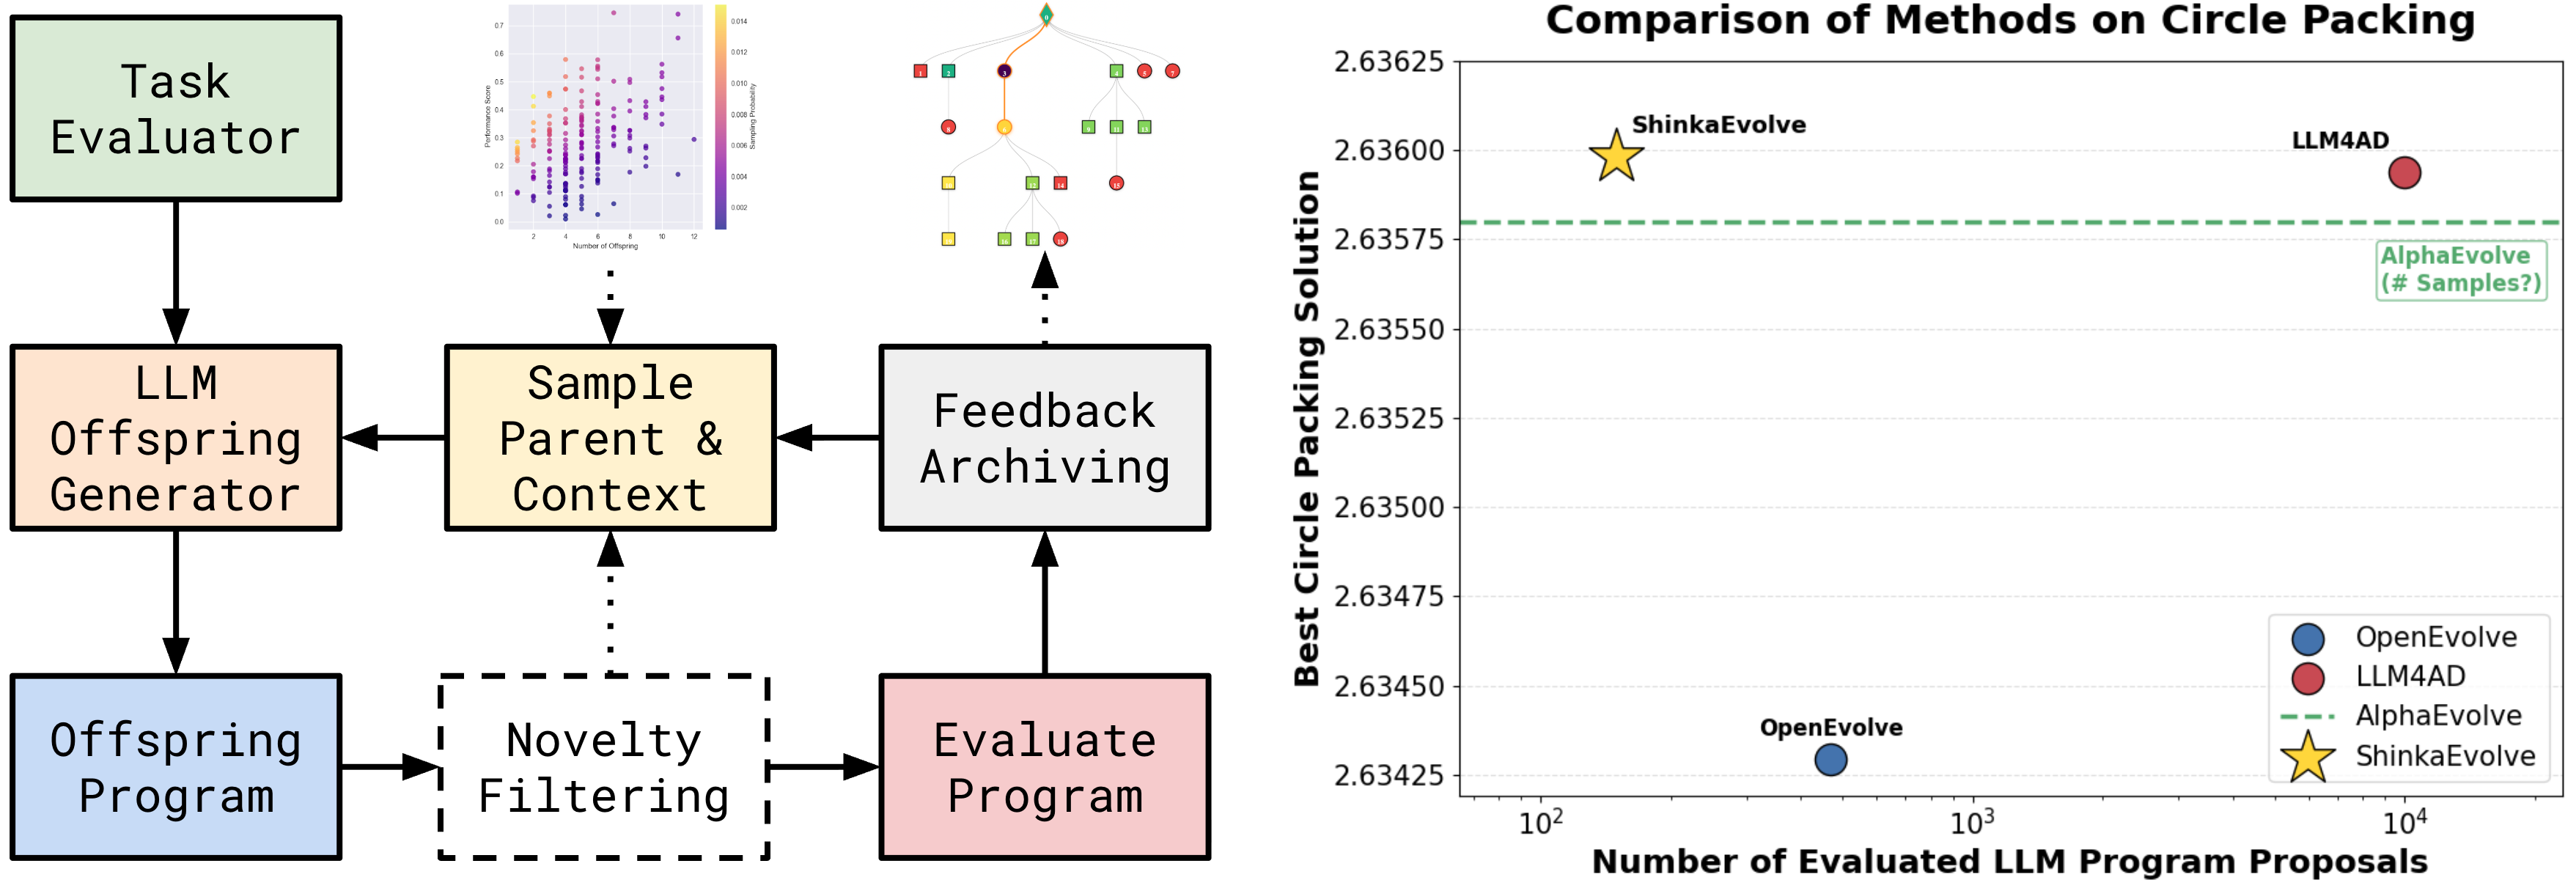
- [`shinka`](https://sakana.ai/shinka-evolve/) is a framework that combines Large Language Models (LLMs) with evolutionary algorithms to drive scientific discovery. By leveraging the creative capabilities of LLMs and the optimization power of evolutionary search, `shinka` enables automated exploration and improvement of scientific code. The system is inspired by the [AI Scientist](https://sakana.ai/ai-scientist/), [AlphaEvolve](https://deepmind.google/discover/blog/alphaevolve-a-gemini-powered-coding-agent-for-designing-advanced-algorithms/) and the [Darwin Goedel Machine](https://sakana.ai/dgm/): It maintains a population of programs that evolve over generations, with an ensemble of LLMs acting as intelligent mutation operators that suggest code improvements.
- ---
- **May 2026 Update**: Added [Headless](https://github.com/RobertTLange/headless-cli) CLI-backed mutation models for subscription-backed agent usage. Use model strings such as `headless/codex@gpt-5.5?effort=high` or `headless/claude`. Check the [example](https://github.com/SakanaAI/ShinkaEvolve/tree/main/examples/sine_approx_headless) for more detail.
- **Apr 2026 Update**: Added the new [documentation website](https://sakanaai.github.io/ShinkaEvolve/) with guides for getting started, configuration, async evolution, local models, WebUI usage, and agentic workflows.
- **Mar 2026 Update**: Refactored API and unified runner `ShinkaEvolveRunner` (replacing `EvolutionRunner` and `AsyncEvolutionRunner`). You can now install `shinka` via PyPI and `uv`: `pip install shinka-evolve`.
- **Feb 2026 Update**: Added [agent skills](https://sakanaai.github.io/ShinkaEvolve/agentic_usage/) for using `shinka` within coding agents (Claude Code, Codex, etc.) for new task generation ([`shinka-setup`](https://github.com/SakanaAI/ShinkaEvolve/blob/main/skills/shinka-setup/SKILL.md)), converting your repo ([`shinka-convert`](https://github.com/SakanaAI/ShinkaEvolve/blob/main/skills/shinka-convert/SKILL.md)), evolution ([`shinka-run`](https://github.com/SakanaAI/ShinkaEvolve/blob/main/skills/shinka-run/SKILL.md)), and result inspection ([`shinka-inspect`](https://github.com/SakanaAI/ShinkaEvolve/blob/main/skills/shinka-inspect/SKILL.md)). Install them via `npx`:
- ```
- npx skills add SakanaAI/ShinkaEvolve --skill '*' -a claude-code -a codex -y
- ```
- **Jan 2026 Update**: ShinkaEvolve was accepted at ICLR 2026 and we [released an update](https://github.com/SakanaAI/ShinkaEvolve/blob/main/CHANGELOG.md) with new features.
- **Nov 2025 Update**: Rob gave several public talks about our ShinkaEvolve effort ([Official](https://x.com/SakanaAILabs/status/1989352976792846356?s=20), [AutoML Seminar](https://www.youtube.com/watch?v=dAOIer_1INo)).
- **Oct 2025 Update** ShinkaEvolve supported Team Unagi in winning the [ICFP 2025 Programming Contest](https://sakana.ai/icfp-2025/).
- ---
- The framework supports **parallel evaluation of candidates** locally or on a Slurm cluster. It maintains an archive of successful solutions, enabling knowledge transfer between different evolutionary islands. `shinka` is particularly well-suited for scientific tasks where there is a verifier available and the goal is to optimize performance metrics while maintaining code correctness and readability.
- 
- ## Documentation 📝
- | Guide | Description | What You'll Learn |
- |-------|-------------|-------------------|
- | 🚀 **[First steps](https://sakanaai.github.io/ShinkaEvolve/getting_started/)** | Installation, basic usage, and examples | Setup, first evolution run, core concepts |
- | 📓 **[Tutorial](https://github.com/SakanaAI/ShinkaEvolve/blob/main/examples/shinka_tutorial.ipynb)** | Interactive walkthrough of Shinka | Hands-on examples, config, best practices |
- | ⚙️ **[Config](https://sakanaai.github.io/ShinkaEvolve/configuration/)** | Comprehensive config reference | All config options & advanced features |
- | 🎨 **[WebUI](https://sakanaai.github.io/ShinkaEvolve/webui/)** | Interactive visualization and monitoring | Real-time tracking, result analysis, debugging |
- | ⚡ **[Async Evo](https://sakanaai.github.io/ShinkaEvolve/async_evolution/)** | High-perf. throughput (5-10x speedup) | Concurrent processing, proposal/eval tuning |
- | 🧠 **[Local Models](https://sakanaai.github.io/ShinkaEvolve/support_local_models/)** | How to use local LLMs and embeddings with Shinka | Running open-source models & integration tips |
- | 🤖 **[Agentic Use](https://sakanaai.github.io/ShinkaEvolve/agentic_usage/)** | Run Shinka with Claude/Codex skills | CLI install, skill placement, setup/run workflows |
- ## Installation & Quick Start 🚀
- ```bash
- # Install from PyPI
- pip install shinka-evolve
- # Or with uv
- uv pip install shinka-evolve
- # Run your first evolution experiment
- shinka_launch variant=circle_packing_example
- ```
- The distribution name is `shinka-evolve`; Python imports stay `import shinka`.
- `shinka_launch` still supports the original shorthand group overrides:
- ```bash
- shinka_launch variant=circle_packing_example
- shinka_launch task=novelty_generator database=island_small
- ```
- Built-in Hydra presets ship inside the package under `shinka/configs/`. To add your own presets from a PyPI install without cloning the repo, place them in your own config directory and pass `--config-dir`:
- ```bash
- mkdir -p ~/my-shinka-configs/variant
- $EDITOR ~/my-shinka-configs/variant/my_variant.yaml
- shinka_launch --config-dir ~/my-shinka-configs variant=my_variant
- ```
- For development installs from source:
- ```bash
- git clone https://github.com/SakanaAI/ShinkaEvolve
- cd ShinkaEvolve
- uv venv --python 3.11
- source .venv/bin/activate # On Windows: .venv\Scripts\activate
- uv pip install -e .
- ```
- For detailed installation instructions and usage examples, see the [Getting Started Guide](https://sakanaai.github.io/ShinkaEvolve/getting_started/).
- ## Examples 📖
- | Example | Description | Environment Setup |
- |---------|-------------|-------------------|
- | ⭕ [Circle Packing](https://github.com/SakanaAI/ShinkaEvolve/tree/main/examples/circle_packing) | Optimize circle packing to maximize radii. | `LocalJobConfig` |
- | 🎮 [Game 2048](https://github.com/SakanaAI/ShinkaEvolve/tree/main/examples/game_2048) | Optimize a policy for the Game of 2048. | `LocalJobConfig` |
- | ∑ [Julia Prime Counting](https://github.com/SakanaAI/ShinkaEvolve/tree/main/examples/julia_prime_counting) | Optimize a Julia solver for prime-count queries. | `LocalJobConfig` |
- | 🔥 [Fortran Heat Diffusion](https://github.com/SakanaAI/ShinkaEvolve/tree/main/examples/fortran_heat_diffusion) | Optimize a compiled Fortran stencil solver. | `LocalJobConfig` |
- | 🧮 [Wolfram GCD Sum](https://github.com/SakanaAI/ShinkaEvolve/tree/main/examples/wolfram_gcd_sum) | Optimize a Wolfram Language GCD-sum solver. | `LocalJobConfig` |
- | ✨ [Novelty Generator](https://github.com/SakanaAI/ShinkaEvolve/tree/main/examples/novelty_generator) | Generate creative, surprising outputs (e.g., ASCII art). | `LocalJobConfig` |
- | ∿ [Sine Approx Headless](https://github.com/SakanaAI/ShinkaEvolve/tree/main/examples/sine_approx_headless) | Evolve a bounded sine approximation using Headless subscription-backed mutation calls. | `LocalJobConfig` |
- | ⚡ [RTLLM PPA](https://github.com/SakanaAI/ShinkaEvolve/tree/main/examples/rtllm) | Evolve Verilog RTL for power/performance/area under a fixed spec (RTLLM v2.0). Requires `iverilog` + `yosys` + `OpenSTA`. | `LocalJobConfig` |
- ## `shinka` Run with Python API 🐍
- For the simplest setup with default settings, you only need to specify the evaluation program:
- ```python
- from shinka.core import ShinkaEvolveRunner, EvolutionConfig
- from shinka.database import DatabaseConfig
- from shinka.launch import LocalJobConfig, SlurmCondaJobConfig, SlurmDockerJobConfig
- # Minimal - only specify what's required
- job_conf = LocalJobConfig(eval_program_path="evaluate.py")
- # Or source a uv/venv environment per job:
- # job_conf = LocalJobConfig(
- # eval_program_path="evaluate.py",
- # activate_script=".venv/bin/activate",
- # )
- # Or run evaluations on SLURM:
- # job_conf = SlurmCondaJobConfig(
- # eval_program_path="evaluate.py",
- # partition="gpu",
- # time="01:00:00",
- # cpus=1,
- # gpus=1,
- # mem="8G",
- # conda_env="shinka",
- # )
- # Or run evaluations in a Docker container on SLURM:
- # job_conf = SlurmDockerJobConfig(
- # eval_program_path="evaluate.py",
- # image="ubuntu:latest",
- # partition="gpu",
- # time="01:00:00",
- # cpus=1,
- # gpus=1,
- # mem="8G",
- # )
- db_conf = DatabaseConfig()
- evo_conf = EvolutionConfig(init_program_path="initial.py")
- runner = ShinkaEvolveRunner(
- evo_config=evo_conf,
- job_config=job_conf,
- db_config=db_conf,
- max_evaluation_jobs=2,
- max_proposal_jobs=3, # modest oversubscription when proposal generation is slower than eval
- max_db_workers=4,
- )
- runner.run()
- ```
- ### Live model pricing
- Shinka refreshes supported model metadata and token prices from
- [`models.dev`](https://models.dev) when a new run starts. Requests use HTTP
- cache validation, then fall back to the last validated user-cache response or
- the packaged snapshot when offline. The exact catalog used by a run is written
- to `pricing_snapshot.json` in its results directory and reused when that run is
- resumed.
- Set `SHINKA_PRICING_MODE=offline` to skip the network check, or
- `SHINKA_PRICING_MODE=required` to fail startup when live pricing cannot be
- validated. Run `shinka_models --verbose` to inspect catalog provenance and the
- models available for configured provider credentials.
- ### Weights & Biases logging
- Install the optional W&B integration and enable it for a run:
- ```bash
- pip install 'shinka-evolve[wandb]'
- # Authenticate online runs. In CI, provide this through a secret manager.
- export WANDB_API_KEY=<your-api-key>
- shinka_run --task-dir examples/circle_packing \
- --results_dir results/circle_wandb \
- --num_generations 20 \
- --set evo.enable_wandb_logging=true \
- --set evo.wandb_project=shinka-evolve
- ```
- W&B logging is additive: the existing SQLite database and WebUI logging remain
- enabled. Population and island snapshots use the monotonic
- `population/evaluated_count` axis for counts, correctness, scores, cumulative
- `cost/*`, and cumulative `timing/*_total`. Raw evaluated candidates use
- `score/individual` and `individual/*` fields without binding those events to a
- generation step. Administrative island copies remain in population/table counts
- but are excluded from evaluated count, candidate history, and costs. The final
- population is available as `population/final_table`, without program code or
- embeddings. Resuming the same results directory reuses its persisted W&B run ID
- by default. Online mode uses credentials from `wandb login` or `WANDB_API_KEY`;
- use `wandb_mode=offline` to record locally without uploading. See
- [Configuration](docs/configuration.md#evolutionconfig-shinkacoreconfigevolutionconfig)
- for all W&B options.
- Shinka disables W&B console, Git, code, requirements, machine, and system-stat
- capture. Run configuration contains an explicit allowlist of scalar experiment
- settings plus the recursively redacted `wandb_config` extension. Arbitrary
- `wandb_config` values cross the upload boundary when their keys are not
- recognized as sensitive, so do not put secrets or private data there. Candidate
- telemetry excludes private metrics and logs at most 64 public numeric metrics
- with keys no longer than 128 characters; secret-like metric names are dropped.
- Population snapshots use a dedicated serialized telemetry worker and a compact
- database aggregate, throttled to at most once every five seconds. Overlapping
- requests are coalesced so telemetry cannot stall active job processing. The
- bounded candidate queue drops the newest raw event with a rate-limited warning
- if saturated; population and final snapshots remain authoritative.
- <details>
- <summary><strong>EvolutionConfig Parameters</strong> (click to expand)</summary>
- Class defaults below come from `shinka/core/config.py` (`EvolutionConfig`). Hydra presets and CLI overrides can replace these values. Concurrency lives on `ShinkaEvolveRunner` via `max_evaluation_jobs`, `max_proposal_jobs`, and `max_db_workers`; the shared Hydra async launch path currently defaults to `4/6/2` for evaluation/proposal/DB workers.
- | Key | Default Value | Type | Explanation |
- |-----|---------------|------|-------------|
- | `task_sys_msg` | `"You are an expert optimization and algorithm design assistant. Improve the program while preserving correctness and immutable regions."` | `Optional[str]` | System message describing the optimization task |
- | `patch_types` | `["diff", "full", "cross"]` | `List[str]` | Types of patches to generate: "diff", "full", "cross" |
- | `patch_type_probs` | `[0.6, 0.3, 0.1]` | `List[float]` | Probabilities for each patch type |
- | `num_generations` | `50` | `int` | Number of evolution generations to run |
- | `max_patch_resamples` | `3` | `int` | Max times to resample a patch if it fails |
- | `max_patch_attempts` | `1` | `int` | Max attempts to generate a valid patch |
- | `job_type` | `"local"` | `str` | Job execution type: "local", "slurm_docker", "slurm_conda" |
- | `language` | `"python"` | `str` | Programming language for evolution |
- | `llm_models` | `["gpt-5-mini", "gemini-3-flash-preview", "gemini-3.1-pro-preview", "gpt-5.4"]` | `List[str]` | List of LLM models for code generation |
- | `llm_dynamic_selection` | `"ucb"` | `Optional[Union[str, BanditBase]]` | Dynamic model selection strategy |
- | `llm_dynamic_selection_kwargs` | `{"cost_aware_coef": 0.5}` | `dict` | Kwargs for dynamic selection |
- | `llm_kwargs` | `{"temperatures": [0.0, 0.5, 1.0], "max_tokens": 16384}` | `dict` | Additional kwargs for LLM calls |
- | `meta_rec_interval` | `10` | `Optional[int]` | Interval for meta-recommendations |
- | `meta_llm_models` | `None` | `Optional[List[str]]` | LLM models for meta-recommendations |
- | `meta_llm_kwargs` | `{}` | `dict` | Kwargs for meta-recommendation LLMs |
- | `meta_max_recommendations` | `5` | `int` | Max number of meta-recommendations |
- | `sample_single_meta_rec` | `True` | `bool` | Sample a single recommendation from meta output when enabled |
- | `embedding_model` | `"text-embedding-3-small"` | `Optional[str]` | Model for code embeddings. Also accepts `local/<model>@http(s)://host[:port]/v1` for local OpenAI-compatible embedding servers, with optional `?api_key_env=ENV_VAR` for per-model credentials. |
- | `init_program_path` | `"initial.py"` | `Optional[str]` | Path to initial program to evolve |
- | `results_dir` | `None` | `Optional[str]` | Directory to save results (auto-generated if None) |
- | `enable_wandb_logging` | `False` | `bool` | Mirror evolution metrics to W&B without disabling SQLite or WebUI logging |
- | `wandb_project` | `"shinka-evolve"` | `Optional[str]` | W&B project used when logging is enabled |
- | `wandb_entity` | `None` | `Optional[str]` | Optional W&B entity or team |
- | `wandb_group` | `None` | `Optional[str]` | Optional W&B run group |
- | `wandb_name` | `None` | `Optional[str]` | Optional run name; defaults to the results directory name |
- | `wandb_mode` | `None` | `Optional[str]` | Optional W&B mode such as `offline` or `disabled` |
- | `wandb_tags` | `[]` | `List[str]` | Optional W&B tags |
- | `wandb_notes` | `None` | `Optional[str]` | Optional W&B run notes |
- | `wandb_dir` | `None` | `Optional[str]` | Optional local W&B directory; defaults to `results_dir` |
- | `wandb_run_id` | `None` | `Optional[str]` | Optional W&B run ID; otherwise generated and persisted in the results directory |
- | `wandb_resume` | `"allow"` | `str` | W&B resume policy used with the persisted run ID |
- | `wandb_config` | `{}` | `Dict[str, Any]` | Extra values merged into the W&B run config |
- | `max_novelty_attempts` | `3` | `int` | Max attempts for novelty generation |
- | `code_embed_sim_threshold` | `0.99` | `float` | Similarity threshold for code embeddings |
- | `novelty_llm_models` | `None` | `Optional[List[str]]` | LLM models for novelty judgment |
- | `novelty_llm_kwargs` | `{}` | `dict` | Kwargs for novelty LLMs |
- | `use_text_feedback` | `False` | `bool` | Whether to use text feedback in evolution |
- | `max_api_costs` | `None` | `Optional[float]` | Total API budget cap (USD); async runner stops new proposals at cap |
- | `enable_controlled_oversubscription` | `False` | `bool` | Enable bounded proposal oversubscription when proposal generation is slower than evaluation. |
- | `proposal_target_mode` | `'adaptive'` | `str` | Proposal target controller mode (`adaptive` or `fixed`). |
- | `proposal_target_min_samples` | `5` | `int` | Minimum completed timing samples before adaptive targeting activates. |
- | `proposal_target_ratio_cap` | `2.0` | `float` | Maximum sampling/evaluation ratio used by the adaptive controller. |
- | `proposal_buffer_max` | `2` | `int` | Maximum extra proposal jobs beyond evaluation concurrency. |
- | `proposal_target_hard_cap` | `None` | `Optional[int]` | Absolute cap for the adaptive proposal target. |
- | `proposal_target_ewma_alpha` | `0.3` | `float` | EWMA smoothing factor for proposal/evaluation timing estimates. |
- | `inspiration_sort_order` | `"ascending"` | `str` | Inspiration ordering (`"ascending"`, `"chronological"`, `"none"`) |
- | `evolve_prompts` | `False` | `bool` | Enable meta-prompt evolution loop |
- | `prompt_patch_types` | `["diff", "full"]` | `List[str]` | Patch formats used for prompt evolution |
- | `prompt_patch_type_probs` | `[0.7, 0.3]` | `List[float]` | Sampling probabilities for prompt patch formats |
- | `prompt_evolution_interval` | `None` | `Optional[int]` | Prompt-evolution cadence in generations (`None` disables periodic updates) |
- | `prompt_archive_size` | `10` | `int` | Size of system-prompt archive |
- | `prompt_llm_models` | `None` | `Optional[List[str]]` | LLM models for prompt evolution (`None` falls back to `llm_models`) |
- | `prompt_llm_kwargs` | `{}` | `dict` | Extra kwargs for prompt-evolution LLM calls |
- | `prompt_ucb_exploration_constant` | `1.0` | `float` | UCB exploration constant for prompt sampling |
- | `prompt_epsilon` | `0.1` | `float` | Epsilon-greedy exploration probability for prompt sampling |
- | `prompt_evo_top_k_programs` | `3` | `int` | Number of top programs used as context in prompt evolution |
- | `prompt_percentile_recompute_interval` | `20` | `int` | Generations between prompt percentile recomputations |
- </details>
- <details>
- <summary><strong>DatabaseConfig Parameters</strong> (click to expand)</summary>
- Class defaults below come from `shinka/database/dbase.py` (`DatabaseConfig`). Hydra presets and CLI overrides can replace these values.
- | Key | Default Value | Type | Explanation |
- |-----|---------------|------|-------------|
- | `db_path` | `None` | `Optional[str]` | Database file path (auto-generated if None) |
- | `num_islands` | `2` | `int` | Number of evolution islands for diversity |
- | `archive_size` | `40` | `int` | Global archive size cap |
- | `elite_selection_ratio` | `0.3` | `float` | Proportion of elite programs for inspiration |
- | `num_archive_inspirations` | `1` | `int` | Number of archive programs to use as inspiration |
- | `num_top_k_inspirations` | `1` | `int` | Number of top-k programs for inspiration |
- | `migration_interval` | `10` | `int` | Generations between island migrations |
- | `migration_rate` | `0.0` | `float` | Proportion of island population to migrate |
- | `island_elitism` | `True` | `bool` | Keep best programs on their original islands |
- | `enforce_island_separation` | `True` | `bool` | Enforce full separation between islands |
- | `island_selection_strategy` | `"uniform"` | `str` | Island sampler (`"uniform"`, `"equal"`, `"proportional"`, `"weighted"`) |
- | `enable_dynamic_islands` | `False` | `bool` | Enable stagnation-triggered island spawning |
- | `stagnation_threshold` | `100` | `int` | Generations without improvement before spawning a new island |
- | `island_spawn_strategy` | `"initial"` | `str` | New-island seed strategy (`"initial"`, `"best"`, `"archive_random"`) |
- | `island_spawn_subtree_size` | `1` | `int` | Number of programs copied when spawning an island |
- | `parent_selection_strategy` | `"weighted"` | `str` | Parent selection: "weighted", "power_law", "beam_search" |
- | `exploitation_alpha` | `1.0` | `float` | Power-law exponent (0=uniform, 1=power-law) |
- | `exploitation_ratio` | `0.2` | `float` | Chance to pick parent from archive |
- | `parent_selection_lambda` | `10.0` | `float` | Sharpness of sigmoid for weighted selection |
- | `num_beams` | `5` | `int` | Number of beams for beam search selection |
- | `archive_selection_strategy` | `"fitness"` | `str` | Archive replacement strategy (`"fitness"` or `"crowding"`) |
- | `archive_criteria` | `{"combined_score": 1.0}` | `Dict[str, float]` | Weighted ranking criteria used by fitness archive updates |
- </details>
- <details>
- <summary><strong>JobConfig Parameters</strong> (click to expand)</summary>
- **LocalJobConfig** (for local execution):
- | Key | Default Value | Type | Explanation |
- |-----|---------------|------|-------------|
- | `eval_program_path` | `"evaluate.py"` | `Optional[str]` | Path to evaluation script |
- | `extra_cmd_args` | `{}` | `Dict[str, Any]` | Additional command line arguments |
- | `time` | `None` | `Optional[str]` | Time limit for job execution |
- | `conda_env` | `None` | `Optional[str]` | Conda environment to run jobs in |
- | `activate_script` | `None` | `Optional[str]` | Sourceable env script path, e.g. `.venv/bin/activate` |
- **SlurmDockerJobConfig** (for SLURM with Docker):
- | Key | Default Value | Type | Explanation |
- |-----|---------------|------|-------------|
- | `eval_program_path` | `"evaluate.py"` | `Optional[str]` | Path to evaluation script |
- | `extra_cmd_args` | `{}` | `Dict[str, Any]` | Additional command line arguments |
- | `image` | `"ubuntu:latest"` | `str` | Docker image to use |
- | `image_tar_path` | `None` | `Optional[str]` | Path to Docker image tar file |
- | `docker_flags` | `""` | `str` | Additional Docker flags |
- | `partition` | `"gpu"` | `str` | SLURM partition to use |
- | `time` | `"01:00:00"` | `str` | Job time limit |
- | `cpus` | `1` | `int` | Number of CPUs to request |
- | `gpus` | `1` | `int` | Number of GPUs to request |
- | `mem` | `"8G"` | `Optional[str]` | Memory to request |
- **SlurmCondaJobConfig / SlurmEnvJobConfig** (for SLURM with sourced or Conda environments):
- | Key | Default Value | Type | Explanation |
- |-----|---------------|------|-------------|
- | `eval_program_path` | `"evaluate.py"` | `Optional[str]` | Path to evaluation script |
- | `extra_cmd_args` | `{}` | `Dict[str, Any]` | Additional command line arguments |
- | `conda_env` | `""` | `str` | Conda environment name |
- | `activate_script` | `None` | `Optional[str]` | Sourceable env script path, e.g. `.venv/bin/activate` |
- | `modules` | `[]` | `Optional[List[str]]` | Environment modules to load |
- | `partition` | `"gpu"` | `str` | SLURM partition to use |
- | `time` | `"01:00:00"` | `str` | Job time limit |
- | `cpus` | `1` | `int` | Number of CPUs to request |
- | `gpus` | `1` | `int` | Number of GPUs to request |
- | `mem` | `"8G"` | `Optional[str]` | Memory to request |
- `conda_env` and `activate_script` are mutually exclusive.
- </details>
- ### Evaluation Setup & Initial Solution 🏃
- To use `ShinkaEvolveRunner`, you need two key files: The **`evaluate.py`** script defines how to test and score your programs - it runs multiple evaluations, validates results, and aggregates them into metrics that guide the `shinka` evolution loop. The **`initial.py`** file contains your starting solution with the core algorithm that will be iteratively improved by LLMs across generations.
- <table>
- <tr>
- <td width="50%">
- **`evaluate.py` - Evaluation Script**
- ```python
- from shinka.core import run_shinka_eval
- def main(program_path: str,
- results_dir: str):
- metrics, correct, err = run_shinka_eval(
- program_path=program_path,
- results_dir=results_dir,
- experiment_fn_name="run_experiment",
- num_runs=3, # Multi-evals to aggreg.
- run_workers=1, # >1 => per-run parallel
- get_experiment_kwargs=get_kwargs,
- aggregate_metrics_fn=aggregate_fn,
- validate_fn=validate_fn, # Optional
- )
- def get_kwargs(run_idx: int) -> dict:
- return {"param1": "value", "param2": 42}
- def aggregate_fn(results: list) -> dict:
- score = results[0]
- text = results[1]
- return {
- "combined_score": float(score),
- "public": {...}, # shinka-visible
- "private": {...}, # shinka-invisible
- "extra_data": {...}, # store as pkl
- "text_feedback": text, # str fb
- }
- if __name__ == "__main__":
- # argparse program path & dir
- main(program_path, results_dir)
- ```
- </td>
- <td width="50%">
- **`initial.py` - Starting Solution**
- ```python
- # EVOLVE-BLOCK-START
- def advanced_algo():
- # This will be evolved
- return solution
- # EVOLVE-BLOCK-END
- def run_experiment(**kwargs):
- """Main called by evaluator"""
- result = solve_problem(kwargs)
- return result
- def solve_problem(params):
- solution = advanced_algo()
- return solution
- ```
- **Key Points:**
- - Eval name matches `experiment_fn_name`
- - Use `EVOLVE-BLOCK-START` and `EVOLVE-BLOCK-END` to mark evolution sections
- - Return format matches validation expectations
- - Dependencies must be available in env
- - Results can be unpacked for metrics
- - Auto-stores several results in `results_dir`
- - Can add text feedback in `shinka` loop
- - Higher `combined_score` values indicate better performance (maximization)
- </td>
- </tr>
- </table>
- ## `shinka` Launcher with Hydra 🚀
- `shinka` Launcher utilizes [Hydra](https://hydra.cc/) to configure and launch evolutionary experiments effortlessly. It supports concise configuration via Hydra's powerful override syntax, making it easy to manage and iterate scientific explorations.
- ```bash
- # Run with the shared default baseline
- shinka_launch
- # Run with custom parameters
- shinka_launch \
- task=circle_packing \
- database=island_large \
- evolution=small_budget \
- cluster=local \
- evo_config.num_generations=20
- ```
- For comprehensive configuration options and advanced usage, see the [Configuration Guide](https://sakanaai.github.io/ShinkaEvolve/configuration/).
- ## `shinka_run` Agent CLI 🤖
- `shinka_run` is a task-directory launcher for async evolution. It is designed for agent workflows and does not require Hydra config files.
- ```bash
- # Inspect full interface (detailed help)
- shinka_run --help
- # Minimal run
- shinka_run \
- --task-dir examples/circle_packing \
- --results_dir results/circle_agent_run \
- --num_generations 20
- # Run with keyword overrides
- shinka_run \
- --task-dir examples/circle_packing \
- --results_dir results/circle_agent_custom \
- --num_generations 50 \
- --max-evaluation-jobs 6 \
- --set db.num_islands=2 \
- --set job.time=00:10:00 \
- --set job.activate_script=.venv/bin/activate \
- --set evo.llm_models='["gpt-5-mini","gemini-3-flash-preview"]'
- # Load optional YAML config (relative to --task-dir), then override via --set
- shinka_run \
- --task-dir examples/circle_packing \
- --config-fname shinka_small.yaml \
- --results_dir results/circle_agent_from_yaml \
- --num_generations 50 \
- --set db.num_islands=2
- ```
- `--task-dir` must contain `evaluate.py` and `initial.<ext>`.
- `--config-fname` can define `evo/db/job` (or `evo_config/db_config/job_config`) plus `max_evaluation_jobs/max_proposal_jobs/max_db_workers` and `verbose/debug`.
- Precedence: config YAML < `--set` < authoritative flags.
- `--results_dir` and `--num_generations` are authoritative and always override config/`--set` values for `evo.results_dir` and `evo.num_generations`.
- ### Headless Agent Models
- Use `headless/<agent>` model strings to route mutation calls through the local Headless CLI instead of provider API clients. Shinka uses `npx -y @roberttlange/headless` by default and runs `headless --check` before evolution starts.
- ```bash
- shinka_run \
- --task-dir examples/sine_approx_headless \
- --results_dir results/sine_approx_headless \
- --num_generations 5 \
- --max-evaluation-jobs 1 \
- --max-proposal-jobs 1 \
- --set evo.llm_models='["headless/codex@gpt-5.5?effort=high"]' \
- --set evo.embedding_model=null \
- --set evo.patch_types='["full", "diff"]' \
- --set evo.patch_type_probs='[0.5, 0.5]'
- ```
- For a Python runner using both Codex and Claude through Headless:
- ```bash
- python examples/sine_approx_headless/run_evo.py
- ```
- ## Interactive WebUI 🎨
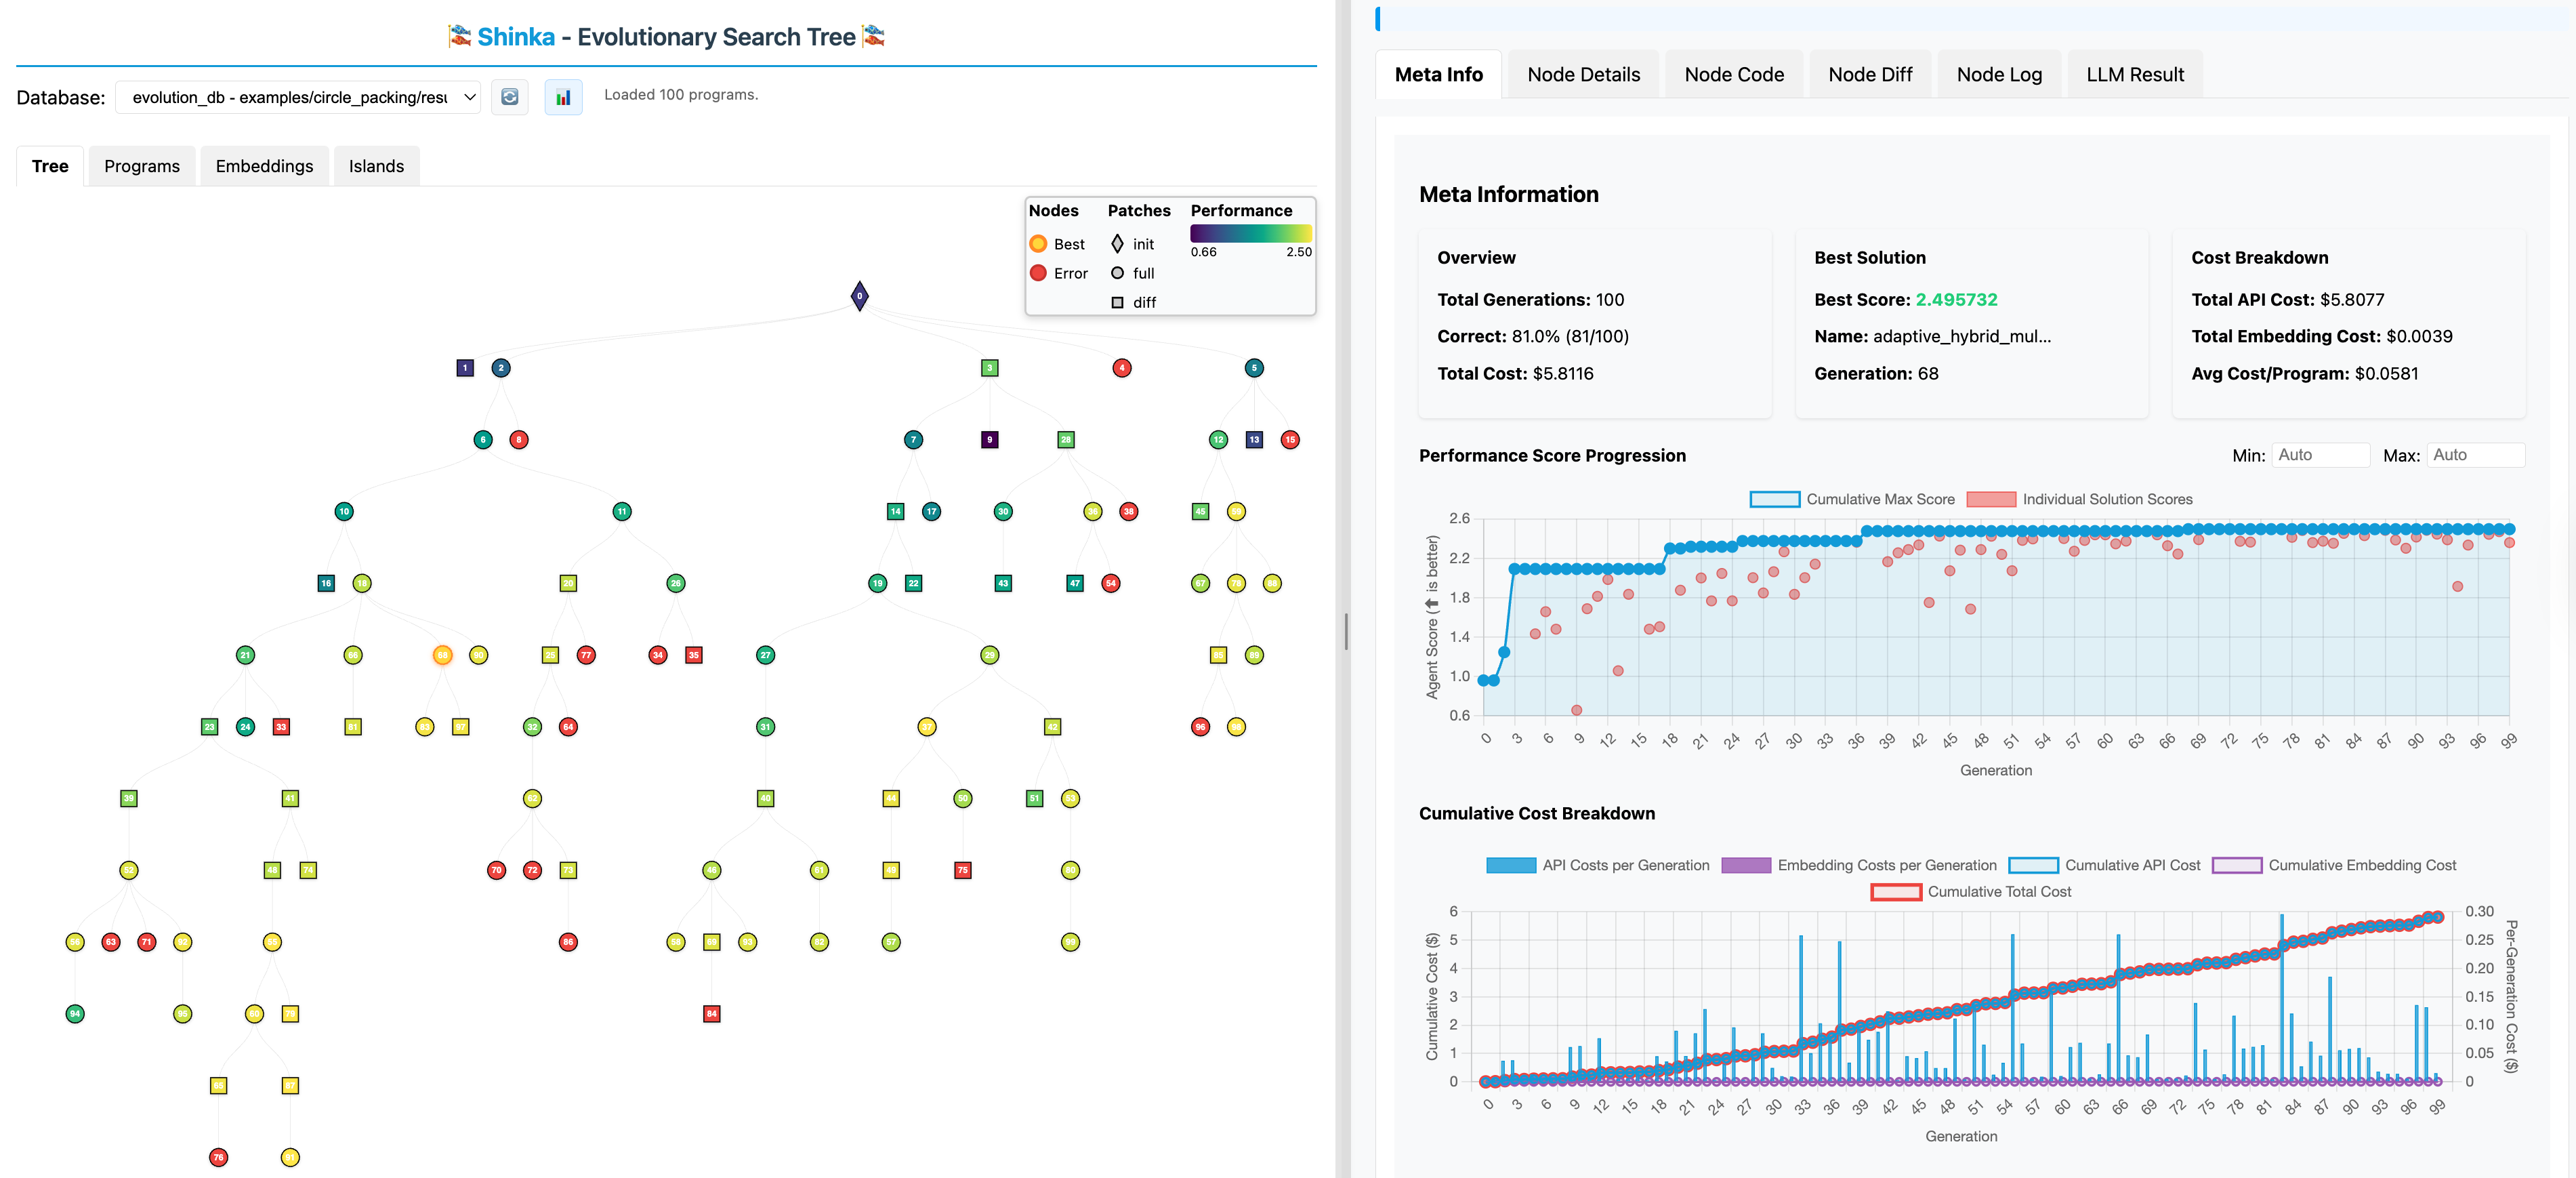
- Monitor your evolution experiments in real-time with Shinka's interactive web interface! The WebUI provides live visualization of the evolutionary process, genealogy trees, and performance metrics.
- 
- Launch the WebUI alongside your evolution experiment:
- ```bash
- # Start your evolution experiment
- shinka_launch
- # In another terminal, launch the WebUI
- shinka_visualize --port 8888 --open
- ```
- For detailed WebUI documentation, see the [WebUI Guide](https://sakanaai.github.io/ShinkaEvolve/webui/).
- ## Local Docs Development
- To preview the documentation site locally on `localhost`:
- ```bash
- uv sync --group docs
- uv run --group docs mkdocs serve --dev-addr 127.0.0.1:8000
- ```
- Then open `http://127.0.0.1:8000/`.
- ## Contributing 👥
- Contributions are welcome across code, docs, representative benchmarks, and bug reports.
- Please read the [contribution guide](https://github.com/SakanaAI/ShinkaEvolve/blob/main/CONTRIBUTING.md) before opening an issue or pull request. It documents the expected issue and PR structure, local checks, and the extra evidence required for changes to the core program evolution pipeline.
- If you propose a change to the core evolution pipeline, please include results on a representative runnable task that highlights the new capability and compare them against a baseline. Please do not add random benchmark tasks just to justify a PR.
- ## Related Open-Source Projects 🧑🔧
- - [OpenEvolve](https://github.com/codelion/openevolve): An open-source implementation of AlphaEvolve
- - [LLM4AD](https://github.com/Optima-CityU/llm4ad): A Platform for Algorithm Design with Large Language Model
- ## Citation ✍️
- If you use `ShinkaEvolve` in your research, please cite it as follows:
- ```
- @article{lange2025shinka,
- title={ShinkaEvolve: Towards Open-Ended And Sample-Efficient Program Evolution},
- author={Lange, Robert Tjarko and Imajuku, Yuki and Cetin, Edoardo},
- journal={arXiv preprint arXiv:2509.19349},
- year={2025}
- }
- ```
Ratings and comments
Sign in to rate this skill.
Sign inFree to use. If it’s helped, pass it on.