paper-search-mcp
MCP, CLI, Skills for searching and downloading academic papers from multiple sources like arXiv, PubMed, bioRxiv, etc.
Safety scan
A static text scan, not a guarantee. Select the badge to see what was scanned and every finding.
Badge for your README

Markdown
[](/listings/openags--paper-search-mcp)HTML
<a href="/listings/openags--paper-search-mcp"><img src="/api/listings/openags--paper-search-mcp/badge.svg" alt="findsafeskills safety rating" /></a>Install
Install instructions from the README
As written by the repo's author. findsafeskills has not verified these steps.
Choose the method that best fits your workflow. All methods support the same [optional API keys](#credential--api-key-requirements).
---
Claude Code (Skill) — recommended for Claude Code users
Install as a Claude Code skill instead of an MCP server. This gives Claude automatic access to paper search when you mention finding papers, academic literature, etc. — no MCP configuration needed.
**Prerequisites**: [uv](https://docs.astral.sh/uv/getting-started/installation/) and [Claude Code](https://docs.anthropic.com/en/docs/claude-code/overview).
**Step 1 — Install the CLI:**
uv tool install paper-search-mcp
**Step 2 — Install the skill:**
mkdir -p ~/.claude/skills/paper-search
curl -fsSL https://raw.githubusercontent.com/openags/paper-search-mcp/main/claude-code/SKILL.md \
  -o ~/.claude/skills/paper-search/SKILL.md
**Step 3 (optional) — Configure API keys:**
Create `~/.config/paper-search-mcp/.env` for optional API keys (see [Environment Variables](#environment-variables-env-file)).
**That's it.** Next time you start Claude Code, just ask it to find papers — the skill activates automatically. For example:
- "Find me recent papers on CRISPR base editing" - "Search arxiv and semantic scholar for transformer attention mechanisms" - "Download the PDF for arxiv paper 2106.12345"
The skill uses a CLI (`paper-search`) that wraps the same library as the MCP server, outputting JSON for search/download and plain text for read.
`paper-search download` reports `status: "ok"` only when the returned path is a readable, non-empty regular file with a PDF header. Connector error strings, missing files, and saved HTML error pages produce a JSON error and exit code 1. This lightweight check does not establish complete PDF integrity or paper identity; those checks remain the responsibility of the source connector and the reader.
Choose sources explicitly when latency matters:
paper-search search "gender imbalance neuroscience references" -s fast -n 3
paper-search search "gender imbalance neuroscience references" -s fastest -n 3
paper-search search "gender imbalance neuroscience references" -s all -n 3
paper-search download semantic DOI:10.1038/s41593-020-0658-y -o ./downloads
The CLI keeps `-s all` as its default broad source set. `--exhaustive` is an accepted compatibility no-op because broad search is already the default. Explicit `-s` selections always take precedence, including `-s fast` and `-s fastest`. The broad preset includes the supported public sources; optional paid sources are never added to these presets.
`-s fast` selects OpenAlex, Crossref, arXiv, PubMed, and Europe PMC. A nonblank `PAPER_SEARCH_MCP_SEMANTIC_SCHOLAR_API_KEY` (or legacy `SEMANTIC_SCHOLAR_API_KEY`) also includes Semantic Scholar. `-s fastest` selects only OpenAlex and Crossref. Presets are latency-oriented choices, not guarantees of response time or exhaustive literature coverage. Anonymous Semantic Scholar 429 responses fail immediately; authenticated requests retain bounded retries.
Only selected searchers are constructed. Source lists and presets are honored exactly: a DOI in the query never adds another source. Use `-s unpaywall` for a DOI lookup, or include `unpaywall` explicitly in a comma-separated source list. The broad `all` preset already includes it. MCP server search defaults are unchanged.
To stop a slow source from holding up a CLI search, opt into a per-source deadline:
paper-search search "robot scientist" -s fast --source-timeout 45
`--source-timeout SECONDS` must be positive and finite. It runs selected sources in separate Python processes, at most four at once. Each source's budget starts after OS process creation returns and includes Python/provider initialization, search, serialization, and worker exit. Process creation, time waiting for a worker slot, and process cleanup add overhead outside that budget. It is
What was scanned
The files the safety scan read, as written by the repository's author and shown as plain text. Lines with a finding are marked.
README.md · README · 838 lines
View this file on GitHub (read at the repository's current version: the scan did not record which commit it read)
- # Paper Search MCP
- A Model Context Protocol (MCP) server for searching and downloading academic papers from multiple sources. The project follows a free-first strategy: prioritize open and public data sources, support optional API keys when they improve stability or coverage, and keep source-specific connectors extensible for advanced users.
-   
- [](https://smithery.ai/server/@openags/paper-search-mcp)
- ---
- ## Table of Contents
- - [Overview](#overview)
- - [Project Principles](#project-principles)
- - [MCP Authorization Compatibility](#mcp-authorization-compatibility)
- - [Features](#features)
- - [Source Strategy](#source-strategy)
- - [Sci-Hub Notice](#sci-hub-notice)
- - [Installation](#installation)
- - [Claude Code (Skill)](#claude-code-skill--recommended-for-claude-code-users)
- - [Method 1 — Smithery](#method-1--smithery-one-command-recommended-for-claude-desktop)
- - [Method 2 — uvx](#method-2--uvx-no-install-always-latest)
- - [Method 3 — uv](#method-3--uv-persistent-install)
- - [Method 4 — pip](#method-4--pip-standard-python-install)
- - [Method 5 — npx](#method-5--npx-via-smithery-cli-no-local-python-needed)
- - [Method 6 — Docker](#method-6--docker)
- - [Method 7 — Clone & run from source](#method-7--clone--run-from-source-development--recommended-for-macos-local)
- - [DeepSeek Harness (DSH)](#deepseek-harness-dsh)
- - [Environment Variables](#environment-variables-env-file)
- - [Contributing](#contributing)
- - [Demo](#demo)
- - [Star History](#star-history)
- - [License](#license)
- - [TODO](#todo)
- ---
- ## Overview
- `paper-search-mcp` is a Python-based tool for searching and downloading academic papers from various platforms. It provides tools for searching papers, downloading PDFs, and extracting text, making it ideal for researchers and AI-driven workflows. It can be used as an MCP server (for Claude Desktop and other MCP clients) or as a Claude Code skill with a CLI interface.
- ## Project Principles
- - **Free-First**: Public and open sources are the default roadmap. Paid or restricted sources are not the core direction of this project.
- - **Optional API Keys**: API keys are supported only when they improve stability, rate limits, or metadata quality. The MCP should still be usable without them whenever possible.
- - **LLM-Friendly Retrieval**: Search results should be standardized, deduplicated, and as complete as possible for downstream LLM workflows.
- - **Source Transparency**: Different sources have different strengths. The MCP should make those tradeoffs explicit instead of pretending every source supports full-text retrieval.
- ---
- ## MCP Authorization Compatibility
- The bundled MCP server supports `stdio` (the default), `sse`, and `streamable-http`. Network transports bind to `127.0.0.1` by default. Optional OAuth protected-resource mode adds standard discovery, JWT bearer-token validation and required scopes to both HTTP transports, using an external authorization server.
- Enable it with `--auth oauth` or `PAPER_SEARCH_MCP_AUTH=oauth` and the explicit issuer/JWKS/resource/audience/scope configuration in [OAuth protected-resource setup](docs/OAUTH_PROTECTED_RESOURCE.md). Invalid or incomplete HTTP auth settings fail startup. stdio remains independent of HTTP authentication. Local HTTP without OAuth configuration remains open; do not publish that listener directly. A protected remote deployment still needs TLS, rate limits and filesystem isolation. This feature does not host login/accounts or replace the external issuer's OAuth flow; live identity-provider interoperability must be validated for your deployment.
- ---
- ## Features
- - **Two-Layer Architecture**:
- - **Layer 1 (Unified Tooling)**: High-level `search_papers` for multi-source concurrent search & deduplication, and `download_with_fallback` relying on publisher open access links with sequential fallbacks.
- - **Layer 2 (Platform Connectors)**: Modular connectors for specific academic platforms (arXiv, PubMed, bioRxiv, Semantic Scholar, etc.) equipped with intelligent DOI extraction via regex text analysis or API fields.
- - **Multi-Source Support**: Search and download papers from arXiv, PubMed, bioRxiv, medRxiv, Google Scholar, IACR ePrint Archive, Semantic Scholar, Crossref, OpenAlex, PubMed Central (PMC), CORE, Europe PMC, dblp, OpenAIRE, CiteSeerX, DOAJ, BASE, Zenodo, HAL, SSRN, OpenReview, Unpaywall (DOI lookup), and optional Sci-Hub workflows.
- - **Opt-in Fast Search**: CLI search keeps broad coverage by default. Use `-s fast` (OpenAlex, Crossref, arXiv, PubMed, Europe PMC) or `-s fastest` (OpenAlex and Crossref) when lower latency matters more than coverage.
- - **Standardized Output**: Papers are returned in a consistent dictionary format via the `Paper` class.
- - **Free-First Design**: Open and public sources are prioritized before any optional commercial or restricted integrations.
- - **Optional API-Key Enhancement**: Sources like Semantic Scholar can work better with a user-provided API key, but are not intended to force paid usage.
- - **Discovery + Retrieval Workflow**: Google Scholar and Crossref can be used for discovery and DOI backfilling, while open repositories and publisher links are used for lawful full-text resolution where available.
- - **OA-First Fallback Chain**: `download_with_fallback` now follows source-native download → OpenAIRE/CORE/Europe PMC/PMC discovery → Unpaywall DOI resolution → optional Sci-Hub.
- - **Bounded reference lookups**: [OpenAlex references and citing papers](docs/OPENALEX_RELATIONSHIPS.md) from a DOI or OpenAlex ID, with explicit budgets and truncation metadata.
- - **MCP Integration**: Compatible with MCP clients for LLM context enhancement.
- - **DeepSeek Harness (DSH) Integration**: A dsh profile bundle (clone the repo, `npx @deepseek-ai/dsh@0.2.0-rc.2 plugin --profile web add link:./dsh`) exposing every tool as `mcp__paper-search__*`, with an optional guidance skill.
- - **Extensible Design**: Easily add new academic platforms by extending the `academic_platforms` module.
- ## Source Strategy
- The long-term goal is not to depend on a single search engine, but to combine multiple free and public sources with clear roles:
- - **Open metadata backbone**: Crossref, OpenAlex, Semantic Scholar, dblp, CiteSeerX, SSRN, Unpaywall (DOI-centric OA metadata).
- - **Discipline-specific sources**: arXiv, PubMed, PubMed Central, Europe PMC, IACR.
- - **Open-access full-text sources**: arXiv, PMC, CORE, OpenAIRE, DOAJ, BASE, Zenodo, HAL, publisher open-access links.
- - **Discovery and DOI recovery**: Google Scholar can be useful for finding titles, versions, and DOI clues when other public metadata sources are incomplete.
- Recommended free-first roadmap:
- 1. Keep current public sources stable.
- 2. Add OpenAlex as a broad free metadata source.
- 3. Add PubMed Central and Europe PMC for stronger biomedical full-text access.
- 4. Add CORE and OpenAIRE for repository-based open-access retrieval.
- 5. Use Google Scholar mainly as a discovery fallback, not as the primary canonical source.
- ## Platform Capability Matrix
- This matrix reflects **verified live-integration results** from functional and end-to-end regression tests in this repository. Columns show the highest capability level observed under normal conditions.
- | Platform | Search | Download | Read | Notes |
- |---|---|---|---|---|
- | arXiv | ✅ | ✅ | ✅ | Open API; reliable |
- | PubMed | ✅ | ❌ | ⚠️ info-only | Open API; reliable |
- | bioRxiv | ✅ | ✅ | ✅ | Open API; reliable |
- | medRxiv | ✅ | ✅ | ✅ | Open API; reliable |
- | Google Scholar | ⚠️ | ❌ | ❌ | Upstream bot-detection/rate limits can prevent search; reported as source errors |
- | IACR | ✅ | ✅ | ✅ | Open API; reliable |
- | Semantic Scholar | ✅ | ✅ (OA) | ✅ (OA) | Works without key (rate-limited); key improves limits; key rejection (403) retried automatically without key |
- | Crossref | ✅ | ❌ | ⚠️ info-only | Open API; reliable |
- | OpenAlex | ✅ | ❌ | ⚠️ info-only | Open API; free API key improves daily limits |
- | PMC | ✅ | ✅ (OA only) | ✅ (OA only) | OA PDFs only; direct download may be blocked by some proxy environments |
- | CORE | ✅ | ✅ (record-dependent) | ✅ (record-dependent) | Free key recommended; connector retries with backoff and falls back to key-less on 401/403 |
- | Europe PMC | ✅ | ✅ (OA) | ✅ (OA) | OA PDFs only; direct download may be blocked by some proxy environments |
- | dblp | ✅ | ❌ | ⚠️ info-only | Open API; reliable |
- | OpenAIRE | ✅ | ❌ | ❌ | Open API; retries 3× with escalating request profiles on transient 403 |
- | CiteSeerX | ⚠️ | ✅ (record-dependent) | ⚠️ | API endpoint intermittently unavailable / redirects to web archive |
- | DOAJ | ✅ | ⚠️ (URL-dependent) | ⚠️ (URL-dependent) | PDF availability varies by article; free key raises rate limits |
- | BASE | ⚠️ | ✅ (record-dependent) | ✅ (record-dependent) | OAI-PMH endpoint requires institutional IP registration; returns empty gracefully otherwise |
- | Zenodo | ✅ | ✅ (record-dependent) | ✅ (record-dependent) | Open API; reliable |
- | HAL | ✅ | ✅ (record-dependent) | ✅ (record-dependent) | Open API; reliable |
- | SSRN | ✅ (OpenAlex metadata) | ⚠️ best-effort | ⚠️ best-effort | Public discovery verified; SSRN page/PDF identity must be verified separately |
- | OpenReview | ✅ (anonymous API v2) | ⚠️ public-only | ⚠️ public-only | Search verified; exact-note lookup returned 403 in live PDF check; PDF success is mock-tested only |
- | Unpaywall | ✅ (DOI lookup) | ❌ | ❌ | **Requires** `PAPER_SEARCH_MCP_UNPAYWALL_EMAIL` |
- | Sci-Hub (optional) | ⚠️ fallback-only | ✅ | ❌ | Optional; unstable mirrors; user responsibility |
- | **IEEE Xplore** 🔑 | ⚠️ configured metadata | ❌ | ❌ | Deterministic tests only; no live key-authenticated validation; metadata key does not grant full text |
- | **ACM DL** | ✅ (Crossref metadata) | ⚠️ | ⚠️ | Keyless search; direct PDF/read may be blocked by browser challenges; use OA fallback |
- > ✅ = reliable in live tests. ⚠️ = works but subject to upstream instability or access restrictions. ❌ = not supported. 🔑 = key required. 🚧 = skeleton only.
- ---
- ## Credential & API Key Requirements
- All keys are **optional** unless noted. Configure them in `~/.config/paper-search-mcp/.env` (preferred) or as shell exports.
- | Environment Variable | Provider | Required? | How to obtain |
- |---|---|---|---|
- | `PAPER_SEARCH_MCP_UNPAYWALL_EMAIL` | Unpaywall | **Yes** (Unpaywall disabled without it) | Any valid email; register at [unpaywall.org](https://unpaywall.org/products/api) |
- | `PAPER_SEARCH_MCP_CORE_API_KEY` | CORE | Recommended | Free at [core.ac.uk/services/api](https://core.ac.uk/services/api) |
- | `PAPER_SEARCH_MCP_SEMANTIC_SCHOLAR_API_KEY` | Semantic Scholar | Optional | Free at [semanticscholar.org](https://www.semanticscholar.org/product/api) — improves rate limits |
- | `PAPER_SEARCH_MCP_OPENALEX_API_KEY` | OpenAlex | Optional | Free at [openalex.org/settings/api](https://openalex.org/settings/api); increases the keyless daily budget 10x |
- | `PAPER_SEARCH_MCP_OPENALEX_EMAIL` | OpenAlex | Optional | Contact email used in the OpenAlex `User-Agent` |
- | `PAPER_SEARCH_MCP_GOOGLE_SCHOLAR_PROXY_URL` | Google Scholar | Optional | Your HTTP/HTTPS proxy URL; does not guarantee access or remove provider limits |
- | `PAPER_SEARCH_MCP_DOAJ_API_KEY` | DOAJ | Optional | Free at [doaj.org](https://doaj.org/apply-for-api-key/) — raises hourly rate limit |
- | `PAPER_SEARCH_MCP_ZENODO_ACCESS_TOKEN` | Zenodo | Optional | Free at [zenodo.org](https://zenodo.org/account/settings/applications/) — required for private records |
- | `PAPER_SEARCH_MCP_IEEE_API_KEY` | IEEE Xplore | **Required to activate** | Free at [developer.ieee.org](https://developer.ieee.org/) |
- All variables follow the `PAPER_SEARCH_MCP_<NAME>` prefix scheme. Legacy names without the prefix (e.g. `CORE_API_KEY`, `UNPAYWALL_EMAIL`) are still supported for backward compatibility.
- ---
- ## Known Upstream Limitations
- Some search failures are caused by external provider instability, not by bugs in this project:
- | Source | Symptom | Cause | Workaround |
- |---|---|---|---|
- | Google Scholar | Source error for HTTP/network failures, CAPTCHA, or persistent consent pages | Upstream rate limits, access checks, or connectivity | Reduce request frequency or use another public source; CAPTCHA is not solved automatically |
- | Semantic Scholar | 429 rate-limited responses | Anonymous access rate limit | Set `PAPER_SEARCH_MCP_SEMANTIC_SCHOLAR_API_KEY`; if key is rejected (403) connector automatically retries without key |
- | OpenAlex | 403/429 or daily quota errors | Anonymous access daily limit | Set `PAPER_SEARCH_MCP_OPENALEX_API_KEY` |
- | CORE | 500 / timeout errors | Unauthenticated rate limiting | Set `PAPER_SEARCH_MCP_CORE_API_KEY` (free); connector retries with exponential backoff and falls back to key-less on 401/403 |
- | OpenAIRE | Transient 403 responses | IP-based session rate limiting | Connector retries 3× per profile, escalating: plain session → XML Accept header → raw `requests.get` with Mozilla UA |
- | CiteSeerX | 404 via web archive redirect | PSU endpoint intermittently redirects to archive | No workaround; connector returns empty gracefully |
- | BASE | Search returns 0 results | OAI-PMH endpoint requires institutional IP registration | Register at [base-search.net](https://www.base-search.net/about/en/) for API access; connector returns empty gracefully otherwise |
- | SSRN full text | HTTP 403 or identity unavailable | Public page/PDF delivery may be restricted | Search uses OpenAlex; download reports failure without login, redirects or HTML search fallback |
- | PMC / Europe PMC | PDF download ProxyError | Local proxy blocking direct HTTPS PDF download | Disable proxy or use `download_with_fallback` instead |
- | Unpaywall | Skipped entirely | `UNPAYWALL_EMAIL` env var not set | Set `PAPER_SEARCH_MCP_UNPAYWALL_EMAIL` in `~/.config/paper-search-mcp/.env` |
- Google Scholar failures are exposed in `errors.google_scholar` by unified MCP
- and CLI search, while successful sources still return their papers. Direct
- Scholar searches raise `GoogleScholarSearchError` for those failures. A normal
- empty result page still returns an empty list. If a later page fails, the source
- is reported as failed rather than returning its earlier pages as complete.
- Timeouts also raise a source error rather than implying that no papers exist.
- After exhausted HTTP 403/429/503 retries or a CAPTCHA, the shared Scholar
- connector enters a 60-second cooldown. Consecutive blocked searches extend it
- exponentially up to 15 minutes; a valid upstream `Retry-After` can extend this
- interval. A successful page resets the streak. Calls during cooldown fail
- immediately with a retry interval and do not contact Scholar. Retries honor
- valid `Retry-After` seconds or HTTP dates up to 24 hours. Longer instructions
- pause automatic requests for the lifetime of this connector instead of retrying
- earlier than the provider requested. Delays above 30 seconds are carried across
- calls without sleeping in a worker. Concurrent calls share the same paced session. The connector does not rotate
- identity between requests or solve CAPTCHAs. Cooldown state is process-local,
- not a guarantee of an upstream quota or recovery after that interval.
- For a survey, select alternative sources explicitly, for example MCP
- `search_papers(query, sources="google_scholar,openalex,semantic,crossref")` or CLI
- `paper-search search "query" -s google_scholar,openalex,semantic,crossref`.
- Successful providers keep their own source labels and their papers even when
- Scholar is cooling down. Alternatives have their own access/rate limits; they
- are never silently returned as Google Scholar results.
- ## Local PDF section extraction
- `extract_sections` splits an already-downloaded PDF at recognized standalone
- headings, preserving extracted text order and page spans with explicit limits
- and truncation. Reads are confined to the configured download root; no network,
- OCR, medical inference or new dependency is added. Labels are heuristic and may
- be uncertain. See [bounded PDF sections](docs/PDF_SECTIONS.md) for access rules,
- CLI usage and parser limitations.
- ### arXiv PDF downloads and reads
- arXiv downloads validate bare modern/legacy paper IDs, serialize and pace requests,
- check HTTP status, stream at most 100 MiB to a same-directory temporary file, and
- check the PDF header and parser before atomically replacing the destination.
- A failed transfer or invalid PDF leaves an existing file unchanged. Downloads
- use 10-second connect and 30-second read timeouts, not a hard total transfer
- or parser runtime limit, and do not automatically retry denied responses.
- `read arxiv` reports invalid/encrypted/image-only PDFs as errors rather than
- successful empty output; it does not perform OCR or delete invalid cached files.
- ## Optional Paid Platform Connectors (Phase 3)
- IEEE Xplore provides **opt-in metadata search**, disabled until an existing API key is configured.
- ACM Digital Library search is **keyless and enabled by default**, using Crossref metadata restricted to ACM DOI prefix `10.1145`.
- | Platform | Env Var | Status |
- |---|---|---|
- | IEEE Xplore | `PAPER_SEARCH_MCP_IEEE_API_KEY` | Metadata search with pagination; direct download/read remain unsupported |
- | ACM Digital Library | None | Crossref-backed search; PDF download/read depend on publisher access |
- **How to enable:**
- ```bash
- export PAPER_SEARCH_MCP_IEEE_API_KEY=<your_ieee_key> # free key at https://developer.ieee.org/
- ```
- With an IEEE key, `ieee` and its tools are registered at startup. See [IEEE metadata limits and full-text boundaries](docs/IEEE_METADATA.md). ACM (`acm`, `search_acm`, `download_acm`, and `read_acm_paper`) is always available. Legacy `PAPER_SEARCH_MCP_ACM_API_KEY` / `ACM_API_KEY` settings are no longer used and can be removed.
- ACM downloads require an ACM DOI such as `10.1145/...`. Publisher browser challenges may block scripted access; use `download_with_fallback(source="acm", paper_id="10.1145/...", doi="10.1145/...")` to try open repositories. `read_acm_paper` downloads a PDF into `save_path` before extracting text and can overwrite that file.
- ## Free Source Expansion (Phase 4)
- Additional public-source connectors are integrated into the MCP server:
- - `zenodo`: Official Zenodo REST API connector (search + record-dependent PDF/read support).
- - `hal`: HAL public API connector (search + record-dependent PDF/read support).
- - `ssrn`: [OpenAlex-backed discovery](docs/SSRN_OPENALEX.md) with strict SSRN identity and validated best-effort public downloads.
- - `openreview`: [Anonymous public API v2 papers](docs/OPENREVIEW.md), excluding reviews/private notes; verified OpenReview-hosted PDF download/read.
- - `unpaywall`: DOI-centric OA metadata source for standalone lookup (`search_unpaywall`) and fallback URL resolution.
- SSRN integration remains compliance-first: it only attempts direct public PDF links exposed by SSRN pages. If login/restricted delivery is required, the connector returns a clear message instead of bypassing access controls.
- ## Sci-Hub Notice
- Sci-Hub support can remain available as an optional connector for users who explicitly choose to enable it, but it should not be treated as the default or recommended full-text path.
- - `download_with_fallback` leaves Sci-Hub disabled by default. Pass `use_scihub=true` only when you explicitly choose to use it.
- - Availability is unstable and mirrors change frequently.
- - Legal and policy risks vary by jurisdiction.
- - README and tool descriptions should clearly state that users are responsible for enabling and using it.
- - Open-access and publisher-permitted sources should be tried first whenever possible.
- ---
- ## Installation
- Choose the method that best fits your workflow. All methods support the same [optional API keys](#credential--api-key-requirements).
- ---
- ### Claude Code (Skill) — recommended for Claude Code users
- Install as a Claude Code skill instead of an MCP server. This gives Claude automatic access to paper search when you mention finding papers, academic literature, etc. — no MCP configuration needed.
- **Prerequisites**: [uv](https://docs.astral.sh/uv/getting-started/installation/) and [Claude Code](https://docs.anthropic.com/en/docs/claude-code/overview).
- **Step 1 — Install the CLI:**
- ```bash
- uv tool install paper-search-mcp
- ```
- **Step 2 — Install the skill:**
- ```bash
- mkdir -p ~/.claude/skills/paper-search
- curl -fsSL https://raw.githubusercontent.com/openags/paper-search-mcp/main/claude-code/SKILL.md \
- -o ~/.claude/skills/paper-search/SKILL.md
- ```
- **Step 3 (optional) — Configure API keys:**
- Create `~/.config/paper-search-mcp/.env` for optional API keys (see [Environment Variables](#environment-variables-env-file)).
- **That's it.** Next time you start Claude Code, just ask it to find papers — the skill activates automatically. For example:
- - "Find me recent papers on CRISPR base editing"
- - "Search arxiv and semantic scholar for transformer attention mechanisms"
- - "Download the PDF for arxiv paper 2106.12345"
- The skill uses a CLI (`paper-search`) that wraps the same library as the MCP server, outputting JSON for search/download and plain text for read.
- `paper-search download` reports `status: "ok"` only when the returned path is a
- readable, non-empty regular file with a PDF header. Connector error strings,
- missing files, and saved HTML error pages produce a JSON error and exit code 1.
- This lightweight check does not establish complete PDF integrity or paper identity;
- those checks remain the responsibility of the source connector and the reader.
- Choose sources explicitly when latency matters:
- ```bash
- paper-search search "gender imbalance neuroscience references" -s fast -n 3
- paper-search search "gender imbalance neuroscience references" -s fastest -n 3
- paper-search search "gender imbalance neuroscience references" -s all -n 3
- paper-search download semantic DOI:10.1038/s41593-020-0658-y -o ./downloads
- ```
- The CLI keeps `-s all` as its default broad source set. `--exhaustive` is an
- accepted compatibility no-op because broad search is already the default.
- Explicit `-s` selections always take precedence, including `-s fast` and
- `-s fastest`. The broad preset includes the supported public sources;
- optional paid sources are never added to these presets.
- `-s fast` selects OpenAlex, Crossref, arXiv, PubMed, and Europe PMC. A nonblank
- `PAPER_SEARCH_MCP_SEMANTIC_SCHOLAR_API_KEY` (or legacy
- `SEMANTIC_SCHOLAR_API_KEY`) also includes Semantic Scholar. `-s fastest` selects
- only OpenAlex and Crossref. Presets are latency-oriented choices, not guarantees
- of response time or exhaustive literature coverage. Anonymous Semantic Scholar
- 429 responses fail immediately; authenticated requests retain bounded retries.
- Only selected searchers are constructed. Source lists and presets are honored
- exactly: a DOI in the query never adds another source. Use `-s unpaywall` for a
- DOI lookup, or include `unpaywall` explicitly in a comma-separated source list.
- The broad `all` preset already includes it. MCP server search defaults are
- unchanged.
- To stop a slow source from holding up a CLI search, opt into a per-source deadline:
- ```bash
- paper-search search "robot scientist" -s fast --source-timeout 45
- ```
- `--source-timeout SECONDS` must be positive and finite. It runs selected sources
- in separate Python processes, at most four at once. Each source's budget starts
- after OS process creation returns and includes Python/provider initialization,
- search, serialization, and worker exit. Process creation, time waiting for a
- worker slot, and process cleanup add overhead outside that budget. It is
- not a deadline for the whole command. Timed-out workers are killed and reaped
- before their slots are reused, so a blocked network call cannot hold up Python's
- thread-executor shutdown. Successful sources keep their results and timed-out
- sources appear in `errors` with a zero `source_results` count. Source selection,
- labels, sorting, JSON fields, and partial-result exit status (0) are unchanged.
- Subprocess startup adds overhead, especially for very small budgets. Without the
- flag, existing connector-specific timeouts and in-process search are unchanged.
- Sort search results by citation count or publication date:
- ```bash
- paper-search search "transformer attention" --sources arxiv,semantic --sort citations
- paper-search search "CRISPR" --sort date
- ```
- `--sort relevance` (the default) preserves the existing order: selected sources
- in order, with each source's returned order unchanged. It does not compute a
- cross-source relevance score. `--sort citations` orders highest counts first;
- `--sort date` orders newest publication dates first. Sorting is client-side,
- after deduplication, and only covers retrieved results (`--max-results` is per
- source); it does not change source queries or search the full source collection
- for its most-cited/newest papers. Ties retain their original order. Missing or
- invalid values sort last; numeric citation strings are supported. Dates accept
- ISO dates/timestamps, with naive timestamps and date-only values treated as UTC.
- The default JSON output and selected sources are unchanged.
- #### MCP tools from the CLI
- `paper-search tool` calls the same registered tools as the MCP server, including
- source-specific options and DOI lookup. Required arguments are positional;
- optional arguments use kebab-case flags. Boolean flags use `--flag` and
- `--no-flag`; omitted options retain their MCP defaults.
- ```bash
- paper-search tool --help
- paper-search tool --list # JSON tool list, schemas, and annotations
- paper-search tool search_crossref --help
- paper-search tool search_crossref "transformer attention" --filter from-pub-date:2024-01-01 --sort published --order desc --max-results 2
- paper-search tool get_crossref_paper_by_doi 10.1038/nature12373
- paper-search tool search_iacr "cryptography" --no-fetch-details
- ```
- Objects and lists return JSON; text and download paths return plain text. An
- exception returns a JSON error with exit code 1; invalid CLI syntax exits with
- code 2. A normal MCP result retains its original meaning, including error or
- partial-result fields returned by the tool itself. `--list` shows only tools
- enabled by the current configuration, so IEEE tools still require their API
- key. The existing `search`, `download`, `read`, and `sources` commands are
- unchanged. Tool calls keep the MCP tools' source selection and timeout behavior;
- Sci-Hub fallback remains opt-in through `--use-scihub`.
- #### Skill ZIP uploads and other Claude runtimes
- The steps above install a **local Claude Code skill** at `~/.claude/skills/paper-search/SKILL.md`, following the [Claude Code skill layout](https://code.claude.com/docs/en/skills). They do not require a ZIP upload.
- GitHub's **Download ZIP** contains the entire repository, with the skill nested under `paper-search-mcp-main/claude-code/`. It is not a standalone skill archive. If an uploader reports that `SKILL.md` is nested too deeply, check the archive layout first. Anthropic's [custom-skill packaging guide](https://support.claude.com/en/articles/12512198-how-to-create-custom-skills) specifies a single skill folder at the archive root, with the skill file directly inside it:
- ```text
- paper-search-skill.zip
- └── paper-search/
- └── SKILL.md
- ```
- To create that layout for inspection or adaptation, run this from a repository checkout (requires Python 3; overwrites `paper-search-skill.zip`):
- ```python
- from zipfile import ZIP_DEFLATED, ZipFile
- with ZipFile("paper-search-skill.zip", "w", compression=ZIP_DEFLATED) as archive:
- archive.write("claude-code/SKILL.md", arcname="paper-search/SKILL.md")
- ```
- A reusable builder is also available: `python scripts/build_skill_zip.py --output paper-search-skill.zip`. It refuses to overwrite an existing file unless `--force` is supplied. Its archive layout, frontmatter, and byte-for-byte instruction contents are covered by offline tests.
- This only packages the instructions; it does not bundle Python dependencies, install `paper-search`, or configure an MCP connection. The bundled skill expects a runtime that can execute the CLI and reach the academic services. Upload acceptance and execution in Claude web or another runtime have **not been validated by this project**. Check that runtime's current metadata, package-installation, network-access, and code-execution requirements before adapting the skill. If you want to use an MCP client instead, follow the MCP installation methods below; uploading a skill ZIP does not start or connect an external MCP server.
- ---
- > **MCP Server Config file locations** (for methods below)
- > - **macOS**: `~/Library/Application Support/Claude/claude_desktop_config.json`
- > - **Windows**: `%APPDATA%\Claude\claude_desktop_config.json`
- > - **Linux**: `~/.config/Claude/claude_desktop_config.json`
- ---
- ### Method 1 — Smithery (one-command, recommended for Claude Desktop)
- ```bash
- npx -y @smithery/cli install @openags/paper-search-mcp --client claude
- ```
- Smithery automatically writes the correct config block for you. No manual JSON editing needed.
- ---
- ### Method 2 — `uvx` (no install, always latest)
- `uvx` runs the package directly from PyPI without a permanent install. Requires [uv](https://docs.astral.sh/uv/getting-started/installation/).
- ```bash
- # Install uv (skip if already installed)
- curl -LsSf https://astral.sh/uv/install.sh | sh
- ```
- > ⚠️ **macOS note**: `uvx` generated wrapper scripts rely on `realpath`, which is not included in macOS by default. If you see a `realpath: command not found` error, either install GNU coreutils (`brew install coreutils`) or use **Method 3 (`uv run`)** instead — it does not have this limitation.
- **Claude Desktop config:**
- ```json
- {
- "mcpServers": {
- "paper-search-mcp": {
- "command": "uvx",
- "args": ["paper-search-mcp"],
- "env": {
- "PAPER_SEARCH_MCP_UNPAYWALL_EMAIL": "your@email.com",
- "PAPER_SEARCH_MCP_CORE_API_KEY": "",
- "PAPER_SEARCH_MCP_SEMANTIC_SCHOLAR_API_KEY": "",
- "PAPER_SEARCH_MCP_ZENODO_ACCESS_TOKEN": "",
- "PAPER_SEARCH_MCP_GOOGLE_SCHOLAR_PROXY_URL": "",
- "PAPER_SEARCH_MCP_IEEE_API_KEY": ""
- }
- }
- }
- }
- ```
- ---
- ### Method 3 — `uv` (persistent install)
- ```bash
- uv tool install paper-search-mcp
- ```
- **Claude Desktop config:**
- ```json
- {
- "mcpServers": {
- "paper-search-mcp": {
- "command": "uv",
- "args": ["tool", "run", "paper-search-mcp"],
- "env": {
- "PAPER_SEARCH_MCP_UNPAYWALL_EMAIL": "your@email.com",
- "PAPER_SEARCH_MCP_CORE_API_KEY": "",
- "PAPER_SEARCH_MCP_SEMANTIC_SCHOLAR_API_KEY": "",
- "PAPER_SEARCH_MCP_ZENODO_ACCESS_TOKEN": "",
- "PAPER_SEARCH_MCP_GOOGLE_SCHOLAR_PROXY_URL": "",
- "PAPER_SEARCH_MCP_IEEE_API_KEY": ""
- }
- }
- }
- }
- ```
- ---
- ### Method 4 — `pip` (standard Python install)
- ```bash
- pip install paper-search-mcp
- ```
- **Claude Desktop config:**
- ```json
- {
- "mcpServers": {
- "paper-search-mcp": {
- "command": "python",
- "args": ["-m", "paper_search_mcp.server"],
- "env": {
- "PAPER_SEARCH_MCP_UNPAYWALL_EMAIL": "your@email.com",
- "PAPER_SEARCH_MCP_CORE_API_KEY": "",
- "PAPER_SEARCH_MCP_SEMANTIC_SCHOLAR_API_KEY": "",
- "PAPER_SEARCH_MCP_ZENODO_ACCESS_TOKEN": "",
- "PAPER_SEARCH_MCP_GOOGLE_SCHOLAR_PROXY_URL": "",
- "PAPER_SEARCH_MCP_IEEE_API_KEY": ""
- }
- }
- }
- }
- ```
- > If `python` is not on your PATH, replace it with the full path (e.g. `/usr/bin/python3` or `C:\Python311\python.exe`). Run `which python3` / `where python` to find it.
- ---
- ### Method 5 — `npx` (via Smithery CLI, no local Python needed)
- ```bash
- npx -y @smithery/cli run @openags/paper-search-mcp
- ```
- **Claude Desktop config:**
- ```json
- {
- "mcpServers": {
- "paper-search-mcp": {
- "command": "npx",
- "args": ["-y", "@smithery/cli", "run", "@openags/paper-search-mcp"],
- "env": {
- "PAPER_SEARCH_MCP_UNPAYWALL_EMAIL": "your@email.com",
- "PAPER_SEARCH_MCP_CORE_API_KEY": "",
- "PAPER_SEARCH_MCP_SEMANTIC_SCHOLAR_API_KEY": ""
- }
- }
- }
- }
- ```
- ---
- ### Method 6 — Docker
- ```bash
- docker build -t paper-search-mcp .
- docker run --rm -i \
- -e PAPER_SEARCH_MCP_UNPAYWALL_EMAIL=your@email.com \
- -e PAPER_SEARCH_MCP_CORE_API_KEY=your_core_key \
- paper-search-mcp
- ```
- **Claude Desktop config:**
- ```json
- {
- "mcpServers": {
- "paper-search-mcp": {
- "command": "docker",
- "args": ["run", "--rm", "-i", "paper-search-mcp"],
- "env": {
- "PAPER_SEARCH_MCP_UNPAYWALL_EMAIL": "your@email.com",
- "PAPER_SEARCH_MCP_CORE_API_KEY": "",
- "PAPER_SEARCH_MCP_SEMANTIC_SCHOLAR_API_KEY": "",
- "PAPER_SEARCH_MCP_ZENODO_ACCESS_TOKEN": "",
- "PAPER_SEARCH_MCP_GOOGLE_SCHOLAR_PROXY_URL": "",
- "PAPER_SEARCH_MCP_IEEE_API_KEY": ""
- }
- }
- }
- }
- ```
- ---
- ### Method 7 — Clone & run from source (development / recommended for macOS local)
- This is the most reliable method on macOS — no wrapper scripts, no `realpath` issues.
- ```bash
- # 1. Install uv (skip if already installed)
- curl -LsSf https://astral.sh/uv/install.sh | sh
- # 2. Clone repo
- git clone https://github.com/openags/paper-search-mcp.git
- cd paper-search-mcp
- # 3. Verify it runs (uv auto-resolves dependencies, no manual install needed)
- uv run -m paper_search_mcp.server
- ```
- **Claude Desktop config** (replace the directory path with your actual clone location):
- ```json
- {
- "mcpServers": {
- "paper-search-mcp": {
- "command": "uv",
- "args": [
- "run",
- "--directory", "/path/to/paper-search-mcp",
- "-m", "paper_search_mcp.server"
- ],
- "env": {
- "PAPER_SEARCH_MCP_UNPAYWALL_EMAIL": "your@email.com",
- "PAPER_SEARCH_MCP_CORE_API_KEY": "",
- "PAPER_SEARCH_MCP_SEMANTIC_SCHOLAR_API_KEY": "",
- "PAPER_SEARCH_MCP_ZENODO_ACCESS_TOKEN": "",
- "PAPER_SEARCH_MCP_GOOGLE_SCHOLAR_PROXY_URL": "",
- "PAPER_SEARCH_MCP_IEEE_API_KEY": ""
- }
- }
- }
- }
- ```
- For example, if you cloned to `/Users/mac/Pengsong/paper-search-mcp`:
- ```json
- "args": ["run", "--directory", "/Users/mac/Pengsong/paper-search-mcp", "-m", "paper_search_mcp.server"]
- ```
- > `uv run` automatically installs dependencies into an isolated environment on first run — no `pip install` or `venv` needed.
- To run one shared network server instead of one stdio process per client:
- ```bash
- paper-search-mcp --transport streamable-http --host 127.0.0.1 --port 8000 --path /mcp
- ```
- The available transports are `stdio`, `sse`, and `streamable-http`. The default
- remains `stdio`. The same network settings can be supplied with
- `PAPER_SEARCH_MCP_TRANSPORT`, `PAPER_SEARCH_MCP_HOST`,
- `PAPER_SEARCH_MCP_PORT`, and `PAPER_SEARCH_MCP_PATH`; command-line options take
- precedence. With the default `--auth none`, binding to a non-loopback host such
- as `0.0.0.0` exposes an unauthenticated server. For protected HTTP, configure
- [optional OAuth mode](docs/OAUTH_PROTECTED_RESOURCE.md) and keep the backend behind
- TLS and appropriate deployment controls; otherwise use an authenticated gateway.
- For active development, optionally install an editable copy:
- ```bash
- uv venv && source .venv/bin/activate # Windows: .venv\Scripts\activate
- uv pip install -e ".[dev]"
- ```
- ---
- ### DeepSeek Harness (DSH)
- Paper search is available inside [DeepSeek Harness](https://github.com/deepseek-ai/deepseek-harness) (`dsh`) as a profile bundle: it boots the MCP server and registers all its tools in any dsh profile as `mcp__paper-search__*`. The bundle only mounts a composition row — the MCP server itself is untouched.
- **Prerequisites**: [uv](https://docs.astral.sh/uv/getting-started/installation/) (the default launcher is `uvx`) and [pnpm](https://pnpm.io/installation) (`dsh plugin` forwards to pnpm). Commands below use the `npx @deepseek-ai/dsh` launcher (no global install needed); with a global dsh install, drop the prefix.
- ```bash
- git clone https://github.com/openags/paper-search-mcp.git
- cd paper-search-mcp
- npx @deepseek-ai/dsh@0.2.0-rc.2 plugin --profile web add link:./dsh
- ```
- `link:` updates the bundle configuration from the checkout. `git pull` does not update the separately launched PyPI server; see `dsh/README.md` for a source-checkout launcher and reproducible version selection. Replace `web` with your profile name; a missing profile is initialized automatically. Restart the profile (`npx @deepseek-ai/dsh@0.2.0-rc.2 web`, or relaunch) and the tools appear — e.g. `mcp__paper-search__search_papers`, `mcp__paper-search__download_with_fallback`, `mcp__paper-search__search_arxiv`.
- **API keys**: just follow [Environment Variables](#environment-variables-env-file) — the server auto-loads `~/.config/paper-search-mcp/.env`. DSH deliberately scrubs credential-shaped ambient env vars from spawned processes, so shell exports do not reach the server; to forward variables explicitly, override the `mcp-paper-search` row in `~/.dsh/profiles/<name>/cordis.patch.yml` (a config override replaces the whole object — see `dsh/README.md` for a complete example).
- **Optional skill** with usage guidance (workflow, source table, tool mapping):
- ```bash
- mkdir -p ~/.dsh/skills && cp -r dsh/skills/paper-search ~/.dsh/skills/
- ```
- **Uninstall**:
- ```bash
- npx @deepseek-ai/dsh@0.2.0-rc.2 plugin --profile web remove paper-search-mcp-dsh
- rm -rf ~/.dsh/skills/paper-search
- ```
- Removing the bundle reconciles its row out of the composition. It does not delete downloaded papers, package caches, or user-managed settings.
- If you already run paper-search-mcp through your own `@deepseek-ai/dsh-mcp-client` row, remove that row (or give one of the two a distinct `serverName`) before adding the bundle — duplicate `serverName`s fail at load. The bundle package version tracks this checkout's Python project version; `dsh/README.md` documents alternate launchers (`uv tool run`, `python -m`, `npx`), environment forwarding, and development.
- ---
- ### Environment Variables (`.env` file)
- Instead of putting keys directly in the JSON config you can store them in the user config file (auto-loaded on startup):
- ```bash
- mkdir -p ~/.config/paper-search-mcp
- curl -fsSL https://raw.githubusercontent.com/openags/paper-search-mcp/main/.env.example \
- -o ~/.config/paper-search-mcp/.env
- $EDITOR ~/.config/paper-search-mcp/.env
- ```
- ```dotenv
- PAPER_SEARCH_MCP_UNPAYWALL_EMAIL=your@email.com
- PAPER_SEARCH_MCP_CORE_API_KEY=
- PAPER_SEARCH_MCP_SEMANTIC_SCHOLAR_API_KEY=
- PAPER_SEARCH_MCP_ZENODO_ACCESS_TOKEN=
- PAPER_SEARCH_MCP_GOOGLE_SCHOLAR_PROXY_URL=
- PAPER_SEARCH_MCP_IEEE_API_KEY=
- ```
- To use a custom path: `export PAPER_SEARCH_MCP_ENV_FILE=/absolute/path/to/.env`
- > Legacy variable names without the `PAPER_SEARCH_MCP_` prefix (e.g. `CORE_API_KEY`, `UNPAYWALL_EMAIL`) are still supported for backward compatibility.
- ---
- ### Optional local search cache
- [Opt-in SQLite search caching](docs/SEARCH_CACHE.md) adds TTL, size limits,
- status, and clearing. It is disabled by default and bypasses authenticated sources.
- ## Contributing
- We welcome contributions! Here's how to get started:
- 1. **Fork the Repository**:
- Click "Fork" on GitHub.
- 2. **Clone and Set Up**:
- ```bash
- git clone https://github.com/yourusername/paper-search-mcp.git
- cd paper-search-mcp
- uv venv && source .venv/bin/activate
- uv pip install -e ".[dev]"
- ```
- 3. **Make Changes**:
- - Add new platforms in `academic_platforms/`.
- - Update tests in `tests/`.
- 4. **Submit a Pull Request**:
- Push changes and create a PR on GitHub.
- ---
- ## Demo
- <img src="docs\images\demo.png" alt="Demo" width="800">
- ## TODO
- ### Planned Academic Platforms
- - [√] arXiv
- - [√] PubMed
- - [√] bioRxiv
- - [√] medRxiv
- - [√] Google Scholar
- - [√] IACR ePrint Archive
- - [√] Semantic Scholar
- - [√] Crossref
- - [√] PubMed Central (PMC)
- - [√] CORE
- - [√] Europe PMC
- - [√] Sci-Hub warning and enablement docs
- ### Development Tasks
- - [√] Fix Async search bugs and ensure reliable fast MCP events
- - [√] End-to-End full pipeline testing script (search, parse, download)
- - [√] Establish two-layer federated architecture (Layer 1 tool: `search_papers`)
- - [√] Ensure pervasive DOI extraction across metadata fields & abstract fallbacks
- - [ ] Citation graph & Paper relation context feature
- - [√] Expand full-stack OpenAlex provider
- ### Priority Free and Open Sources
- - [√] PubMed Central (PMC)
- - [√] CORE
- - [√] OpenAlex
- - [√] Europe PMC
- - [√] OpenAIRE
- - [√] dblp
- - [√] CiteSeerX
- - [√] DOAJ
- - [√] BASE
- - [√] Zenodo
- - [√] HAL
- - [√] SSRN (discovery + best-effort full-text)
- - [√] Unpaywall (standalone DOI search source)
- ### Optional and Non-Core Integrations
- - [ ] ResearchGate
- - [ ] JSTOR
- - [ ] ScienceDirect
- - [ ] Springer Link
- - [√] IEEE Xplore (optional skeleton — activate with `IEEE_API_KEY`)
- - [√] ACM Digital Library (keyless Crossref search; publisher PDF access varies)
- - [ ] Web of Science
- - [ ] Scopus
- ---
- ## Star History
- [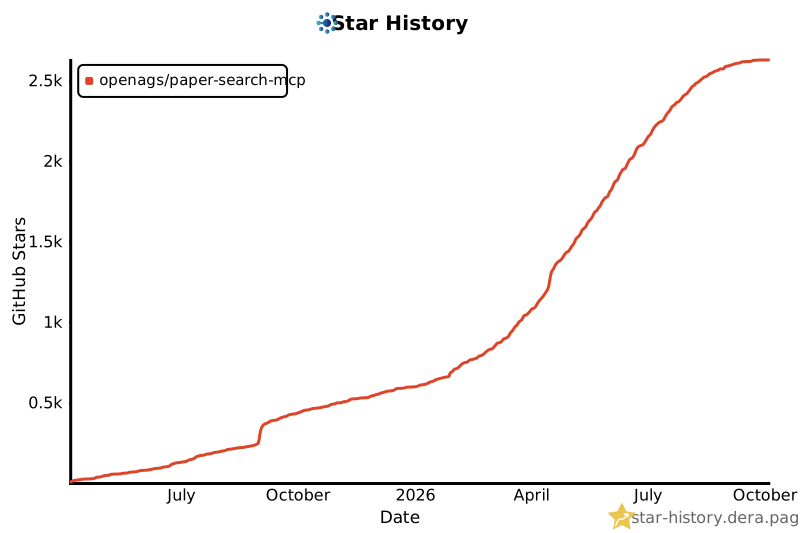](https://star-history.dera.page/#openags/paper-search-mcp&Date)
- ---
- ## License
- This project is licensed under the MIT License. See the LICENSE file for details.
- ---
- Happy researching with `paper-search-mcp`! If you encounter issues, open a GitHub issue.
- ### Explicit institutional metadata connectors
- Web of Science Starter is available only through `search_wos` or an explicit
- `wos` source (`paper-search search 'TI=(machine learning)' -s wos`). Supplying a
- key does **not** add it to default, `all`, `fast`, or `fastest` searches. Supply
- `PAPER_SEARCH_MCP_WOS_API_KEY` (legacy `WOS_API_KEY` also works) at runtime; the
- connector does not create accounts or persist credentials. See
- [the institutional connector guide](docs/INSTITUTIONAL_CONNECTORS.md) for limits,
- errors, capability boundaries, and validation status.
- Scopus is likewise explicit-only (`-s scopus` or MCP `search_scopus`), using
- `PAPER_SEARCH_MCP_SCOPUS_API_KEY` (legacy `SCOPUS_API_KEY`). Metadata search defaults
- to `STANDARD`. Abstract retrieval is available via `paper-search read scopus ID`
- or MCP `read_scopus_paper`; ScienceDirect article retrieval requires explicit
- `--full-text` / `full_text=true` and a verified DOI/PII match. The response labels
- `full_text`, `abstract_only`, and `unavailable` separately. Neither connector's
- live institutional entitlement has been validated by these fixture tests.
Ratings and comments
Sign in to rate this skill.
Sign inFree to use. If it’s helped, pass it on.