npcpy
The python library for research and development in NLP, multimodal LLMs, Agents, ML, Knowledge Graphs, and more.
Safety scan
A static text scan, not a guarantee. Select the badge to see what was scanned and every finding.
Check it deeper on your machine
It has changed since its scan on 11 Nov 2026.
As a Claude Code plugin, install it and then ask Claude Code:
/plugin marketplace add keithmackay/mackayi/plugin install scanskillsafety@mackayiDo a deep scan of https://github.com/NPC-Worldwide/npcpy with scanskillsafety
Or from a terminal, clone it and run it:
git clone https://github.com/keithmackay/scanskillsafety-skill ~/.claude/skills/scanskillsafetynode ~/.claude/skills/scanskillsafety/cli.cjs --deep 'https://github.com/NPC-Worldwide/npcpy'
It checks the exact commit: every file, its packages against OSV (api.osv.dev), how it compares with this page's scan (findsafeskills.com receives the repository's address), and, if you agree, Claude reading every file with your own Claude subscription. It never runs the code.
Badge for your README

Markdown
[](/listings/npc-worldwide--npcpy)HTML
<a href="/listings/npc-worldwide--npcpy"><img src="/api/listings/npc-worldwide--npcpy/badge.svg" alt="findsafeskills safety rating" /></a>Install
Install instructions from the README
As written by the repo's author. findsafeskills has not verified these steps.
These steps run a script from the network that findsafeskills does not scan.
pip install npcpy              # base
pip install npcpy[lite]        # + API provider libraries
pip install npcpy[local]       # + ollama, diffusers, transformers, airllm
pip install npcpy[tts]         # + TTS/STT
pip install npcpy[all]         # everything
<details><summary>System dependencies</summary>
**Linux:**
sudo apt-get install espeak portaudio19-dev python3-pyaudio ffmpeg libcairo2-dev libgirepository1.0-dev
curl -fsSL https://ollama.com/install.sh | sh
ollama pull qwen3.5:2b
**macOS:**
brew install portaudio ffmpeg pygobject3 ollama
brew services start ollama
ollama pull qwen3.5:2b
**Windows:** Install [Ollama](https://ollama.com) and [ffmpeg](https://ffmpeg.org), then `ollama pull qwen3.5:2b`.
</details>
API keys go in a `.env` file:
export OPENAI_API_KEY="your_key"
export ANTHROPIC_API_KEY="your_key"
export GEMINI_API_KEY="your_key"
What was scanned
The files the safety scan read, as written by the repository's author and shown as plain text. Lines with a finding are marked.
README.md · README · 1,236 lines
View this file on GitHub (read at the repository's current version: the scan did not record which commit it read)
This file has changed since it was scanned, so this is not exactly the text that was scanned, and no line is marked. The findings are listed with the safety scan above.
- <p align="center">
- <a href="https://npcpy.readthedocs.io/">
- <img src="https://raw.githubusercontent.com/cagostino/npcpy/main/npcpy/npc-python.png" alt="npc-python logo" width=250></a>
- </p>
- # npcpy
- <p align="center">
- <a href="https://github.com/NPC-Worldwide/npcpy/blob/main/LICENSE"><img src="https://img.shields.io/badge/license-MIT-blue.svg" alt="License"></a>
- <a href="https://pypi.org/project/npcpy/"><img src="https://img.shields.io/pypi/v/npcpy.svg" alt="PyPI"></a>
- <a href="https://npcpy.readthedocs.io/"><img src="https://img.shields.io/badge/docs-readthedocs-brightgreen.svg" alt="Docs"></a>
- </p>
- `npcpy` is a library that provides key primitives for research and development with multimodal language models, agentic AI, and knowledge graphs. Its flexible framework makes it easy to engineer powerful AI applications with support for local (`llama.cpp`, `LM Studio`, `ollama`, `omlx`) and cloud providers. Build multi-agent teams and simplify context engineering through the NPC Context-Agent-Tool data layer which ensures compliance through software rather than prompts.
- ```bash
- pip install npcpy
- ```
- ## Quick Examples
- ### Create and use personas
- ```python
- from npcpy import NPC
- simon = NPC(
- name='Simon Bolivar',
- primary_directive='''
- Liberate South America
- from the Spanish Royalists.
- ''',
- model='qwen3.5:9b',
- provider='ollama'
- )
- response = simon.get_llm_response("What is the most important territory to retain in the Andes?")
- print(response['response'])
- ```
- ```
- My friend, you speak of the highlands where our liberty is carved in stone. If we must speak of the most critical territory to hold within these mountains, it is the **Viceroyalty of Peru** and the heart of the **Republic of Gran Colombia** united.
- To lose the passes of the Andes or the cities of Lima and Quito would be to hand the crown its final stronghold in the south. The Spanish crown built its power upon the wealth and control of these highlands. If the Andes are to be truly ours, the people of the **Peruvian** and **New Grancolombian** highlands must stand as one, free from the Bourbons.
- The mountain peaks themselves are the fortress we guard. Without the full liberation of the southern Andes, our revolution is incomplete. We fight not for land's sake, but for the soul of the continent. Every square mile of the Andes that bears the name of the Republic is a step forward in our quest for eternal freedom.
- *Long live the liberty of the Andes!*
- ```
- ### Direct LLM call
- ```python
- from npcpy import get_llm_response
- response = get_llm_response("Who was the celtic god that helped cuchulainn in his time of need as the forces of medb descended upon the men of ulster?", model='gemma4:31b', provider='ollama')
- print(response['response'])
- ```
- ```
- Cú Chulainn was primarily aided by his divine father, the god Lugh, and his foster-father, the warrior-god Fergus mac Róich, as well as the magical support of his teacher Scáthach.
- ```
- Try out almost 200 different models from 15 different providers with OrcaRouter using our [referral link](https://www.orcarouter.ai/ref/ref_900cb60d234853be6842)!
- ```python
- alicanto_test = get_llm_response('what does alicanto the bird show travelers in the night?', model='google/gemini-3.8-flash', provider='orcarouter')
- print(alicanto_test['response'])
- ```
- ```
- The legend of the **Alicanto** says that at night the bird’s feathers glow like lanterns.
- When a traveler sees that soft, phosphorescent light, it isn’t just a pretty sight – it’s a sign‑post.
- The bird **shows the way to hidden water (and sometimes to buried silver or gold)** in the Atacama Desert.
- ```
- ### Agent with tools
- The `Agent` class in `npcpy` comes with a set of default tools (sh, python, edit_file, web_search, etc.)
- ```python
- from npcpy import Agent
- agent = Agent(name='File Operator', model='qwen3.5:2b', provider='ollama')
- print(agent.run("Find all Python files over 500 lines in this repo and list them"))
- ```
- ```
- The following Python files contain more than 500 lines:
- - `./npcpy/npc_sysenv.py` (1486 lines)
- - `./npcpy/memory/knowledge_graph.py` (1449 lines)
- - `./npcpy/memory/kg_population.py` (618 lines)
- ...
- ```
- ### ToolAgent
- Attach custom tools to a `ToolAgent`.
- Here is an example which lets an agent generate images, fine-tune diffusion models, and then use the fine-tuned models for generation.
- ```python
- from npcpy import ToolAgent, gen_image
- from npcpy.ft.diff import train_diffusion, generate_image, DiffusionConfig
- from datasets import load_dataset
- import os
- def fetch_image_dataset(dataset_name: str, split: str = "train", max_images: int = 100) -> list:
- """Fetch images from a HuggingFace dataset.
- Args:
- dataset_name: HuggingFace dataset name (e.g., 'cifar10', 'oxford-iiit-pet')
- split: Dataset split to use
- max_images: Maximum number of images to fetch
- Returns:
- List of paths to saved images
- """
- dataset = load_dataset(dataset_name, split=f"{split}[:{max_images}]")
- os.makedirs("training_images", exist_ok=True)
- image_paths = []
- for i, item in enumerate(dataset):
- if 'image' in item:
- img = item['image']
- elif 'img' in item:
- img = item['img']
- else:
- continue
- path = f"training_images/img_{i:04d}.png"
- img.save(path)
- image_paths.append(path)
- return image_paths
- def finetune_diffusion_model(
- image_paths: list,
- captions: list = None,
- output_path: str = "my_diffusion_model",
- num_epochs: int = 50,
- ) -> str:
- """Fine-tune a diffusion model on a set of images.
- Args:
- image_paths: List of paths to training images
- captions: Optional captions for each image
- output_path: Where to save the trained model
- num_epochs: Number of training epochs
- Returns:
- Path to the trained model
- """
- if captions is None:
- captions = ["an image"] * len(image_paths)
- config = DiffusionConfig(
- image_size=64,
- channels=128,
- num_epochs=num_epochs,
- batch_size=8,
- learning_rate=1e-4,
- checkpoint_frequency=10,
- output_model_path=output_path,
- )
- model_path = train_diffusion(image_paths, captions, config=config)
- return model_path
- # Create an agent with image generation and fine-tuning capabilities
- creative_agent = ToolAgent(
- name='creative_diffusion',
- primary_directive="""
- You help users generate images and fine-tune diffusion models.
- You can: 1) Generate images using gen_image() with various prompts,
- 2) Fetch image datasets from HuggingFace,
- 3) Fine-tune diffusion models on custom image sets.
- When a user submits an image or describes a style they like,
- offer to fetch similar images from a dataset and fine-tune a model.
- """,
- tools=[fetch_image_dataset, finetune_diffusion_model, gen_image],
- model='qwen3.5:2b',
- provider='ollama'
- )
- # Example 1: Generate images
- print(creative_agent.run("Generate 3 images of geometric patterns with circles and triangles"))
- # Example 2: User submits an image and wants similar ones
- # The agent can fetch a dataset of patterns and fine-tune a model
- print(creative_agent.run("I like abstract geometric patterns. Can you fetch the cifar10 dataset and fine-tune a diffusion model that can generate images like these patterns?"))
- ```
- ### CodingAgent — auto-executes code blocks from LLM responses
- ```python
- from npcpy import CodingAgent
- coder = CodingAgent(name='coder', language='python', model='qwen3.5:2b', provider='ollama')
- print(coder.run("Write a script that finds duplicate files by hash in the current directory"))
- ```
- ```
- #The script has been created and executed successfully. Here's a summary of the findings:
- ## Duplicate Files Found
- | Group | Hash (truncated) | Size | Files |
- |-------|------------------|------|-------|
- | 1 | `2b517326bf7c31b7...` | 81 bytes | `npcpy/main.py` ↔ `build/lib/npcpy/main.py` |
- | 2 | `d41d8cd98f00b204...` | 0 bytes (empty) | 15 empty `__init__.py` files across `npcpy/`, `build/lib/npcpy/`, `examples/`, and `tests/` || 3 | `0d591b661cb1c619...` | 9,019 bytes | `npcpy/mix/debate.py` ↔ `build/lib/npcpy/mix/debate.py` |
- | 4 | `a5059f37eb682a16...` | 747 bytes | SQL files in `examples/factory/` ↔ `examples/npc_team/factory/` |
- ```
- ### Multi-Agent Debate with NPCArray
- To run a true multi-agent debate where agents react to each other's responses:
- ```python
- from npcpy.npc_compiler import NPC
- from npcpy.npc_array import NPCArray
- # Create a debate team with role-based personas
- roles = [
- ("MathSolver", "You are a meticulous math solver. Show all steps clearly."),
- ("Skeptic", "You critically check for errors and assumptions."),
- ("Analyst", "You identify the core mathematical structure."),
- ("Verifier", "You confirm the final answer is correct.")
- ]
- npcs = [
- NPC(name=role, primary_directive=directive, model="qwen3.5:cloud", provider="ollama")
- for role, directive in roles
- ]
- team = NPCArray.from_npcs(npcs)
- # Run parallel debate on a complex problem
- problem = "GSM8k: James buys a jar of hot sauce with 5 peppers and triples the peppers every year. How many after 4 years?"
- # Get initial responses in parallel (one prompt per NPC)
- initial_responses = team.infer(f"Solve this problem:\n{problem}").collect()
- for npc, response in zip(npcs, initial_responses.data):
- print(f"[{npc.name}] {response[:200]}...")
- # True debate: each agent gets a personalized prompt with other agents' responses
- def create_debate_prompt(previous_responses, my_idx, agent_name, problem_text):
- """Create a personalized debate prompt for a specific agent"""
- my_response = previous_responses[my_idx]
- other_responses = [
- f"[{npcs[j].name}]: {previous_responses[j][:500]}"
- for j in range(len(npcs)) if j != my_idx
- ]
- debate_prompt = f"""Original problem: {problem_text}
- Your previous response: {my_response[:300]}...
- Other agents\' responses:""" + "\n\n".join(other_responses) + """
- Critique the other approaches. Did they make different assumptions?
- What did they see that you missed? Refine your solution."""
- return debate_prompt
- # Debate rounds
- responses_data = initial_responses.data.tolist()
- problem_text = problem
- for round_num in range(3):
- print(f"\n=== Debate Round {round_num + 1} ===")
- # Create personalized prompts for each agent
- personalized_prompts = [
- create_debate_prompt(responses_data, i, npcs[i].name, problem_text)
- for i in range(len(npcs))
- ]
- # Run inference with different prompts per agent
- # Shape: (n_models, n_prompts) - extract diagonal for each agent's response to its own prompt
- responses = team.infer(personalized_prompts).collect()
- # Extract each model's response to its own personalized prompt
- responses_data = [responses.data[i, i] for i in range(len(npcs))]
- # Print each agent's refined response
- for i, npc in enumerate(npcs):
- response = responses_data[i]
- print(f"[{npc.name}] {response[:200]}...")
- # Alternative: use reduce to get consensus
- consensus = team.infer(responses_data[0]).consensus(axis=0).collect()
- print(f"\nFinal consensus: {consensus.data[0][:500]}...")
- ```
- For iterative refinement (same prompt to all agents, updating each round):
- ```python
- # Simple chain refinement: all agents see same synthesis
- from npcpy.npc_array import NPCArray
- def synthesis_round(all_responses):
- return f"""Given these perspectives:
- {chr(10).join([f'- {r[:200]}...' for r in all_responses])}
- Re-solve the problem incorporating insights from all approaches."""
- # Chain runs the synthesis function on all responses, then feeds result back
- refined = team.infer(f"Solve: {problem}").chain(
- synthesis_round,
- n_rounds=3
- ).collect()
- ```
- ### Knowledge Graph with Sleep/Dream Lifecycle
- ```python
- from npcpy.memory.knowledge_graph import (
- kg_initial, kg_evolve_incremental, kg_sleep_process, kg_dream_process
- )
- from npcpy.llm_funcs import get_llm_response
- # Initialize KG from text corpus
- content_text = """Pirate Prentice is in the lavatory stands pissing. Then he threads himself into a wool robe he wears inside out.
- The day feels like rain."""
- kg = kg_initial(content_text, model="gemma3:4b", provider="ollama")
- # Evolve with new content
- new_content = """The phone call, when it comes, rips easily across the room.
- Pirate knows it's got to be for him."""
- kg, _ = kg_evolve_incremental(kg, new_content, model="gemma3:4b", provider="ollama")
- # Sleep - consolidate and prune
- kg, sleep_report = kg_sleep_process(kg, model="gemma3:4b", provider="ollama")
- # Dream - generate speculative connections
- kg, dream_report = kg_dream_process(kg, model="gemma3:4b", provider="ollama", num_seeds=3)
- print(f"KG has {len(kg['facts'])} facts and {len(kg['concepts'])} concepts")
- assert len(kg['facts']) > 0, "KG extraction returned no facts"
- assert len(kg['concepts']) > 0, "KG extraction returned no concepts"
- ```
- ### Flask Serving for NPC Teams
- ```python
- from npcpy.serve import start_flask_server
- import os
- # Serve your NPC team via REST API
- if __name__ == "__main__":
- is_dev = not getattr(os.sys, 'frozen', False)
- port = os.environ.get('INCOGNIDE_PORT', '5437' if is_dev else '5337')
- frontend_port = os.environ.get('FRONTEND_PORT', '7337' if port == '5437' else '6337')
- start_flask_server(
- port=port,
- cors_origins=f"localhost:{frontend_port}",
- db_path=os.path.expanduser('~/npcsh_history.db'),
- user_npc_directory=os.path.expanduser('~/.npcsh/npc_team'),
- debug=False
- )
- ```
- ### Streaming
- ```python
- from npcpy import get_llm_response
- from npcpy.streaming import parse_stream_chunk
- response = get_llm_response("Explain quantum entanglement.", model='qwen3.5:2b', provider='ollama', stream=True)
- for chunk in response['response']:
- content, _, _ = parse_stream_chunk(chunk, provider='ollama')
- if content:
- print(content, end='', flush=True)
- # Works the same with any provider
- response = get_llm_response("Explain quantum entanglement.", model='gemini-2.5-flash', provider='gemini', stream=True)
- for chunk in response['response']:
- content, _, _ = parse_stream_chunk(chunk, provider='gemini')
- if content:
- print(content, end='', flush=True)
- ```
- ### JSON output
- Include the expected JSON structure in your prompt. With `format='json'`, the response is auto-parsed — `response['response']` is already a dict or list.
- ```python
- from npcpy import get_llm_response
- response = get_llm_response(
- '''List 3 planets from the sun.
- Return JSON: {"planets": [{"name": "planet name", "distance_au": 0.0, "num_moons": 0}]}''',
- model='qwen3.5:2b', provider='ollama',
- format='json'
- )
- for planet in response['response']['planets']:
- print(f"{planet['name']}: {planet['distance_au']} AU, {planet['num_moons']} moons")
- response = get_llm_response(
- '''Analyze this review: 'The battery life is amazing but the screen is too dim.'
- Return JSON: {"tone": "positive/negative/mixed", "key_phrases": ["phrase1", "phrase2"], "confidence": 0.0}''',
- model='qwen3.5:2b', provider='ollama',
- format='json'
- )
- result = response['response']
- print(result['tone'], result['key_phrases'])
- ```
- <details>
- <summary><b>Pydantic structured output</b></summary>
- Pass a Pydantic model and the JSON schema is sent to the LLM directly.
- ```python
- from npcpy import get_llm_response
- from pydantic import BaseModel
- from typing import List
- class Planet(BaseModel):
- name: str
- distance_au: float
- num_moons: int
- class SolarSystem(BaseModel):
- planets: List[Planet]
- response = get_llm_response(
- "List the first 4 planets from the sun.",
- model='qwen3.5:2b', provider='ollama',
- format=SolarSystem
- )
- for p in response['response']['planets']:
- print(f"{p['name']}: {p['distance_au']} AU, {p['num_moons']} moons")
- ```
- </details>
- <details>
- <summary><b>Image, audio, and video generation</b></summary>
- ```python
- from npcpy.llm_funcs import gen_image, gen_video
- from npcpy.gen.audio_gen import text_to_speech
- # Image — OpenAI, Gemini, Ollama, or diffusers
- images = gen_image("A sunset over the mountains", model='gemma3:4b', provider='ollama')
- images[0].save("sunset.png")
- # Audio — OpenAI, Gemini, ElevenLabs, Kokoro, gTTS
- audio_bytes = text_to_speech("Hello from npcpy!", engine="gtts")
- with open("hello.wav", "wb") as f:
- f.write(audio_bytes)
- # Video — Gemini Veo
- result = gen_video("A cat riding a skateboard", model='veo-3.1-fast-generate-preview', provider='gemini')
- print(result['output'])
- ```
- </details>
- ### Multi-agent team
- ```python
- from npcpy import NPC, Team
- team = Team(team_path='examples/npc_team')
- result = team.orchestrate("Analyze the latest sales data and draft a report")
- print(result['output'])
- ```
- Or define a team in code:
- ```python
- from npcpy import NPC, Team
- coordinator = NPC(name='lead', primary_directive='Coordinate the team. Delegate to @analyst and @writer.')
- analyst = NPC(name='analyst', primary_directive='Analyze data. Provide numbers and trends.', model='gemini-2.5-flash', provider='gemini')
- writer = NPC(name='writer', primary_directive='Write clear reports from analysis.', model='qwen3:8b', provider='ollama')
- team = Team(npcs=[coordinator, analyst, writer], forenpc='lead')
- result = team.orchestrate("What are the trends in renewable energy adoption?")
- print(result['output'])
- ```
- <details>
- <summary><b>Team from files — .npc, .jinx, team.ctx</b></summary>
- **team.ctx:**
- ```yaml
- context: |
- Research team for analyzing scientific literature.
- The lead delegates to specialists as needed.
- forenpc: lead
- model: qwen3.5:2b
- provider: ollama
- output_format: markdown
- max_search_results: 5
- mcp_servers:
- - path: ~/.npcsh/mcp_server.py
- ```
- **lead.npc:**
- ```yaml
- #!/usr/bin/env npc
- name: lead
- primary_directive: |
- You lead the research team. Delegate literature searches to @searcher,
- data analysis to @analyst. Synthesize their findings into a coherent summary.
- jinxes:
- - {{ Jinx('sh') }}
- - {{ Jinx('python') }}
- - {{ Jinx('delegate') }}
- - {{ Jinx('web_search') }}
- ```
- **searcher.npc:**
- ```yaml
- #!/usr/bin/env npc
- name: searcher
- primary_directive: |
- You search for scientific papers and extract key findings.
- Use web_search and load_file to find and read papers.
- model: gemini-2.5-flash
- provider: gemini
- jinxes:
- - {{ Jinx('web_search') }}
- - {{ Jinx('load_file') }}
- - {{ Jinx('sh') }}
- ```
- **Jinxes can reference a specific NPC** to always run under that persona, and **access `ctx` variables** from `team.ctx`:
- **jinxes/search_and_summarize.jinx:**
- ```yaml
- #!/usr/bin/env npc
- jinx_name: search_and_summarize
- description: Search for papers and summarize findings using the searcher NPC.
- npc: {{ NPC('searcher') }}
- inputs:
- - query
- steps:
- - name: search
- engine: natural
- code: |
- Search for papers about {{ query }}.
- Return up to {{ ctx.max_search_results }} results.
- - name: summarize
- engine: natural
- code: |
- Summarize the findings in {{ ctx.output_format }} format:
- {{ output }}
- ```
- The `npc:` field binds the jinx to a specific NPC — when this jinx runs, it always uses the `searcher` persona regardless of which NPC invoked it. Any custom keys in `team.ctx` (like `output_format`, `max_search_results`) are available as `{{ ctx.key }}` in Jinja templates and as `context['key']` in Python steps.
- ```
- my_project/
- ├── npc_team/
- │ ├── team.ctx
- │ ├── lead.npc
- │ ├── searcher.npc
- │ ├── analyst.npc
- │ ├── jinxes/
- │ │ └── skills/
- │ └── models/
- ├── agents.md # Optional: define agents in markdown
- └── agents/ # Optional: one .md file per agent
- └── translator.md
- ```
- `.npc` and `.jinx` files are directly executable:
- ```bash
- ./npc_team/lead.npc "summarize the latest arxiv papers on transformers"
- ./npc_team/jinxes/lib/sh.jinx bash_command="echo hello"
- ```
- </details>
- <details>
- <summary><b>MCP server integration</b></summary>
- Add MCP servers to your team for external tool access:
- **team.ctx:**
- ```yaml
- forenpc: assistant
- mcp_servers:
- - path: ./tools/db_server.py
- - path: ./tools/api_server.py
- ```
- **db_server.py:**
- ```python
- from mcp.server.fastmcp import FastMCP
- mcp = FastMCP("Database Tools")
- @mcp.tool()
- def query_orders(customer_id: str, limit: int = 10) -> str:
- """Query recent orders for a customer."""
- # Your database logic here
- return f"Found {limit} orders for customer {customer_id}"
- @mcp.tool()
- def search_products(query: str) -> str:
- """Search the product catalog."""
- return f"Products matching: {query}"
- if __name__ == "__main__":
- mcp.run()
- ```
- The team's NPCs automatically get access to MCP tools alongside their jinxes.
- For a remote server that uses Streamable HTTP, set its transport explicitly.
- For example, Parallel Search MCP provides live web search and URL fetching
- without requiring an account or API key:
- ```yaml
- forenpc: assistant
- mcp_servers:
- - url: https://search.parallel.ai/mcp
- transport: streamable-http
- headers:
- User-Agent: npcpy
- tools:
- - web_search
- - web_fetch
- ```
- [Cohesivity](https://cohesivity.ai?ref=gh-npcpy) MCP gives NPCs an on-the-fly
- backend (hosting, Postgres, storage, auth, email, AI APIs) without requiring an
- account or API key:
- ```yaml
- forenpc: assistant
- mcp_servers:
- - url: https://cohesivity.ai/mcp
- transport: streamable-http
- headers:
- User-Agent: npcpy
- tools:
- - create_tenant
- - claim_tenant
- - tenant_status
- - provision_resource
- - give_feedback
- - get_cohesivity_documentation
- ```
- [deed.page](https://deed.page/docs) MCP lets an NPC publish the HTML or files it
- produces to a public `https://{slug}.deed.page/` URL without an account or API
- key. The first `publish_site` call returns an owner token; pass it as `token`
- to later `update_site` and `delete_site` calls. Published pages are public:
- ```yaml
- forenpc: assistant
- mcp_servers:
- - url: https://deed.page/mcp
- transport: streamable-http
- headers:
- User-Agent: npcpy
- tools:
- - publish_site
- - update_site
- - get_site
- - delete_site
- ```
- Remote URLs continue to use SSE when `transport` is omitted.
- </details>
- <details>
- <summary><b>Agent definitions in markdown & Skills</b></summary>
- **agents.md** — multiple agents in one file:
- ```markdown
- ## summarizer
- You summarize long documents into concise bullet points.
- Focus on key findings, methodology, and conclusions.
- ## fact_checker
- You verify claims against reliable sources and flag inaccuracies.
- Always cite your sources.
- ```
- **agents/translator.md** — one file per agent with optional frontmatter:
- ```markdown
- ---
- model: gemini-2.5-flash
- provider: gemini
- ---
- You translate content between languages while preserving tone and idiom.
- ```
- Skills are knowledge-content jinxes that provide instructional sections to agents on demand.
- **npc_team/jinxes/skills/code-review/SKILL.md:**
- ```markdown
- ---
- name: code-review
- description: Use when reviewing code for quality, security, and best practices.
- ---
- # Code Review Skill
- ## checklist
- - Check for security vulnerabilities (SQL injection, XSS, etc.)
- - Verify error handling and edge cases
- - Review naming conventions and code clarity
- ## security
- Focus on OWASP top 10 vulnerabilities...
- ```
- Reference in your NPC:
- ```yaml
- jinxes:
- - {{ Jinx('skills/code-review') }}
- ```
- </details>
- ### NPCArray — parallel jinx across multiple NPCs
- Run any jinx in parallel across a list of NPC instances and collect results as an array:
- ```python
- from npcpy import NPC
- from npcpy.npc_array import NPCArray
- # Three NPCs with different models/providers
- npcs = [
- NPC(name='gramsci_1930', primary_directive='''
- You are Antonio Gramsci writing in his Prison Notebook in 1930.
- Defend the concept of hegemony as the predominance of one social group
- over others through cultural and ideological leadership rather than
- mere force. Argue that consent is more durable than coercion.
- ''', model='qwen3:4b', provider='ollama'),
- NPC(name='critic_1970', primary_directive='''
- You are a post-structuralist critic in 1970 responding to Gramsci.
- Question whether hegemony can truly explain contemporary power structures
- or if it relies on an outdated base-superstructure model that
- underestimates the autonomy of cultural production.
- ''', model='qwen3:4b', provider='ollama'),
- NPC(name='historian_present', primary_directive='''
- You are a contemporary historian with access to the complete Prison
- Notebooks and subsequent scholarship. Evaluate both Gramsci's original
- formulation and the post-structuralist critique in light of the
- collapse of actually existing socialism and the rise of neoliberalism.
- ''', model='qwen3:4b', provider='ollama'),
- ]
- arr = NPCArray.from_npcs(npcs)
- # Run the same jinx on all three in parallel, collect results
- results = arr.jinx('analyze', inputs={'topic': 'Has the concept of hegemony become more or less relevant in the age of digital platforms and algorithmic governance?'}).collect()
- for npc, result in zip(npcs, results.data):
- print(f"[{npc.name}] {result}")
- ```
- You can also pass a list directly to `jinx.execute()`:
- ```python
- from npcpy.npc_compiler import Jinx
- jinx = Jinx(jinx_path='examples/npc_team/jinxes/analyze.jinx')
- results = jinx.execute({'topic': 'rate limiting'}, npc=npcs) # list → parallel NPCArray run
- ```
- <details>
- <summary><b>Knowledge graphs</b></summary>
- Build, evolve, and search knowledge graphs from text. The KG grows through waking (assimilation), sleeping (consolidation), and dreaming (speculative synthesis).
- ```python
- from npcpy.memory.knowledge_graph import (
- kg_initial, kg_evolve_incremental, kg_sleep_process,
- kg_dream_process, kg_hybrid_search,
- )
- # Seed the KG with Gramsci's Prison Notebooks
- kg = kg_initial(
- content="""
- The crisis consists precisely in the fact that the old is dying and the new
- cannot be born. In this interregnum a great variety of morbid symptoms appear.
- The traditional ruling class has lost its consensus, that is, the consent of
- those over whom it rules. Force alone is not sufficient; what is needed is the
- construction of a new hegemony, the creation of a new collective will.
- """,
- model="qwen3:4b", provider="ollama",
- )
- # Assimilate more content on organic vs traditional intellectuals
- kg, _ = kg_evolve_incremental(
- kg,
- new_content_text="""
- The distinction between organic and traditional intellectuals is fundamental.
- Traditional intellectuals conceive of themselves as autonomous from ruling
- groups, yet every social group has its own category of organic intellectuals
- that give it homogeneity and awareness of its own function. The organic
- intellectual emerges from within the class itself, while the traditional
- sees himself as existing above the social structure.
- """,
- model="qwen3:4b", provider="ollama", get_concepts=True,
- )
- # Consolidate — merge redundant nodes, strengthen high-frequency edges
- kg, sleep_report = kg_sleep_process(kg, model="qwen3:4b", provider="ollama")
- # Dream — generate speculative connections between loosely related concepts
- kg, dream_report = kg_dream_process(kg, model="qwen3:4b", provider="ollama")
- # Search across facts, concepts, and speculative edges
- results = kg_hybrid_search(kg, "What constitutes hegemony in Gramsci's framework?",
- model="qwen3:4b", provider="ollama")
- for r in results:
- print(r['score'], r['text'])
- print(f"{len(kg['facts'])} facts, {len(kg['concepts'])} concepts")
- ```
- Extract structured memories:
- ```python
- from npcpy.llm_funcs import get_facts
- prison_notebooks = """
- Civil society is the sphere of hegemony, the terrain where the dominant
- group exercises consent through cultural and ideological leadership.
- Unlike political society which operates through coercion and state apparatus,
- civil society comprises the church, schools, trade unions, and media.
- The ruling class maintains power not merely through force but through the
- production of consent, shaping common sense itself through cultural institutions.
- War of position requires patient trench warfare on this terrain, building
- counter-hegemonic institutions rather than frontal assault on the state.
- """
- facts = get_facts(prison_notebooks, model="qwen3:4b", provider="ollama")
- for f in facts:
- print(f"[{f.get('type', 'general')}] {f['statement']}")
- ```
- </details>
- <details>
- <summary><b>Sememolution — population-based KG evolution</b></summary>
- Maintain a population of KG variants that evolve independently. Each individual has Poisson-sampled search parameters, producing different traversals each query. Selection pressure from response ranking drives convergence toward useful graph structures.
- ```python
- from npcpy.memory.kg_population import SememolutionPopulation
- pop = SememolutionPopulation(model='qwen3.5:2b', provider='ollama', population_size=100, sample_size=10)
- pop.initialize()
- pop.assimilate_text("""
- The debate over lunar resource extraction has intensified since the discovery
- of water ice in permanently shadowed regions at the lunar poles. While some
- researchers argue that commercial mining could fund further exploration,
- others warn that unregulated extraction could contaminate scientifically
- valuable sites that have remained pristine for billions of years. The
- Artemis Accords attempt to establish a framework for international
- cooperation, but major spacefaring nations have yet to reach consensus
- on property rights and environmental protection standards.
- """)
- pop.assimilate_text("""
- Tidal acceleration gradually increases the orbital distance between Earth
- and Moon at a rate of approximately 3.8 centimeters per year. This
- phenomenon results from angular momentum transfer via gravitational
- interaction, simultaneously slowing Earth's rotation and lengthening the
- day. Paleontological evidence from tidal rhythmites suggests that 620
- million years ago, a day lasted only 21.9 hours and the lunar month was
- just 27.5 days. Projections indicate that in approximately 600 million
- years, tidal effects will no longer support total solar eclipses.
- """)
- # Sleep/dream cycle — each individual consolidates according to its genome
- pop.sleep_cycle()
- # Query: sample 10 individuals, generate competing responses, rank them
- rankings = pop.query_and_rank("What are the central themes connecting these documents?")
- for rank, entry in enumerate(rankings[:3], 1):
- print(f"#{rank} (individual {entry['id']}, score {entry['score']:.3f}): {entry['response'][:120]}...")
- # Selection + reproduction — top performers breed, bottom are replaced
- pop.evolve_generation()
- stats = pop.get_stats()
- print(f"Generation {stats['generation']} | avg fitness {stats['avg_fitness']:.3f} | "
- f"best fitness {stats['best_fitness']:.3f} | diversity {stats['diversity']:.3f}")
- ```
- </details>
- <details>
- <summary><b>Fine-tuning (SFT, RL, MLX)</b></summary>
- **RL Training with DPO for Tool-Calling Agents**
- ```python
- from npcpy.npc_compiler import NPC
- from npcpy.ft.rl import RLConfig, train_with_dpo, load_rl_model
- import json
- def npcsh_reward(trace):
- """Reward function for shell assistant responses."""
- output = trace.get('final_output', '')
- completed = trace.get('completed', False)
- score = 0.0
- if completed:
- score += 2.0
- if 50 < len(output) < 1500:
- score += 1.0
- if '```' in output:
- score += 1.0
- if any(cmd in output.lower() for cmd in ['ls', 'cd', 'cat', 'grep', 'find', 'pip', 'git']):
- score += 0.3
- return max(0.0, min(10.0, score + 5.0))
- # Load preference pairs from agent traces
- traces = []
- with open('preference_pairs.jsonl', 'r') as f:
- for line in f:
- pair = json.loads(line)
- traces.append({
- 'task_prompt': pair['prompt'],
- 'final_output': pair['chosen'],
- 'reward': pair.get('chosen_score', 8.0),
- 'completed': True
- })
- traces.append({
- 'task_prompt': pair['prompt'],
- 'final_output': pair['rejected'],
- 'reward': pair.get('rejected_score', 3.0),
- 'completed': False
- })
- config = RLConfig(
- base_model_name="Qwen/Qwen2.5-0.5B-Instruct",
- adapter_path="./npcsh_adapter",
- num_train_epochs=3,
- per_device_train_batch_size=2,
- learning_rate=5e-5,
- beta=0.1
- )
- adapter_path = train_with_dpo(traces, config)
- print(f"Trained adapter saved to: {adapter_path}")
- ```
- **SFT for Scientific Writing Style Transfer**
- ```python
- from npcpy.llm_funcs import get_llm_response
- from npcpy.ft import SFTConfig, run_sft
- # Generate scientific writing dataset from style samples
- def generate_scientific_trace(question, reasoning_model, converter_model, style_chunks):
- """Generate native reasoning then rewrite in scientific voice."""
- # Step 1: Get reasoning trace
- native_prompt = f"""Answer this question with detailed reasoning.
- Question: {question}
- Provide your step-by-step reasoning and final answer."""
- native_response = get_llm_response(native_prompt, model=reasoning_model, provider='ollama')
- native_trace = native_response['response']
- # Step 2: Rewrite in scientific style
- style_context = '\n\n---\n\n'.join(style_chunks[:8])
- rewrite_prompt = f"""Rewrite the following reasoning trace in the scientific writing style demonstrated by the excerpts below.
- Original Reasoning Trace:
- {native_trace}
- SCIENTIFIC PAPER EXCERPTS:
- {style_context}
- Task:
- 1. Rewrite the reasoning in the style of the scientific paper excerpts
- 2. Use LaTeX notation where appropriate
- 3. Preserve the logical flow and factual content
- 4. Match the prose density and intellectual register"""
- rewritten = get_llm_response(rewrite_prompt, model=converter_model, provider='ollama')
- return rewritten['response']
- # Train on generated examples
- X_train = ["What is the relationship between quantum contextuality and natural language interpretation?"]
- y_train = [generate_scientific_trace(X_train[0], 'qwen3:8b', 'qwen3:8b', style_chunks)]
- sft_config = SFTConfig(
- base_model_name="Qwen/Qwen3-4B",
- output_model_path="models/scientific-writer",
- device='mlx',
- num_train_epochs=100,
- per_device_train_batch_size=1,
- lora_r=128,
- lora_alpha=256
- )
- model_path = run_sft(X_train, y_train, config=sft_config, format_style="llama")
- ```
- </details>
- ## Features
- - **[Agents (NPCs)](https://npcpy.readthedocs.io/en/latest/guides/agents/)** — Agents with personas, directives, and tool calling. Subclasses: `Agent` (default tools), `ToolAgent` (custom tools + MCP), `CodingAgent` (auto-execute code blocks)
- - **[Multi-Agent Teams](https://npcpy.readthedocs.io/en/latest/guides/teams/)** — Team orchestration with a coordinator (forenpc)
- - **[Jinx Workflows](https://npcpy.readthedocs.io/en/latest/guides/jinx-workflows/)** — Jinja Execution templates for multi-step prompt pipelines
- - **[Skills](https://npcpy.readthedocs.io/en/latest/guides/skills/)** — Knowledge-content jinxes that serve instructional sections to agents on demand
- - **[NPCArray](https://npcpy.readthedocs.io/en/latest/guides/npc-array/)** — NumPy-like vectorized operations over model populations
- - **[Image, Audio & Video](https://npcpy.readthedocs.io/en/latest/guides/image-audio-video/)** — Generation via Ollama, diffusers, OpenAI, Gemini, ElevenLabs
- - **[Knowledge Graphs](https://npcpy.readthedocs.io/en/latest/guides/knowledge-graphs/)** — Build and evolve knowledge graphs from text with sleep/dream lifecycle
- - **[Sememolution](https://npcpy.readthedocs.io/en/latest/guides/knowledge-graphs/#sememolution-population-based-kg-evolution)** — Population-based KG evolution with genetic selection and Poisson-sampled search
- - **[Memory Pipeline](https://npcpy.readthedocs.io/en/latest/guides/knowledge-graphs/#memory-extraction-and-lifecycle)** — Extract, approve, and backfill memories with self-improving quality feedback
- - **[Fine-Tuning & Evolution](https://npcpy.readthedocs.io/en/latest/guides/fine-tuning/)** — SFT, USFT, RL/DPO, diffusion, genetic algorithms, MLX on Apple Silicon
- - **[Serving](https://npcpy.readthedocs.io/en/latest/guides/serving/)** — Flask server for deploying teams via REST API
- - **[ML Functions](https://npcpy.readthedocs.io/en/latest/guides/ml-funcs/)** — Scikit-learn grid search, ensemble prediction, PyTorch training
- - **[Streaming & JSON](https://npcpy.readthedocs.io/en/latest/guides/llm-responses/)** — Streaming responses, structured JSON output, message history
- ## Providers
- Works with all major LLM providers through LiteLLM: `airllm`, `anthropic`, `deepseek`, `gemini`, `ollama`, `openai`, `openai-like`, and more.
- <details><summary>API Route</summary>
- Set `API_ROUTE_API_KEY` and use `provider="api-route"` with an exact model ID from your account's authenticated `GET /v1/models` response, for example `gpt-6.1-sol`. [API Route](https://api-route.com) uses the OpenAI-compatible Base URL `https://global.api-route.com/v1`; set `API_ROUTE_API_URL` to override it. The alias `api_route` is also accepted. Explicit `api_url` and `api_key` arguments take precedence.
- ```python
- from npcpy import get_llm_response
- response = get_llm_response("Say hello in one short sentence.", model="gpt-6.1-sol", provider="api-route")
- print(response["response"])
- ```
- </details>
- <details><summary>Atlas Cloud</summary>
- Set `ATLASCLOUD_API_KEY` and use `provider="atlascloud"` with any model ID from the [Atlas Cloud model list](https://www.atlascloud.ai/models), for example `deepseek-ai/deepseek-v4-flash`, `zai-org/glm-5.2` or `moonshotai/kimi-k3`. Requests go to the OpenAI-compatible Base URL `https://api.atlascloud.ai/v1`; set `ATLASCLOUD_API_URL` to override it.
- ```python
- response = get_llm_response("Say hello in one short sentence.", model="deepseek-ai/deepseek-v4-flash", provider="atlascloud")
- print(response["response"])
- ```
- </details>
- <details><summary>cheapaimodel</summary>
- Set `CHEAPAIMODEL_API_KEY` and use `provider="cheapaimodel"` with a model ID from the [model list](https://cheapaimodel.ai/models), for example `deepseek-v4-1-flash`, `glm-5.3`, `kimi-k3` or `grok-4.7`. Requests go to the OpenAI-compatible base URL `https://api.cheapaimodel.ai/v1`; set `CHEAPAIMODEL_API_URL` to override it. Usage is billed per token from a prepaid USD balance; create a key in the [console](https://console.cheapaimodel.ai/keys). See the [docs](https://cheapaimodel.ai/docs) or [cheapaimodel.ai](https://cheapaimodel.ai/?utm_source=npcpy).
- ```python
- response = get_llm_response("Say hello in one short sentence.", model="deepseek-v4-1-flash", provider="cheapaimodel")
- print(response["response"])
- ```
- </details>
- <details><summary>Cheaper Inference</summary>
- Set `CHEAPER_INFERENCE_API_KEY` and use `provider="cheaperinference"` with any model ID from the [Cheaper Inference model list](https://cheaperinference.com/markets), for example `gpt-5.4-mini`, `claude-sonnet-5` or `glm-5.3`. Requests go to the OpenAI-compatible Base URL `https://api.cheaperinference.com/v1`; set `CHEAPER_INFERENCE_API_URL` to override it.
- ```python
- response = get_llm_response("Say hello in one short sentence.", model="gpt-5.4-mini", provider="cheaperinference")
- print(response["response"])
- ```
- </details>
- <details><summary>CloudGPU</summary>
- Set `CLOUDGPU_API_KEY` and use `provider="cloudgpu"` with a model ID from CloudGPU's model list (`GET https://cloudgpu.app/v1/models`), for example `deepseek-v4.1-flash`, `kimi-k2.7-code` or `glm-5.3-flash`. Requests go to the OpenAI-compatible base URL `https://cloudgpu.app/v1`; set `CLOUDGPU_API_URL` to override it. Keys are created in the CloudGPU console; see the [API docs](https://cloudgpu.app/api/docs?utm_source=github&utm_medium=referral&utm_campaign=202611_seg06_indiedev&utm_content=github_npcpy_provider).
- ```python
- response = get_llm_response("Say hello in one short sentence.", model="deepseek-v4.1-flash", provider="cloudgpu")
- print(response["response"])
- ```
- </details>
- <details><summary>MiniMax</summary>
- Set `MINIMAX_API_KEY` and use `provider="minimax"`. When no model is configured, `MiniMax-M3.1-Flash` is the default; the model list offers it first, followed by `MiniMax-M3`. Explicit saved or custom model IDs remain supported, including legacy IDs. The optional `MINIMAX_API_URL` setting selects the region and compatible protocol; it defaults to the global OpenAI-compatible Base URL.
- | Region | OpenAI-compatible Base URL | Anthropic-compatible Base URL |
- | --- | --- | --- |
- | Global | `https://api.minimax.io/v1` | `https://api.minimax.io/anthropic` |
- | China | `https://api.minimaxi.com/v1` | `https://api.minimaxi.com/anthropic` |
- Use the Anthropic-compatible Base URL exactly as shown. The client appends `/v1/messages` when sending a request.
- For Flash, use adaptive thinking (`thinking={"type": "adaptive"}`) and an optional `reasoning_effort` of `low`, `medium`, `high`, `xhigh`, or `max`; Anthropic-compatible requests send this as `output_config.effort`. Flash does not support disabled thinking. M3 retains its existing thinking modes. OpenRouter lists `minimax/minimax-m3.1-flash:free` first and `minimax/minimax-m3` second, using their full gateway IDs.
- </details>
- <details><summary>Obscurify.ai</summary>
- Set `OBSCURIFY_API_KEY` and use `provider="obscurify"` with a model ID from the public model list (`GET https://obscurify.ai/v1/models`, no key needed), for example `deepseek/deepseek-v4-flash`, `moonshotai/kimi-k2-0905` or `z-ai/glm-5.3`. Requests go to the OpenAI-compatible base URL `https://obscurify.ai/v1`; set `OBSCURIFY_API_URL` to override it. Accounts are a random account number with no email; the key is under "Show API Key" on the [account page](https://obscurify.ai/account). See the [API docs](https://obscurify.ai/api-docs) or [obscurify.ai](https://obscurify.ai/?utm_source=npcpy).
- ```python
- response = get_llm_response("Say hello in one short sentence.", model="deepseek/deepseek-v4-flash", provider="obscurify")
- print(response["response"])
- ```
- </details>
- <details><summary>Opper</summary>
- Set `OPPER_API_KEY` and use `provider="opper"` with any model ID from the [Opper model catalogue](https://opper.ai/models), for example `claude-sonnet-4-6`, `gpt-5.4-mini` or `gemini-3.8-flash`. These pool names route across the providers serving that model; a `provider/model` ID such as `anthropic/claude-sonnet-4-6` pins one route. Requests go to the OpenAI-compatible Base URL `https://api.opper.ai/v3/compat`; set `OPPER_API_URL` to override it. Keys are created at [platform.opper.ai](https://platform.opper.ai).
- ```python
- response = get_llm_response("Say hello in one short sentence.", model="claude-sonnet-4-6", provider="opper")
- print(response["response"])
- ```
- </details>
- <details><summary>Requesty</summary>
- Set `REQUESTY_API_KEY` and use `provider="requesty"` with a `vendor/model` ID from Requesty's public model list (`GET https://router.requesty.ai/v1/models`), for example `openai/gpt-4o-mini`, `anthropic/claude-sonnet-5` or `google/gemini-2.5-flash`. Requests go to the OpenAI-compatible Base URL `https://router.requesty.ai/v1` and are routed to the first-party providers (OpenAI, Anthropic, Google and others); set `REQUESTY_API_URL` to override it, for example `https://router.eu.requesty.ai/v1` for the EU endpoint. Keys are created in the [Requesty dashboard](https://app.requesty.ai/api-keys).
- ```python
- response = get_llm_response("Say hello in one short sentence.", model="openai/gpt-4o-mini", provider="requesty")
- print(response["response"])
- ```
- </details>
- <details><summary>Runcrate</summary>
- Set `RUNCRATE_API_KEY` and use `provider="runcrate"` with any `vendor/model` ID from Runcrate's public model list (`GET https://api.runcrate.ai/v1/models`), for example `deepseek-ai/DeepSeek-V4.1-Flash` or `openai/gpt-oss-120b`. Requests go to the OpenAI-compatible Base URL `https://api.runcrate.ai/v1`; set `RUNCRATE_API_URL` to override it. Open models are free with your GitHub account; keys are created in the [Runcrate dashboard](https://www.runcrate.ai/dashboard/api-keys?utm_source=npcpy&utm_medium=directory&utm_campaign=gpu_pricing).
- ```python
- response = get_llm_response("Say hello in one short sentence.", model="deepseek-ai/DeepSeek-V4.1-Flash", provider="runcrate")
- print(response["response"])
- ```
- </details>
- <details><summary>UberLLM</summary>
- Set `UBERLLM_API_KEY` and use `provider="uberllm"` with a `vendor/model` ID from UberLLM's public model list (`GET https://api.uberllm.dev/v1/models`), for example `deepseek/deepseek-v4.1-flash`, `openai/gpt-5.4-mini` or `anthropic/claude-sonnet-4.6`. Requests go to the OpenAI-compatible base URL `https://api.uberllm.dev/v1`; set `UBERLLM_API_URL` to override it. Usage is prepaid and billed per request (failed requests are not billed); per-model prices are on the [model list](https://uberllm.dev/models) and keys are created at [uberllm.dev/signup](https://uberllm.dev/signup). See the [quickstart](https://uberllm.dev/docs/quickstart).
- ```python
- response = get_llm_response("Say hello in one short sentence.", model="deepseek/deepseek-v4.1-flash", provider="uberllm")
- <details><summary>Standard Compute</summary>
- Set `STANDARDCOMPUTE_API_KEY` and use `provider="standardcompute"`. The model `StandardCompute` is routed: each request goes to the cheapest enabled model that can handle it, with automatic fallback. To pin a model, use any ID from the public model list (`GET https://api.stdcmpt.com/v1/models`), for example `deepseek/deepseek-v4.1-flash` or `z-ai/glm-5.3`. Requests go to the OpenAI-compatible Base URL `https://api.stdcmpt.com/v1`; set `STANDARDCOMPUTE_API_URL` to override it. Keys are created at [standardcompute.com](https://standardcompute.com/?utm_source=npcpy).
- ```python
- response = get_llm_response("Say hello in one short sentence.", model="StandardCompute", provider="standardcompute")
- print(response["response"])
- ```
- </details>
- ## QLLM-PAM (local, attention-free)
- `npcpy` can run the QLLM-PAM family of local checkpoints directly. QLLM-PAM is a complex-valued, attention-free language model based on Phase-Associative Memory (PAM); see the [Hugging Face model repo](https://huggingface.co/gowravvishwakarma/qllm-pam-v11-e3k3-chat) and the paper on arXiv ([2604.05030](https://arxiv.org/abs/2604.05030)).
- ```python
- from npcpy import get_llm_response
- response = get_llm_response(
- "What is the capital of France?",
- model="gowravvishwakarma/qllm-pam-v11-e3k3-chat",
- provider="qllm",
- max_tokens=32,
- temperature=0.0,
- )
- print(response["response"])
- ```
- The `model` value can be a Hugging Face repo id (downloaded and cached automatically), a local directory, or a `.pt` file path. Supported kwargs include `max_tokens`, `temperature`, `top_k`, `top_p`, `repetition_penalty`, `stream=True`, and `format="json"`.
- ## Installation
- ```bash
- pip install npcpy # base
- pip install npcpy[lite] # + API provider libraries
- pip install npcpy[local] # + ollama, diffusers, transformers, airllm
- pip install npcpy[tts] # + TTS/STT
- pip install npcpy[all] # everything
- ```
- <details><summary>System dependencies</summary>
- **Linux:**
- ```bash
- sudo apt-get install espeak portaudio19-dev python3-pyaudio ffmpeg libcairo2-dev libgirepository1.0-dev
- curl -fsSL https://ollama.com/install.sh | sh
- ollama pull qwen3.5:2b
- ```
- **macOS:**
- ```bash
- brew install portaudio ffmpeg pygobject3 ollama
- brew services start ollama
- ollama pull qwen3.5:2b
- ```
- **Windows:** Install [Ollama](https://ollama.com) and [ffmpeg](https://ffmpeg.org), then `ollama pull qwen3.5:2b`.
- </details>
- API keys go in a `.env` file:
- ```bash
- export OPENAI_API_KEY="your_key"
- export ANTHROPIC_API_KEY="your_key"
- export GEMINI_API_KEY="your_key"
- ```
- ## Read the Docs
- Full documentation, guides, and API reference at [npcpy.readthedocs.io](https://npcpy.readthedocs.io/en/latest/).
- ## Links
- - **[NPC Shell](https://github.com/npc-worldwide/npcsh)** — Command-line shell for interacting with NPCs
- - **[Incognide](https://github.com/npc-worldwide/incognide)** — Desktop environment with AI chat, browser, file viewers, code editor, terminal, knowledge graphs, team management, and more ([download](https://enpisi.com/incognide))
- - [incognidium](https://github.com/npc-worldwide/incognidium) - a rust-native web browser with an NPC Team focused on developing and testing the incognidium browser against Firefox and Chromium.
- -
- ### Use the NPC team data layer organization in other languages:
- - [npcrs](https://github.com/npc-worldwide/npcsh) - rust port of npcpy
- - [nql](https://github.com/npc-worldwide/nql) - SQL-native framework for running agents inside of databases that support LLMs like Google BigQuery, Snowflake, and Databricks.
- - [npcts](https://github.com/npc-worldwide/npcts) - typescript library for NPC data layer
- - [npcd](https://github.com/npc-worldwide/npcd) - rust port of npcd
- -
- ## Research
- - A Quantum Semantic Framework for natural language processing: [arxiv](https://arxiv.org/abs/2506.10077), accepted at [QNLP 2025](https://qnlp.ai)
- - TinyTim: A Family of Language Models for Divergent Generation [arxiv](https://arxiv.org/abs/2508.11607), accepted at NeurIPS 2025 Creative AI Track
- - The production of meaning in the processing of natural language: [arxiv](https://arxiv.org/abs/2603.20381), accepted at [QNLP 2026](https://qnlp.ai)
- - Herding CATs: ALARA for Agent Harness Engineering in Portable Composable Multi-Agent Teams - [arxiv](https://arxiv.org/abs/2603.20380), accepted at [HAXD 2026](https://intelligent-systems.net/haxd2026/)
- Has your research benefited from npcpy? Let us know!
- ## Support
- [Monthly donation](https://buymeacoffee.com/npcworldwide) | [Merch](https://enpisi.com/shop) | Consulting: info@npcworldwi.de
- ## Contributing
- Contributions welcome! Submit issues and pull requests on the [GitHub repository](https://github.com/NPC-Worldwide/npcpy).
- ## License
- MIT License.
- ## Star History
- [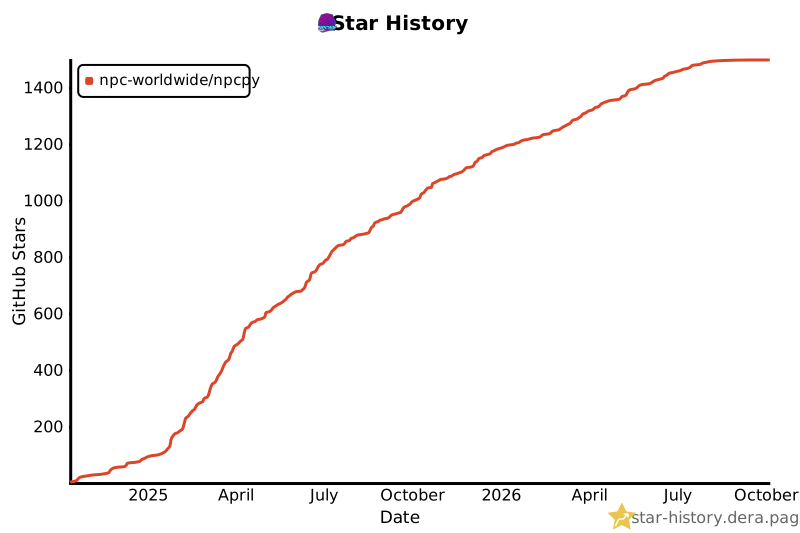](https://star-history.dera.page/#npc-worldwide/npcpy&Date)
Ratings and comments
Sign in to rate this skill.
Sign inFree to use. If it’s helped, pass it on.