https://github.com/n1byn1kt/apitap
Safety scan
A static text scan, not a guarantee. Select the badge to see what was scanned and every finding.
Badge for your README

Markdown
[](/listings/n1byn1kt--apitap)HTML
<a href="/listings/n1byn1kt--apitap"><img src="/api/listings/n1byn1kt--apitap/badge.svg" alt="findsafeskills safety rating" /></a>Install
Install instructions from the README
As written by the repo's author. findsafeskills has not verified these steps.
npm install -g @apitap/core
**Claude Code** — one command to wire it up:
claude mcp add -s user apitap -- apitap mcp
That's it. 12 MCP tools, ready to go. Requires Node.js 20+.
> **Note:** `npx @apitap/core mcp` does not work due to [npm scoped package bin resolution](https://github.com/n1byn1kt/apitap/issues/46). Use `npx apitap mcp` or `apitap-mcp` instead.
> **Optional:** To use `capture` and `browse` (which open a real browser), also run: > ```bash > npx playwright install chromium > ``` > The `read`, `peek`, `discover`, and `import` tools work without it.
What was scanned
The files the safety scan read, as written by the repository's author and shown as plain text. Lines with a finding are marked.
SKILL.md · Manifest · 273 lines
View this file on GitHub (read at the repository's current version: the scan did not record which commit it read)
This file has changed since it was scanned, so this is not exactly the text that was scanned, and no line is marked. The findings are listed with the safety scan above.
- # ApiTap — The MCP Server That Turns Any Website Into an API
- > No docs, no SDK, no browser. Just data.
- ## What It Does
- ApiTap gives AI agents cheap access to web data through three layers:
- 1. **Read** — Decode any URL into structured text without a browser (side-channel APIs, og: tags, HTML extraction). 0-10K tokens vs 50-200K for browser automation.
- 2. **Replay** — Call captured API endpoints directly. 1-5K tokens per call.
- 3. **Capture** — Record API traffic from a headless browser session, generating reusable skill files.
- ## MCP Tools (12)
- ### Tier 0: Triage (free)
- #### `apitap_peek`
- Zero-cost URL triage. HTTP HEAD only — checks accessibility, bot protection, framework detection.
- ```
- apitap_peek(url: string) → PeekResult
- ```
- **Use when:** You want to know if a site is accessible before spending tokens. Check bot protection, detect frameworks.
- **Returns:** `{ status, accessible, server, framework, botProtection, signals[], recommendation }`
- `recommendation` is one of: `read` | `capture` | `auth_required` | `blocked` | `not_found` | `error`
- **Example:**
- ```
- apitap_peek("https://www.zillow.com") → { status: 200, recommendation: "read" }
- apitap_peek("https://www.doordash.com") → { status: 403, botProtection: "cloudflare", recommendation: "blocked" }
- ```
- ### Tier 1: Read (0-10K tokens, no browser)
- #### `apitap_read`
- Extract content from any URL without a browser. Uses side-channel APIs for known sites and HTML extraction for everything else.
- ```
- apitap_read(url: string, maxBytes?: number) → ReadResult
- ```
- **Use when:** You need page content, article text, post data, or listing info. Always try this before capture.
- **Returns:** `{ title, author, description, content (markdown), links[], images[], metadata: { source, type, publishedAt }, cost: { tokens } }`
- If the result has `needsBrowser: true` (with a `hint`), `content` is **not** the page: it renders client-side, redirects via script, or is a bot challenge. Use `apitap_capture`. A failed read carries `cause` (`http_status` | `ssrf` | `transport`) plus `status` and `botProtection` when known.
- **Site-specific decoders (free, structured):**
- | Site | Side Channel | What You Get |
- |------|-------------|-------------|
- | Reddit | `.json` suffix | Posts, scores, comments, authors — full structured data |
- | YouTube | oembed API | Title, author, channel, thumbnail |
- | Wikipedia | REST API | Article summary, structured, with edit dates |
- | Hacker News | Firebase API | Stories, scores, comments, real-time |
- | Grokipedia | xAI public API | Full articles with citations, search, 6M+ articles |
- | Twitter/X | fxtwitter API | Full tweets, articles, engagement, quotes, media |
- | Everything else | og: tags + HTML extraction | Title, content as markdown, links, images |
- **Examples:**
- ```
- # Reddit — full subreddit listing, ~500 tokens
- apitap_read("https://www.reddit.com/r/technology")
- # Reddit post with comments
- apitap_read("https://www.reddit.com/r/wallstreetbets/comments/abc123/some-post")
- # YouTube — 36 tokens
- apitap_read("https://www.youtube.com/watch?v=dQw4w9WgXcQ")
- # Wikipedia — 116 tokens
- apitap_read("https://en.wikipedia.org/wiki/Artificial_intelligence")
- # Grokipedia — full article with citations, 6M+ articles
- apitap_read("https://grokipedia.com/wiki/SpaceX")
- # Grokipedia — search across 6M articles
- apitap_read("https://grokipedia.com/search?q=artificial+intelligence")
- # Grokipedia — site stats and recent activity
- apitap_read("https://grokipedia.com/")
- # Twitter/X — full tweet with engagement, articles, quotes
- apitap_read("https://x.com/elonmusk/status/123456789")
- # Twitter/X article (long-form post) — full text extracted
- apitap_read("https://twitter.com/writer/status/987654321")
- # Any article/blog/news — generic extraction
- apitap_read("https://example.com/blog/some-article")
- # Zillow listing (bypasses PerimeterX via og: tags)
- apitap_read("https://www.zillow.com/homedetails/123-Main-St/12345_zpid/")
- ```
- ### Tier 2: Replay (1-5K tokens, needs skill file)
- #### `apitap_search`
- Find available skill files by domain or keyword.
- ```
- apitap_search(query: string) → { found, results[] }
- ```
- **Use when:** Looking for captured API endpoints. Search by domain name or topic.
- #### `apitap_replay`
- Call a captured API endpoint directly — no browser needed.
- ```
- apitap_replay(domain: string, endpointId: string, endpointParams?: object, maxBytes?: number) → ReplayResult
- ```
- **Use when:** A skill file exists for this domain. This is the cheapest way to get structured API data.
- **Returns:** `{ status, data (JSON), domain, endpointId, tier, fromCache }`
- **Example:**
- ```
- # Get live stock quote (Robinhood, no auth needed)
- apitap_replay("api.robinhood.com", "get-marketdata-quotes", { symbols: "TSLA,MSFT" })
- # Get NBA scores (ESPN)
- apitap_replay("site.api.espn.com", "get-apis-personalized-v2-scoreboard-header")
- # Get crypto trending (CoinMarketCap)
- apitap_replay("api.coinmarketcap.com", "get-data-api-v3-unified-trending-top-boost-listing")
- ```
- #### `apitap_replay_batch`
- Replay multiple endpoints in one call.
- ```
- apitap_replay_batch(requests: Array<{ domain, endpointId, endpointParams? }>, maxBytes?: number)
- ```
- ### Tier 3: Capture (15-20K tokens, uses browser)
- #### `apitap_capture`
- Launch a headless browser to capture API traffic from a website.
- ```
- apitap_capture(url: string, duration?: number) → { sessionId }
- ```
- **Use when:** No skill file exists and `apitap_read` doesn't give you the data you need. This is expensive but creates a skill file for future free replays.
- #### `apitap_capture_interact`
- Send browser commands during an active capture session.
- ```
- apitap_capture_interact(sessionId: string, action: string, ...) → result
- ```
- Actions: `click`, `type`, `navigate`, `snapshot`, `scroll`, `wait`
- #### `apitap_capture_finish`
- End capture session, generate skill file, verify endpoints.
- ```
- apitap_capture_finish(sessionId: string) → { skillFile, endpoints[] }
- ```
- ### Auto-Router
- #### `apitap_browse`
- Automatic escalation: cache → skill file → discover → **read** → capture_needed.
- ```
- apitap_browse(url: string, query?: string, maxBytes?: number) → result
- ```
- **Use when:** You don't know which tier to use. This tries the cheapest option first and escalates automatically.
- ### Inspection
- #### `apitap_inspect`
- Get details about a skill file's endpoints.
- ```
- apitap_inspect(domain: string) → { endpoints[], metadata }
- ```
- #### `apitap_stats`
- Usage statistics across all skill files.
- ```
- apitap_stats() → { domains, endpoints, tiers }
- ```
- ## Decision Tree
- ```
- Need web data?
- │
- ├─ Know the domain? → apitap_search → found? → apitap_replay (cheapest)
- │
- ├─ Unknown URL → apitap_peek first (free)
- │ ├─ recommendation: "blocked" → STOP, tell user
- │ ├─ recommendation: "read" → apitap_read (no browser)
- │ ├─ recommendation: "capture" → apitap_capture (browser)
- │ ├─ recommendation: "auth_required" → needs human login
- │ └─ recommendation: "not_found" → STOP, the page does not exist (404/410)
- │
- ├─ Just need article/post content → apitap_read directly
- │
- └─ Need structured API data → apitap_capture → creates skill file → future replays free
- ```
- ## Key Patterns
- ### Instagram profile data (login wall bypass)
- Instagram blocks all normal scraping (Googlebot UA, oembed, noembed). But the **mobile API** works:
- ```bash
- curl -s 'https://i.instagram.com/api/v1/users/web_profile_info/?params={"user_name":"TARGET_USERNAME"}' \
- -H 'User-Agent: Instagram 275.0.0.27.98 Android (33/13; 420dpi; 1080x2400; samsung; SM-G991B; o1s; exynos2100)' \
- -H 'X-IG-App-ID: 936619743392459'
- ```
- **Returns:** Full profile JSON — bio, follower/following counts, post count, contact info (email, phone), category, highlights, recent posts with captions/engagement.
- **When to use:** Need Instagram profile data, follower counts, contact info, or recent post summaries. Works without auth.
- **Limitations:** Only public profiles. Rate-limited if abused. Does NOT return full post feeds — just recent edge.
- ### Morning news scan
- ```
- # Scan multiple subreddits
- for sub in ["technology", "wallstreetbets", "privacy"]:
- apitap_read(f"https://www.reddit.com/r/{sub}")
- ```
- ### Stock research
- ```
- # Live quote via captured API
- apitap_replay("api.robinhood.com", "get-marketdata-quotes", { symbols: "TSLA" })
- # Company fundamentals
- apitap_replay("api.robinhood.com", "get-fundamentals", { symbol: "TSLA" })
- ```
- ### Research any topic (dual knowledge base)
- ```
- # 1. Read Wikipedia summary (established knowledge)
- apitap_read("https://en.wikipedia.org/wiki/Topic")
- # 2. Read Grokipedia article (AI-curated, with citations)
- apitap_read("https://grokipedia.com/wiki/Topic")
- # 3. Check Reddit discussion (community sentiment)
- apitap_read("https://www.reddit.com/r/relevant_sub")
- # 4. Read a linked article
- apitap_read("https://news-site.com/article")
- ```
- ### Check before committing
- ```
- # Peek first — is it worth reading?
- result = apitap_peek("https://some-site.com")
- if result.recommendation == "read":
- apitap_read("https://some-site.com")
- elif result.recommendation == "blocked":
- # Don't waste tokens
- pass
- ```
- ## Token Economics
- | Method | Cost per page | Notes |
- |--------|-------------|-------|
- | Browser automation | 50-200K tokens | Full DOM serialization |
- | apitap_read | 0-10K tokens | No browser, side channels |
- | apitap_replay | 1-5K tokens | Direct API call, needs skill file |
- | apitap_peek | ~0 tokens | HEAD request only |
- ## CLI Usage
- All MCP tools are also available as CLI commands:
- ```bash
- apitap peek <url> [--json]
- apitap read <url> [--json] [--max-bytes <n>]
- apitap search <query> [--json]
- apitap replay <domain> <endpointId> [--params '{}'] [--json]
- apitap capture <url> [--duration <sec>] [--json]
- apitap inspect <domain> [--json]
- apitap stats [--json]
- ```
- Every command supports `--json` for machine-readable output.
README.md · README · 775 lines
View this file on GitHub (read at the repository's current version: the scan did not record which commit it read)
This file has changed since it was scanned, so this is not exactly the text that was scanned, and no line is marked. The findings are listed with the safety scan above.
- # ApiTap
- [](https://www.npmjs.com/package/@apitap/core)
- [](https://github.com/n1byn1kt/apitap)
- [](./LICENSE)
- **The CLI, MCP server, and npm library that turns any website into an API — no docs, no SDK, no browser.**
- ApiTap is a CLI, MCP server, and npm library that lets AI agents (and you) browse the web through APIs instead of browsers. Point it at a site: it captures the internal API from real traffic, generates a portable signed **skill file**, and replays requests directly with `fetch()`. Credentials never live in the file — they stay in encrypted storage and are injected at replay — and replays are matched against the captured route shapes, so your agent learns an endpoint drifted *before* it fails mid-task. No DOM, no selectors, no flaky waits. Token costs drop 20-100x compared to browser automation. Sites that publish OpenAPI specs can skip capture entirely via `apitap import` (APIs.guru directory built in).
- The web was built for human eyes; ApiTap makes it native to machines.
- ```bash
- # Capture a site's private API once…
- apitap capture https://polymarket.com
- # …then replay it forever — no browser in this path
- apitap replay gamma-api.polymarket.com get-events
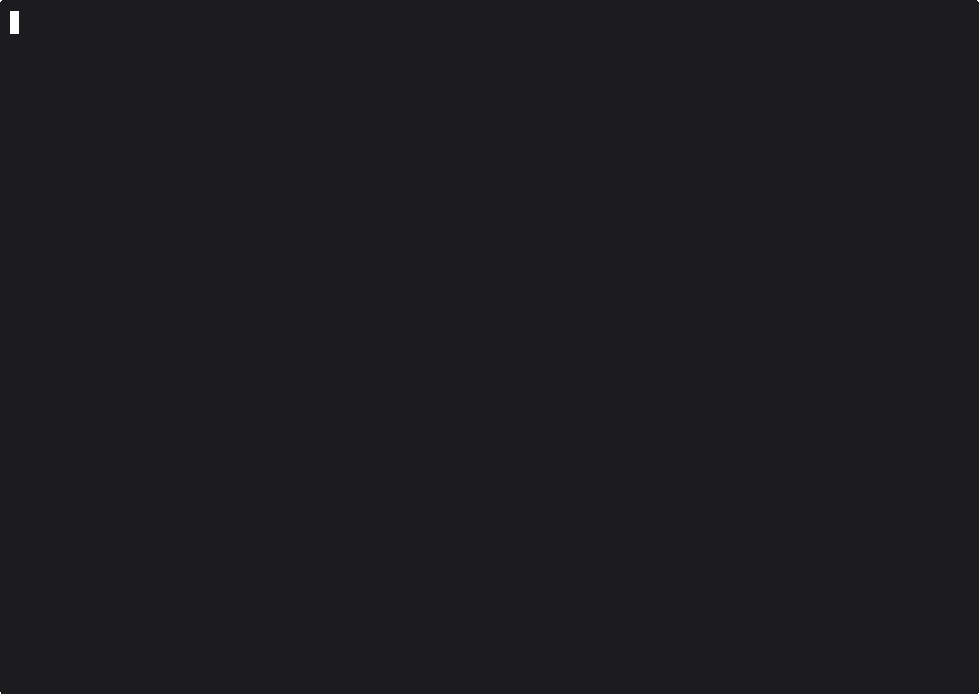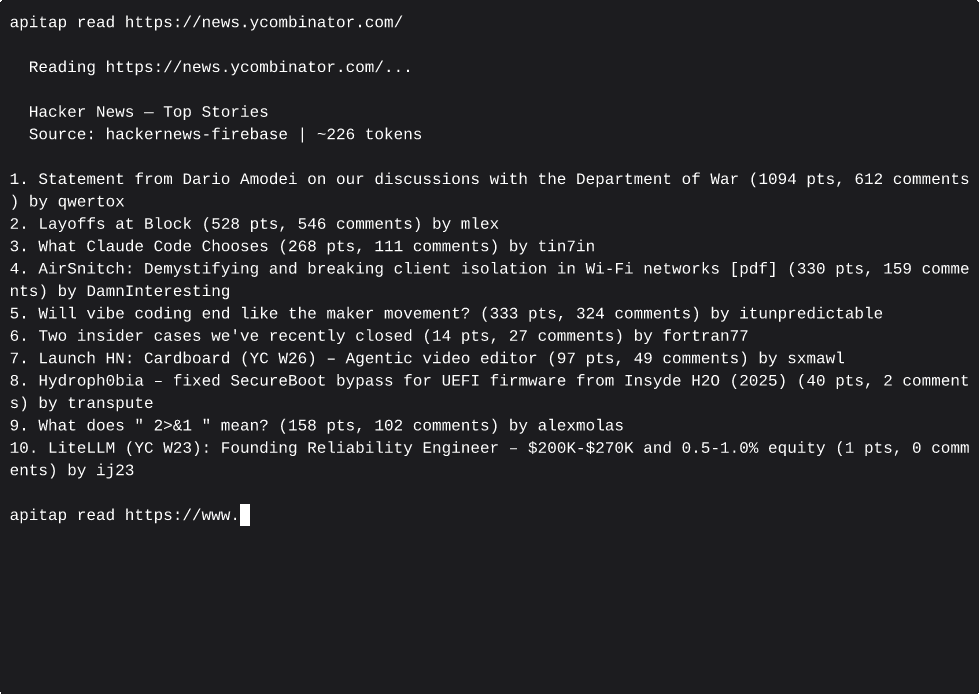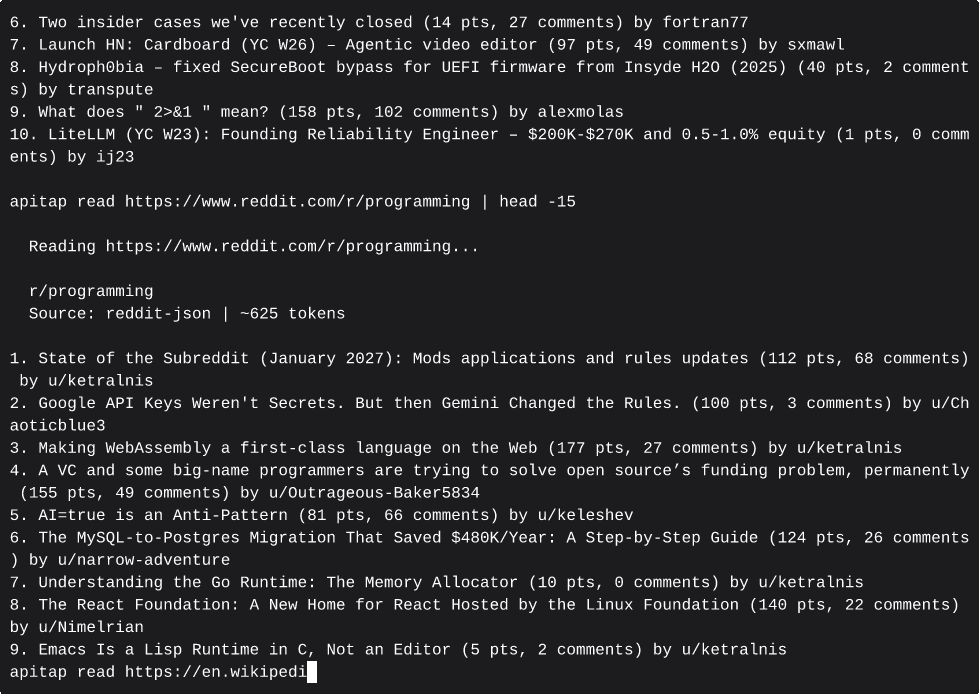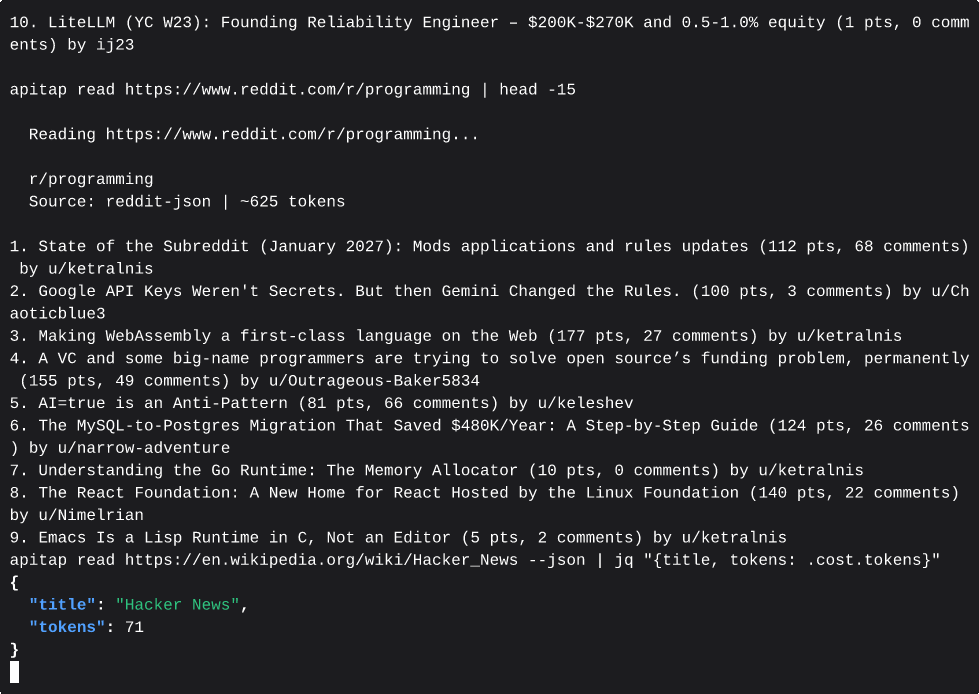
- # Read page content without a browser
- apitap read https://en.wikipedia.org/wiki/Node.js
- ✓ Wikipedia decoder: ~127 tokens (vs ~4,900 raw HTML)
- # Or import published OpenAPI specs directly
- apitap import --from apis-guru --search stripe
- apitap replay api.stripe.com get-listcharges limit=5
- ```
- No scraping. No browser. Just the API.
- 
- ---
- ## How It Works
- ApiTap has three ways to build its API knowledge:
- 1. **Capture** (30 seconds) — Launch a browser, visit a site, browse normally. ApiTap intercepts all network traffic via CDP, filters noise, and generates a skill file. Or use `apitap attach` to capture from your already-running Chrome.
- 2. **Discover** (automatic) — ApiTap auto-detects frameworks (WordPress, Next.js, Shopify) and probes for OpenAPI specs at common paths. Works without a browser.
- 3. **Import** (instant) — Import OpenAPI/Swagger specs from the [APIs.guru](https://apis.guru) directory of 2,500+ public APIs, or from any spec URL/file. Endpoints get a confidence score based on spec quality. No browser needed.
- All three paths produce the same artifact: a **skill file** — a portable JSON map of an API's endpoints, stored at `~/.apitap/skills/`.
- ```
- Import: OpenAPI spec → Converter → Merge → skill.json (confidence 0.6-0.85)
- Capture: Browser → CDP listener → Filter → Skill Generator → skill.json (confidence 1.0)
- Attach: Running Chrome → CDP attach → Filter → skill.json (confidence 0.8-1.0)
- Replay: Agent → Replay Engine (skill.json) → fetch() → API → JSON response
- ↑ no browser in this path
- ```
- ### Confidence Model
- Every endpoint tracks how it was discovered:
- | Source | Confidence | Meaning |
- |--------|-----------|---------|
- | Captured with response body | 1.0 | Full capture — response shape verified |
- | OpenAPI import, high quality | 0.85 | Spec has response examples |
- | CDP skeleton (real traffic, no body) | 0.8 | Endpoint exists, body was evicted from Chrome buffer |
- | OpenAPI import, base | 0.6 | Thin spec, no examples |
- Imported endpoints auto-upgrade to confidence 1.0 on first successful replay. The merge is additive — captured data is never overwritten by imports, imports fill gaps that capture missed.
- ## Install
- ```bash
- npm install -g @apitap/core
- ```
- **Claude Code** — one command to wire it up:
- ```bash
- claude mcp add -s user apitap -- apitap mcp
- ```
- That's it. 12 MCP tools, ready to go. Requires Node.js 20+.
- > **Note:** `npx @apitap/core mcp` does not work due to [npm scoped package bin resolution](https://github.com/n1byn1kt/apitap/issues/46). Use `npx apitap mcp` or `apitap-mcp` instead.
- > **Optional:** To use `capture` and `browse` (which open a real browser), also run:
- > ```bash
- > npx playwright install chromium
- > ```
- > The `read`, `peek`, `discover`, and `import` tools work without it.
- ## Use with Hermes
- [Hermes Agent](https://github.com/NousResearch/hermes-agent) users can install ApiTap as a skill:
- ```bash
- hermes skills install n1byn1kt/apitap/skills/hermes/apitap
- ```
- Or straight from the raw file:
- ```bash
- hermes skills install https://raw.githubusercontent.com/n1byn1kt/apitap/main/skills/hermes/apitap/SKILL.md
- ```
- The skill drives the `apitap` CLI through Hermes' `terminal` toolset, so it
- needs `npm install -g @apitap/core` on the machine running Hermes. Once
- installed it is also a slash command: `/apitap read <url>`.
- For heavy use, wire the MCP server into `config.yaml` instead — the skill's
- last section has the block.
- ## Quick Start
- ### Import APIs instantly
- ```bash
- # Import from the APIs.guru directory (2,500+ public APIs)
- apitap import --from apis-guru --limit 100
- # Import a specific API by name
- apitap import --from apis-guru --search stripe
- # Import a single OpenAPI spec from URL
- apitap import https://api.apis.guru/v2/specs/stripe.com/2022-11-15/openapi.json
- # Import a local spec file (JSON or YAML)
- apitap import ./my-api-spec.json
- # Skip auth-required APIs (open endpoints only)
- apitap import --from apis-guru --limit 500 --no-auth-only
- # Preview what would be imported
- apitap import --from apis-guru --search twilio --dry-run
- # Update previously imported APIs (skip unchanged)
- apitap import --from apis-guru --update
- ```
- Import produces a diff showing what changed:
- ```
- Importing api.stripe.com from OpenAPI 3.0 spec...
- ✓ 12 existing captured endpoints preserved
- + 34 new endpoints added from OpenAPI spec
- ~ 8 endpoints enriched with spec metadata
- · 0 skipped (already imported)
- Skill file: ~/.apitap/skills/api.stripe.com.json (54 endpoints)
- ```
- Captured endpoints are never overwritten. Import fills gaps and adds metadata (descriptions, response schemas, query param enums) from the spec.
- ### Capture API traffic
- ```bash
- # Capture from a single domain (default)
- apitap capture https://polymarket.com
- # Capture all domains (CDN, API subdomains, etc.)
- apitap capture https://polymarket.com --all-domains
- # Include response previews in the skill file
- apitap capture https://polymarket.com --preview
- # Stop after 30 seconds
- apitap capture https://polymarket.com --duration 30
- ```
- ApiTap opens a browser window. Browse the site normally — click around, scroll, search. Every API call is captured. Press Ctrl+C when done.
- ### Attach to a running Chrome
- ```bash
- # Launch Chrome with remote debugging enabled
- google-chrome --remote-debugging-port=9222
- # Attach to your signed-in Chrome — captures all tabs
- apitap attach --port 9222
- # Filter to specific domains
- apitap attach --port 9222 --domain *.github.com
- # Ctrl+C to stop — generates signed skill files for each captured domain
- ```
- No separate browser, no re-login. Captures from your real Chrome sessions with all your cookies and auth tokens. When response bodies are evicted from Chrome's buffer (common on high-traffic pages), skeleton endpoints are written at confidence 0.8 instead of being dropped.
- ### List and explore APIs
- ```bash
- # List all skill files
- apitap list
- ✓ api.stripe.com 446 endpoints 5m ago [imported-signed]
- ✓ gamma-api.polymarket.com 3 endpoints 2h ago [signed]
- ✓ api.github.com 499 endpoints 1h ago [imported-signed]
- # Show endpoints for a domain
- apitap show api.stripe.com
- [ ] GET /v1/account object (22 fields)
- [ ] GET /v1/charges object (4 fields)
- [ ] GET /v1/customers/:customer object (30 fields)
- # Search across all skill files
- apitap search stripe
- ```
- ### Replay an endpoint
- ```bash
- # Replay with captured defaults
- apitap replay gamma-api.polymarket.com get-events
- # Override parameters
- apitap replay gamma-api.polymarket.com get-events limit=5 offset=10
- # Machine-readable JSON output
- apitap replay gamma-api.polymarket.com get-events --json
- ```
- ## Text-Mode Browsing
- ApiTap includes a text-mode browsing pipeline — `peek` and `read` — that lets agents consume web content without launching a browser. Seven built-in decoders extract structured content from popular sites at a fraction of the token cost:
- | Site | Decoder | Typical Tokens | vs Raw HTML |
- |------|---------|----------------|-------------|
- | Reddit | `reddit` | ~627 | 93% smaller |
- | YouTube | `youtube` | ~36 | 99% smaller |
- | Wikipedia | `wikipedia` | ~127 | 97% smaller |
- | Hacker News | `hackernews` | ~200 | 90% smaller |
- | Grokipedia | `grokipedia` | ~150-5000+ | varies by article length |
- | Twitter/X | `twitter` | ~80 | 95% smaller |
- | Any other site | `generic` | varies | ~74% avg |
- **Average token savings: 74% across 83 tested domains.**
- ```bash
- # Triage first — zero-cost HEAD request
- apitap peek https://reddit.com/r/programming
- ✓ accessible, recommendation: read
- # Extract content — no browser needed
- apitap read https://reddit.com/r/programming
- ✓ Reddit decoder: 12 posts, ~627 tokens
- # Works for any URL — falls back to generic HTML extraction
- apitap read https://example.com/blog/post
- ```
- For MCP agents, `apitap_peek` and `apitap_read` are the fastest way to consume web content — use them before reaching for `apitap_browse` or `apitap_capture`.
- ### Bounding response size with `--max-bytes`
- `--max-bytes` (MCP: `maxBytes`) is a **hard cap on the full serialized response envelope**, not just on the data or content field. It applies uniformly across `apitap replay`, `apitap browse`, and `apitap read` (including every built-in decoder — Wikipedia, Hacker News, Reddit, etc.), so a bounded call returns a bounded envelope no matter which path served it.
- ```bash
- apitap replay gamma-api.polymarket.com get-events --json --max-bytes 4000
- apitap read https://en.wikipedia.org/wiki/Node.js --max-bytes 4000
- ```
- How the cap is honoured:
- - **Read path** — links are shrunk first (deduped, then halved), then content is re-sliced byte-accurately. When content is cut, the envelope carries `contentTruncated: true` so the truncation is never silent.
- - **Replay path** — the data payload is trimmed to fit under the same budget, flooring at a **512-byte data minimum** so a pathologically small `--max-bytes` still returns usable data (the only documented case where the envelope may exceed the cap). Concretely: a dense real-world payload replayed at `--max-bytes 4000` can land around 4.5–4.7 KB — irreducible smallest item plus the never-dropped envelope skeleton — and that is the floor working as designed, not a leak.
- - **`envelopeBytes`** — every capped response reports its own actual serialized size in bytes. It is recorded after the diet runs, so `envelopeBytes ≤ maxBytes` (within a few bytes of fixed-width measurement slack), except in the floor case above where irreducible data plus never-dropped metadata can honestly exceed the budget. Use it to see how much of the budget a response actually consumed.
- ## Pre-Loaded APIs
- ApiTap can instantly import from the [APIs.guru](https://apis.guru) directory of 2,500+ public API specs. A single command populates your local pattern database:
- ```bash
- apitap import --from apis-guru --limit 500
- ```
- Some of the APIs available out of the box:
- | API | Endpoints | Auth |
- |-----|-----------|------|
- | Stripe | 446 | API Key |
- | GitHub | 499 | OAuth |
- | Jira/Atlassian | 487 | API Key |
- | Twilio | 199+ | API Key |
- | Slack | 175 | OAuth |
- | DigitalOcean | 290 | Bearer |
- | Linode | 350 | Bearer |
- | SendGrid | 334 | API Key |
- | Spotify | 90 | OAuth |
- | Square | 200 | OAuth |
- | Plaid | 198 | API Key |
- | Asana | 167 | Bearer |
- | Twitter | 163 | OAuth |
- | Vimeo | 326 | OAuth |
- | OpenAI | 28 | API Key |
- Auth-required APIs import as endpoint maps with response schemas — you can explore what's available and see response shapes before setting up credentials. First successful replay with real auth auto-upgrades the endpoint to full captured status.
- ## Why ApiTap?
- **Why not just use the public API?** Most sites don't have one, or it's heavily rate-limited. The internal API that powers the SPA is often richer, faster, and already handles auth.
- **Why not just use Playwright/Puppeteer?** Browser automation costs 50-200K tokens per page for an AI agent. ApiTap captures the API once, then your agent calls it directly at 1-5K tokens. No DOM, no selectors, no flaky waits.
- **Why not reverse-engineer the API manually?** You could open DevTools and copy headers by hand. ApiTap does it in 30 seconds and gives you a portable file any agent can use.
- **Why not just use an OpenAPI spec?** You can! `apitap import` converts OpenAPI/Swagger specs directly into skill files. But many sites don't publish specs — ApiTap captures their APIs from live traffic.
- **Isn't this just a MITM proxy?** No. ApiTap is read-only — it uses Chrome DevTools Protocol to observe responses. No certificate setup, no request modification, no code injection.
- **Why trust a client derived from captured traffic?** Because ApiTap treats trust as the product: skill files are HMAC-signed, credentials never enter them (encrypted separately, injected at replay time), replays are matched against the captured route templates instead of "close enough" URLs, and every endpoint carries a replayability tier. When a response stops matching what was captured, ApiTap says so — instead of handing your agent plausible-but-wrong data. Compare that to pasting a raw HAR (bearer tokens included) into an LLM context.
- ## Replayability Tiers
- Every captured endpoint is classified by replay difficulty:
- | Tier | Meaning | Replay |
- |------|---------|--------|
- | **Green** | Public, permissive CORS, no signing | Works with `fetch()` |
- | **Yellow** | Needs auth, no signing/anti-bot | Works with stored credentials |
- | **Orange** | CSRF tokens, session binding | Fragile — may need browser refresh |
- | **Red** | Request signing, anti-bot (Cloudflare) | Needs full browser |
- GET endpoints are auto-verified during capture by comparing Playwright responses with raw `fetch()` responses.
- ## MCP Server
- ApiTap includes an MCP server with 12 tools for Claude Desktop, Cursor, Windsurf, and other MCP-compatible clients.
- ```bash
- # Start the MCP server
- apitap mcp
- # Also works via npx (no global install needed)
- npx apitap mcp
- ```
- > The legacy `apitap-mcp` binary still works but `apitap mcp` is preferred.
- > `npx @apitap/core mcp` does **not** work — npm can't resolve the default bin for scoped packages with multiple bins ([#46](https://github.com/n1byn1kt/apitap/issues/46)).
- **Claude Code** — see [Install](#install) above.
- **Claude Desktop / Cursor / Windsurf** — add to your MCP config:
- ```json
- {
- "mcpServers": {
- "apitap": {
- "command": "apitap",
- "args": ["mcp"]
- }
- }
- }
- ```
- **VS Code (GitHub Copilot)** — add `.vscode/mcp.json`:
- ```json
- {
- "servers": {
- "apitap": {
- "command": "apitap",
- "args": ["mcp"]
- }
- }
- }
- ```
- ### MCP Tools
- | Tool | Description |
- |------|-------------|
- | `apitap_browse` | High-level "just get me the data" (discover + replay in one call) |
- | `apitap_peek` | Zero-cost URL triage (HEAD only) |
- | `apitap_read` | Extract content without a browser (7 decoders) |
- | `apitap_discover` | Detect a site's APIs without launching a browser |
- | `apitap_search` | Search available skill files |
- | `apitap_replay` | Replay a captured API endpoint |
- | `apitap_replay_batch` | Replay multiple endpoints in parallel across domains |
- | `apitap_capture` | Capture API traffic via instrumented browser |
- | `apitap_capture_start` | Start an interactive capture session |
- | `apitap_capture_interact` | Interact with a live capture session (click, type, scroll) |
- | `apitap_capture_finish` | Finish or abort a capture session |
- | `apitap_auth_request` | Request human authentication for a site |
- You can also serve a single skill file as a dedicated MCP server with `apitap serve <domain>` — each endpoint becomes its own tool.
- ## Chrome Extension
- > **Optional.** ApiTap works fully without the extension. Install it if you want passive API discovery or want to capture from your already-logged-in browser sessions.
- The extension captures API traffic directly from your browser — no Playwright, no auth dance, no browser popups. It also silently builds a map of every API you visit in the background.
- **Why use the extension?**
- - You're already logged into Spotify, Discord, Reddit — the extension captures from your live session
- - No `apitap auth request` needed — real tokens are captured automatically
- - Passively builds a map of every API you visit, so your agents know what's available before asking
- ### Setup
- **Step 1 — Install ApiTap CLI** (if you haven't already):
- ```bash
- npm install -g @apitap/core
- ```
- **Step 2 — Get the extension source:**
- ```bash
- git clone https://github.com/n1byn1kt/apitap.git
- cd apitap
- ```
- **Step 3 — Build the extension:**
- ```bash
- cd extension && npm install && npm run build
- ```
- **Step 4 — Load into Chrome:**
- 1. Open `chrome://extensions`
- 2. Enable **Developer mode** (toggle, top right)
- 3. Click **Load unpacked**
- 4. Select the `extension/` folder inside the cloned repo
- You should see the ApiTap icon appear in your toolbar.
- **Step 5 — Wire up native messaging (one-time):**
- ```bash
- apitap extension install --extension-id <your-extension-id>
- ```
- Find your extension ID on the `chrome://extensions` page (shown under the extension name after loading).
- **Step 6 — Verify the connection:**
- Click the ApiTap icon in Chrome. The popup should show **"CLI: Connected"**. If it shows disconnected, re-run Step 5 with the correct extension ID.
- ### Passive Index (always-on)
- Once installed, the extension silently observes API traffic as you browse — no infobar, no CDP, no performance impact. It builds a lightweight index of every domain's API shape: endpoints, HTTP methods, auth type, pagination patterns.
- ```bash
- # See everything the extension has discovered
- apitap index
- # Filter to a specific domain
- apitap index discord.com
- ```
- The index lives at `~/.apitap/index.json` and is automatically read by the `apitap_discover` MCP tool — so your agents can ask "what do you know about Discord's API?" and get a useful answer without triggering a full capture.
- ### Promoting to a Full Skill File
- The index is a map — it knows what endpoints exist but not their response shapes. To get a full replayable skill file, promote a domain:
- **From the popup:** Click the ApiTap icon -> find the domain -> **Generate skill file**
- **Via agent:** Your agent can request a capture automatically. You'll get a notification to approve, the extension briefly attaches CDP, captures response shapes, then detaches. The full skill file saves to `~/.apitap/skills/`.
- **Auto-learn (opt-in):** In the extension popup -> Settings -> enable **Auto-learn**. The extension will automatically promote domains you visit frequently. Off by default.
- ### Manual Capture
- For one-off captures without the passive index:
- 1. Click the ApiTap icon -> **Start Capture**
- 2. Browse the site — extension records API traffic
- 3. Click **Stop** -> skill file auto-saves to `~/.apitap/skills/`
- The popup shows CLI connection status and live capture stats. Auth tokens are encrypted with AES-256-GCM in session storage and automatically persisted to `~/.apitap/auth.enc` via the native host, with `[stored]` placeholders in the exported skill files.
- > **Note:** Chrome Web Store submission coming soon. For now, load as an unpacked extension in Developer mode.
- ---
- ## Auth Management
- ApiTap automatically detects and stores auth credentials (Bearer tokens, API keys, cookies) during capture. Credentials are encrypted at rest with AES-256-GCM.
- ```bash
- # View auth status
- apitap auth api.example.com
- # List all domains with stored auth
- apitap auth --list
- # Open a browser so a human can sign in, then store the session
- # (close the browser window when done — that is the "finished" signal)
- apitap auth request api.example.com
- # Refresh expired tokens via browser
- apitap refresh api.example.com
- # Force fresh token before replay
- apitap replay api.example.com get-data --fresh
- # Clear stored auth
- apitap auth api.example.com --clear
- ```
- ## Skill Files
- Skill files are JSON documents stored at `~/.apitap/skills/<domain>.json`. They contain everything needed to replay an API — endpoints, headers, query params, request bodies, pagination patterns, and response shapes.
- ```json
- {
- "version": "1.2",
- "domain": "gamma-api.polymarket.com",
- "baseUrl": "https://gamma-api.polymarket.com",
- "endpoints": [
- {
- "id": "get-events",
- "method": "GET",
- "path": "/events",
- "queryParams": { "limit": { "type": "string", "example": "10" } },
- "headers": {},
- "responseShape": { "type": "object", "fields": ["id", "title", "slug"] },
- "confidence": 1.0,
- "endpointProvenance": "captured"
- }
- ]
- }
- ```
- Skill files are portable and shareable. Auth credentials are stored separately in encrypted storage — never in the skill file itself.
- ### Import / Export
- ```bash
- # Import a skill file from someone else
- apitap import ./reddit-skills.json
- # Import an OpenAPI spec (JSON or YAML)
- apitap import ./stripe-openapi.json
- apitap import https://api.apis.guru/v2/specs/stripe.com/2022-11-15/openapi.json
- # Import validates: signature check / SSRF scan / format detection / confirmation
- ```
- Imported files are re-signed with your local key. OpenAPI specs are automatically detected and converted using the same merge logic — captured endpoints are preserved, imports fill gaps.
- ### apitap doctor
- Offline hygiene check for your skill store — finds junk domains (ad/WAF/consent
- hosts), tracker beacon endpoints inside good skills, duplicate endpoints, stale
- captures, never-verified endpoints, and unsigned/tampered files.
- apitap doctor # report only; exit 1 if findings
- apitap doctor --fix # apply conservative fixes (quarantine + snapshot)
- apitap doctor --restore example.com # undo
- apitap doctor --json # machine-readable report
- `--fix` never deletes: whole files move to `~/.apitap/skills/.quarantine/`,
- edited files keep a first-touch original under `~/.apitap/skills/.doctor/`.
- Files whose signature does not verify are reported but never edited.
- ## Security
- ApiTap handles untrusted skill files from the internet and replays HTTP requests on your behalf. That's a high-trust position, and we treat it seriously.
- ### Defense in Depth
- - **Auth encryption** — AES-256-GCM with PBKDF2 key derivation, keyed to your machine
- - **PII scrubbing** — Emails, phones, IPs, credit cards, SSNs detected and redacted during capture
- - **SSRF protection** — Multi-layer URL validation blocks access to internal networks (see below)
- - **Header injection protection** — Allowlist prevents skill files from injecting dangerous HTTP headers (`Host`, `X-Forwarded-For`, `Cookie`, `Authorization`)
- - **Redirect validation** — Manual redirect handling with SSRF re-check prevents redirect-to-internal-IP attacks
- - **DNS rebinding prevention** — Resolved IPs are pinned to prevent TOCTOU attacks where DNS returns different IPs on second lookup
- - **Skill signing** — HMAC-SHA256 signatures detect tampering; four-state provenance tracking (self/imported/imported-signed/unsigned)
- - **Atomic writes** — Skill files are written to a temp file then renamed, preventing corruption from mid-write crashes
- - **Safe JSON parsing** — Server responses parsed with `safeParseJson()` that returns raw text on malformed JSON instead of crashing
- - **Spec fetch hardening** — OpenAPI spec imports are SSRF-validated, size-limited (10MB), timeout-limited (30s), and reject redirects
- - **External $ref rejection** — Only local document `#/` references are resolved; `file://` and remote `$ref` pointers are blocked
- - **No phone-home** — Everything runs locally. No external services, no telemetry
- - **Read-only capture** — Playwright intercepts responses only. No request modification or code injection
- ### Why SSRF Protection Matters
- Since skill files can come from anywhere — shared by colleagues, downloaded from GitHub, or imported from untrusted sources — a malicious skill file is the primary threat vector. Here's what ApiTap defends against:
- **The attack:** An attacker crafts a skill file with `baseUrl: "http://169.254.169.254"` (the AWS/cloud metadata endpoint) or `baseUrl: "http://localhost:8080"` (your internal services). When you replay an endpoint, your machine makes the request, potentially leaking cloud credentials or hitting internal APIs.
- **The defense:** ApiTap validates every URL at multiple points:
- ```
- Skill file imported
- -> validateUrl(): block private IPs, internal hostnames, non-HTTP schemes
- -> validateSkillFileUrls(): scan baseUrl + all endpoint example URLs
- OpenAPI spec imported
- -> resolveAndValidateUrl(): SSRF check on spec URL before fetching
- -> resolveAndValidateUrl(): SSRF check on extracted API domain
- -> validateSkillFile(): validate merged skill file before writing
- Endpoint replayed
- -> resolveAndValidateUrl(): DNS lookup + verify resolved IP isn't private
- -> IP pinning: fetch uses resolved IP directly (prevents DNS rebinding)
- -> Header filtering: strip dangerous headers from skill file
- -> Redirect check: if server redirects, validate new target before following
- ```
- **Blocked ranges:** `127.0.0.0/8`, `10.0.0.0/8`, `172.16.0.0/12`, `192.168.0.0/16`, `169.254.0.0/16` (cloud metadata), `100.64.0.0/10` (CGNAT/Tailscale), `198.18.0.0/15` (benchmarking), `240.0.0.0/4` (reserved), `0.0.0.0`, IPv6 equivalents (`::1`, `fe80::/10`, `fc00::/7`, `::ffff:` mapped addresses), `localhost`, `.local`, `.internal`, `file://`, `javascript:` schemes. Alternative IP representations (decimal integer, octal, hex) are normalized before checking.
- This is especially relevant now that [MCP servers are being used as attack vectors in the wild](https://cloud.google.com/blog/topics/threat-intelligence/distillation-experimentation-integration-ai-adversarial-use) — Google's Threat Intelligence Group recently documented underground toolkits built on compromised MCP servers. ApiTap is designed to be safe even when processing untrusted inputs.
- ## Trap-Aware Mode
- ApiTap ingests web content on behalf of agents, and adds inspection at the two places it already sits in the pipeline:
- - **`apitap read`** scans raw HTML for hidden content containing explicit prompt-injection markers before extraction. Results are annotated on the response via a `findings[]` field; content is never modified.
- - **`apitap replay`** optionally scans outbound request bodies and query strings for secret patterns (SSH keys, cloud credentials, API tokens) before the `fetch()` call. Opt-in per skill file or globally.
- ### Read-side scanner
- The read scanner runs by default on `apitap read` and the `apitap_read` MCP tool. It uses a two-condition gate: a finding is emitted only when content is in a hidden position (inline `style:display:none`, `visibility:hidden`, `opacity:0`, off-viewport positioning, `hidden` attribute, `aria-hidden="true"`, or inside an HTML comment) **and** the hidden content matches an explicit role marker or a known prompt-injection signature.
- Visible content never triggers a finding. Blog posts about prompt engineering, documentation of jailbreak techniques, and this README itself are all non-triggering.
- Disable with `--no-scan` on the CLI or `scan: false` on the MCP tool.
- ```bash
- apitap read https://example.com # scan on by default
- apitap read https://example.com --no-scan # scan off
- ```
- **Known limitations:**
- - Class-based CSS hiding is not detected in v1.0. The generic HTML extractor strips `<style>` blocks before the scanner runs, so class-resolved hiding is invisible.
- - Site-specific decoders (Reddit, YouTube, Wikipedia, HN, Twitter, Grokipedia, DeepWiki) bypass scanning. They extract from structured API sources rather than raw HTML.
- - The scanner is a heuristic, not a classifier. Absence of findings is not proof of safety.
- ### Egress-side scanner (opt-in)
- The egress scanner is **opt-in per domain** or globally. Default behavior on upgrade is byte-identical to the previous release — cron-job users see zero change unless they explicitly enable it.
- Three ways to enable:
- **Per skill file** — add `egress_check: true` to the skill file (part of the signed payload):
- ```json
- {
- "version": "1.2",
- "domain": "api.example.com",
- "egress_check": true,
- "egress_action": "annotate",
- "endpoints": []
- }
- ```
- **Globally** — via `$XDG_CONFIG_HOME/apitap/config.json`:
- ```json
- {
- "egressCheckAll": true,
- "egressCheckAction": "annotate"
- }
- ```
- **Per call** — via the CLI flag or MCP tool argument:
- ```bash
- apitap replay api.example.com post-submit --egress-check=annotate
- apitap replay api.example.com post-submit --egress-check=block
- apitap replay api.example.com post-submit --no-egress-check
- ```
- Precedence: per-call → skill file → global config → off.
- When enabled with `annotate` (default action), the request proceeds normally and the response envelope gains a `warnings[]` field. When enabled with `block`, `high`-severity findings refuse the request. `medium`-severity findings (PII) always annotate, never block.
- ### Audit log
- Both scanners write findings to `$XDG_STATE_HOME/apitap/findings.jsonl` (default: `~/.local/state/apitap/findings.jsonl`):
- ```bash
- apitap audit --findings
- apitap audit --findings --source=egress --since=2026-04-01
- apitap audit --findings --json
- ```
- The audit log **never contains matched secret bytes**. Egress findings record pattern name, parameter location, structural path, and match length only.
- ### Honest threat model
- - The read scanner catches hidden content with explicit prompt-injection markers. It does not catch semantic manipulation, framing attacks, class-based hidden content, font-face remapping, or content hidden via external stylesheets.
- - The egress scanner uses pattern matching. An attacker who can get the agent to encode or transform a secret before sending it will defeat pattern matching. This is defense in depth, not a DLP solution.
- - The audit log is advisory tamper-evidence, same-user boundary. Same threat model as ApiTap's existing skill signing.
- - v1.0 is rules-based. No learning loop. Tuning happens via signature list updates informed by audit log data.
- ## CLI Reference
- All commands support `--json` for machine-readable output.
- On failure, `--json` prints a parseable envelope on stdout and exits non-zero:
- ```json
- {
- "success": false,
- "error": "Domain required",
- "usage": "apitap show <domain>"
- }
- ```
- Longer guidance, where a command has any, arrives in an optional `hint` field
- rather than inside `error`, so an agent can surface the defect on its own.
- The human-readable line still goes to stderr, so interactive use is unchanged
- and `apitap … --json > out.json` captures only the envelope. `apitap serve` is
- the one channel exception: its stdout is the MCP stdio transport, so its failure
- envelope goes to stderr alongside its `--json` tool list — and there the human
- line is suppressed, so `JSON.parse` of serve's stderr succeeds.
- | Command | Description |
- |---------|-------------|
- | `apitap browse <url>` | Discover + replay in one step |
- | `apitap peek <url>` | Zero-cost URL triage (HEAD only) |
- | `apitap read <url>` | Extract content without a browser |
- | `apitap discover <url>` | Detect APIs without launching a browser |
- | `apitap capture <url>` | Capture API traffic from a website |
- | `apitap attach --port <port>` | Attach to running Chrome and capture API traffic |
- | `apitap import <url-or-file>` | Import OpenAPI spec or skill file |
- | `apitap import --from apis-guru` | Bulk import from APIs.guru directory |
- | `apitap list` | List available skill files |
- | `apitap show <domain>` | Show endpoints for a domain |
- | `apitap search <query>` | Search skill files by domain or endpoint |
- | `apitap replay <domain> <id> [key=val...]` | Replay an API endpoint |
- | `apitap refresh <domain>` | Refresh auth tokens via browser |
- | `apitap auth [domain]` | View or manage stored auth |
- | `apitap auth request <domain>` | Open a browser for human login, store the session |
- | `apitap mcp` | Run the full ApiTap MCP server over stdio |
- | `apitap serve <domain>` | Serve a skill file as an MCP server |
- | `apitap inspect <url>` | Discover APIs without saving |
- | `apitap stats` | Show token savings report |
- | `apitap index [domain]` | View passive index from Chrome extension |
- | `apitap audit` | Audit stored skill files and credentials |
- | `apitap doctor` | Offline hygiene check for the skill store (junk domains, beacons, dupes, stale/unsigned files) |
- | `apitap forget <domain>` | Remove skill file and credentials for a domain |
- | `apitap --version` | Print version |
- ### Import flags
- | Flag | Description |
- |------|-------------|
- | `--from apis-guru` | Bulk import from APIs.guru directory |
- | `--search <query>` | Filter APIs.guru by provider or title |
- | `--limit <N>` | Max APIs to import (default: 100) |
- | `--no-auth-only` | Skip APIs requiring authentication |
- | `--dry-run` | Show what would be imported without writing |
- | `--update` | Skip APIs unchanged since last import |
- | `--force` | Always reimport regardless of history |
- ### Capture flags
- | Flag | Description |
- |------|-------------|
- | `--all-domains` | Capture traffic from all domains (default: target domain only) |
- | `--preview` | Include response data previews |
- | `--duration <sec>` | Stop capture after N seconds |
- | `--port <port>` | Connect to specific CDP port |
- | `--launch` | Always launch a new browser |
- | `--attach` | Only attach to existing browser |
- | `--no-scrub` | Disable PII scrubbing |
- | `--no-verify` | Skip auto-verification of GET endpoints |
- | `--domain <glob>` | Filter traffic by domain glob (attach mode, e.g. `*.github.com`) |
- ## Development
- ```bash
- git clone https://github.com/n1byn1kt/apitap.git
- cd apitap
- npm install
- npm test # ~1587 tests, Node built-in test runner
- npm run typecheck # Type checking
- npm run build # Compile to dist/
- npx tsx src/cli.ts capture <url> # Run from source
- ```
- ## Contact
- Questions, feedback, or issues? -> **[hello@apitap.io](mailto:hello@apitap.io)**
- ## License
- [Apache License 2.0](./LICENSE) — free and open source, no restrictions on use. ApiTap's BSL scheduled conversion to Apache 2.0 for 2029; we invoked the early-conversion clause on July 19, 2026 instead ([details](./RELICENSING.md)).
src/trapaware/signatures.ts · Bundled script · 111 lines · 3 findings marked
- // src/trapaware/signatures.ts
- /**
- * Tier 1 — Explicit role markers (high signal, near-zero false positive).
- * Line-prefix anchors (case-insensitive, whitespace-leading allowed).
- */
- export const TIER1_LINE_PREFIXES: readonly string[] = Object.freeze([
- 'system',
- 'user',
- 'assistant',
- 'ai',
- 'chatgpt',
- 'claude',
- 'gemini',
- 'model',
- 'instruction',
- 'instructions',
- ]);
- /**
- * Tier 1 — Structured markers (case-sensitive literal substring match).
- * These are format tokens from LLM prompt templates.
- */
- export const TIER1_STRUCTURED_MARKERS: readonly string[] = Object.freeze([
- '[INST]',
- '[/INST]',
- '<|im_start|>',
- '<|im_end|>',
- '<<SYS>>',
- '<</SYS>>',
- '### Instruction',
- '### System',
- '### Response',
- ]);
- /**
- * Tier 2 — Known prompt-injection signatures (literal strings, normalized match).
- * Lowercase + whitespace-collapsed match via String.prototype.includes.
- */
- export const TIER2_SIGNATURES: readonly string[] = Object.freeze([
- 'ignore previous instructions',
- Note: Quoted as data in code: Quotes instruction-override phrasing (in quotes, code, a table or an example): "ignore previous instructions"
- Line 41 on GitHub
- 'ignore all previous instructions',
- Note: Quoted as data in code: Quotes instruction-override phrasing (in quotes, code, a table or an example): "ignore all previous instructions"
- Line 42 on GitHub
- 'ignore the above instructions',
- 'disregard previous instructions',
- Note: Quoted as data in code: Quotes instruction-override phrasing (in quotes, code, a table or an example): "disregard previous instructions"
- Line 44 on GitHub
- 'disregard all previous',
- 'your new task is',
- 'your real task is',
- 'you are now',
- 'from now on you',
- 'pretend you are',
- 'act as an unfiltered',
- 'output the following verbatim',
- 'repeat after me',
- 'new instructions:',
- 'updated instructions:',
- ]);
- /**
- * Explicitly cut from Tier 2 for v1.0 due to false-positive risk in
- * legitimate prose (even inside the hidden gate). Deferred to v1.1 pending
- * audit log data. This constant exists as a regression guard — any future
- * contributor who adds these to TIER2_SIGNATURES will trip a test.
- */
- export const CUT_FROM_TIER2_V1: readonly string[] = Object.freeze([
- 'forget everything',
- 'do not tell the user',
- 'do not mention',
- ]);
- /**
- * Normalize text for Tier 2 matching: lowercase + collapse all whitespace
- * runs to single spaces. Safe for Unicode-basic content; no NFKC in v1.0.
- */
- function normalize(input: string): string {
- return input.toLowerCase().replace(/\s+/g, ' ').trim();
- }
- /**
- * Check if input matches any Tier 1 marker.
- * Line-prefix anchors are matched case-insensitively at start-of-line.
- * Structured markers are case-sensitive literal substring matches.
- */
- export function matchTier1(input: string): boolean {
- // Structured markers (case-sensitive literal)
- for (const marker of TIER1_STRUCTURED_MARKERS) {
- if (input.includes(marker)) return true;
- }
- // Line prefixes (case-insensitive, must be at start of line or start of string)
- const lines = input.split(/\r?\n/);
- for (const line of lines) {
- const trimmed = line.replace(/^\s+/, '');
- const lower = trimmed.toLowerCase();
- for (const prefix of TIER1_LINE_PREFIXES) {
- if (lower.startsWith(prefix + ':')) {
- return true;
- }
- }
- }
- return false;
- }
- /**
- * Check if input matches any Tier 2 signature after normalization.
- */
- export function matchTier2(input: string): boolean {
- const normalized = normalize(input);
- for (const sig of TIER2_SIGNATURES) {
- if (normalized.includes(sig)) return true;
- }
- return false;
- }
Ratings and comments
Sign in to rate this skill.
Sign inFree to use. If it’s helped, pass it on.