llamastash
Zero-overhead, terminal-native local-LLM orchestrator. Run any engine, any model via the same proxy.
Safety scan
A static text scan, not a guarantee. Select the badge to see what was scanned and every finding.
Check it deeper on your machine
It has changed since its scan on 11 Nov 2026.
As a Claude Code plugin, install it and then ask Claude Code:
/plugin marketplace add keithmackay/mackayi/plugin install scanskillsafety@mackayiDo a deep scan of https://github.com/llamastash/llamastash with scanskillsafety
Or from a terminal, clone it and run it:
git clone https://github.com/keithmackay/scanskillsafety-skill ~/.claude/skills/scanskillsafetynode ~/.claude/skills/scanskillsafety/cli.cjs --deep 'https://github.com/llamastash/llamastash'
It checks the exact commit: every file, its packages against OSV (api.osv.dev), how it compares with this page's scan (findsafeskills.com receives the repository's address), and, if you agree, Claude reading every file with your own Claude subscription. It never runs the code.
Badge for your README

Markdown
[](/listings/llamastash--llamastash)HTML
<a href="/listings/llamastash--llamastash"><img src="/api/listings/llamastash--llamastash/badge.svg" alt="findsafeskills safety rating" /></a>Install
Install instructions from the README
As written by the repo's author. findsafeskills has not verified these steps.
These steps run a script from the network that findsafeskills does not scan.
Pick whichever channel you prefer — all install the same binary. Full per-platform notes, troubleshooting, and the agent-friendly non-interactive path live in [`INSTALL.md`](INSTALL.md).
# macOS + Linux, one-shot
curl -fsSL https://llamastash.dev/install.sh | sh

# Windows 11 (PowerShell, no admin elevation)
irm https://llamastash.dev/install.ps1 | iex

# Homebrew (macOS + Linuxbrew)
brew install llamastash/llamastash/llamastash

# Arch Linux (AUR — pick one)
yay -S llamastash       # source build

# From crates.io (any platform with a Rust toolchain)
cargo install llamastash

# Windows via Scoop bucket
scoop bucket add llamastash https://github.com/llamastash/scoop-llamastash && scoop install llamastash
_Windows: 64-bit Windows 10 1809+ / Windows 11, PowerShell 5.1+, [Windows Terminal](https://aka.ms/terminal) recommended for the TUI; the bundled `llama-server` needs the VC++ 2015–2022 Redistributable (x64). See [INSTALL.md](INSTALL.md#platform-notes)._
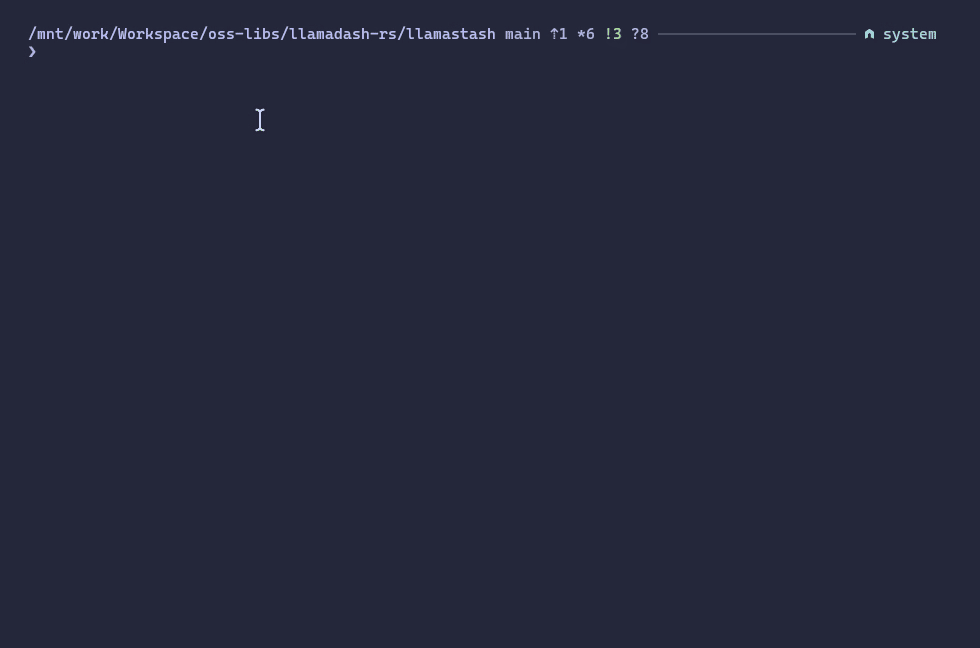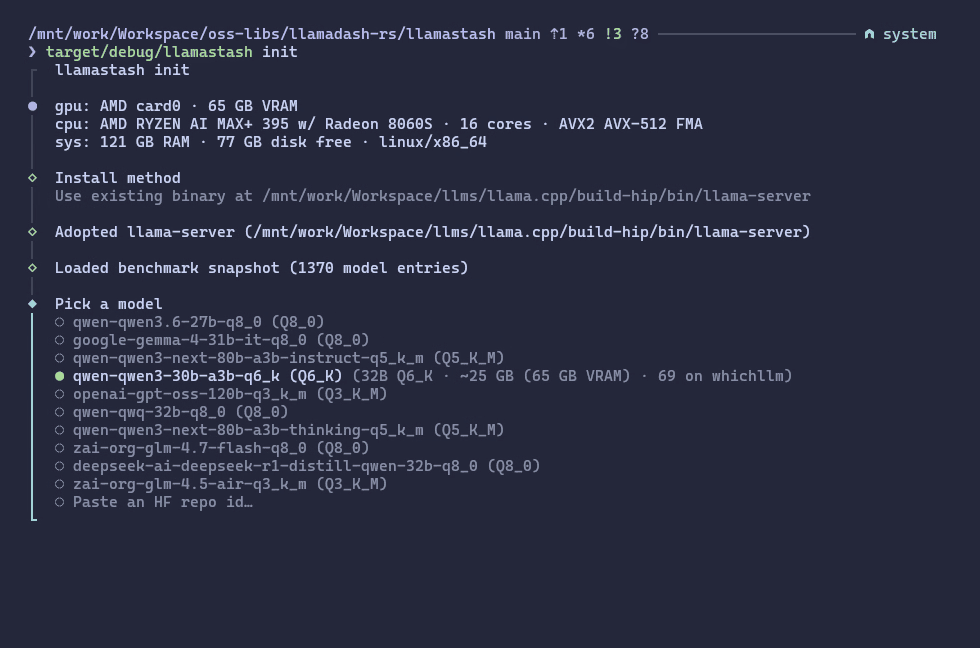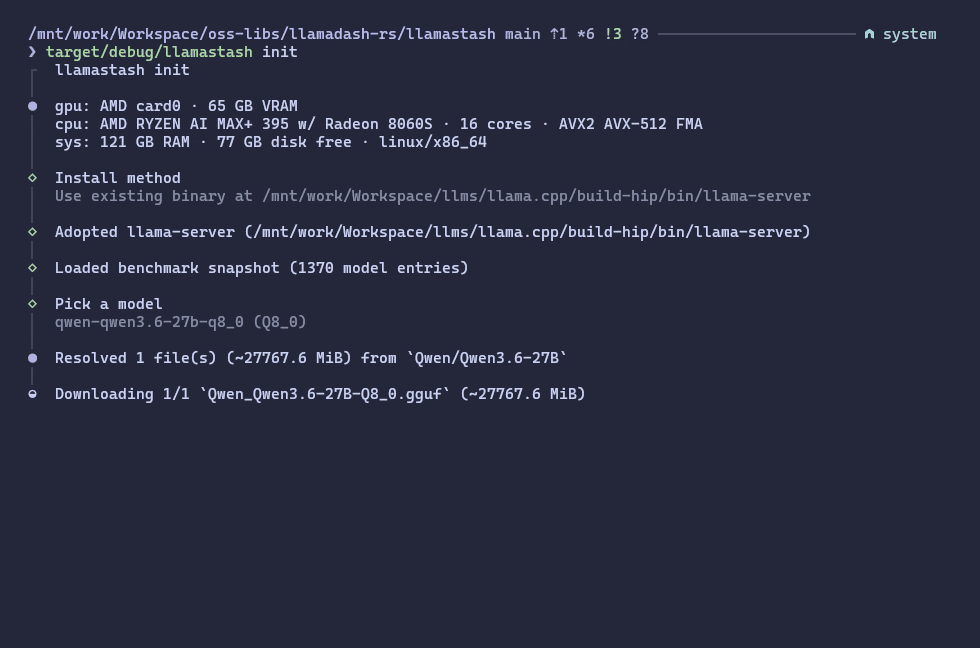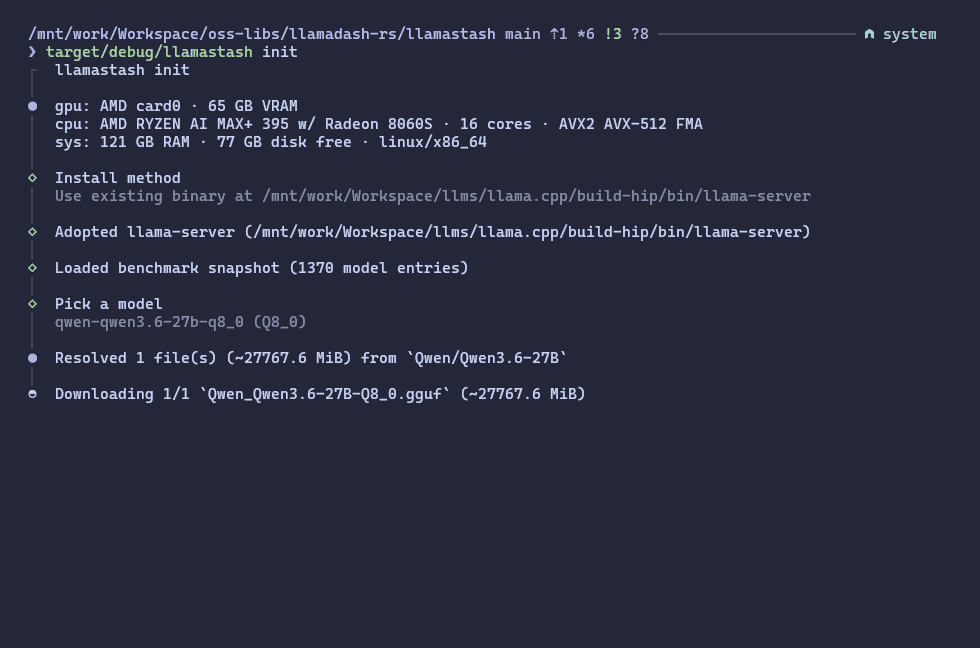
Then run `llamastash init` — the interactive wizard installs `llama-server` for your hardware, downloads a starter GGUF, writes a tuned config, and smoke-launches it.
What was scanned
The files the safety scan read, as written by the repository's author and shown as plain text. Lines with a finding are marked.
.claude-plugin/marketplace.json · Manifest · 20 lines
View this file on GitHub (read at the repository's current version: the scan did not record which commit it read)
This file has changed since it was scanned, so this is not exactly the text that was scanned, and no line is marked. The findings are listed with the safety scan above.
- {
- "name": "llamastash",
- "owner": {
- "name": "Deepu K Sasidharan",
- "email": "d4udts@gmail.com"
- },
- "metadata": {
- "description": "Control local llama.cpp-backed models through the LlamaStash CLI",
- "version": "0.0.1-beta.0"
- },
- "plugins": [
- {
- "name": "llamastash",
- "description": "Control local llama.cpp-backed models through the LlamaStash CLI. Use when an agent needs to install or initialize LlamaStash, list models, start or stop a model, inspect daemon or proxy health, pull GGUFs from HuggingFace, or obtain the local OpenAI-compatible proxy address for harnesses like Claude Code, OpenClaw, OpenCode, Pi, and other shell-capable AgentSkills clients.",
- "source": "./",
- "strict": false,
- "skills": ["./skills/llamastash"]
- }
- ]
- }
README.md · README · 495 lines
View this file on GitHub (read at the repository's current version: the scan did not record which commit it read)
This file has changed since it was scanned, so this is not exactly the text that was scanned, and no line is marked. The findings are listed with the safety scan above.
- # LlamaStash
- **Zero-overhead, terminal-native local-LLM orchestrator. Run any engine, any model via the same proxy.**
- <p align="center">
- <img src="https://raw.githubusercontent.com/llamastash/llamastash/main/assets/logo-h.jpg" alt="Logo" width="50%">
- </p>
- 
- 
- [](https://crates.io/crates/llamastash)
- [](https://crates.io/crates/llamastash)
- [](https://github.com/llamastash/llamastash/releases)
- [](https://github.com/llamastash/llamastash/releases)
- 
- 
- [](https://coveralls.io/github/llamastash/llamastash?branch=main)
- [](https://github.com/llamastash/llamastash)
- [](https://bsky.app/profile/deepu105.bsky.social)
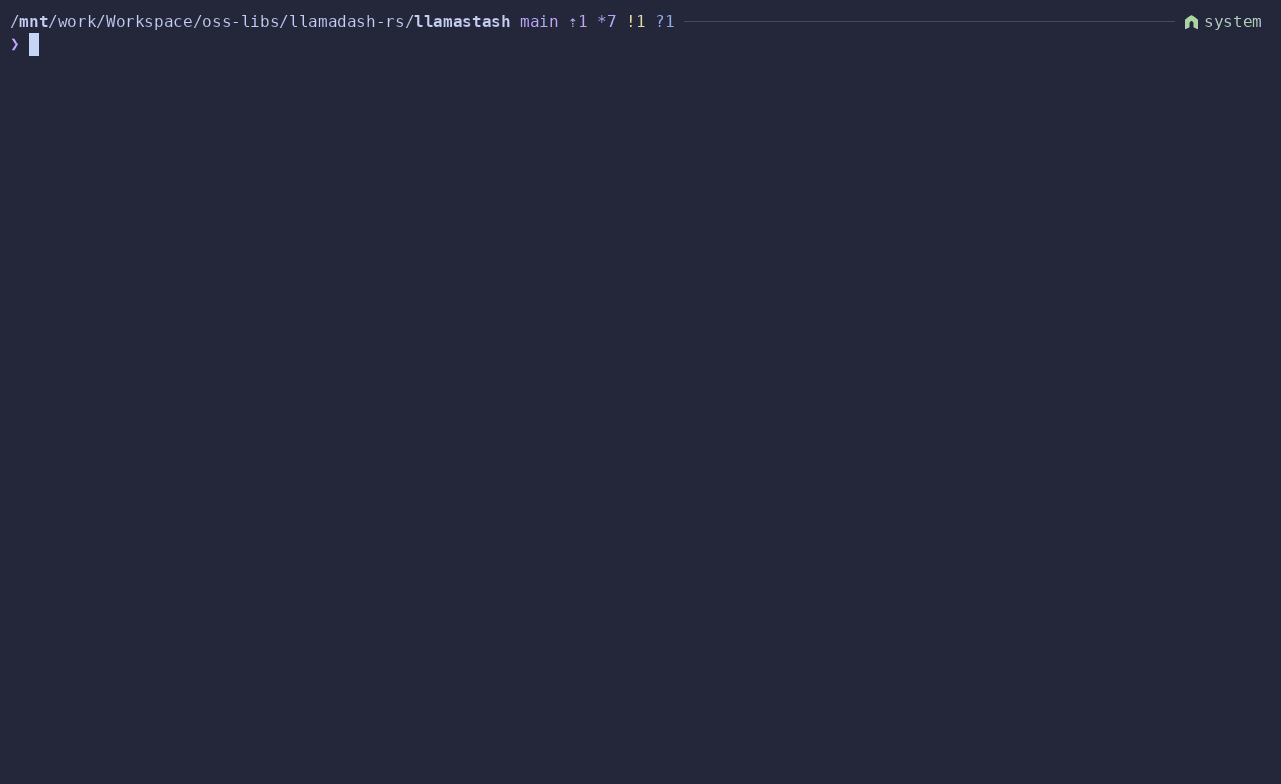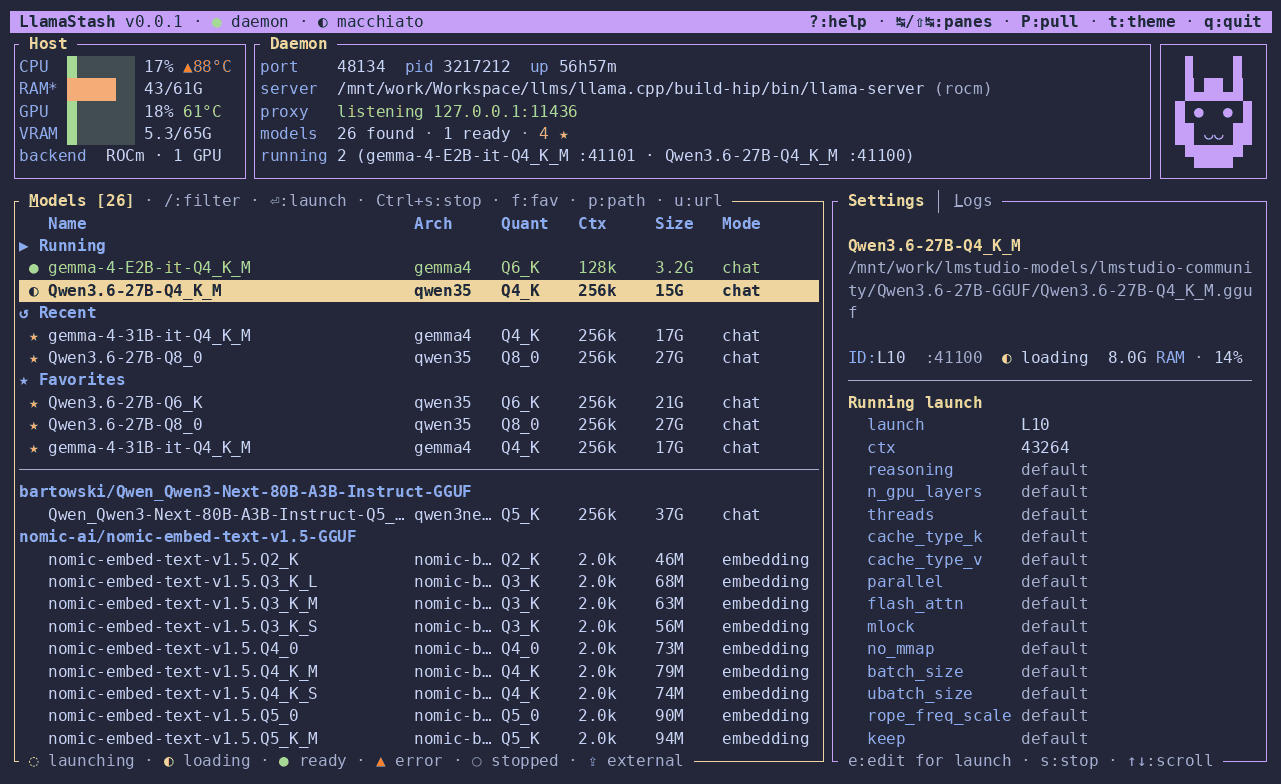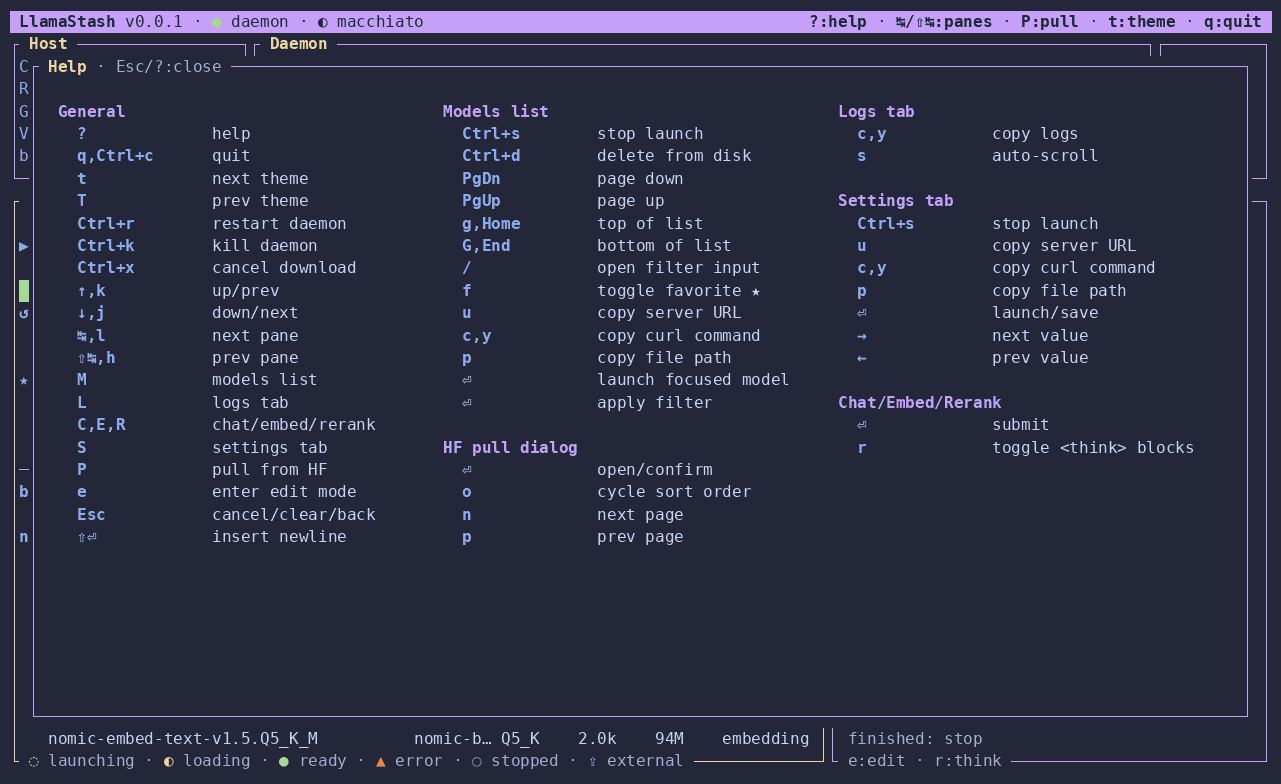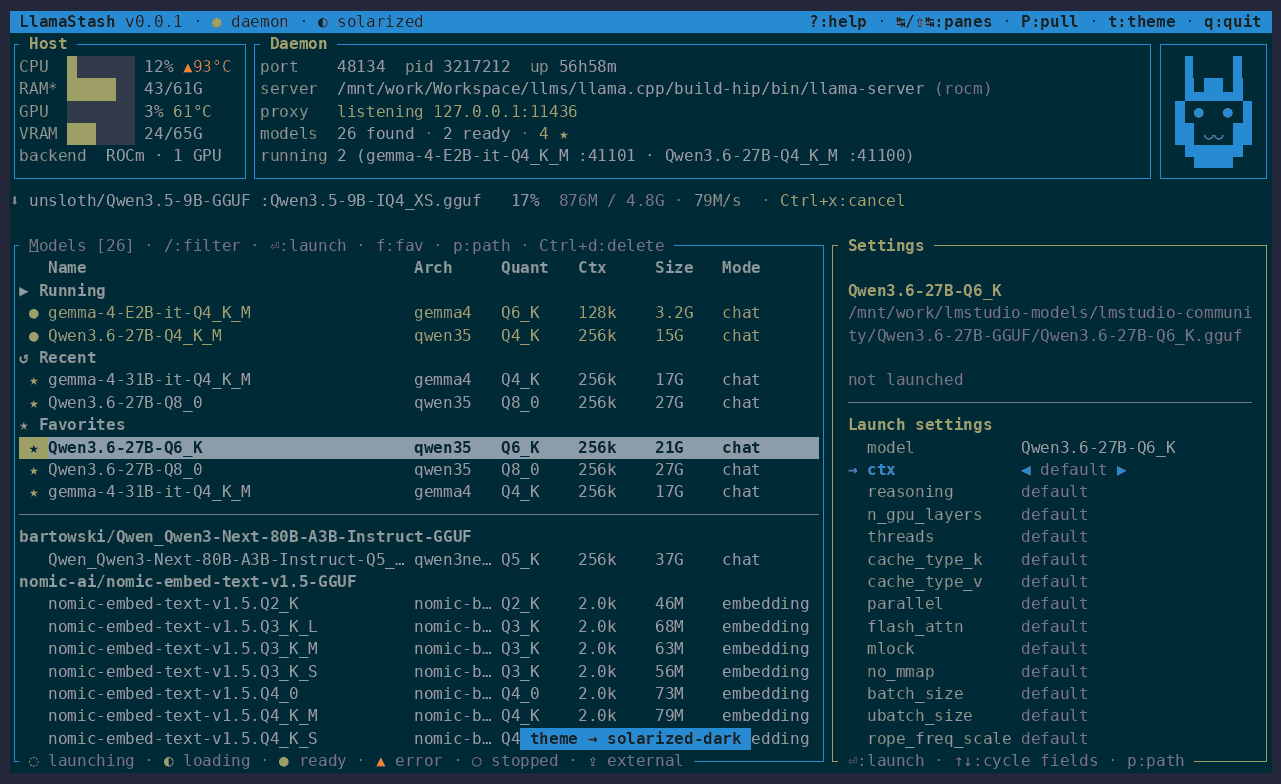
- A fast TUI **and** CLI with init wizard for running local LLMs. One Rust binary that's a TUI, a CLI, a daemon, and an OpenAI-compatible proxy. Bring any model and any engine: [llama.cpp](https://github.com/ggml-org/llama.cpp) for GGUFs with zero overhead vs raw `llama-server`, [vLLM](https://github.com/vllm-project/vllm) and [SGLang](https://github.com/sgl-project/sglang) for safetensors, and a generic backend that runs any other OpenAI-compatible server you declare in config, such as [Lemonade](https://github.com/lemonade-sdk/lemonade) and [FastFlowLM](https://github.com/FastFlowLM/FastFlowLM) on the NPU, [ds4](https://github.com/antirez/ds4) for DeepSeek-V4, gufo, Halogen and whisper.cpp. You don't learn each engine's flags, ports and quirks: LlamaStash manages them all the same way, behind one proxy URL and one TUI, CLI and agent surface. See [Engines](#engines).
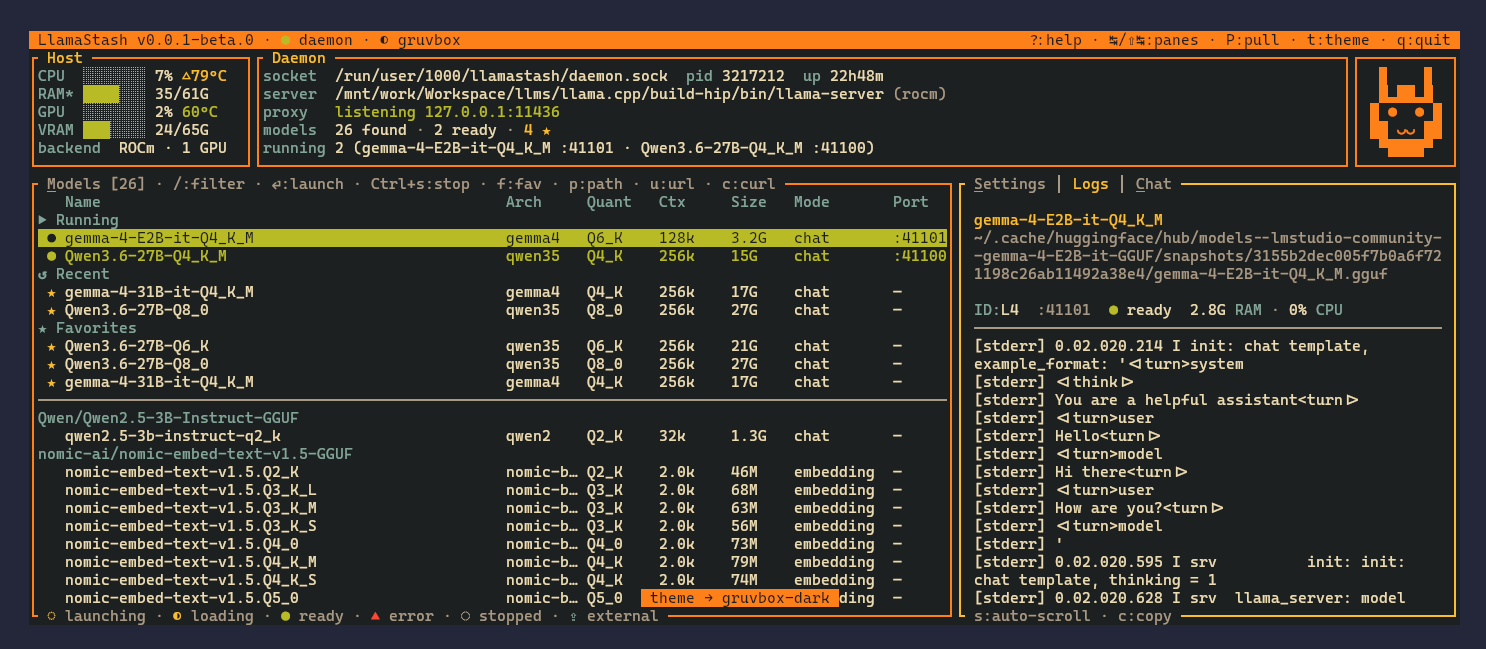
- 
- 
- ## Contents
- - [Why](#why)
- - [Install](#install)
- - [Quickstart](#quickstart)
- - [Engines](#engines)
- - [Agent Skills](#agent-skills)
- - [Features](#features)
- - [Benchmarks](#benchmarks)
- - [Screenshots](#screenshots)
- - [Configuration](#configuration)
- - [CLI exit codes](#cli-exit-codes)
- - [Platforms](#platforms)
- - [Roadmap](#roadmap)
- - [Contributing](#contributing)
- ## Why
- Heavy abstractions (Ollama, LM Studio) hide the engine and tie you to the engines they bundle; running `llama-server`, `vllm serve` or any other engine by hand is tedious. LlamaStash is a fast, transparent orchestrator that runs whichever engine fits each model, and it is also a first-class shell-tool surface for agents — one binary, daemon on demand, same primitives in the TUI and the CLI.
- > **AI agents installing this for a user:** jump to [`INSTALL.md` § For AI agents](INSTALL.md#for-ai-agents). The non-interactive install + verify contract, and exit-code branching live there.
- ## Install
- Pick whichever channel you prefer — all install the same binary. Full per-platform notes, troubleshooting, and the agent-friendly non-interactive path live in [`INSTALL.md`](INSTALL.md).
- ```bash
- # macOS + Linux, one-shot
- curl -fsSL https://llamastash.dev/install.sh | sh
- # Windows 11 (PowerShell, no admin elevation)
- irm https://llamastash.dev/install.ps1 | iex
- # Homebrew (macOS + Linuxbrew)
- brew install llamastash/llamastash/llamastash
- # Arch Linux (AUR — pick one)
- yay -S llamastash # source build
- # From crates.io (any platform with a Rust toolchain)
- cargo install llamastash
- # Windows via Scoop bucket
- scoop bucket add llamastash https://github.com/llamastash/scoop-llamastash && scoop install llamastash
- ```
- _Windows: 64-bit Windows 10 1809+ / Windows 11, PowerShell 5.1+, [Windows Terminal](https://aka.ms/terminal) recommended for the TUI; the bundled `llama-server` needs the VC++ 2015–2022 Redistributable (x64). See [INSTALL.md](INSTALL.md#platform-notes)._
- Then run `llamastash init` — the interactive wizard installs `llama-server` for your hardware, downloads a starter GGUF, writes a tuned config, and smoke-launches it.
- ## Quickstart
- ```bash
- # Open the TUI. Scans default caches; daemon auto-spawns on demand.
- llamastash
- # List discovered models. TTY → padded + table; piped or
- # `--no-colors` → TSV bytes. `--json` is the agent contract.
- llamastash list
- llamastash list --json | jq
- # Launch a model by name, name substring, path, or canonical id.
- llamastash start qwen-coder --ctx 16384 --reasoning on
- # `run` is an alias for `start`, and the positional takes a YAML
- # launch file: one model, its presets, nothing saved to config.yaml.
- llamastash run qwen-coder.yml
- # Drive a smoke-test request against the running endpoint.
- curl -s http://127.0.0.1:41100/v1/chat/completions \
- -H 'Content-Type: application/json' \
- -d '{"model": "qwen-coder", "messages": [{"role": "user", "content": "hi"}]}'
- # Stop it.
- llamastash stop qwen-coder
- ```
- **Tip — mouse focus.** Mouse capture is off by default so the terminal keeps native click-and-drag text selection. To opt in on every TUI run, alias the binary in your shell rc:
- ```bash
- # bash / zsh
- alias llamastash='llamastash --mouse-focus'
- # fish
- alias llamastash 'llamastash --mouse-focus'
- ```
- Or set it permanently in `config.yaml`:
- ```yaml
- mouse_focus: true
- ```
- Either source flips on click-to-focus for the Models list, the right pane, and the tab labels (`Settings`/`Logs`/`Chat`/`Embed`/`Rerank`). Most terminals still expose a bypass modifier (Shift on iTerm2 / Alacritty / foot / wezterm, Option on Apple Terminal) so ad-hoc selection stays reachable.
- **Tip — shell completions.** `llamastash completions <shell>` prints a completion script for bash, zsh, fish, PowerShell or Elvish. Subcommands, flags and fixed value lists complete; model names do not. Install it once:
- ```bash
- # bash
- mkdir -p ~/.local/share/bash-completion/completions
- llamastash completions bash > ~/.local/share/bash-completion/completions/llamastash
- # zsh — put `fpath+=(~/.zsh/completions)` above `compinit` in ~/.zshrc
- mkdir -p ~/.zsh/completions
- llamastash completions zsh > ~/.zsh/completions/_llamastash
- # fish
- llamastash completions fish > ~/.config/fish/completions/llamastash.fish
- ```
- Full subcommand reference: [`docs/usage.md`](docs/usage.md). Proxy client setup (including an OpenCode example): [`docs/usage.md#opencode-setup`](docs/usage.md#opencode-setup). Tested configs for llama.cpp builds, vLLM, SGLang, gufo, Halogen, ds4, Lemonade, FastFlowLM and whisper.cpp, with model presets: [`RECIPES.md`](RECIPES.md). Architecture and IPC contract: [`docs/architecture.md`](docs/architecture.md). When things go wrong: [`docs/troubleshooting.md`](docs/troubleshooting.md).
- ## Engines
- Any model, any engine, one proxy URL. Every launch gets the same treatment whatever runs it: a reserved port, a readiness probe, the admission gate, proxy routing, the same `start` / `stop` / `status` / `--json` commands, and a row in the TUI. You install the engines you want and LlamaStash drives them. The one exception is `llama-server`, which `llamastash init` can install for you.
- | Engine | Runs | Status | Turn it on |
- | ------------------------------------ | ----------------------------- | --------------- | --------------------------------------------------- |
- | [llama.cpp](#llamacpp-default) | any GGUF | stable, default | built in; `llamastash init` installs `llama-server` |
- | [Generic](#generic-bring-any-engine) | any OpenAI-compatible server, e.g. Lemonade, FastFlowLM, ds4, gufo, whisper.cpp | stable | a `backend.generic.servers` entry in `config.yaml` |
- | [vLLM](#vllm-experimental) | safetensors HuggingFace repos | experimental | on when a `vllm` launcher resolves |
- | [SGLang](#sglang-experimental) | safetensors HuggingFace repos | experimental | on when a `sglang` launcher resolves |
- ### llama.cpp (default)
- - **Unmodified upstream `llama-server`, no measured overhead** against running it by hand (see [Benchmarks](#benchmarks)). Every GGUF binds to it by default.
- - **Several builds side by side.** List a ROCm, a Vulkan and a CPU build under `backend.llamacpp.servers` and each one is a server you pick per launch or per preset. Recipe: [llama.cpp builds](RECIPES.md#llamacpp-builds).
- - Arch defaults, context auto-fit, MTP, mmproj pairing and device selection are listed under [Features](#features).
- ### Generic: bring any engine
- If an engine speaks the OpenAI API, LlamaStash can run it. A `backend.generic.servers` entry declares the binary (or a wrapper script around `docker run`), its args with `{port}` / `{model}` placeholders, its readiness path, its stop grace and its own knobs. LlamaStash supervises it, admission-gates it and routes the proxy to it like a llama.cpp launch. No Rust code and no LlamaStash release needed.
- ```yaml
- backend:
- generic:
- servers:
- - name: gufo # server id: generic-gufo
- model: Qwen3.8-Flash-Next-UD-Q4_K_XL # catalog GGUF(s) it runs; globs work
- binary: /path/to/gufo/build/release/gufo
- args:
- [
- serve,
- --host,
- "{host}",
- --port,
- "{port}",
- llm,
- --served-model-name,
- "{name}",
- --model,
- "{model}",
- ]
- knobs:
- - { flag: --context, ctx: true, default: "131072" }
- - --seed
- ready: /ready
- stop_grace_secs: 60
- rewrite_model: true # gufo answers only to {name}
- ```
- - **Run a GGUF through another engine.** An entry with `model:` becomes a server option on the matching catalog rows, next to llama.cpp, in the TUI Server row, `--server` and presets. Its knobs show up in the launch editor, presets and last-used like any other.
- - **Or serve models LlamaStash can't see.** An entry without `model:` is its own row, for engines with their own weight format. `rows_from` asks the engine for its installed models and lists one row per model.
- - **Tested engines**, each with a working config in [`RECIPES.md`](RECIPES.md):
- | Engine | Use it for | Recipe |
- | --------------------------------------------------------------- | ----------------------------------------------------------------------------------- | -------------------------------------------------- |
- | [Lemonade](https://github.com/lemonade-sdk/lemonade) (`lemond`) | NPU and multi-engine inference behind one server | [Lemonade](RECIPES.md#lemonade) |
- | [FastFlowLM](https://github.com/FastFlowLM/FastFlowLM) (`flm`) | LLMs and Whisper on the AMD XDNA2 NPU | [FastFlowLM](RECIPES.md#fastflowlm-amd-npu) |
- | [ds4](https://github.com/antirez/ds4) (`ds4-server`) | DeepSeek-V4 Flash / PRO, with MTP, DSpark, SSD streaming and disk KV cache as knobs | [DeepSeek V4](RECIPES.md#deepseek-v4) |
- | Strata, Halogen (Docker), gufo, CIRU | Qwen3.8 Flash-Next | [Strata](RECIPES.md#strata), [Halogen](RECIPES.md#halogen), [gufo](RECIPES.md#gufo), [CIRU](RECIPES.md#ciru) |
- | whisper.cpp | speech to text | [whisper.cpp](RECIPES.md#whispercpp) |
- Field reference: [`docs/usage.md` § Generic backend](docs/usage.md#generic-backend). ds4 and Lemonade used to be dedicated backends; a generic entry now does the same job with the same argv and speed ([why](docs/plans/2026-10-17-002-refactor-drop-lemonade-backend-plan.md)).
- ### vLLM (experimental)
- - **⚠️ Experimental**: tested with vLLM 0.27.1; behaviour and config may change.
- - **The non-GGUF half of your cache.** Safetensors repos in `~/.cache/huggingface` appear in the catalog and launch through `vllm serve`. A GGUF still binds llama.cpp; vLLM claims safetensors repos only.
- - **Default-on when a `vllm` launcher resolves** (PATH or `backend.vllm.servers`); force with `--vllm` / `LLAMASTASH_VLLM=1`, opt out with `backend.vllm.enabled: false`. Zero footprint when absent. On ROCm, where vLLM ships only as a container, point the config at a small wrapper script: see **[vLLM setup](docs/vllm-setup.md)**.
- - **Nine native knobs** (`--kv-cache-memory-bytes`, `--gpu-memory-utilization`, `--tensor-parallel-size`, `--dtype`, `--kv-cache-dtype`, `--quantization`, `--max-num-seqs`, `--enforce-eager`, `--trust-remote-code`) in the launch picker and presets; `--ctx` maps to `--max-model-len`.
- ### SGLang (experimental)
- - **⚠️ Experimental**: tested with SGLang 0.5.18; behaviour and config may change.
- - **The same rows vLLM serves.** Safetensors repos launch through `sglang serve`; a GGUF still binds llama.cpp. With both engines installed a repo lists both and `auto` picks vLLM; `--backend sglang` selects SGLang.
- - **Default-on when a `sglang` launcher resolves** (PATH or `backend.sglang.servers`); force with `--sglang` / `LLAMASTASH_SGLANG=1`, opt out with `backend.sglang.enabled: false`. Zero footprint when absent. Setup: **[SGLang setup](docs/sglang-setup.md)**.
- - **A token cap, not a byte cap, on unified-memory hosts.** SGLang's only fixed bound on its KV pool is `--max-total-tokens`, so the launcher divides the shared byte budget by the model's KV bytes per token, read from `config.json`. Eight native knobs in the launch picker and presets; `--ctx` maps to `--context-length`.
- ## Agent Skills
- The CLI ships with an [Agent Skills](https://agentskills.io) manifest so supported agents can load repo-specific instructions for using `llamastash` as a local model-management CLI.
- - Canonical skill bundle: [`skills/llamastash/`](https://github.com/llamastash/llamastash/tree/main/skills/llamastash)
- **Any supported agent (recommended):** install the bundled skill with the [Agent Skills](https://agentskills.io) CLI. It auto-detects your harness and writes the bundle to the right path:
- ```bash
- npx skills add llamastash/llamastash
- ```
- **Claude Code plugin marketplace:** install the repo as a plugin, then install the bundled skill:
- ```text
- /plugin marketplace add llamastash/llamastash
- /plugin install llamastash@llamastash
- /reload-plugins
- ```
- Manual install examples:
- ```bash
- # OpenClaw
- mkdir -p ~/.openclaw/skills && cp -r skills/llamastash ~/.openclaw/skills/
- # OpenCode
- mkdir -p ~/.config/opencode/skills && cp -r skills/llamastash ~/.config/opencode/skills/
- ```
- The skill teaches agents to prefer `--json`, branch on LlamaStash's documented exit codes, reuse exact discovered model names, and read `status --json` `proxy.listen` before configuring an OpenAI-compatible client.
- ## Features
- Full detail per feature in [`FEATURES.md`](FEATURES.md) — including trade-offs, contracts, and links into [`docs/usage.md`](docs/usage.md).
- ### [Zero-to-chat in one command](FEATURES.md#zero-to-chat-in-one-command)
- - [`llamastash init` — first-run wizard](FEATURES.md#llamastash-init--first-run-wizard) that detects hardware, installs `llama-server`, picks + downloads a starter GGUF, writes a tuned config, and smoke-launches.
- - [Hardware-aware model recommender](FEATURES.md#hardware-aware-model-recommender) with a VRAM-fit filter + composite ranking over a CI-refreshed benchmark snapshot.
- - [`llamastash doctor`](FEATURES.md#llamastash-doctor--read-only-health-check) — typed, agent-branchable findings; always exits `0`.
- ### [Discovers what you already have](FEATURES.md#discovers-what-you-already-have)
- - [Auto-scans HuggingFace, Ollama, and LM Studio caches](FEATURES.md#auto-scans-huggingface-ollama-and-lm-studio-caches), plus user paths.
- - [Rich GGUF intelligence](FEATURES.md#rich-gguf-intelligence) — architecture, params, quant, native context, chat template, KV-cache-aware memory estimates.
- - [Multimodal projector detection](FEATURES.md#multimodal-projector-detection) — auto-pairs an mmproj GGUF beside a model, loads it with `--mmproj`, flags vision (`◉`) / audio (`♪`) in the TUI.
- - [MTP speculative decoding](docs/usage.md#mtp-speculative-decoding) — auto-detects MTP-capable GGUFs (embedded or separate `mtp-*.gguf` head) and enables `--spec-type draft-mtp` by default for ~2x decode with no quality loss; `--mtp auto\|on\|off`, a `↯` TUI badge, live draft-acceptance in `status`. `pull` fetches the mmproj / MTP-head companions too.
- - [Smart deduplication](FEATURES.md#smart-deduplication) — symlinks collapsed, split GGUFs unified, Ollama blobs named.
- - [Live filesystem watching](FEATURES.md#live-filesystem-watching) — new GGUFs appear without a restart.
- ### [Launches anything, supervises everything](FEATURES.md#launches-anything-supervises-everything)
- - [Daemon-on-demand](FEATURES.md#daemon-on-demand) — one binary as TUI + CLI + daemon; running models survive TUI close.
- - [Multi-model concurrency](FEATURES.md#multi-model-concurrency) — per-model port from a configurable range, `/health`-probed state machine.
- - [GPU-aware built-in arch defaults](FEATURES.md#gpu-aware-built-in-arch-defaults) — sensible flags per `(architecture, gpu_backend)` with zero YAML.
- - [Intelligent context auto-fit](FEATURES.md#intelligent-context-auto-fit) — when `ctx` is unset, llamastash picks the largest context that fits free VRAM (or RAM, CPU-only) from the GGUF attention geometry. Sidesteps llama.cpp `--fit`'s 4096 collapse on Linux 7+ iGPUs (AMD Strix Halo) where unified-memory free space is mis-reported.
- - [Typed launch-knob editor](FEATURES.md#typed-launch-knob-editor) with `(source)` chips and a layered preset → last-params → arch-defaults → built-ins resolver.
- - [Multi-GPU device selection](FEATURES.md#typed-launch-knob-editor) — pin a model to one card (`--device`) instead of letting llama.cpp split it across every GPU; the picker lists exactly what `llama-server --list-devices` reports.
- - [Named presets, favorites, last-params recall](FEATURES.md#named-presets-favorites-last-params-recall) — presets live in `config.yaml` (per-model or per-arch), edited from the CLI, the TUI `Ctrl+P` save dialog, or by hand; a preset cycle row in the Settings form picks one in a keystroke.
- ### [A TUI that doesn't get in your way](FEATURES.md#a-tui-that-doesnt-get-in-your-way)
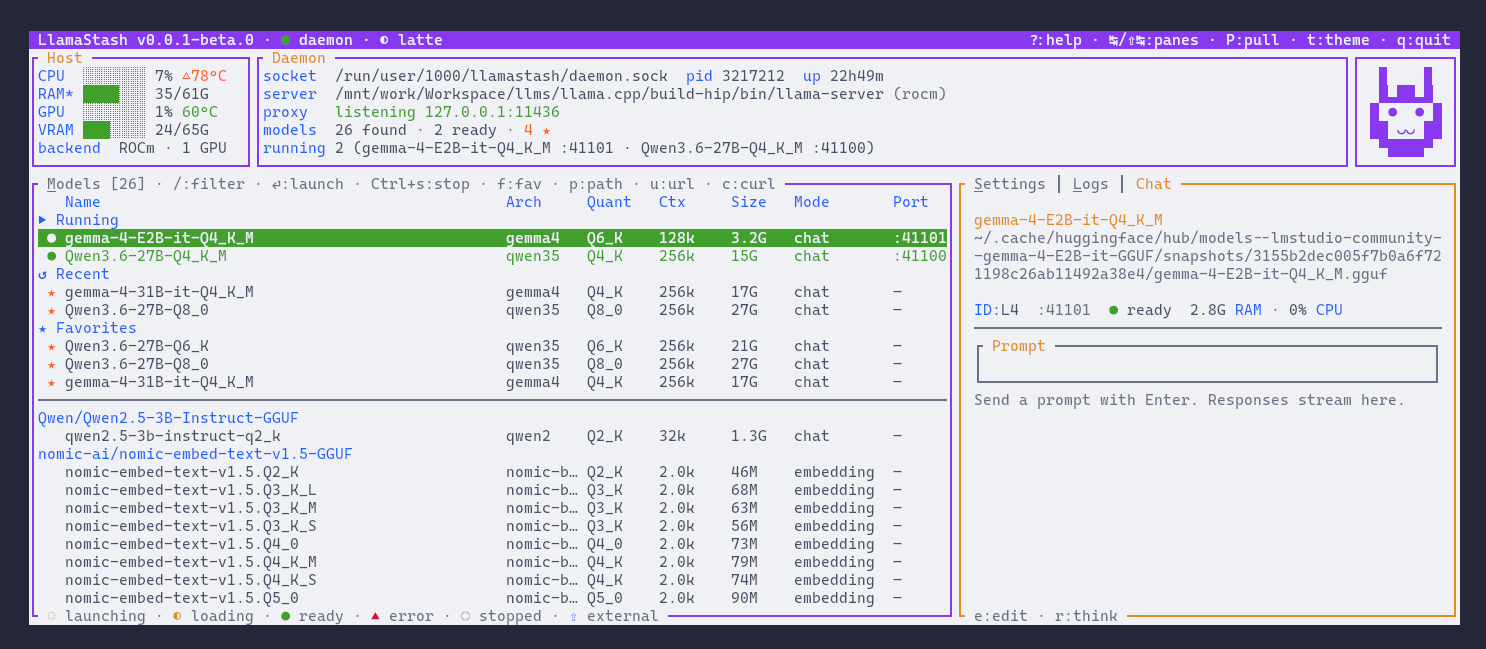
- - [Keyboard-driven everywhere](FEATURES.md#keyboard-driven-everywhere) — vim-style `hjkl` + `Ctrl+F`/`Ctrl+B` paging, `0`/`$` top/bottom, `gt`/`gT` tab cycling; `/` filter, `u`/`c`/`p` yank, `?` help.
- - [Right pane is your smoke test](FEATURES.md#right-pane-is-your-smoke-test) — Logs / Chat / Embed / Rerank over the same OpenAI-compatible endpoints external clients use.
- - [In-TUI HuggingFace browser](FEATURES.md#in-tui-huggingface-browser) — search, sort, paginate, per-file hardware fit, download strip with cancel.
- - [Theming and rebinding](FEATURES.md#theming-and-rebinding) — five themes + custom palette; every action rebindable.
- - [Accessible by default](FEATURES.md#accessible-by-default) — dual-encoded status (color + glyph), readable on mono terminals.
- - [Adaptive layout — works from 60 cells up](FEATURES.md#adaptive-layout--works-from-60-cells-up) — below 100 cells the right pane goes drill-in-only; list columns and hint chips drop by priority rank as the pane shrinks so the model name stays readable.
- ### [First-class CLI for agents and scripts](FEATURES.md#first-class-cli-for-agents-and-scripts)
- - [Subcommands cover every TUI capability](FEATURES.md#subcommands-cover-every-tui-capability) with `--json` as the stable agent contract.
- - [Documented exit codes per failure class](FEATURES.md#documented-exit-codes-per-failure-class) — pin numbers, not message text.
- - [Colored TTY output, byte-stable TSV when piped](FEATURES.md#colored-tty-output-byte-stable-tsv-when-piped) — existing `awk` / `column` pipelines keep working.
- - [`llamastash pull <hf-repo>`](FEATURES.md#llamastash-pull-hf-repo--standalone-hf-fetch) — same primitive as the wizard, with disk-space prechecks.
- - [`llamastash recommend`](FEATURES.md#llamastash-recommend--hardware-aware-picks-in-your-shell) — the recommender on its own, agent-friendly.
- - [`llamastash integrations`](FEATURES.md#llamastash-integrations--point-your-ai-tools-at-the-proxy) — point OpenCode, Aider, Continue.dev, Zed, pi.dev or Codex CLI at the proxy, with your favorites registered and effort pickers wired for reasoning models.
- - [`llamastash session <tool> [model]`](docs/usage.md#llamastash-session-tool-model) — launch Claude Code, Codex, OpenCode, pi or Aider at one model for that run only, through env vars, flags or a per-run file, so no tool config is written.
- - [Reproducible pulls via `--revision <SHA>`](FEATURES.md#reproducible-pulls-via---revision-sha).
- ### [Drop-in OpenAI + Ollama proxy](FEATURES.md#drop-in-openai--ollama-proxy)
- - [OpenAI-compatible endpoint](FEATURES.md#openai-compatible-endpoint) at `http://127.0.0.1:11435/v1` by default (or the next free port up to `11440`) — drives every discovered model through one URL; OpenCode, Pi (pi.dev), Cline, llm-cli, the OpenAI SDKs all work as-is. Auto-starts the requested model; falls back to a Ready peer with audit headers (`x-llamastash-served-by`, `x-llamastash-fallback-reason`) when launch fails. The default port is `11435` (one above Ollama's well-known `11434`) so a llamastash daemon and an Ollama install can co-exist without a port collision.
- - [Anthropic Messages API](FEATURES.md#anthropic-messages-api-claude-code) on the same proxy — `/v1/messages` + `/v1/messages/count_tokens` forward to llama-server's native endpoints, so Claude Code and the Anthropic SDK attach via `ANTHROPIC_BASE_URL` (key sent as `x-api-key`). `llamastash init`'s **Claude Code** integration drops a sourceable `claude-code.sh` so you opt in per-shell (`source claude-code.sh && claude`) without hijacking its global config. Tool calling works out of the box (`--jinja` on by default).
- - [Browser web UI](FEATURES.md#browser-web-ui) at `http://127.0.0.1:11435/ui/` — opens the running model's stock llama.cpp web UI through the proxy on one port-stable origin, so you never chase the ephemeral backend port. A chooser (plus `/ui/switch`) handles several running models; reachable over LAN behind the same key via a browser Basic-auth prompt.
- - [Ollama discovery surface](FEATURES.md#ollama-discovery-surface) — `GET /api/tags` / `/api/version` / `/api/ps`, `POST /api/show` so tools that auto-detect Ollama via `OLLAMA_HOST` recognise llamastash and fall through to the OpenAI-compat endpoints for inference.
- - **Ollama drop-in mode is opt-in.** Enable with `--ollama-compat` (or `proxy.ollama_compat: true` / `LLAMASTASH_OLLAMA_COMPAT=1`) and the proxy claims port `11434`, answers `GET /` with the byte-exact `"Ollama is running"` handshake string, and works as a transparent replacement for the official `ollama` CLI and other Ollama-Go-based clients. Leaving compat off keeps the safe coexistence default (port `11435`, `"LlamaStash is running"` identity).
- - [Loopback by default, opt-in LAN with auth](FEATURES.md#auth-posture) — the proxy binds `127.0.0.1` and runs keyless for the same-machine threat model. Expose it on the LAN with `--proxy-host 0.0.0.0` (or `proxy.host`) and llamastash auto-generates a bearer key, requires it on every request, and refuses to bind a routable address with no key unless you pass `--insecure-no-auth`. TLS is on the roadmap; LAN mode is plaintext for now (trusted network or front with a reverse proxy). The control plane and `llama-server` children always stay loopback.
- ### [Built to be safe to run](FEATURES.md#built-to-be-safe-to-run)
- - [Bearer-token loopback control plane (`runtime.json` `0600`)](FEATURES.md#bearer-token-control-plane) — the per-daemon token + URL live in `$XDG_STATE_HOME/llamastash/runtime.json`; same-UID trust, no network exposure.
- - [Hardened fetch substrate](FEATURES.md#hardened-fetch-substrate) — HTTPS-only, host allowlist, redirect/body-size caps, IP-literal refusal.
- - [Archive-bomb defenses on installers](FEATURES.md#archive-bomb-defenses-on-installers) — entry/size/ratio caps; SHA-256 verified before extract.
- - [Atomic, mode-checked config + state writes](FEATURES.md#atomic-mode-checked-config--state-writes) — `0600` final mode; corrupt state quarantined, not fatal.
- - [Side-by-side daemons](FEATURES.md#side-by-side-daemons) — isolated instances via `LLAMASTASH_*_DIR` (state / config / cache); each daemon publishes its own `runtime.json`.
- _**Note**: This is beta software. Rough edges are to be expected. Windows and macOS support is not as well-tested as Linux; Same goes for non-AMD GPUs. Please report issues if you hit them. The `llama-server` builds are unmodified upstream binaries; any bugs in them are out of scope for LlamaStash._
- ## Benchmarks
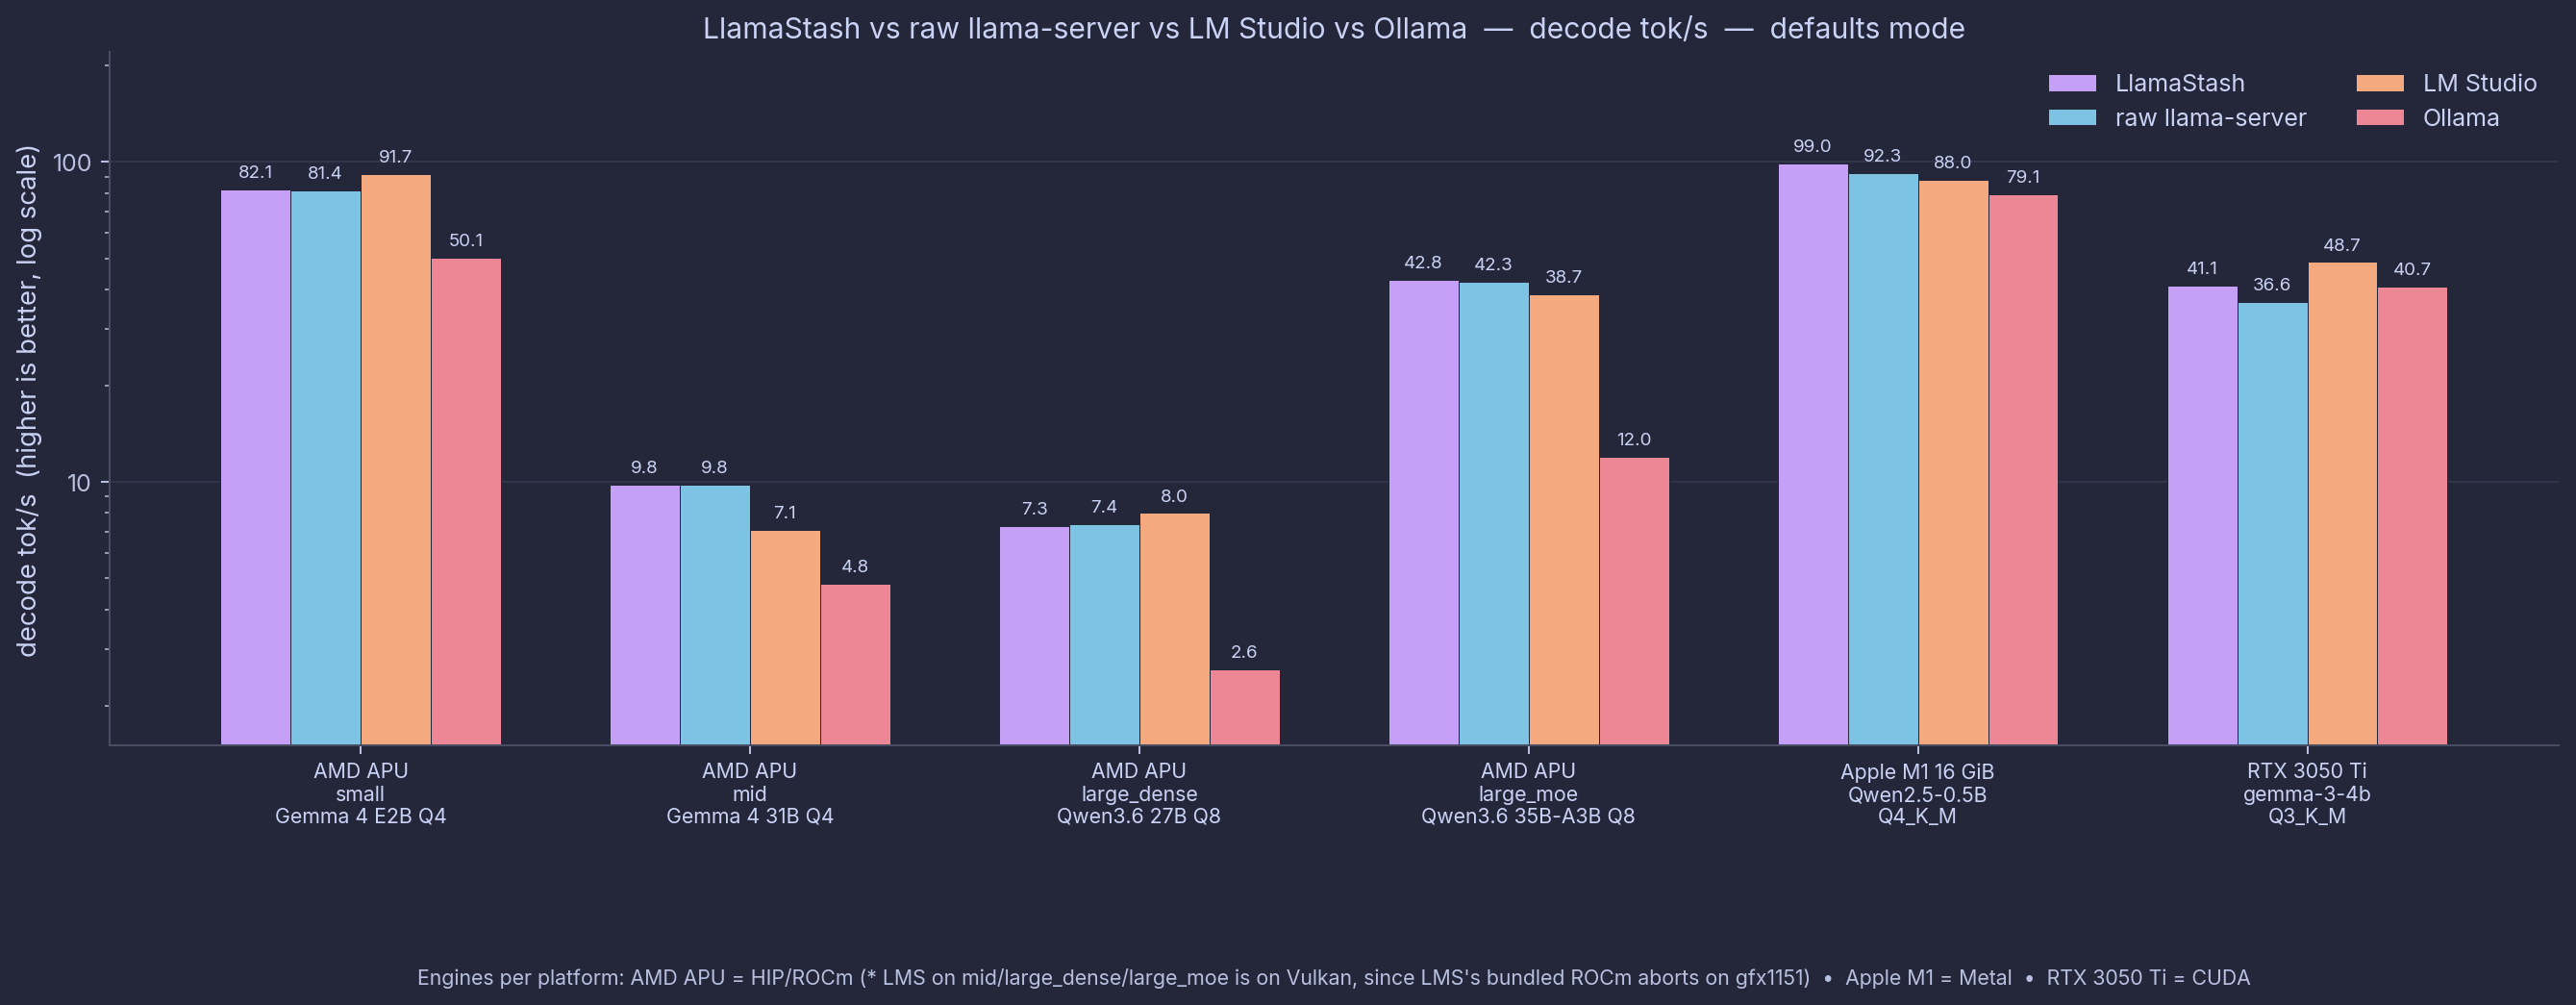
- LlamaStash spawns the unmodified upstream `llama-server`. Three suites track what that means in practice — **Suite A** asserts the wrapper adds no measurable overhead vs raw `llama-server`, **Suite B** compares LlamaStash-as-shipped against Ollama + LM Studio on the same hardware through their OpenAI-compatible endpoints, **Suite C** measures the proxy hop vs hitting `llama-server` directly (TTFT p50 +0.45 ms, decode unchanged). Full write-up + per-workload tables: [`docs/benchmarks.md`](docs/benchmarks.md).
- Each cell below is **decode tok/s / TTFT ms** on the `chat_turn` workload (50-token prompt → 64 tokens decode). LlamaStash matches raw `llama-server` within ≤1% in normalized mode on every platform. Re-run on your hardware: `make bench-end-to-end` (Suite B) or `make bench-overhead` (Suite A).
- 
- ### AMD APU - Linux (Ryzen AI Max+ 395 / Radeon 8060S 128GB unified, system ROCm 7.2.3, llama.cpp build `b9440 (e6123e208)`)
- `chat_turn` `normalized` mode, decode tok/s / TTFT ms. One bench JSON per row (no averaging).
- | Tool | small (E2B Q4) | mid (31B Q4) | large_dense (27B Q8) | large_moe (35B-A3B Q8) | Engine notes |
- | ------------------ | -------------: | ------------: | -------------------: | ---------------------: | -------------------------------------- |
- | **LlamaStash** | **82.1 / 51** | **9.9 / 468** | **7.5 / 406** | **42.3 / 178** | local HIP/ROCm |
- | raw `llama-server` | 81.0 / 51 | 9.9 / 466 | 7.5 / 406 | 43.1 / 185 | local HIP/ROCm |
- | LM Studio 2.18.0 | 91.1 / 187 | — (crash¹) | — (crash¹) | — (crash¹) | bundled ROCm 6.4 vendor (see footnote) |
- | Ollama 0.24.0 | 50.8 / 224 | 4.8 / 1096 | 2.6 / 1750 | 12.2 / 484 | bundled |
- ¹ LM Studio's bundled ROCm vendor libraries (v6.4) abort in `ggml_cuda_error` during backend init on `gfx1151` (Strix Halo) across all LMS-shipped runtimes. System ROCm 7.2.3 loads the same models cleanly via raw `llama-server`, so this is an LMS vendor-bundle limitation. LMS Vulkan numbers are in the [benchmark blog](https://deepu.tech/benchmarking-llamastash) and in the [final report](https://github.com/llamastash/llamastash/blob/main/docs/benchmarks/linux-amd-apu-final-report.md).
- #### AMD APU — Vulkan addendum (LlamaStash vs LM Studio, 2026-06-01)
- | Tool | small (E2B Q4) | mid (31B Q4) | large_dense (27B Q8) | large_moe (35B-A3B Q8) |
- | ---------------- | -------------: | -------------: | -------------------: | ---------------------: |
- | **LlamaStash** | **101.2 / 55** | **10.8 / 671** | 7.5 / 196 | **50.7 / 72** |
- | LM Studio 2.18.0 | 93.6 / 191 | 7.1 / 2307 | **8.0 / 801** | 38.4 / 227 |
- Same backend (Vulkan b9440 / `vulkan-avx2@2.18.0`), same GGUF bytes. raw `llama-server` and Ollama omitted: the wrapper-overhead claim already covered by the HIP table; Ollama mainline has no Vulkan support.
- ### NVIDIA - Linux (RTX 3050 Ti, 4 GiB VRAM, llama.cpp build `b9360`)
- | Tool | CUDA (gemma-3-4b Q3 `defaults`) | Vulkan (gemma-3-4b Q3 `defaults`) |
- | ------------------ | ------------------------------: | --------------------------------: |
- | **LlamaStash** | **41.1 / 74** ✦ | **42.0 / 113** |
- | raw `llama-server` | 36.6 / 110 | 37.5 / 148 |
- | LM Studio 2.16.0 | **48.7 / 318** | **48.3 / 308** |
- | Ollama 0.24.0 | 40.7 / 120 | 42.0 / 115 |
- ✦ LlamaStash leads raw `llama-server` in defaults mode (12–16% decode, 33–49% TTFT) via the hardware-aware defaults overlay; normalized mode: within ≤0.5 tok/s. Vulkan decode ≥ CUDA on this hardware in 26 of 28 cells (median +5%). Curated report with six findings: [`linux-nvidia-final.md`](https://github.com/llamastash/llamastash/blob/main/docs/benchmarks/linux-nvidia-final.md).
- ### Apple M1 - macOS (16 GB unified memory, Metal, llama.cpp build `9330 (328874d05)`)
- | Tool | small (Qwen2.5-0.5B Q4) |
- | ------------------ | ----------------------: |
- | **LlamaStash** | **95.6 / 18** ✦ |
- | raw `llama-server` | 91.9 / 20 |
- | LM Studio | 88.4 / 68 |
- | Ollama 0.24.0 | 79.6 / 102 |
- ✦ LlamaStash leads raw `llama-server` on M1 in `defaults` mode (99.0 vs 92.3 tok/s, 15 vs 19 ms TTFT) because its Metal defaults overlay injects hardware-optimal knobs at startup. Normalized mode: 92.2 vs 91.5 — within 1%. Curated report: [`macos-m1-final-report.md`](https://github.com/llamastash/llamastash/blob/main/docs/benchmarks/macos-m1-final-report.md).
- ## Screenshots
- 
- 
- ## Configuration
- LlamaStash reads `$XDG_CONFIG_HOME/llamastash/config.yaml` on Linux (fallback `~/.config/llamastash/config.yaml`), `~/Library/Application Support/llamastash/config.yaml` on macOS, and `%APPDATA%\llamastash\config\config.yaml` on Windows. A fully-annotated sample lives at [`config.example.yaml`](config.example.yaml) — copy it to the path above and edit. Run `llamastash config` to open the active file in `$EDITOR`, or `llamastash config bindings` to print every effective keybinding as YAML. The full schema reference is in [`docs/usage.md`](docs/usage.md#configuration).
- Quick tour of the top-level keys:
- | Key | What it controls |
- | ------------------------------ | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
- | `theme` | Built-in palette: `macchiato` (default), `latte`, `gruvbox-dark`, `solarized-dark`, `mono`. Set to `custom` to use the `custom_theme` block. Cycle live with `t:theme`. |
- | `custom_theme` | User-defined palette. Inherits unspecified slots from `base:` (default macchiato). Accepts `#RRGGBB` hex or ANSI names. Once defined, `Custom` joins the `t:theme` cycle. |
- | `model_paths` | Extra directories to scan for `.gguf` files. Merged with `-p/--model-path` and `LLAMASTASH_MODEL_PATHS`. |
- | `disable_default_cache_paths` | Per-bucket toggles (`huggingface`, `ollama`, `lm_studio`) for the auto-walked caches. |
- | `disable_scan` | Skip filesystem scanning entirely. Same as `--no-scan` / `LLAMASTASH_NO_SCAN=1`. |
- | `daemon.port_range` | Inclusive `{start, end}` TCP range the supervisor picks from. Default `41100..=41300`. |
- | `daemon.probe_timeout_secs` | Health-probe deadline per launch. Default `120`. Bump for 70B+ on slow disks. |
- | `daemon.idle_timeout_secs` | Shut the daemon down after N seconds with no running models and no client attached. Default `0` (never). |
- | `daemon.metrics_interval_secs` | Host-metrics sampler cadence. Default `1` (1 Hz), clamped to `1..=60`. Raise it to spawn `nvidia-smi` / `rocm-smi` less often. |
- | `gpu.enable_vulkan_probe` | Run the `vulkaninfo` fallback probe. Default `true`; `false` skips it when a native NVIDIA/AMD/Metal probe already covers your GPUs. |
- | `gpu.reprobe_interval_secs` | How often to re-run the full vendor probe chain for hotplug / late driver loads. Default `60`; `0` probes only at daemon start. |
- | `backend.llamacpp.servers` | llama.cpp build/binary variants (`[{binary, name?}]`), either `llama-server` or the unified `llama`. First = default; each is a selectable "server". `--llama-server` / `LLAMASTASH_LLAMA_SERVER` set the first. |
- | `keybindings` | Action-name → key-spec overrides. Kdash-style dialect (`ctrl+q`, `shift+tab`, `f1`, …). |
- Environment variables:
- | Variable | Purpose |
- | ------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
- | `LLAMASTASH_CONFIG` | Override config-file path |
- | `LLAMASTASH_LLAMA_SERVER` | Path to `llama-server` or the unified `llama` |
- | `LLAMASTASH_NO_SCAN` | Skip filesystem scanning |
- | `LLAMASTASH_IPC_URL` | Point a CLI/TUI at a non-default daemon control plane (verbatim URL, e.g. `http://127.0.0.1:48134`). Must be set together with `LLAMASTASH_IPC_TOKEN`. |
- | `LLAMASTASH_IPC_TOKEN` | Bearer token for the control-plane URL. See `LLAMASTASH_IPC_URL`. |
- | `LLAMASTASH_OFFLINE` | Disable outbound network for `init`, `pull`, and `doctor` fetch paths. Accepts `true` / `false` when bound via clap's `--offline` flag; the runtime `fetch::offline_requested` check also accepts `1` / `yes` for compatibility with scripts that follow the `XDG`/`gh` convention. Equivalent to `--offline`. |
- | `HF_TOKEN` | HuggingFace API token. Read by `init` and `pull` only; never propagated into spawned `llama-server` children. Cache-file (`~/.cache/huggingface/token`) source is refused if its mode is group/world-readable. |
- | `HF_ENDPOINT` | Override the HuggingFace API endpoint host. Must be `https://` and on the HF-allowlist (`huggingface.co` and its LFS CDN); non-allowlisted values are refused. Default: `https://huggingface.co`. |
- ### Default scan paths
- When `model_paths` and `--model-path` are empty, LlamaStash walks these caches automatically. Each bucket is independently toggleable via `disable_default_cache_paths.<bucket>: true` in `config.yaml`, or globally via `--no-scan` / `LLAMASTASH_NO_SCAN=1`.
- | Bucket | Linux | macOS |
- | ----------- | ------------------------------------------------- | -------------------------------------------------------- |
- | HuggingFace | `~/.cache/huggingface/hub` | `~/Library/Caches/huggingface/hub` |
- | Ollama | `~/.ollama/models` | `~/.ollama/models` |
- | LM Studio | `~/.lmstudio/models`, `~/.cache/lm-studio/models` | `~/Library/Caches/LMStudio/models`, `~/.lmstudio/models` |
- Files anywhere under these roots that end in `.gguf` (and aren't `.gguf.part`) get parsed and added to the catalog.
- ## CLI exit codes
- Every non-interactive subcommand returns a documented exit code so agent scripts can branch on failure class. Pin against numbers, not message text — they are the public contract.
- | Code | Meaning |
- | ---- | -------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
- | `0` | Success |
- | `64` | Usage error (missing required arg, invalid combination — clap-emitted) |
- | `65` | Daemon unreachable (`runtime.json` absent, control plane refused connection, timeout) |
- | `66` | Model reference matched zero or multiple models (stderr lists candidates) |
- | `67` | `start_model` failed at the supervisor (probe timeout, port allocation failure) |
- | `68` | `stop_model` / `stop_all` failed |
- | `69` | `pull` download failed (transport, checksum, or HF cache write) |
- | `70` | `llama-server` binary not found (`--llama-server`, `LLAMASTASH_LLAMA_SERVER`, or `$PATH`) |
- | `71` | Unexpected error (catch-all) |
- | `72` | `init` aborted before substantive work — failed precondition, integrity check, or rate-limited GH API. Safe to re-run. |
- | `73` | `init` download failed mid-step — disk space, transport, or HF cache write. Partial state recorded; re-run picks up where it stopped. |
- | `74` | `init` smoke-launch failed — phase-1 dry-run exceeded VRAM ceiling, or `--version` probe returned non-zero. Binary is installed; re-run smoke with `init --only smoke` or use `llamastash doctor` to diagnose. |
- | `75` | `delete` did not remove the model — the daemon refused it (not a catalog row, a launch still holds the file, the plan grew past what was shown) or the removal failed. A refusal removes nothing. |
- > **Note on sysexits.h**: the numbers above are deliberately reused from `<sysexits.h>` for familiarity, but LlamaStash's _meanings_ diverge from the standard ones. Scripts that import `EX_NOHOST` (68) expecting "host unreachable" will get our "stop failed"; `EX_DATAERR` (65) is reused for "daemon unreachable", not "data error". Branch on LlamaStash's table above, not the libc constants.
- ## Platforms
- Linux (x86_64, aarch64), macOS (Apple Silicon, Intel), and Windows 11 (x86_64). One binary, one TUI, one CLI — the daemon's control plane is bearer-token-authed HTTP loopback on every platform, and the supervisor uses the OS's native process-group semantics (POSIX `setsid` + signals, Windows Job Objects + CTRL+BREAK). Windows AMD GPU detection and `aarch64-pc-windows-msvc` are on the roadmap.
- ### Supported llama-server version
- LlamaStash hands GPU/CPU placement and context sizing to llama.cpp's `--fit` (on by default), so it needs a `llama-server` that has it.
- - **Minimum: build `b7410`** (2025-12-15), the first release carrying `--fit` / `--fit-ctx` (llama.cpp [PR #16653](https://github.com/ggml-org/llama.cpp/pull/16653)). Older builds abort on the unknown argument the moment a model launches.
- - **Recommended: a recent build** (`b8500`+, 2026). The May 2026 AMD GPU-stack updates (kernel, amdgpu firmware, ROCm) materially improved `--fit` on unified memory; verified on `b9245`.
- llama.cpp has no semantic versioning, no stable branch, and no stability policy ([discussion #16111](https://github.com/ggml-org/llama.cpp/discussions/16111)) — it tags ~10-14 rolling builds a day. So the build number is a floor for _flag existence_, not a behaviour guarantee; LlamaStash's own pre-spawn admission control is what actually prevents out-of-memory launches regardless of build. `llamastash init` installs a known-good build for your hardware.
- ## Roadmap
- Tracked in detail in [`TODO.md`](https://github.com/llamastash/llamastash/blob/main/TODO.md). The headline items on deck:
- - **MLX backend** — if the surface area lands cheaply alongside llama.cpp.
- - **llama.cpp version pinning** — prevent silent drift / incompatibility on `brew upgrade`.
- - **MCP and LAN-exposed HTTP surfaces** — Model Context Protocol, plus auth + TLS + LAN binding for the proxy. The loopback OpenAI-compatible proxy ships today (see [Drop-in OpenAI + Ollama proxy](#drop-in-openai--ollama-proxy)); the rest of the v1 R34 deferral (Anthropic compat, MCP, network exposure) stays on the roadmap.
- - **Per-PID VRAM attribution** via NVML's `nvmlDeviceGetComputeRunningProcesses`. Today the right pane shows per-model RAM + CPU%; VRAM is reported only at the host level.
- - **Docker-ready packaging** — official images plus a documented `docker run` path.
- - **Windows AMD GPU detection** — pick a probe path (DXGI / WMI / ADLX). 0.0.2 shows "GPU detection unavailable" on Windows AMD hosts.
- - **`aarch64-pc-windows-msvc`** — Snapdragon X / Surface Pro coverage. Deferred from 0.0.2.
- ## Contributing
- Bug reports, design discussion, and PRs welcome. Start with [`CONTRIBUTING.md`](CONTRIBUTING.md).
- ## AI Usage
- Multiple AI Coding Harnesses and LLMs were heavily used to create this project.
- ## License
- MIT © Deepu K Sasidharan
- ## Terms of use
- - The Software shall be used for Good, not Evil.
- - This software shall not be used for any military purposes including intelligence agencies.
- ## Related projects
- - [`kdash`](https://github.com/kdash-rs/kdash) — Kubernetes dashboard TUI by the same author. LlamaStash borrows its engineering and release scaffolding from kdash: the org layout (`llamastash/llamastash`, `llamastash/homebrew-llamastash`, `llamastash/llamastash.github.io`), the brew-tap structure, the `cli.rs` subdomain setup, and the release-on-tag workflow shape. The product itself is independent.
- - [`jwt-ui`](https://github.com/jwt-rs/jwt-ui) — JWT decoder / encoder TUI by the same author.
- ## Star History
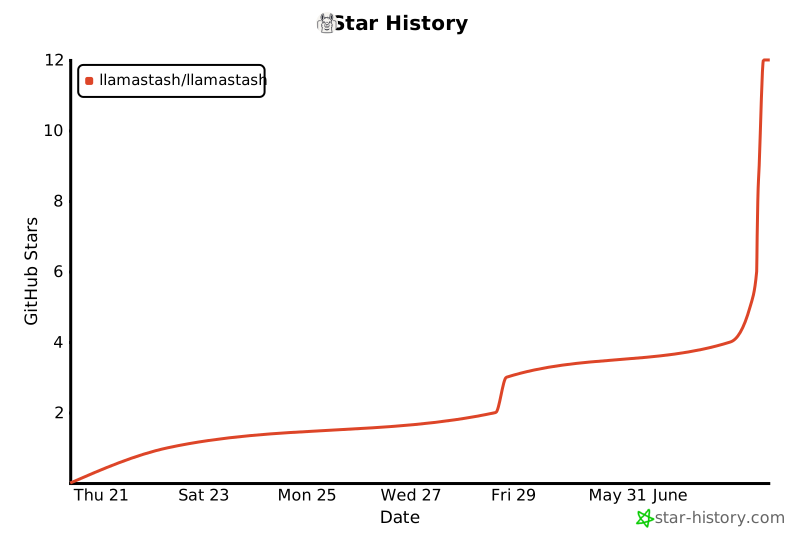
- If LlamaStash is useful to you, a star helps other people find it.
- [](https://www.star-history.com/?type=date&repos=llamastash%2Fllamastash)
Ratings and comments
Sign in to rate this skill.
Sign inFree to use. If it’s helped, pass it on.