rea-video
Reverse-engineer any video, shot by shot: tells whether each shot was filmed, AI-generated or coded, how the captions, cuts and audio were made, and how to remake it. 逆向一切视频,逐镜拆出制作方式并给出复刻方案。
Safety scan
A static text scan, not a guarantee. Select the badge to see what was scanned and every finding.
Check it deeper on your machine
It has changed since its scan on 11 Nov 2026.
As a Claude Code plugin, install it and then ask Claude Code:
/plugin marketplace add keithmackay/mackayi/plugin install scanskillsafety@mackayiDo a deep scan of https://github.com/JuneYaooo/rea-video with scanskillsafety
Or from a terminal, clone it and run it:
git clone https://github.com/keithmackay/scanskillsafety-skill ~/.claude/skills/scanskillsafetynode ~/.claude/skills/scanskillsafety/cli.cjs --deep 'https://github.com/JuneYaooo/rea-video'
It checks the exact commit: every file, its packages against OSV (api.osv.dev), how it compares with this page's scan (findsafeskills.com receives the repository's address), and, if you agree, Claude reading every file with your own Claude subscription. It never runs the code.
Badge for your README

Markdown
[](/listings/juneyaooo--rea-video)HTML
<a href="/listings/juneyaooo--rea-video"><img src="/api/listings/juneyaooo--rea-video/badge.svg" alt="findsafeskills safety rating" /></a>Install
Install instructions from the README
As written by the repo's author. findsafeskills has not verified these steps.
rea-video is built for AI agents. In Claude Code, Codex or any agent that can run commands, say:
Install https://github.com/JuneYaooo/rea-video, then break down this video: /path/to/video.mp4
The agent installs the CLI, learns the workflow and runs the whole thing. You need ffmpeg and Python 3.10+.
You get:
- a one-line summary, e.g. "41% AI video + 59% code UI, 8 s of real screen recording, library music at 122 BPM" - a remake plan, split into what to film, what to generate and what to code - a full `report.html` with per-shot frames, evidence, prompts, camera and lighting notes, and the audio breakdown
Add a video-capable model — Gemini or Doubao both work: give the agent the endpoint and key. It makes live/AI/3D calls more accurate and writes a reverse-engineered prompt for every shot. Without one it still works; if your agent can see images, it will check the uncertain shots itself.
What was scanned
The files the safety scan read, as written by the repository's author and shown as plain text. Lines with a finding are marked.
.claude-plugin/marketplace.json · Manifest · 11 lines
View this file on GitHub (read at the repository's current version: the scan did not record which commit it read)
This file has changed since it was scanned, so this is not exactly the text that was scanned, and no line is marked. The findings are listed with the safety scan above.
- {
- "name": "rea-video",
- "owner": { "name": "June" },
- "plugins": [
- {
- "name": "rea-video",
- "source": "./",
- "description": "逆向拆解视频:逐镜头判断制作方式,拆剪辑包装、声音和真实素材,给出复刻方案。"
- }
- ]
- }
README.md · README · 266 lines
View this file on GitHub (read at the repository's current version: the scan did not record which commit it read)
This file has changed since it was scanned, so this is not exactly the text that was scanned, and no line is marked. The findings are listed with the safety scan above.
- <div align="center">
- <picture>
- <source media="(prefers-color-scheme: dark)" srcset="docs/brand/logo-light.svg">
- <img src="docs/brand/logo-dark.svg" width="400" alt="rea-video">
- </picture>
- Reverse-engineer any video.
- Shot by shot: was it filmed, AI-generated or coded, and how to remake it.
- Every breakdown is written in **[VIDEO.md](https://videomd.github.io/videomd/)**, an open format that agents read layer by layer.
- [Website](https://www.reavideo.ai) | [中文](i18n/README_zh.md) | English | [Русский](i18n/README_ru.md) | [日本語](i18n/README_ja.md) | [한국어](i18n/README_ko.md) | [Español](i18n/README_es.md) | [Português](i18n/README_pt.md) | [Français](i18n/README_fr.md) | [Deutsch](i18n/README_de.md) | [Tiếng Việt](i18n/README_vi.md) | [বাংলা](i18n/README_bn.md) | [Türkçe](i18n/README_tr.md)
- **⚠️ Notice: rea-video is an open-source project. I have not launched and will not launch any cryptocurrency token. Any token using this project’s name is not affiliated with me, and I do not endorse it or accept fees from it. Please be cautious of scams.**
- [](https://github.com/JuneYaooo/rea-video/stargazers)
- 
- 
- [](https://videomd.github.io/videomd/)
- <a href="https://trendshift.io/repositories/334878" target="_blank"><img src="https://trendshift.io/api/badge/trendshift/repositories/334878/daily" alt="JuneYaooo/rea-video | Trendshift" width="250" height="55"></a>
- [](https://www.reavideo.ai) [](https://discord.gg/dZj8D3GqWT) [](i18n/README_zh.md#社区) [](https://x.com/yao_june12106)
- ⭐ *Help more people find rea-video. Star this repo!*
- <img src="docs/cases/demo.gif" width="440" alt="Left: TikTok original shot on a phone; right: someone's AI remake with a different product">
- Left: a TikTok ad shot on a phone. Right: an AI remake with another product. rea-video's verdict: the left is all live footage, one set and two camera positions; the right is all AI, 8 shots across 3 generations.
- </div>
- ## Quick start
- rea-video is built for AI agents. In Claude Code, Codex or any agent that can run commands, say:
- ```text
- Install https://github.com/JuneYaooo/rea-video, then break down this video: /path/to/video.mp4
- ```
- The agent installs the CLI, learns the workflow and runs the whole thing. You need ffmpeg and Python 3.10+.
- Breakdowns are fully upgraded. Each one gives you two outputs:
- - **Report** (`report.html` / PDF), for you: more reader-friendly, with a clearer structure, easier to learn from and to understand how the video was made and how to remake it.
- - **[VIDEO.md](https://videomd.github.io/videomd/)**, for your AI: layered, so the AI reads only what a question needs and uses fewer tokens.
- You can also hook up a video-capable model (Gemini or Doubao both work) by giving the agent its endpoint and key. That makes the live/AI/3D calls more accurate and adds a reverse-engineered prompt for every shot. It works fine without one; if your agent can see images, it checks the uncertain shots itself.
- > Reports are written in whichever language you ask in (Chinese or English). The example reports below are in English.
- ## What it can break down
- | Video type | Examples | What you get |
- |---|---|---|
- | Live footage | Talking-head, tabletop, handheld product demo, vlog, store visit | Setups and camera positions, framing, camera moves, lighting (12 setups with gear lists), color grade |
- | AI video | Text/image-to-video, AI short drama, AI music video | Evidence, a reverse-engineered prompt per shot, how to batch into generations and which model to use |
- | Avatar | A portrait driven by audio, lip-sync | Which shots are avatar shots, what portrait and audio you need |
- | 3D / animation | Blender / C4D explainers, product animation, 2D animation, stop-motion | Whether to generate with a video model or render from 3D code |
- | Code / template | Kinetic type, UI demos, charts, slide-style cards | Text, layout and motion timing, ready to rebuild as a Remotion project |
- | Screen recording | Software tutorials, web demos | Which parts are real material you'll need to record yourself |
- | Mixed / edits | AI characters + code UI + real screen capture; live footage with AI edits | Each shot judged separately, then reassembled on the original timeline |
- Besides how the visuals were made, every breakdown also covers:
- - Captions and styled text: start and end of each line (exports to SRT / ASS), plus color, outline and how the text comes in
- - Stickers, emoji, picture-in-picture: where they sit and how long they stay
- - Editing: where the cuts are, how fast, whether they hit the beat
- - Audio: human or AI voice, AI or library music and its BPM, where each sound effect lands
- - Material you'll need to supply yourself: screen recordings, screenshots, product photos
- ## Examples
- The sample videos in `docs/cases/videos/` are re-compressed to keep the repo small, which strips the TikTok / Douyin platform tags. So if you run them yourself, you'll get different results from the reports below, especially without a vision model. To reproduce them, use the original downloads from the platform.
- <table>
- <tr>
- <td width="50%" valign="top">
- <a href="docs/cases.md#2-混合片ai-人物对话--代码界面--真实录屏"><img src="docs/cases/dual_role/thumb.jpg"></a><br>
- <b>Mixed-media clip</b> · 19 s · 10 shots<br>
- AI characters talking + code-built UI + 8 s of real screen recording. The 5 dialogue shots are broken up by UI segments but share one set, so a single generation covers all of them.<br>
- <a href="docs/cases/videos/dual_role.mp4">Video</a> · <a href="docs/cases/dual_role/report_en.md">Report</a>
- </td>
- <td width="50%" valign="top">
- <a href="docs/cases.md#3-3d-科普片咸鸭蛋为什么会流油"><img src="docs/cases/salted_egg/thumb.jpg"></a><br>
- <b>3D explainer</b> · 67 s · 21 shots<br>
- All 3D, AI narration. You can do it in 10 video generations, or have an LLM write Blender / Three.js code.<br>
- <a href="docs/cases/videos/salted_egg.mp4">Video</a> · <a href="docs/cases/salted_egg/report_en.md">Report</a>
- </td>
- </tr>
- <tr>
- <td width="50%" valign="top">
- <a href="docs/cases.md#4-代码-ui-动效产品宣传片"><img src="docs/cases/v10/thumb.jpg"></a><br>
- <b>Product promo</b> · 70 s · 12 shots<br>
- 83% code-driven motion graphics, 12% screen recording. No video model needed; one Remotion project does it.<br>
- <a href="docs/cases/videos/v10_oiioii_gen_coding_first.mp4">Video</a> · <a href="docs/cases/v10/report_en.md">Report</a>
- </td>
- <td width="50%" valign="top">
- <a href="docs/cases.md#5-ai-音乐-mv歌是-ai-写的还是曲库的"><img src="docs/cases/qing_mv/thumb.jpg"></a><br>
- <b>AI music video</b> · 165 s · 86 shots<br>
- Correctly flags the song as AI-generated (it was made with Suno). The vision model called some shots "live-action drama"; the agent spotted fake Chinese characters on a scroll and ruled them AI.<br>
- <a href="docs/cases/videos/qing_mv.mp4">Video</a> · <a href="docs/cases/qing_mv/report_en.md">Report</a>
- </td>
- </tr>
- <tr>
- <td width="50%" valign="top">
- <a href="docs/cases.md#6-实拍带货沉浸式开箱"><img src="docs/cases/unboxing/thumb.jpg"></a><br>
- <b>Live-action unboxing</b> · 72 s · 29 shots<br>
- All real footage: an overhead phone rig, one rug, one camera position, no voice-over, room sound plus library BGM. After platform transcoding, the offline tools called 35% of it AI; after agent review it came out 97% live-action.<br>
- <a href="docs/cases/videos/unboxing.mp4">Video</a> · <a href="docs/cases/unboxing/report_en.md">Report</a>
- </td>
- </tr>
- </table>
- ## Remakes
- After rea-video breaks a video down, the remake recipe in [capsule-cinema](https://github.com/JuneYaooo/capsule-cinema) generates a new version that keeps the original's camera, motion, pacing and transitions and swaps only the elements you pick.
- These were made with a self-hosted MiniMax H3, using the original shot as the motion reference and keyframes with the swapped elements (gpt-image-2) for the look.
- Below are three remakes OiiOii showed in its WeChat articles. We made two versions of each: one with the same swap as OiiOii, and one that also swaps the subject, setting and props.
- Each GIF plays four versions in sync: the original, OiiOii's remake, our remake and the element-swap version.
- <table>
- <tr><td>
- <b>Overhead outfit change</b> · 12 s<br>
- Same swap: woman → man, three outfits → matching menswear. Element swap: a girl in three historical Hanfu outfits in a Chinese study; the remote becomes a round fan.<br>
- <img src="docs/cases/remake/outfit.gif"><br>
- <a href="docs/cases/remake/outfit_compare.mp4">HD comparison video (with audio)</a> · <a href="docs/cases/remake/outfit_sheet.jpg">same-moment stills</a>
- </td></tr>
- <tr><td>
- <b>Paper-craft / watercolor animation</b> · 30 s<br>
- Same swap: new clay girl as the lead. Element swap: a fox; forest → coral reef, clouds → starry sky, sunset → aurora.<br>
- <img src="docs/cases/remake/paper.gif"><br>
- <a href="docs/cases/remake/paper_compare.mp4">HD comparison video (with audio)</a> · <a href="docs/cases/remake/paper_sheet.jpg">same-moment stills</a>
- </td></tr>
- <tr><td>
- <b>Handheld product video</b> · 21 s · 11 shots<br>
- Same swap: an original new product, English sticker → Chinese caption. Element swap: pink product, kitchen → camping table, new ingredients.<br>
- <img src="docs/cases/remake/juicer.gif"><br>
- <a href="docs/cases/remake/juicer_compare.mp4">HD comparison video (with audio)</a> · <a href="docs/cases/remake/juicer_sheet.jpg">same-moment stills</a>
- </td></tr>
- </table>
- The HD comparison videos use the original audio. The originals and OiiOii versions come from the articles and are shown for comparison only.
- You can also do the remake in [ChatCut](https://chatcut.io/r/github-e4rd), a hosted AI video editor: there is no model to set up, and the generated shots land on a timeline you can keep editing. <sub>Sponsor</sub>
- ## Sponsors
- rea-video is free and open source. Sponsors help keep it maintained.
- <table><tr>
- <td align="center" width="200"><a href="https://chatcut.io/r/github-e4rd"><picture>
- <source media="(prefers-color-scheme: dark)" srcset="docs/brand/chatcut-logo-light.svg">
- <img src="docs/brand/chatcut-logo-dark.svg" height="32" alt="ChatCut">
- </picture></a></td>
- <td><b><a href="https://chatcut.io/r/github-e4rd">ChatCut</a></b> is an AI video editor for Claude Code and Codex that generates the shots, cuts them on a timeline and exports the finished video.<br>
- <a href="https://chatcut.io/r/github-e4rd">Try ChatCut for free</a></td>
- </tr></table>
- <sub>Sponsored · <a href="https://reavideo.ai/en/contact/">Become a sponsor</a></sub>
- ## Accuracy
- Accuracy of the how-it-was-made call, weighted by shot duration:
- | | Tuning set (15) | Holdout (16) | Re-encoded WeChat videos (10) |
- |---|---|---|---|
- | Tools only (offline, free) | 98.3% | 99.6% / 98.9% | 88.6% |
- | + vision model (Gemini) | — | 99.6% / 99.8% | 99.6% |
- | + agent visual review | — | 99.6% / 99.8% | 100% |
- The Holdout column shows two numbers: holdout (9 videos) and holdout2 (7 videos).
- On original files, the tools alone are usually enough. Videos downloaded from platforms have been recompressed, which wipes out the noise evidence, so you need a visual check to get back above 99%.
- Real-asset detection is 97–99%; on nine hand-labelled clips, shot boundaries reach 95% recall and 94% precision. Numbers and how to reproduce them: [eval/RESULTS.md](eval/RESULTS.md).
- ## How it works
- 
- 1. Split: cut the video into shots and split the audio into voice, music and effects.
- 2. Gather evidence: measure (frame cadence, sensor noise, whether the whole image moves as one flat plane, AIGC tags in the metadata), look (hands, text, physics) and listen (BPM, key, singing vs speech).
- 3. Decide: hard evidence like AIGC tags and frame cadence beats "looks like". Conflicts get flagged for the agent to check visually.
- 4. Plan the remake: batch shots according to what the target video model can actually do, such as max clip length, multi-shot support and how many reference images it takes.
- ## Star History
- [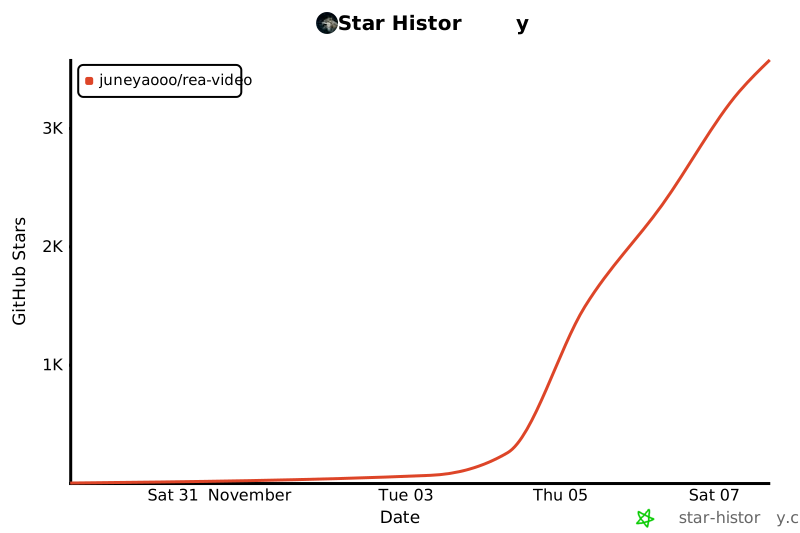](https://star-history.com/#JuneYaooo/rea-video&Date)
- ## FAQ
- <details>
- <summary>How is this different from one-click remake tools like Hypit?</summary>
- [Hypit](https://github.com/hypit-ai/hypit) takes a reference video and makes a new one: the agent reads frame grids to understand the original, generates footage with the models it supports (Seedance, PixVerse, MiniMax, Wan and others), and renders captions and motion graphics in HTML.
- It doesn't ask how the original was made. A live-action source goes through the same pipeline; it won't tell you how many cameras were used or how it was lit. What AI video it can match depends on the models it supports: no Kling or Veo, no dedicated avatar or 3D path, and no AI music (you bring your own). It's strongest on talking-head, podcast and interview videos that follow a script, and weaker on music-driven edits, product motion graphics and cinematic shorts.
- rea-video doesn't render a video. It works out shot by shot whether something was filmed, AI-generated or built in code, then gives a shooting plan, prompts or a code approach for each. For a quick lookalike, Hypit is faster. To understand how the original was made and remake it cheaply, use rea-video. They work fine together.
- </details>
- <details>
- <summary>Do I need a video-capable model? What does it cost?</summary>
- No. Tools-only mode is offline and free, and already accurate on original files. For recompressed platform downloads, add a video-capable model (Gemini or Doubao both work) or use an agent that can see images; you pay whatever that service charges. Automatic video generation (capsule-cinema) does a free dry run first and only calls paid models after you confirm.
- </details>
- <details>
- <summary>Can it remake the whole video automatically?</summary>
- Partly. With [capsule-cinema](https://github.com/JuneYaooo/capsule-cinema) installed, AI shots are generated and placed back on the original timeline automatically. You film the live shots from the shooting plan, and the agent writes the code shots as a Remotion project. See [docs/replicate.md](docs/replicate.md).
- </details>
- <details>
- <summary>Can it break down a multi-episode short drama?</summary>
- rea-video works on one video at a time. For multi-episode short dramas with a running story, see [rea-toon](https://github.com/JuneYaooo/rea-toon).
- </details>
- <details>
- <summary>What is VIDEO.md, and why does rea-video write one?</summary>
- Every skill has a `SKILL.md`; every video gets a `VIDEO.md`. It is an open format for video breakdowns, made so that models read only what a question needs. A full breakdown runs to hundreds of thousands of tokens; VIDEO.md lays it out in levels: a card of a few hundred tokens, an overview and map, a timeline with one line per shot, then one file per shot. Every file states its size, and what is seen on screen is kept apart from what the tools infer.
- rea-video writes one into every output folder (`out/ref/VIDEO.md`), and its agent skill reads it instead of the raw data. Other agents and tools can read it without knowing rea-video: `pip install videomd`, then `videomd check out/ref`. The spec and guides are at [videomd.github.io/videomd](https://videomd.github.io/videomd/).
- </details>
- <details>
- <summary>Can I just repost someone else's video?</summary>
- No. rea-video is for learning a video's structure, pacing and techniques, then remaking it with material you have the rights to. Don't reuse other people's footage, music, characters or likeness. Follow platform rules and local AI-content labeling requirements when you publish.
- </details>
- ## Docs
- - [docs/what-it-detects.md](docs/what-it-detects.md): everything it detects (10 visual types, camera, lighting, grade, audio)
- - [docs/replicate.md](docs/replicate.md): how to remake from the report
- - [docs/cases.md](docs/cases.md): details on each example
- - [docs/decompose.md](docs/decompose.md): detection rules
- - [docs/cli.md](docs/cli.md): CLI usage and capsule-cinema integration
- - [docs/videomd.md](docs/videomd.md): VIDEO.md, the standard breakdown package that agents and downstream tools read (open format: [videomd/videomd](https://github.com/videomd/videomd))
- - [rea_video/capabilities/](rea_video/capabilities/README.md): capability tables for video / image / audio models, used to pick models for the remake plan
- - [eval/RESULTS.md](eval/RESULTS.md): eval results
- The docs are in Chinese for now.
- ## Community
- Questions, breakdowns and remake ideas: [GitHub Discussions](https://github.com/JuneYaooo/rea-video/discussions). Chat with us on [Discord](https://discord.gg/dZj8D3GqWT). Chinese speakers can also find us on [linux.do](https://linux.do/).
- Want a video broken down? Open a [request issue](https://github.com/JuneYaooo/rea-video/issues/new?template=request_breakdown.yml) with the link and we'll publish the result as a case.
- ## Credits
- Inspired by [REA (Reverse Engineer Anything)](https://github.com/morluto/rea): work back from what you see to how it was made, back every claim with evidence, and verify by measuring.
- Sound separation uses [UVR MDX-Net](https://github.com/TRvlvr/model_repo) for voice and music, and [BandIt v2](https://github.com/kwatcharasupat/bandit-v2) (Watcharasupat, Wu and Orife; weights CC BY-SA 4.0) for sound effects. Both models are downloaded on first use and are not part of this repo.
scripts/render_flow_svg.py · Bundled script · 816 lines
- #!/usr/bin/env python3
- """生成 README 用的流程图 docs/rea-flow.svg(中文)和 docs/rea-flow_en.svg(英文)和 docs/rea-flow_ja.svg(日文),以及韩 / 俄 / 西 / 葡 / 法 / 德 / 越 / 孟加拉版 docs/rea-flow_{ko,ru,es,pt,fr,de,vi,bn}.svg。
- 用法:python3 scripts/render_flow_svg.py [输出目录,默认 docs]
- 画的是一个具体例子:一条带货视频切成 5 个镜头 + 声音,每列一个镜头,每行一步
- (切开 / 取证据 / 判断 / 复刻方案)。改文案改顶部的 ZH / EN / JA / KO / RU / ES / PT / FR / DE / VI / BN 字典即可。
- """
- import sys
- from pathlib import Path
- ZH = dict(
- title="拿一条带货视频举例:切成 5 个镜头和声音,每个镜头走四步",
- subtitle="横着看是同一个镜头从取证到复刻方案;竖着看是同一步里不同镜头的差别",
- steps=[
- ("①", "切开", "按镜头切开\n声音拆三轨"),
- ("②", "取证据", "测画面\n看图\n听声音"),
- ("③", "判断", "硬证据优先\n冲突就复核"),
- ("④", "复刻方案", "按模型能力\n分批、分路"),
- ],
- shots=["0:00–0:06", "0:06–0:11", "0:11–0:16", "0:16–0:21", "0:21–0:24"],
- sound_lanes=["人声", "配乐", "音效"],
- sound_caption="整条 0:00–0:24",
- kinds={"m": "测", "l": "看", "h": "听"},
- evidence=[
- [("m", "60fps,无重复帧"), ("m", "有传感器噪点"), ("l", "手指、文字正常")],
- [("m", "背景像素逐帧不变"), ("m", "只有局部在动"), ("l", "真实 App 界面")],
- [("m", "24fps,重复帧规律"), ("m", "文件带 AIGC 标识"), ("l", "礼盒上文字乱码")],
- [("m", "工具:像 3D 渲染"), ("l", "看图:像 AI 视频"), ("l", "意见冲突 ⚠")],
- [("m", "背景像素冻结"), ("m", "OCR 出文字轨"), ("l", "没有拍摄痕迹")],
- [("h", "3–8Hz 音节调制"), ("h", "122 BPM,D 小调"), ("h", "切点落在节拍上")],
- ],
- verdicts=[
- ("live", "实拍", 0.96, None),
- ("screen", "录屏 · 真实素材", 0.93, None),
- ("ai", "AI 视频", 0.98, None),
- ("ai", "AI 视频", 0.88, "agent 看图复核后定"),
- ("code", "代码渲染", 0.95, None),
- ("sound", "真人口播 + 曲库配乐", 0.9, None),
- ],
- rule="硬证据(AIGC 标识、帧率规律)优先于「看起来像」;几方意见冲突的镜头标出来,交给 agent 看图复核",
- plans={
- "s1": ("cam", ["自己拍", "1 场景 1 机位", "环形灯 + 手机"]),
- "s2": ("screen", ["自己录屏", "真实素材", "不用模型生成"]),
- "s34": ("ai", ["两镜合并成 1 次生成", "多镜头提示词 + 2 张产品图 + @原片", "按模型能力分批:单次 10 秒、", "能出多镜头、吃 2 张参考图"]),
- "s5": ("code", ["写代码", "Remotion 工程", "文字、版式、动效"]),
- "snd": ("sound", ["三条轨分开做", "口播:自己配或 TTS", "配乐:曲库找 122 BPM", "音效:按时间表加"]),
- },
- footer=("报告 report.html · breakdown.json", "一句话结论 · 按实拍 / AI 生成 / 代码分开写的复刻方案 · 逐镜截图、判断依据、提示词 · 字幕 SRT / ASS"),
- )
- EN = dict(
- title="A worked example: one product video cut into 5 shots plus sound, each shot going through four steps",
- subtitle="Read across for one shot from evidence to remake plan; read down to compare shots within a step",
- steps=[
- ("1", "Split", "cut into shots\nsplit audio 3 ways"),
- ("2", "Evidence", "measure frames\nlook at images\nlisten"),
- ("3", "Decide", "hard evidence first\nreview conflicts"),
- ("4", "Plan", "batched by model\ncapabilities"),
- ],
- shots=["0:00–0:06", "0:06–0:11", "0:11–0:16", "0:16–0:21", "0:21–0:24"],
- sound_lanes=["voice", "music", "sfx"],
- sound_caption="whole track 0:00–0:24",
- kinds={"m": "M", "l": "L", "h": "H"},
- evidence=[
- [("m", "60fps, no dup frames"), ("m", "sensor noise"), ("l", "hands, text fine")],
- [("m", "static background"), ("m", "only local motion"), ("l", "a real app UI")],
- [("m", "24fps dup cadence"), ("m", "AIGC metadata tag"), ("l", "garbled box text")],
- [("m", "tools: looks 3D"), ("l", "VLM: looks AI"), ("l", "conflict ⚠")],
- [("m", "static background"), ("m", "OCR text track"), ("l", "no camera traces")],
- [("h", "3–8Hz syllable rate"), ("h", "122 BPM, D minor"), ("h", "cuts land on beats")],
- ],
- verdicts=[
- ("live", "Live action", 0.96, None),
- ("screen", "Screen recording", 0.93, None),
- ("ai", "AI video", 0.98, None),
- ("ai", "AI video", 0.88, "agent reviews visually"),
- ("code", "Code render", 0.95, None),
- ("sound", "Voice + library music", 0.9, None),
- ],
- rule="Hard evidence (AIGC tags, frame cadence) outranks \"looks like\"; shots where the sources disagree are flagged for the agent to review visually",
- plans={
- "s1": ("cam", ["Shoot it", "1 scene, 1 camera", "ring light + phone"]),
- "s2": ("screen", ["Record it", "real asset", "never generated"]),
- "s34": ("ai", ["Merge 2 shots into 1 generation", "multi-shot prompt + 2 product images + @source", "batched by model capability: 10 s per call,", "multi-shot output, 2 reference images"]),
- "s5": ("code", ["Write code", "Remotion project", "text, layout, motion"]),
- "snd": ("sound", ["Three tracks", "voice: record or TTS", "music: library, 122 BPM", "sfx: by timetable"]),
- },
- footer=("Report report.html · breakdown.json", "one-line verdict · remake plan split into shoot / generate / code · per-shot stills, evidence, prompts · subtitles SRT / ASS"),
- )
- JA = dict(
- title="商品紹介動画を例に:5 ショットと音声に分け、各ショットが 4 ステップを通る",
- subtitle="横に読むと 1 ショットの根拠からリメイク案まで、縦に読むと同じステップでのショットごとの違い",
- steps=[
- ("①", "分割", "ショットに分け\n音声を 3 つに分離"),
- ("②", "根拠", "フレーム計測\n画像を見る\n音を聴く"),
- ("③", "判定", "確かな根拠を優先\n矛盾は再確認"),
- ("④", "リメイク案", "モデルの能力に\n合わせてまとめる"),
- ],
- shots=["0:00–0:06", "0:06–0:11", "0:11–0:16", "0:16–0:21", "0:21–0:24"],
- sound_lanes=["声", "音楽", "効果音"],
- sound_caption="全体 0:00–0:24",
- kinds={"m": "測", "l": "見", "h": "聴"},
- evidence=[
- [("m", "60fps、重複なし"), ("m", "センサーノイズ"), ("l", "指と文字が自然")],
- [("m", "背景の画素が不変"), ("m", "動くのは一部だけ"), ("l", "実在アプリの UI")],
- [("m", "24fps 重複の周期"), ("m", "AIGC タグあり"), ("l", "箱の文字が崩れ")],
- [("m", "ツール:3D っぽい"), ("l", "VLM:AI 動画"), ("l", "意見が矛盾 ⚠")],
- [("m", "背景の画素が固定"), ("m", "OCR で文字軌道"), ("l", "撮影の痕跡なし")],
- [("h", "3–8Hz の音節変調"), ("h", "122 BPM、ニ短調"), ("h", "カットが拍に乗る")],
- ],
- verdicts=[
- ("live", "実写", 0.96, None),
- ("screen", "画面収録・実素材", 0.93, None),
- ("ai", "AI 動画", 0.98, None),
- ("ai", "AI 動画", 0.88, "agent が目視で再確認"),
- ("code", "コード描画", 0.95, None),
- ("sound", "実声 + ライブラリ音楽", 0.9, None),
- ],
- rule="確かな根拠(AIGC タグ、フレーム周期)は「そう見える」より優先。意見が割れたショットは agent が目視で再確認",
- plans={
- "s1": ("cam", ["自分で撮る", "1 シーン 1 カメラ", "照明 + スマホ"]),
- "s2": ("screen", ["画面収録", "実素材", "生成しない"]),
- "s34": ("ai", ["2 ショットを 1 回で生成", "マルチショット用プロンプト + 商品画像 2 枚", "モデルの能力に合わせて:1 回 10 秒、", "マルチショット出力、参照画像 2 枚"]),
- "s5": ("code", ["コードを書く", "Remotion で再現", "文字、配置、動き"]),
- "snd": ("sound", ["3 トラック", "声:自分で録るか TTS", "音楽:122 BPM の曲", "効果音:時刻表どおり"]),
- },
- footer=("レポート report.html · breakdown.json", "一文の結論 · 実写 / AI 生成 / コード別のリメイク案 · ショットごとのスクショ、根拠、プロンプト · 字幕 SRT / ASS"),
- )
- KO = dict(
- title="상품 영상 예시: 5개 샷과 사운드로 나누고, 각 샷이 4단계를 거칩니다",
- subtitle="가로로 읽으면 한 샷의 근거부터 리메이크 계획까지, 세로로 읽으면 같은 단계에서 샷별 차이",
- steps=[
- ("①", "분할", "샷 단위로 분할\n오디오 3트랙 분리"),
- ("②", "근거", "프레임 측정\n이미지 보기\n소리 듣기"),
- ("③", "판정", "확실한 근거 우선\n충돌은 재검토"),
- ("④", "리메이크", "모델 능력에\n맞춰 묶기"),
- ],
- shots=["0:00–0:06", "0:06–0:11", "0:11–0:16", "0:16–0:21", "0:21–0:24"],
- sound_lanes=["음성", "음악", "효과음"],
- sound_caption="전체 0:00–0:24",
- kinds={"m": "측", "l": "시", "h": "청"},
- evidence=[
- [("m", "60fps, 중복 없음"), ("m", "센서 노이즈"), ("l", "손·글자 정상")],
- [("m", "배경 픽셀 고정"), ("m", "일부만 움직임"), ("l", "실제 앱 화면")],
- [("m", "24fps 중복 주기"), ("m", "AIGC 태그 있음"), ("l", "상자 글자 깨짐")],
- [("m", "도구: 3D 같음"), ("l", "VLM: AI 영상"), ("l", "의견 충돌 ⚠")],
- [("m", "배경 픽셀 고정"), ("m", "OCR 자막 트랙"), ("l", "촬영 흔적 없음")],
- [("h", "3–8Hz 음절 변조"), ("h", "122 BPM, D 단조"), ("h", "컷이 비트에 맞음")],
- ],
- verdicts=[
- ("live", "실사", 0.96, None),
- ("screen", "화면 녹화 · 실소재", 0.93, None),
- ("ai", "AI 영상", 0.98, None),
- ("ai", "AI 영상", 0.88, "에이전트가 이미지로 재검토"),
- ("code", "코드 렌더링", 0.95, None),
- ("sound", "음성 + 라이브러리 음악", 0.9, None),
- ],
- rule="확실한 근거(AIGC 태그, 프레임 주기)가 「그렇게 보인다」보다 우선. 의견이 갈리는 샷은 표시해서 에이전트가 이미지로 재검토",
- plans={
- "s1": ("cam", ["직접 촬영", "1 장면 1 카메라", "링라이트 + 휴대폰"]),
- "s2": ("screen", ["직접 녹화", "실제 소재", "생성하지 않음"]),
- "s34": ("ai", ["2개 샷을 1번에 생성", "멀티샷 프롬프트 + 제품 이미지 2장 + @원본", "모델 능력에 맞춰 묶음: 1회 10초,", "멀티샷 출력, 참조 이미지 2장"]),
- "s5": ("code", ["코드 작성", "Remotion 프로젝트", "텍스트, 레이아웃, 모션"]),
- "snd": ("sound", ["트랙 3개 따로", "음성: 직접 녹음 또는 TTS", "음악: 122 BPM 라이브러리", "효과음: 타임라인대로"]),
- },
- footer=("리포트 report.html · breakdown.json", "한 줄 결론 · 촬영 / AI 생성 / 코드로 나눈 리메이크 계획 · 샷별 스틸, 근거, 프롬프트 · 자막 SRT / ASS"),
- )
- RU = dict(
- title="Пример: рекламный ролик разбит на 5 кадров и звук, каждый кадр проходит четыре шага",
- subtitle="По горизонтали — один кадр от доказательств до плана ремейка; по вертикали — разные кадры на одном шаге",
- steps=[
- ("1", "Нарезка", "делим на кадры\nзвук на 3 дорожки"),
- ("2", "Факты", "замер кадров\nсмотрим\nслушаем"),
- ("3", "Решение", "сначала факты\nспорное —\nна проверку"),
- ("4", "План", "группируем\nпод модель"),
- ],
- shots=["0:00–0:06", "0:06–0:11", "0:11–0:16", "0:16–0:21", "0:21–0:24"],
- sound_lanes=["голос", "музыка", "эффекты"],
- sound_caption="весь звук 0:00–0:24",
- kinds={"m": "З", "l": "В", "h": "С"},
- evidence=[
- [("m", "60fps, без дублей"), ("m", "шум сенсора"), ("l", "руки и текст ОК")],
- [("m", "фон неподвижен"), ("m", "движется часть"), ("l", "реальный UI")],
- [("m", "24fps, повторы"), ("m", "метка AIGC"), ("l", "текст искажён")],
- [("m", "замер: вроде 3D"), ("l", "VLM: вроде ИИ"), ("l", "конфликт ⚠")],
- [("m", "фон неподвижен"), ("m", "текст по OCR"), ("l", "камеры не видно")],
- [("h", "слоги 3–8 Гц"), ("h", "122 BPM, ре минор"), ("h", "склейки в такт")],
- ],
- verdicts=[
- ("live", "Живая съёмка", 0.96, None),
- ("screen", "Запись экрана", 0.93, None),
- ("ai", "ИИ-видео", 0.98, None),
- ("ai", "ИИ-видео", 0.88, "агент проверяет визуально"),
- ("code", "Рендер кодом", 0.95, None),
- ("sound", "Голос + сток-музыка", 0.9, None),
- ],
- rule="Жёсткие доказательства (метки AIGC, частота кадров) важнее «похоже на»; кадры, где источники расходятся, агент проверяет визуально",
- plans={
- "s1": ("cam", ["Снять", "1 сцена, 1 камера", "лампа + телефон"]),
- "s2": ("screen", ["Записать", "реальный материал", "не генерируем"]),
- "s34": ("ai", ["2 кадра за 1 генерацию", "промпт на 2 кадра + 2 фото + @исходник", "под возможности модели: 10 с за вызов,", "несколько кадров за раз, 2 референса"]),
- "s5": ("code", ["Код", "проект Remotion", "текст и анимация"]),
- "snd": ("sound", ["Три дорожки", "голос: сам или TTS", "музыка: сток, 122 BPM", "эффекты: по таймингу"]),
- },
- footer=("Отчёт report.html · breakdown.json", "вывод в одну строку · план: снять / сгенерировать / написать код · кадры, доказательства, промпты · субтитры SRT / ASS"),
- )
- ES = dict(
- title="Un ejemplo: un vídeo de producto dividido en 5 planos y sonido; cada plano pasa por cuatro pasos",
- subtitle="En horizontal, un plano desde la evidencia hasta el plan de remake; en vertical, planos distintos en un mismo paso",
- steps=[
- ("1", "Dividir", "cortar en planos\naudio en 3 pistas"),
- ("2", "Evidencia", "medir fotogramas\nmirar imágenes\nescuchar"),
- ("3", "Decidir", "primero lo medido\nrevisar conflictos"),
- ("4", "Plan", "agrupar según\nel modelo"),
- ],
- shots=["0:00–0:06", "0:06–0:11", "0:11–0:16", "0:16–0:21", "0:21–0:24"],
- sound_lanes=["voz", "música", "efectos"],
- sound_caption="pista completa 0:00–0:24",
- kinds={"m": "M", "l": "V", "h": "O"},
- evidence=[
- [("m", "60fps, sin repetir"), ("m", "ruido de sensor"), ("l", "manos y texto bien")],
- [("m", "fondo estático"), ("m", "solo mov. local"), ("l", "UI de app real")],
- [("m", "24fps, repetidos"), ("m", "etiqueta AIGC"), ("l", "texto ilegible")],
- [("m", "herramientas: 3D"), ("l", "VLM: parece IA"), ("l", "conflicto ⚠")],
- [("m", "fondo estático"), ("m", "pista de texto OCR"), ("l", "no parece rodado")],
- [("h", "sílabas a 3–8Hz"), ("h", "122 BPM, re menor"), ("h", "cortes a tempo")],
- ],
- verdicts=[
- ("live", "Imagen real", 0.96, None),
- ("screen", "Pantalla grabada", 0.93, None),
- ("ai", "Vídeo IA", 0.98, None),
- ("ai", "Vídeo IA", 0.88, "el agente lo revisa a ojo"),
- ("code", "Render por código", 0.95, None),
- ("sound", "Voz + música de stock", 0.9, None),
- ],
- rule="La evidencia dura (etiquetas AIGC, cadencia de fotogramas) pesa más que «parece»; los planos en conflicto se marcan y el agente los revisa a ojo",
- plans={
- "s1": ("cam", ["Grabarlo", "1 escena, 1 cámara", "aro de luz + móvil"]),
- "s2": ("screen", ["Grabar", "material real", "nunca se genera"]),
- "s34": ("ai", ["2 planos en 1 generación", "prompt multiplano + 2 fotos + @original", "según el modelo: 10 s por llamada,", "salida multiplano, 2 imágenes de referencia"]),
- "s5": ("code", ["Programar", "proyecto Remotion", "texto, diseño, motion"]),
- "snd": ("sound", ["Tres pistas", "voz: grabar o TTS", "música: stock, 122 BPM", "efectos: por tiempos"]),
- },
- footer=("Informe report.html · breakdown.json", "veredicto en una línea · plan: grabar / generar / programar · fotogramas, evidencias y prompts por plano · subtítulos SRT / ASS"),
- )
- PT = dict(
- title="Um exemplo: um vídeo de produto dividido em 5 planos e som; cada plano passa por quatro etapas",
- subtitle="Na horizontal, um plano da evidência até a proposta de remake; na vertical, planos diferentes na mesma etapa",
- steps=[
- ("1", "Dividir", "cortar em planos\náudio em 3 faixas"),
- ("2", "Evidência", "medir quadros\nolhar imagens\nescutar"),
- ("3", "Decidir", "concreto primeiro\nrevisar conflitos"),
- ("4", "Remake", "agrupar conforme\no modelo"),
- ],
- shots=["0:00–0:06", "0:06–0:11", "0:11–0:16", "0:16–0:21", "0:21–0:24"],
- sound_lanes=["voz", "música", "efeitos"],
- sound_caption="faixa inteira 0:00–0:24",
- kinds={"m": "M", "l": "O", "h": "E"},
- evidence=[
- [("m", "60fps, sem repetir"), ("m", "ruído do sensor"), ("l", "mãos e texto ok")],
- [("m", "fundo estático"), ("m", "movimento local"), ("l", "UI de app real")],
- [("m", "24fps, repetições"), ("m", "tag AIGC"), ("l", "texto ilegível")],
- [("m", "ferramentas: 3D"), ("l", "VLM: parece IA"), ("l", "conflito ⚠")],
- [("m", "fundo estático"), ("m", "faixa de texto OCR"), ("l", "não foi filmado")],
- [("h", "sílabas a 3–8Hz"), ("h", "122 BPM, ré menor"), ("h", "cortes no tempo")],
- ],
- verdicts=[
- ("live", "Filmagem real", 0.96, None),
- ("screen", "Gravação de tela", 0.93, None),
- ("ai", "Vídeo de IA", 0.98, None),
- ("ai", "Vídeo de IA", 0.88, "o agente revisa visualmente"),
- ("code", "Render por código", 0.95, None),
- ("sound", "Voz + música de banco", 0.9, None),
- ],
- rule="Evidência concreta (tags AIGC, cadência de quadros) pesa mais que \"parece\"; planos com fontes em conflito vão para revisão visual do agente",
- plans={
- "s1": ("cam", ["Filmar", "1 cenário, 1 câmera", "ring light + celular"]),
- "s2": ("screen", ["Gravar", "material real", "nunca gerado"]),
- "s34": ("ai", ["2 planos em 1 geração", "prompt multiplano + 2 fotos + @original", "conforme o modelo: 10 s por chamada,", "saída multiplano, 2 imagens de referência"]),
- "s5": ("code", ["Programar", "projeto Remotion", "texto, layout, motion"]),
- "snd": ("sound", ["Três faixas", "voz: gravar ou TTS", "música: banco, 122 BPM", "efeitos: por tempo"]),
- },
- footer=("Relatório report.html · breakdown.json", "veredito em uma linha · remake dividido em filmar / gerar / programar · quadros, evidências e prompts por plano · legendas SRT / ASS"),
- )
- FR = dict(
- title="Un exemple : une vidéo produit découpée en 5 plans et le son, chaque plan passant par quatre étapes",
- subtitle="À l'horizontale, un plan des indices jusqu'au plan de remake ; à la verticale, les plans comparés à une même étape",
- steps=[
- ("1", "Découper", "couper en plans\nson en 3 pistes"),
- ("2", "Indices", "mesurer l'image\nregarder\nécouter"),
- ("3", "Trancher", "preuves d'abord\nconflits revus"),
- ("4", "Remake", "regrouper selon\nle modèle"),
- ],
- shots=["0:00–0:06", "0:06–0:11", "0:11–0:16", "0:16–0:21", "0:21–0:24"],
- sound_lanes=["voix", "musique", "effets"],
- sound_caption="piste entière 0:00–0:24",
- kinds={"m": "M", "l": "R", "h": "É"},
- evidence=[
- [("m", "60fps, sans doublon"), ("m", "bruit du capteur"), ("l", "mains, texte OK")],
- [("m", "fond statique"), ("m", "mouvement local"), ("l", "vraie UI d'app")],
- [("m", "24fps, doublons"), ("m", "tag AIGC"), ("l", "texte illisible")],
- [("m", "outils : rendu 3D"), ("l", "VLM : vidéo IA"), ("l", "conflit ⚠")],
- [("m", "fond statique"), ("m", "piste texte OCR"), ("l", "rien de filmé")],
- [("h", "syllabes 3–8Hz"), ("h", "122 BPM, ré mineur"), ("h", "coupes sur le temps")],
- ],
- verdicts=[
- ("live", "Tournage réel", 0.96, None),
- ("screen", "Écran enregistré", 0.93, None),
- ("ai", "Vidéo IA", 0.98, None),
- ("ai", "Vidéo IA", 0.88, "l'agent vérifie à l'œil"),
- ("code", "Rendu par code", 0.95, None),
- ("sound", "Voix + musique stock", 0.9, None),
- ],
- rule="Les preuves solides (tags AIGC, cadence d'images) priment sur « ça ressemble à » ; les plans où les sources divergent sont vérifiés à l'œil par l'agent",
- plans={
- "s1": ("cam", ["Tourner", "1 décor, 1 caméra", "ring light + téléphone"]),
- "s2": ("screen", ["Enregistrer", "vrai contenu", "jamais généré"]),
- "s34": ("ai", ["2 plans en 1 génération", "prompt multi-plan + 2 photos produit + @source", "selon le modèle : 10 s par appel,", "sortie multi-plan, 2 images de référence"]),
- "s5": ("code", ["Coder", "projet Remotion", "texte, layout, motion"]),
- "snd": ("sound", ["Trois pistes", "voix : enregistrée ou TTS", "musique libre, 122 BPM", "effets : selon le minutage"]),
- },
- footer=("Rapport report.html · breakdown.json", "verdict en une ligne · remake réparti en tourner / générer / coder · images, indices et prompts par plan · sous-titres SRT / ASS"),
- )
- DE = dict(
- title="Ein Beispiel: ein Produktvideo in 5 Shots plus Ton zerlegt, jeder Shot durchläuft vier Schritte",
- subtitle="Waagerecht: ein Shot vom Beleg bis zum Remake-Plan; senkrecht: die Shots eines Schritts im Vergleich",
- steps=[
- ("1", "Aufteilen", "in Shots schneiden\nTon in 3 Spuren"),
- ("2", "Belege", "Frames messen\nBilder ansehen\nhinhören"),
- ("3", "Urteil", "erst harte Belege\nKonflikte prüfen"),
- ("4", "Plan", "gebündelt nach\nModellfähigkeit"),
- ],
- shots=["0:00–0:06", "0:06–0:11", "0:11–0:16", "0:16–0:21", "0:21–0:24"],
- sound_lanes=["Stimme", "Musik", "SFX"],
- sound_caption="ganze Spur 0:00–0:24",
- kinds={"m": "M", "l": "S", "h": "H"},
- evidence=[
- [("m", "60fps, nie doppelt"), ("m", "Sensorrauschen"), ("l", "Hände, Text ok")],
- [("m", "Hintergrund fix"), ("m", "nur lokal bewegt"), ("l", "echte App-UI")],
- [("m", "24fps, Dubletten"), ("m", "AIGC-Tag"), ("l", "Text verstümmelt")],
- [("m", "Tools: wirkt 3D"), ("l", "VLM: wirkt KI"), ("l", "Widerspruch ⚠")],
- [("m", "Hintergrund fix"), ("m", "OCR-Textspur"), ("l", "keine Kameraspur")],
- [("h", "Silben 3–8Hz"), ("h", "122 BPM, d-Moll"), ("h", "Schnitte auf Beat")],
- ],
- verdicts=[
- ("live", "Realaufnahme", 0.96, None),
- ("screen", "Bildschirmaufnahme", 0.93, None),
- ("ai", "KI-Video", 0.98, None),
- ("ai", "KI-Video", 0.88, "Agent prüft visuell"),
- ("code", "Code-Rendering", 0.95, None),
- ("sound", "Stimme + Archivmusik", 0.9, None),
- ],
- rule="Harte Belege (AIGC-Tags, Frame-Takt) wiegen schwerer als „sieht aus wie“; Shots, bei denen die Quellen sich widersprechen, prüft der Agent visuell",
- plans={
- "s1": ("cam", ["Drehen", "1 Set, 1 Kamera", "Ringlicht + Handy"]),
- "s2": ("screen", ["Aufnehmen", "echtes Material", "nie generiert"]),
- "s34": ("ai", ["2 Shots in 1 Generierung", "Multi-Shot-Prompt + 2 Produktbilder + @Original", "nach Modellfähigkeit: 10 s pro Aufruf,", "Multi-Shot-Ausgabe, 2 Referenzbilder"]),
- "s5": ("code", ["Coden", "Remotion-Projekt", "Text, Layout, Motion"]),
- "snd": ("sound", ["Drei Spuren", "Stimme: selbst oder TTS", "Musik: Archiv, 122 BPM", "SFX: nach Zeitplan"]),
- },
- footer=("Bericht report.html · breakdown.json", "Fazit in einem Satz · Remake-Plan nach drehen / generieren / coden · Stills, Belege, Prompts pro Shot · Untertitel SRT / ASS"),
- )
- VI = dict(
- title="Ví dụ minh họa: 1 video bán hàng tách thành 5 shot và 3 lớp âm thanh, mỗi shot đi qua 4 bước",
- subtitle="Đọc ngang để theo 1 shot từ bằng chứng đến kế hoạch remake; đọc dọc để so các shot ở từng bước",
- steps=[
- ("1", "Tách", "chia từng shot\ntách âm 3 lớp"),
- ("2", "Chứng cứ", "đo frame\nxem ảnh\nnghe âm"),
- ("3", "Kết luận", "ưu tiên\nchứng cứ cứng\nsoát mâu thuẫn"),
- ("4", "Kế hoạch", "gom theo\nnăng lực của\nmodel đích"),
- ],
- shots=["0:00–0:06", "0:06–0:11", "0:11–0:16", "0:16–0:21", "0:21–0:24"],
- sound_lanes=["giọng", "nhạc", "SFX"],
- sound_caption="toàn đoạn 0:00–0:24",
- kinds={"m": "Đ", "l": "X", "h": "N"},
- evidence=[
- [("m", "60fps, không lặp"), ("m", "nhiễu cảm biến"), ("l", "tay, chữ rõ nét")],
- [("m", "nền đứng yên"), ("m", "chỉ động cục bộ"), ("l", "UI app thật")],
- [("m", "24fps, lặp khung"), ("m", "có nhãn AIGC"), ("l", "chữ trên hộp lỗi")],
- [("m", "tool: giống 3D"), ("l", "VLM: giống AI"), ("l", "mâu thuẫn ⚠")],
- [("m", "nền đứng yên"), ("m", "OCR ra text"), ("l", "không dấu quay")],
- [("h", "nhịp âm 3–8Hz"), ("h", "122 BPM, Rê thứ"), ("h", "cắt khớp nhịp")],
- ],
- verdicts=[
- ("live", "Quay thật", 0.96, None),
- ("screen", "Quay màn hình", 0.93, None),
- ("ai", "Video AI", 0.98, None),
- ("ai", "Video AI", 0.88, "agent xem ảnh chốt"),
- ("code", "Render code", 0.95, None),
- ("sound", "Giọng thật + nhạc kho", 0.9, None),
- ],
- rule="Bằng chứng cứng (nhãn AIGC, nhịp lặp frame) thắng cảm giác \"trông giống\"; shot có nguồn mâu thuẫn sẽ được gắn cờ cho agent xem ảnh kiểm tra",
- plans={
- "s1": ("cam", ["Tự quay", "1 bối cảnh, 1 máy", "đèn + điện thoại"]),
- "s2": ("screen", ["Ghi lại", "tư liệu thật", "không dùng AI tạo"]),
- "s34": ("ai", ["Gộp 2 shot vào 1 lần tạo", "prompt đa shot + 2 ảnh SP + @bản_gốc", "gom theo model: tối đa 10 giây/lần,", "xuất đa shot, nhận 2 ảnh tham chiếu"]),
- "s5": ("code", ["Viết code", "project Remotion", "chữ, bố cục, motion"]),
- "snd": ("sound", ["Ba lớp âm", "giọng: thu hoặc TTS", "nhạc: kho, 122 BPM", "SFX: theo mốc giờ"]),
- },
- footer=("Báo cáo report.html · breakdown.json", "kết luận 1 dòng · kế hoạch tách quay / tạo AI / code · ảnh từng shot, bằng chứng, prompt · phụ đề SRT / ASS"),
- )
- BN = dict(
- title="উদাহরণ: একটি প্রোডাক্ট ভিডিওকে ৫টি শট আর সাউন্ডে ভাগ করা, প্রতিটি শট চারটি ধাপ পার হয়",
- subtitle="পাশাপাশি পড়লে একটি শটের প্রমাণ থেকে রিমেক প্ল্যান; ওপর-নিচে পড়লে একই ধাপে শটগুলোর তুলনা",
- steps=[
- ("১", "ভাগ", "শট ধরে কাটা\nঅডিও ৩ ভাগে"),
- ("২", "প্রমাণ", "ফ্রেম মাপা\nছবি দেখা\nশব্দ শোনা"),
- ("৩", "রায়", "শক্ত প্রমাণ আগে\nগরমিল হলে\nআবার যাচাই"),
- ("৪", "প্ল্যান", "মডেলের\nসক্ষমতা\nঅনুযায়ী ভাগ"),
- ],
- shots=["0:00–0:06", "0:06–0:11", "0:11–0:16", "0:16–0:21", "0:21–0:24"],
- sound_lanes=["কণ্ঠ", "মিউজিক", "ইফেক্ট"],
- sound_caption="পুরো ট্র্যাক 0:00–0:24",
- kinds={"m": "মা", "l": "দে", "h": "শো"},
- evidence=[
- [("m", "60fps, রিপিট নেই"), ("m", "সেন্সর নয়েজ"), ("l", "হাত, লেখা ঠিক")],
- [("m", "স্থির ব্যাকগ্রাউন্ড"), ("m", "শুধু এক অংশ নড়ে"), ("l", "আসল অ্যাপ UI")],
- [("m", "24fps, রিপিট ছন্দ"), ("m", "AIGC ট্যাগ আছে"), ("l", "বাক্সে ভাঙা লেখা")],
- [("m", "টুল: 3D-র মতো"), ("l", "VLM: AI-র মতো"), ("l", "মতভেদ ⚠")],
- [("m", "স্থির ব্যাকগ্রাউন্ড"), ("m", "OCR-এ লেখা পাওয়া"), ("l", "ক্যামেরার ছাপ নেই")],
- [("h", "3–8Hz সিলেবল হার"), ("h", "122 BPM, D মাইনর"), ("h", "কাট পড়ে বিটে")],
- ],
- verdicts=[
- ("live", "আসল শুটিং", 0.96, None),
- ("screen", "স্ক্রিন রেকর্ডিং", 0.93, None),
- ("ai", "AI ভিডিও", 0.98, None),
- ("ai", "AI ভিডিও", 0.88, "এজেন্ট দেখে নিশ্চিত"),
- ("code", "কোড রেন্ডার", 0.95, None),
- ("sound", "কণ্ঠ + লাইব্রেরি মিউজিক", 0.9, None),
- ],
- rule="শক্ত প্রমাণ (AIGC ট্যাগ, ফ্রেমের ছন্দ) “দেখতে এমন লাগে”-র চেয়ে বেশি গুরুত্ব পায়; যে শটে উৎসগুলোর মতভেদ, সেটা এজেন্টের চোখে যাচাইয়ের জন্য চিহ্নিত হয়",
- plans={
- "s1": ("cam", ["নিজে শুট", "১ সিন, ১ ক্যামেরা", "রিং লাইট + ফোন"]),
- "s2": ("screen", ["নিজে রেকর্ড", "আসল ম্যাটেরিয়াল", "জেনারেট নয়"]),
- "s34": ("ai", ["২টি শট ১ বারে জেনারেট", "মাল্টি-শট প্রম্পট + ২টি প্রোডাক্ট ছবি + @মূল", "মডেলের সক্ষমতা অনুযায়ী: প্রতিবার ১০ সেকেন্ড,", "মাল্টি-শট আউটপুট, ২টি রেফারেন্স ছবি"]),
- "s5": ("code", ["কোড লেখা", "Remotion প্রজেক্ট", "লেখা, লেআউট, মোশন"]),
- "snd": ("sound", ["তিনটি ট্র্যাক", "কণ্ঠ: রেকর্ড বা TTS", "মিউজিক: লাইব্রেরি, 122 BPM", "ইফেক্ট: সময় ধরে"]),
- },
- footer=("রিপোর্ট report.html · breakdown.json", "এক লাইনের রায় · শুট / জেনারেট / কোডে ভাগ করা রিমেক প্ল্যান · প্রতি শটের স্থিরচিত্র, প্রমাণ, প্রম্পট · সাবটাইটেল SRT / ASS"),
- )
- TR = dict(
- title="Çözümlü bir örnek: bir ürün videosu 5 çekim artı sese bölünüyor, her çekim dört adımdan geçiyor",
- subtitle="Bir çekimi kanıttan yeniden yapım planına izlemek için yatay oku; bir adımda çekimleri karşılaştırmak için dikey oku",
- steps=[
- ("1", "Ayır", "çekimlere böl\nsesi 3'e ayır"),
- ("2", "Kanıt", "kareleri ölç\ngörüntüye bak\ndinle"),
- ("3", "Karar", "önce sağlam kanıt\nçelişkileri incele"),
- ("4", "Plan", "model yeteneğine\ngöre grupla"),
- ],
- shots=["0:00–0:06", "0:06–0:11", "0:11–0:16", "0:16–0:21", "0:21–0:24"],
- sound_lanes=["ses", "müzik", "efekt"],
- sound_caption="tüm parça 0:00–0:24",
- kinds={"m": "Ö", "l": "G", "h": "D"},
- evidence=[
- [("m", "60fps, tekrar yok"), ("m", "sensör gürültüsü"), ("l", "eller, yazı düzgün")],
- [("m", "sabit arka plan"), ("m", "kısmi hareket"), ("l", "gerçek uygulama")],
- [("m", "24fps tekrar ritmi"), ("m", "AIGC meta etiketi"), ("l", "kutuda bozuk yazı")],
- [("m", "araçlar: 3D gibi"), ("l", "VLM: AI gibi"), ("l", "çelişki ⚠")],
- [("m", "sabit arka plan"), ("m", "OCR metin izi"), ("l", "kamera izi yok")],
- [("h", "3–8Hz hece hızı"), ("h", "122 BPM, Re minör"), ("h", "kesmeler ritimde")],
- ],
- verdicts=[
- ("live", "Gerçek çekim", 0.96, None),
- ("screen", "Ekran kaydı", 0.93, None),
- ("ai", "AI video", 0.98, None),
- ("ai", "AI video", 0.88, "ajan görsel inceler"),
- ("code", "Kod render", 0.95, None),
- ("sound", "Ses + kütüphane müziği", 0.9, None),
- ],
- rule="Sağlam kanıt (AIGC etiketi, kare temposu) \"öyle görünüyor\"dan üstündür; kaynakların çeliştiği çekimler ajanın görsel incelemesi için işaretlenir",
- plans={
- "s1": ("cam", ["Kendin çek", "1 mekân, 1 kamera", "halka ışık + telefon"]),
- "s2": ("screen", ["Kaydet", "gerçek materyal", "asla üretilmez"]),
- "s34": ("ai", ["2 çekimi 1 üretimde birleştir", "çoklu çekim istemi + 2 ürün görseli + @kaynak", "model yeteneğine göre: çağrı başına 10 sn,", "çoklu çekim çıktı, 2 referans görsel"]),
- "s5": ("code", ["Kod yaz", "Remotion projesi", "metin, yerleşim, hareket"]),
- "snd": ("sound", ["Üç parça", "ses: kayıt ya da TTS", "müzik: kütüphane, 122 BPM", "efekt: zamana göre"]),
- },
- footer=("Rapor report.html · breakdown.json", "tek satırlık karar · çekim / üretim / kod olarak bölünmüş yeniden yapım planı · çekim başına kareler, kanıtlar, istemler · altyazı SRT / ASS"),
- )
- # ---------------------------------------------------------------- palette
- C = {
- "ink": "#0f172a", "mute": "#64748b", "line": "#cbd5e1", "band": "#f8fafc", "bg": "#ffffff",
- "live": "#16a34a", "screen": "#2563eb", "ai": "#9333ea", "code": "#d97706", "sound": "#0d9488",
- "live_bg": "#dcfce7", "screen_bg": "#dbeafe", "ai_bg": "#f3e8ff", "code_bg": "#fef3c7", "sound_bg": "#ccfbf1",
- "m_bg": "#e2e8f0", "m_fg": "#334155", "l_bg": "#ede9fe", "l_fg": "#5b21b6", "h_bg": "#ccfbf1", "h_fg": "#115e59",
- "warn": "#b45309", "warn_bg": "#fef3c7",
- }
- W, H = 1000, 738
- GX = 24 # gutter x
- COL0 = 134 # first column x
- COLW = 126
- GAP = 12
- SND_X = COL0 + 5 * (COLW + GAP) + 6 # 830
- SND_W = W - SND_X - 18 # 152
- ROWS = {"split": (84, 214), "evidence": (222, 338), "decide": (346, 466), "plan": (474, 636)}
- FONT_JA = "Hiragino Sans, Hiragino Kaku Gothic ProN, Yu Gothic, Meiryo, Noto Sans CJK JP, Noto Sans JP, sans-serif"
- FONT = "PingFang SC, Hiragino Sans GB, Microsoft YaHei, Noto Sans CJK SC, Source Han Sans SC, Segoe UI, Helvetica, Arial, sans-serif"
- FONT_KO = "Apple SD Gothic Neo, Malgun Gothic, Noto Sans CJK KR, Noto Sans KR, sans-serif"
- FONT_BN = "Kohinoor Bangla, Bangla Sangam MN, Nirmala UI, Vrinda, Noto Sans Bengali, Hind Siliguri, sans-serif"
- FONTS = {"ja": FONT_JA, "ko": FONT_KO, "bn": FONT_BN} # 其余语言和英文一样用 FONT
- def pick(lang, zh, ja, en):
- """字号:中文一档,日文 / 韩文一档,拉丁 / 西里尔字母一档。"""
- return zh if lang == "zh" else ja if lang in ("ja", "ko") else en
- def esc(s):
- return s.replace("&", "&").replace("<", "<").replace(">", ">")
- def col_x(i):
- return COL0 + i * (COLW + GAP)
- def text(x, y, s, size=13, fill=C["ink"], weight=None, anchor=None, extra=""):
- a = f' text-anchor="{anchor}"' if anchor else ""
- w = f' font-weight="{weight}"' if weight else ""
- return f'<text x="{x}" y="{y}" font-size="{size}" fill="{fill}"{w}{a}{extra}>{esc(s)}</text>'
- # ---------------------------------------------------------------- pictograms
- def thumb_frame(x, y, w, h, fill, extra=""):
- return f'<rect x="{x}" y="{y}" width="{w}" height="{h}" rx="8" fill="{fill}" stroke="{C["line"]}"/>{extra}'
- def sparkle(cx, cy, r, fill="#fff"):
- return (f'<path d="M{cx},{cy-r} Q{cx},{cy} {cx+r},{cy} Q{cx},{cy} {cx},{cy+r} Q{cx},{cy} {cx-r},{cy} Q{cx},{cy} {cx},{cy-r} Z" fill="{fill}"/>')
- def thumb_talk(x, y, w, h):
- cx = x + w / 2
- o = [f'<clipPath id="ct"><rect x="{x}" y="{y}" width="{w}" height="{h}" rx="8"/></clipPath>',
- f'<g clip-path="url(#ct)">',
- f'<rect x="{x}" y="{y}" width="{w}" height="{h}" fill="#fde7d6"/>',
- f'<rect x="{x}" y="{y}" width="{w}" height="{h*0.55}" fill="#fbd3b8"/>',
- # shoulders + head
- f'<path d="M{cx-34},{y+h} C{cx-34},{y+h-28} {cx-18},{y+h-32} {cx},{y+h-32} C{cx+18},{y+h-32} {cx+34},{y+h-28} {cx+34},{y+h} Z" fill="#f97316"/>',
- f'<circle cx="{cx}" cy="{y+h-48}" r="14" fill="#fed7aa"/>',
- f'<path d="M{cx-14},{y+h-50} a14,14 0 0 1 28,0 l0,-4 a14,10 0 0 0 -28,0 Z" fill="#7c2d12"/>',
- # mic
- f'<rect x="{cx+16}" y="{y+h-46}" width="6" height="12" rx="3" fill="#1f2937"/><path d="M{cx+19},{y+h-34} v6" stroke="#1f2937" stroke-width="1.6"/>',
- # subtitle bar
- f'<rect x="{x+14}" y="{y+h-16}" width="{w-28}" height="10" rx="3" fill="#fff" opacity="0.9"/>',
- f'<rect x="{x+26}" y="{y+h-13}" width="{w-52}" height="4" rx="2" fill="#f97316"/>',
- '</g>', f'<rect x="{x}" y="{y}" width="{w}" height="{h}" rx="8" fill="none" stroke="{C["line"]}"/>']
- return "".join(o)
- def thumb_phone(x, y, w, h):
- cx = x + w / 2
- px, py, pw, ph = cx - 22, y + 8, 44, h - 16
- o = [thumb_frame(x, y, w, h, "#e2e8f0"),
- f'<rect x="{px}" y="{py}" width="{pw}" height="{ph}" rx="7" fill="#0f172a"/>',
- f'<rect x="{px+3}" y="{py+6}" width="{pw-6}" height="{ph-12}" rx="4" fill="#fff"/>',
- f'<rect x="{px+8}" y="{py+12}" width="{pw-16}" height="5" rx="2" fill="#2563eb"/>',
- f'<rect x="{px+8}" y="{py+22}" width="{pw-20}" height="3" rx="1.5" fill="#94a3b8"/>',
- f'<rect x="{px+8}" y="{py+29}" width="{pw-24}" height="3" rx="1.5" fill="#94a3b8"/>',
- f'<rect x="{px+8}" y="{py+36}" width="{pw-18}" height="3" rx="1.5" fill="#94a3b8"/>',
- f'<rect x="{px+8}" y="{py+ph-22}" width="{pw-16}" height="9" rx="4" fill="#2563eb"/>',
- # cursor hand (a simple pointer)
- f'<path d="M{cx+10},{py+ph-14} l6,-6 l2,2 l-3,3 l6,0 l0,2 l-6,0 l3,3 l-2,2 Z" fill="#f97316" stroke="#fff" stroke-width="0.8"/>']
- return "".join(o)
- def thumb_product(x, y, w, h, close=False, cid="cp"):
- cx = x + w / 2
- o = [f'<clipPath id="{cid}"><rect x="{x}" y="{y}" width="{w}" height="{h}" rx="8"/></clipPath>',
- f'<g clip-path="url(#{cid})">',
- f'<rect x="{x}" y="{y}" width="{w}" height="{h}" fill="url(#gai)"/>',
- f'<ellipse cx="{cx}" cy="{y+h-10}" rx="{w*0.4}" ry="8" fill="#581c87" opacity="0.35"/>']
- if not close:
- # bottle
- o += [f'<rect x="{cx-11}" y="{y+22}" width="22" height="44" rx="6" fill="#faf5ff" stroke="#c084fc"/>',
- f'<rect x="{cx-6}" y="{y+14}" width="12" height="10" rx="2" fill="#a855f7"/>',
- f'<rect x="{cx-8}" y="{y+36}" width="16" height="14" rx="2" fill="#c084fc"/>',
- # gift box beside with garbled text
- f'<rect x="{cx+16}" y="{y+40}" width="26" height="26" rx="3" fill="#fbcfe8" stroke="#ec4899"/>',
- f'<path d="M{cx+16},{y+52} h26 M{cx+29},{y+40} v26" stroke="#ec4899" stroke-width="2"/>',
- text(cx + 19, y + 50, "ホ巿", 7, "#9d174d", extra=' font-family="monospace"'),
- sparkle(x + 18, y + 20, 7), sparkle(x + w - 20, y + 30, 5), sparkle(x + 30, y + h - 24, 4)]
- else:
- o += [f'<rect x="{cx-26}" y="{y+6}" width="52" height="{h}" rx="12" fill="#faf5ff" stroke="#c084fc"/>',
- f'<rect x="{cx-14}" y="{y-6}" width="28" height="18" rx="4" fill="#a855f7"/>',
- f'<rect x="{cx-20}" y="{y+34}" width="40" height="28" rx="4" fill="#c084fc"/>',
- f'<rect x="{cx-14}" y="{y+42}" width="28" height="4" rx="2" fill="#faf5ff"/>',
- f'<rect x="{cx-14}" y="{y+50}" width="18" height="4" rx="2" fill="#faf5ff"/>',
- sparkle(x + 16, y + 26, 6), sparkle(x + w - 18, y + 18, 7), sparkle(x + w - 26, y + h - 20, 4)]
- o += ['</g>', f'<rect x="{x}" y="{y}" width="{w}" height="{h}" rx="8" fill="none" stroke="{C["line"]}"/>']
- return "".join(o)
- def thumb_card(x, y, w, h, headline):
- o = [thumb_frame(x, y, w, h, "#0f172a"),
- f'<rect x="{x+14}" y="{y+16}" width="34" height="8" rx="4" fill="#f59e0b"/>',
- text(x + 14, y + 48, headline, 20, "#fff", 800),
- f'<rect x="{x+14}" y="{y+58}" width="{w-50}" height="4" rx="2" fill="#94a3b8"/>',
- f'<rect x="{x+14}" y="{y+66}" width="{w-70}" height="4" rx="2" fill="#94a3b8"/>',
- # mini bar chart
- f'<rect x="{x+w-38}" y="{y+52}" width="6" height="18" fill="#38bdf8"/>',
- f'<rect x="{x+w-29}" y="{y+44}" width="6" height="26" fill="#38bdf8"/>',
- f'<rect x="{x+w-20}" y="{y+34}" width="6" height="36" fill="#f59e0b"/>']
- return "".join(o)
- def waveform(x, y, w, h, kind, color, seed):
- """Deterministic pseudo-random bars for a lane."""
- import math
- n = 36
- step = w / n
- bars = []
- for i in range(n):
- t = i / n
- if kind == "voice":
- amp = 0.3 + 0.7 * abs(math.sin(i * 1.7 + seed)) * (0 if 0.42 < t < 0.5 or 0.75 < t < 0.8 else 1)
- elif kind == "music":
- amp = 0.45 + 0.55 * abs(math.sin(i * 0.9 + seed)) * (1 if i % 4 else 1.0)
- if i % 4 == 0:
- amp = 1.0
- else:
- amp = 1.0 if i in (5, 17, 29) else 0.08
- bh = max(1.5, amp * h)
- bars.append(f'<rect x="{x+i*step+0.5:.1f}" y="{y+(h-bh)/2:.1f}" width="{step-1.2:.1f}" height="{bh:.1f}" rx="1" fill="{color}"/>')
- return "".join(bars)
- def thumb_sound(x, y, w, h, lanes):
- o = [thumb_frame(x, y, w, h, "#f0fdfa")]
- lane_h = (h - 16) / 3
- cols = ["#f97316", "#0d9488", "#2563eb"]
- kinds = ["voice", "music", "sfx"]
- longest = max(len(n) for n in lanes)
- wx = 42 if longest <= 5 else 12 + longest * 7 # 标签长(俄 / 德等)时波形往右让
- for i, name in enumerate(lanes):
- ly = y + 8 + i * lane_h
- o.append(text(x + 8, ly + lane_h / 2 + 4, name, 10, C["mute"], 700))
- o.append(waveform(x + wx, ly + 3, w - wx - 8, lane_h - 6, kinds[i], cols[i], i * 2.3))
- return "".join(o)
- # ---------------------------------------------------------------- icons for plan cards
- def icon(kind, x, y, color):
- s = 20
- if kind == "cam":
- return (f'<rect x="{x}" y="{y+5}" width="{s}" height="{s-6}" rx="3" fill="none" stroke="{color}" stroke-width="2"/>'
- f'<circle cx="{x+s/2}" cy="{y+12}" r="4" fill="none" stroke="{color}" stroke-width="2"/>'
- f'<rect x="{x+6}" y="{y+1}" width="8" height="5" rx="1" fill="{color}"/>')
- if kind == "screen":
- return (f'<rect x="{x}" y="{y+2}" width="{s}" height="{s-7}" rx="2" fill="none" stroke="{color}" stroke-width="2"/>'
- f'<path d="M{x+6},{y+s} h8 M{x+s/2},{y+s-5} v5" stroke="{color}" stroke-width="2"/>'
- f'<circle cx="{x+s-5}" cy="{y+7}" r="2.5" fill="#ef4444"/>')
- if kind == "ai":
- return sparkle(x + 10, y + 10, 10, color) + sparkle(x + 19, y + 3, 4, color)
- if kind == "code":
- return (f'<path d="M{x+6},{y+3} l-6,7 l6,7 M{x+14},{y+3} l6,7 l-6,7 M{x+12},{y+1} l-4,18" '
- f'fill="none" stroke="{color}" stroke-width="2" stroke-linecap="round" stroke-linejoin="round"/>')
- if kind == "sound":
- return (f'<path d="M{x+2},{y+7} h5 l6,-5 v16 l-6,-5 h-5 Z" fill="{color}"/>'
- f'<path d="M{x+16},{y+6} q4,4 0,8 M{x+19},{y+3} q7,7 0,14" fill="none" stroke="{color}" stroke-width="2" stroke-linecap="round"/>')
- return ""
- # ---------------------------------------------------------------- main
- def build(S, lang):
- o = []
- o.append(f'<svg xmlns="http://www.w3.org/2000/svg" viewBox="0 0 {W} {H}" width="{W}" height="{H}" font-family="{FONTS.get(lang, FONT)}">')
- o.append('<defs>'
- '<marker id="ah" viewBox="0 0 10 10" refX="8" refY="5" markerWidth="7" markerHeight="7" orient="auto-start-reverse">'
- f'<path d="M0,0 L10,5 L0,10 z" fill="{C["mute"]}"/></marker>'
- '<linearGradient id="gai" x1="0" y1="0" x2="1" y2="1"><stop offset="0" stop-color="#c084fc"/><stop offset="1" stop-color="#6d28d9"/></linearGradient>'
- '<filter id="sh" x="-5%" y="-5%" width="110%" height="120%"><feDropShadow dx="0" dy="1.5" stdDeviation="2" flood-color="#0f172a" flood-opacity="0.10"/></filter>'
- '</defs>')
- o.append(f'<rect width="{W}" height="{H}" rx="18" fill="{C["bg"]}"/>')
- # title
- o.append(text(GX, 36, S["title"], pick(lang, 21, 19, 19), C["ink"], 800))
- o.append(text(GX, 60, S["subtitle"], 13, C["mute"]))
- # row bands
- for i, key in enumerate(["split", "evidence", "decide", "plan"]):
- y0, y1 = ROWS[key]
- if i % 2 == 0:
- o.append(f'<rect x="{GX-8}" y="{y0-6}" width="{W-2*GX+16}" height="{y1-y0+12}" rx="12" fill="{C["band"]}"/>')
- # column divider before sound
- dv = SND_X - 8
- o.append(f'<path d="M{dv},{ROWS["split"][0]-2} V{ROWS["plan"][1]+2}" stroke="{C["line"]}" stroke-width="1.5" stroke-dasharray="4 4"/>')
- # step labels in gutter
- step_colors = ["#0f172a", "#0f172a", "#0f172a", "#0f172a"]
- for (num, name, sub), key, colr in zip(S["steps"], ["split", "evidence", "decide", "plan"], step_colors):
- y0, y1 = ROWS[key]
- cy = y0 + 20
- o.append(f'<circle cx="{GX+13}" cy="{cy}" r="13" fill="{C["ink"]}"/>')
- o.append(text(GX + 13, cy + 5, num, 13, "#fff", 800, "middle"))
- o.append(text(GX + 32, cy + 5, name, pick(lang, 16, 15, 14), C["ink"], 800))
- for j, line in enumerate(sub.split("\n")):
- o.append(text(GX, cy + 26 + j * 17, line, 12, C["mute"]))
- # arrow to next row
- if key != "plan":
- ny0 = ROWS[["split", "evidence", "decide", "plan"][["split", "evidence", "decide", "plan"].index(key) + 1]][0]
- o.append(f'<path d="M{GX+13},{y1-4} V{ny0+2}" stroke="{C["mute"]}" stroke-width="1.6" marker-end="url(#ah)" fill="none"/>')
- # ---- row 1: split
- y0, y1 = ROWS["split"]
- ty = y0 + 6
- th = 84
- o.append(thumb_talk(col_x(0), ty, COLW, th))
- o.append(thumb_phone(col_x(1), ty, COLW, th))
- o.append(thumb_product(col_x(2), ty, COLW, th, False, "cp1"))
- o.append(thumb_product(col_x(3), ty, COLW, th, True, "cp2"))
- o.append(thumb_card(col_x(4), ty, COLW, th, "5折" if lang == "zh" else "50%"))
- o.append(thumb_sound(SND_X, ty, SND_W, th, S["sound_lanes"]))
- # filmstrip sprockets between frames
- for i in range(5):
- x = col_x(i)
- for k in range(6):
- o.append(f'<rect x="{x+6+k*22}" y="{ty+th+6}" width="8" height="5" rx="1.5" fill="{C["line"]}"/>')
- o.append(text(x + COLW / 2, ty + th + 28, f"{S['shots'][i]}", 11.5, C["mute"], None, "middle"))
- o.append(text(x + COLW / 2, ty + th + 28, "", 11))
- for i in range(4):
- x = col_x(i) + COLW
- o.append(f'<rect x="{x+1}" y="{ty+30}" width="{GAP-2}" height="24" fill="{C["line"]}" opacity="0.6"/>')
- o.append(text(SND_X + SND_W / 2, ty + th + 28, S["sound_caption"], 11.5, C["mute"], None, "middle"))
- # ---- row 2: evidence chips
- y0, y1 = ROWS["evidence"]
- kinds = S["kinds"]
- for i, chips in enumerate(S["evidence"]):
- x = col_x(i) if i < 5 else SND_X
- w = COLW if i < 5 else SND_W
- for j, (k, label) in enumerate(chips):
- cy = y0 + 8 + j * 32
- bg, fg = C[f"{k}_bg"], C[f"{k}_fg"]
- warn = "⚠" in label
- if warn:
- bg, fg = C["warn_bg"], C["warn"]
- o.append(f'<rect x="{x}" y="{cy}" width="{w}" height="26" rx="7" fill="{bg}"/>')
- o.append(f'<rect x="{x}" y="{cy}" width="22" height="26" rx="7" fill="{fg}" opacity="0.9"/>')
- o.append(f'<rect x="{x+14}" y="{cy}" width="8" height="26" fill="{fg}" opacity="0.9"/>')
- o.append(text(x + 11, cy + 18, kinds[k], 11.5, "#fff", 800, "middle"))
- o.append(text(x + 28, cy + 17.5, label.replace(" ⚠", ""), pick(lang, 11.5, 11, 10.5), fg, 600))
- # ---- row 3: verdict
- y0, y1 = ROWS["decide"]
- for i, (kind, label, conf, note) in enumerate(S["verdicts"]):
- x = col_x(i) if i < 5 else SND_X
- w = COLW if i < 5 else SND_W
- colr, bg = C[kind], C[f"{kind}_bg"]
- py = y0 + 6
- o.append(f'<rect x="{x}" y="{py}" width="{w}" height="30" rx="15" fill="{colr}"' + (f' stroke="{C["warn"]}" stroke-width="2" stroke-dasharray="4 3"' if note else "") + '/>')
- o.append(text(x + w / 2, py + 20, label, pick(lang, 13, 12.5, 11.5), "#fff", 800, "middle"))
- # confidence bar
- by = py + 42
- o.append(f'<rect x="{x}" y="{by}" width="{w}" height="6" rx="3" fill="{C["m_bg"]}"/>')
- o.append(f'<rect x="{x}" y="{by}" width="{w*conf:.0f}" height="6" rx="3" fill="{colr}"/>')
- o.append(text(x, by + 22, f"{int(conf*100)}%", 11, C["mute"], 700))
- if note:
- o.append(text(x, by + 40, "⚠ " + note, 10.5, C["warn"], 700))
- # rule line
- o.append(text(COL0, y1 - 4, S["rule"], pick(lang, 12, 11.5, 12), C["mute"]))
- # ---- row 4: plan cards
- y0, y1 = ROWS["plan"]
- cy0 = y0 + 16
- ch = 120
- layout = [("s1", col_x(0), COLW), ("s2", col_x(1), COLW), ("s34", col_x(2), COLW * 2 + GAP), ("s5", col_x(4), COLW), ("snd", SND_X, SND_W)]
- for key, x, w in layout:
- kind, lines = S["plans"][key]
- colr = {"cam": C["live"], "screen": C["screen"], "ai": C["ai"], "code": C["code"], "sound": C["sound"]}[kind]
- bg = {"cam": C["live_bg"], "screen": C["screen_bg"], "ai": C["ai_bg"], "code": C["code_bg"], "sound": C["sound_bg"]}[kind]
- o.append(f'<g filter="url(#sh)"><rect x="{x}" y="{cy0}" width="{w}" height="{ch}" rx="10" fill="{bg}" stroke="{colr}" stroke-opacity="0.35"/></g>')
- o.append(icon(kind, x + 12, cy0 + 12, colr))
- o.append(text(x + 40, cy0 + 28, lines[0], pick(lang, 14, 13, 12.5), colr, 800))
- for j, line in enumerate(lines[1:]):
- o.append(text(x + 12, cy0 + 52 + j * 21, line, pick(lang, 12, 11, 10.5), C["ink"]))
- # bracket joining shots 3+4 above the merged card
- bx0, bx1 = col_x(2) + 10, col_x(3) + COLW - 10
- o.append(f'<path d="M{bx0},{cy0-12} v6 H{bx1} v-6" fill="none" stroke="{C["ai"]}" stroke-width="2.2"/>')
- o.append(f'<path d="M{(bx0+bx1)/2},{cy0-6} v6" stroke="{C["ai"]}" stroke-width="2.2"/>')
- # ---- footer pipeline
- fy = ROWS["plan"][1] + 28
- fx = COL0
- fw = W - COL0 - 18
- o.append(f'<path d="M{GX+13},{ROWS["plan"][1]-4} V{fy+24} H{fx-8}" fill="none" stroke="{C["mute"]}" stroke-width="1.6" marker-end="url(#ah)"/>')
- name, sub = S["footer"]
- o.append(f'<g filter="url(#sh)"><rect x="{fx}" y="{fy}" width="{fw}" height="52" rx="12" fill="{C["ink"]}"/></g>')
- o.append(text(fx + 16, fy + 22, name, 14, "#fff", 800))
- o.append(text(fx + 16, fy + 41, sub, pick(lang, 11.5, 11.5, 11), "#cbd5e1"))
- o.append('</svg>')
- return "\n".join(o)
- if __name__ == "__main__":
- out = Path(sys.argv[1]) if len(sys.argv) > 1 else Path(__file__).resolve().parent.parent / "docs"
- (out / "rea-flow.svg").write_text(build(ZH, "zh"), encoding="utf-8")
- (out / "rea-flow_en.svg").write_text(build(EN, "en"), encoding="utf-8")
- (out / "rea-flow_ja.svg").write_text(build(JA, "ja"), encoding="utf-8")
- for lang, S in [("ko", KO), ("ru", RU), ("es", ES), ("pt", PT), ("fr", FR), ("de", DE), ("vi", VI), ("bn", BN), ("tr", TR)]:
- (out / f"rea-flow_{lang}.svg").write_text(build(S, lang), encoding="utf-8")
- print("written", out)
Ratings and comments
Sign in to rate this skill.
Sign inFree to use. If it’s helped, pass it on.