Back to search
dailypaper-skills
SkillGitHub
用Agent skills打造我的论文流水线
Safety scan
A static text scan, not a guarantee. Select the badge to see what was scanned and every finding.
Checked today
Badge for your README
Markdown
[](/listings/huangkiki--dailypaper-skills)HTML
<a href="/listings/huangkiki--dailypaper-skills"><img src="/api/listings/huangkiki--dailypaper-skills/badge.svg" alt="findsafeskills safety rating" /></a>Install
i
What was scanned
The files the safety scan read, as written by the repository's author and shown as plain text. Lines with a finding are marked.
README.md · README · 168 lines
View this file on GitHub (read at the repository's current version: the scan did not record which commit it read)
This file has changed since it was scanned, so this is not exactly the text that was scanned, and no line is marked. The findings are listed with the safety scan above.
- # dailypaper-skills 🗞️
- **简体中文** | [English](README.en.md)
- **每天一句话,筛论文、看锐评,把值得读的研究变成自己的笔记。**
- 这是我自己平时追论文、读论文用的一套 Agent skills。从 HuggingFace 和 arXiv 找新论文,按研究兴趣挑重点,再把重点论文读完,整理成带公式、图表和概念链接的 Markdown 笔记。
- ```text
- 今日论文推荐
- ```
- 一次跑完 **抓取 → 筛选 → 点评 → 重点论文笔记**。也可以直接丢一个 arXiv 链接,自动精读并保存到已配置的 Obsidian / Markdown 笔记库。
- [🎬 看演示](#-先看效果) · [🧭 常用指令](#-平时怎么用) · [🚀 开始使用](#-开始使用) · [📖 详细指南](docs/usage.md)
- ## 🎬 先看效果
- > ### [▶ 用 Claude Code 打造我的论文流水线|小红书视频](http://xhslink.com/o/1dhQCn40EWY)
- >
- > 我录的一段实际使用演示。想先看看这套东西怎么用,可以从这里开始。
- >
- > 视频展示的是早期 Claude Code 工作流;当前版本也提供 Codex、Cursor 等 Agent 的安装入口,安装方法以下文为准。
- 跑完后,你会拿到三类相互链接的内容:
- | 产物 | 你可以用它做什么 |
- | --- | --- |
- | 🗞️ **每日推荐页** | 先看“必读 / 值得看 / 可跳过”,决定今天读哪几篇;默认每天最多推荐 10 篇 |
- | 📝 **重点论文笔记** | 跟着研究问题、方法、公式、图表、实验和局限读懂一篇论文 |
- | 🔗 **概念笔记与目录** | 遇到术语顺着链接查,读到相关方法时找到以前的积累 |
- **点评是这套 skills 的一个重点。** 每篇都要说清楚:做了什么、和你的研究有什么关系、哪个设计值得借鉴、哪些结论还需要追问。可以尖锐,但要给出依据;摘要里没说的内容,会标明需要全文确认。
- 推荐页链接到重点论文,论文再链接到 `[[概念]]`。以下是默认目录下的产物结构示意,文件名和分类会随实际内容变化:
- ```text
- 你的笔记目录/
- ├── DailyPapers/
- │ └── YYYY-MM-DD-论文推荐.md ← 今日锐评、阅读优先级、逐篇点评
- └── 论文笔记/
- ├── 具体分类/MethodName.md ← 方法、公式、图表、实验与局限
- └── _概念/主题/Concept.md ← 定义、相关方法、关联论文
- ```
- [查看完整论文笔记模板](obsidian-templates/论文笔记模板.md)。用 Obsidian 浏览双向链接很方便,也可以用普通 Markdown 编辑器或项目自带的 [Web Viewer](docs/usage.md#可选在浏览器里看笔记)。
- ## 🧭 平时怎么用
- 装好后,在 Agent 对话里说你想做什么:
- | 场景 | 直接这样说 |
- | --- | --- |
- | 今天有哪些论文值得看 | `今日论文推荐` |
- | 几天没跟进,补一下 | `过去3天论文推荐` / `过去一周论文推荐` |
- | 发链接就精读并保存 | `https://arxiv.org/abs/2509.24527` |
- | 精读指定论文 | `读一下这篇论文 <arXiv 链接或 PDF 路径>` |
- | 按标题或上下文读论文 | `读一下 Diffusion Policy` / `帮我读这篇` |
- | 先抓住核心贡献 | `快速看一下这篇论文 <PDF 路径>` |
- | 带着问题看方法 | `批判性分析这篇论文 <PDF 路径>` |
- | 读已有收藏 | `读一下 Zotero 里的 Diffusion Policy` |
- | 看开源项目进展 | `GitHub 周榜` |
- | 移动笔记后刷新导航 | `更新索引` |
- **读论文默认就保存笔记。** 单独发送 arXiv 的 `/abs/`、`/pdf/` 或 `/html/` 链接,或说“读一下 XXX”“读一下这篇”“帮我读”,都会获取全文、完整解析并写入已配置的笔记库;保存成功后返回实际笔记路径,不再询问是否保存。快速摘要、批判分析和公式提取保留你要求的阅读深度,也默认保存相应笔记。明确说“只在聊天里回答”“不要保存”或指定其他输出位置时,以你的要求为准。论文身份不明确或保存路径配置缺失时,只补问具体缺项;作为其他任务引用的链接不会自动触发阅读。
- **单篇精读,锐评放最前。** 笔记标题后先给完整锐评,再展开元信息、摘要、方法和实验;聊天答复也先给判断。锐评覆盖真正的新意、最强证据、关键缺口或适用边界,以及值不值得读和复现。评价有来源,不为尖锐编造缺陷;快速摘要、公式提取或明确“只总结、不评价”仍按你的要求执行。
- **研究方向由你设置。** 默认关注大模型 RL、RL infra、世界模型 / JEPA、灵巧手与物理仿真;可以改成你自己的方向。推荐会结合历史去重,相关论文不足时不凑数。“必读”继续生成完整笔记,已有笔记会匹配并链接。
- **中英文跟随你的提问。** `Recommend papers from the past week` 会生成英文推荐和笔记;也可以明确说“用英文输出”或 “write in Chinese”。切换语言不会重命名已有目录和笔记。[语言说明](docs/usage.md#中英文自动切换)
- ## 🚀 开始使用
- 需要一个能读写文件、执行命令和联网的 Agent,以及 **Python 3.10+、Git、curl**。精读 PDF 需要 **Poppler**;Obsidian、Zotero 按需使用。[环境准备](docs/usage.md#1-准备运行环境)
- ### 1. 安装完整技能包
- ```bash
- git clone https://github.com/huangkiki/dailypaper-skills.git
- cd dailypaper-skills
- python3 install.py --agent codex
- ```
- 把 `codex` 换成你使用的 Agent:`claude`、`cursor`、`copilot`、`gemini`、`opencode` 或 `openclaw`。Windows 可将 `python3` 换成 `py -3`。安装器会一起复制七个技能及共享依赖。
- ### 2. 告诉它你的研究方向和保存位置
- 先创建个人配置,已有配置不会被覆盖:
- ```bash
- python3 skills/_shared/user_config.py --init
- ```
- 刷新或重启 Agent 会话,然后在对话中输入,替换成自己的目录和方向:
- ```text
- 帮我配置 dailypaper-skills,使用跨 Agent 的共享配置。
- 把 Markdown 保存到 /path/to/my-research-notes。
- 我关注 robot learning、VLA、世界模型和物理仿真。
- 每天最多推荐 10 篇。
- ```
- **默认无需额外 API key。** 筛选、点评和精读使用当前 Agent 的模型额度。输出目录可以是普通文件夹,也可以是你指定的 Obsidian 库。
- ### 3. 开始第一次推荐
- ```text
- 今日论文推荐
- ```
- Agent 会完成筛选、点评和重点论文笔记,并告诉你产物位置。想从一篇论文试起,直接发送 arXiv 链接或 `读一下这篇论文 <链接或 PDF 路径>`,读完会自动保存笔记。
- 升级、多 Agent 安装、自定义目录和排错见 [使用指南](docs/usage.md)。
- ## 🧩 里面有哪些 Skills
- 日常用 `daily-papers` 追新论文,用 `paper-reader` 读指定论文。抓取、点评和笔记三个阶段会自动衔接,需要补跑时也能单独调用。
- | Skill | 负责什么 |
- | --- | --- |
- | [`daily-papers`](skills/daily-papers/SKILL.md) | 一句话启动完整每日论文流程 |
- | [`paper-reader`](skills/paper-reader/SKILL.md) | arXiv 链接或阅读请求直接读并保存;支持精读、快速摘要、批判分析、本地 PDF、Zotero |
- | [`daily-papers-fetch`](skills/daily-papers-fetch/SKILL.md) | 从 HuggingFace Daily / Trending 与 arXiv 抓取、筛选、富化 |
- | [`daily-papers-review`](skills/daily-papers-review/SKILL.md) | 生成锐评、阅读优先级和推荐页 |
- | [`daily-papers-notes`](skills/daily-papers-notes/SKILL.md) | 重点笔记、概念补充、链接回填 |
- | [`generate-mocs`](skills/generate-mocs/SKILL.md) | 更新论文和概念的目录页 |
- | [`github-trending`](skills/github-trending/SKILL.md) | 开源项目日榜 / 周榜 / 月榜,以及仿真主题检索 |
- 我也会搭配 [Zotero AI Sidebar](https://github.com/huangkiki/zotero-ai-sidebar):用这套 skills 筛选和积累笔记,在 Zotero 里打开 PDF 时,用 Sidebar 即时问答、点译和追问。
- ## 💬 使用前你可能想知道
- **必须用 Obsidian 吗?** 不需要,指定一个本地 Markdown 输出目录即可。Zotero 也只在读取自己的文献库时需要。
- **会每天自动运行、自动上传笔记吗?** 默认由你发起,安装不会创建定时任务;阅读请求默认保存到本地笔记库,Git 自动提交、推送的配置默认关闭。Git 同步遵循有效配置和你已有的长期或当次授权,已有授权不重复询问。定时运行用宿主或系统调度。
- **这些 Agent 都能完整跑通吗?** 安装器提供多个目标,但完整流程需要文件、命令和网络能力。安装与脚本测试通过,不代表所有客户端都完成了端到端实测。[兼容与验证范围](docs/agents.md)
- **能换论文筛选方式吗?** 默认 `agent` 使用当前 Agent 评分,也可选 `keyword` 关键词筛选或 `jev` 专用 API;只有 Jev 需要额外的 `TYPESAFE_API_KEY`。[配置与旧版本迁移](docs/usage.md#3-配置并开始使用)
- <details>
- <summary>⚡ 可选 Jev:历史评分费用与耗时对照</summary>
- <!-- JEV_BENCHMARK_START -->
- 2026-10-05 的一次对照中,同一批 30 篇候选、两组均选 10 篇:GPT-6 Astra 评分约 **$0.109264 / 10.35 秒**,Jev 1.13.0 约 **$0.000576408 / 0.52 秒**,入选重合 **9/10**。按当时标准 API 标价折算,评分费用降低 **99.47%**,调用约快 **20 倍**。
- 这是计入主模型缓存的**单次评分环节测量**,不代表整个阅读流程的费用或账户实际账单;重合率也不等于人工质量评价。[原始证据与复现方法](docs/jev-benchmark.md)
- <!-- JEV_BENCHMARK_END -->
- </details>
- ## 🛠️ 开发与贡献
- [架构说明](ARCHITECTURE.md) · [Agent 接入](docs/agents.md) · [使用指南](docs/usage.md)
- ```bash
- python3 -m pip install -r web-viewer/requirements.txt
- python3 -m unittest discover -s tests -v
- ```
- 欢迎分享用法、适配反馈,或提交 Issue / PR。反馈问题时请附 Agent 与系统版本、失败阶段,以及去除敏感信息的日志。
- [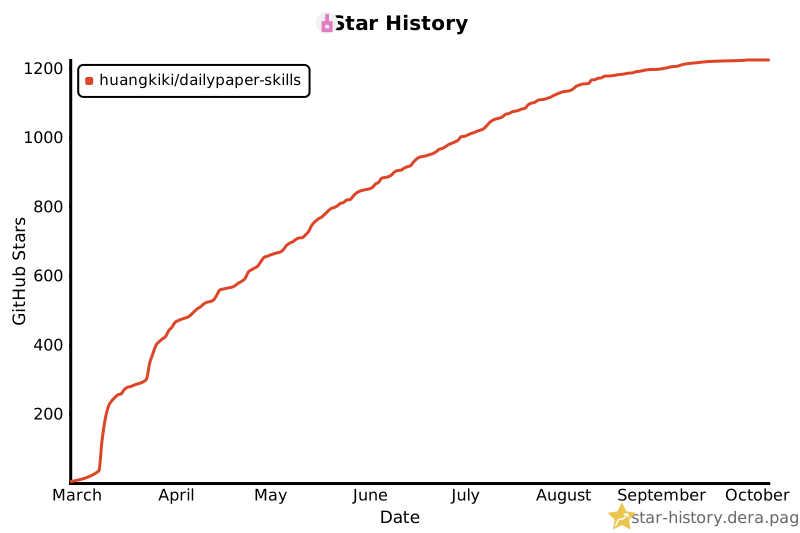](https://star-history.dera.page/#huangkiki/dailypaper-skills&Date)
- ## 📄 License
- Apache-2.0. See [LICENSE](LICENSE).
skills/paper-reader/paper_daemon.py · Bundled script · 788 lines · 1 finding marked
- #!/usr/bin/env python3
- """
- Paper Reading Daemon - 后台论文阅读守护进程
- 功能:
- 1. 从 Zotero 获取指定分类的论文列表(递归子分类)
- 2. 调用 Claude Code 逐篇处理
- 3. 遇到 rate limit 时自动等待并重试
- 4. 支持断点续传
- 用法:
- # 启动守护进程处理 VLA 分类
- screen -S paper-daemon
- python3 paper_daemon.py -c "VLA"
- # 查看进度
- python3 paper_daemon.py --status
- """
- import os
- import sys
- import json
- import sqlite3
- import subprocess
- import shutil
- import time
- import argparse
- import logging
- import re
- from pathlib import Path
- from datetime import datetime, timedelta
- from typing import Optional
- from zoneinfo import ZoneInfo
- _SHARED_DIR = Path(__file__).resolve().parents[1] / "_shared"
- if str(_SHARED_DIR) not in sys.path:
- sys.path.insert(0, str(_SHARED_DIR))
- from user_config import concepts_dir, obsidian_vault_path, paper_notes_dir, zotero_db_path, zotero_storage_dir, temp_file_path
- # 配置
- ZOTERO_DB = str(zotero_db_path())
- ZOTERO_STORAGE = str(zotero_storage_dir())
- OBSIDIAN_VAULT = str(obsidian_vault_path())
- PAPER_NOTES_ROOT = str(paper_notes_dir())
- CONCEPTS_ROOT = str(concepts_dir())
- _DAEMON_STATE_DIR = os.path.expanduser(os.environ.get("PAPER_DAEMON_STATE_DIR", "~/.claude"))
- PROGRESS_FILE = os.path.join(_DAEMON_STATE_DIR, "paper_daemon_progress.json")
- LOG_FILE = os.path.join(_DAEMON_STATE_DIR, "paper_daemon.log")
- PID_FILE = os.path.join(_DAEMON_STATE_DIR, "paper_daemon.pid")
- # Rate limit 配置
- INITIAL_WAIT = 60 # 初始等待时间(秒)
- MAX_WAIT = 21600 # 最大等待时间(6小时)
- WAIT_MULTIPLIER = 2 # 等待时间倍数
- BETWEEN_PAPERS_WAIT = 5 # 论文之间的等待时间(秒)
- QUOTA_WAIT_TIME = 1800 # 命中配额上限时的默认等待时间(30分钟)
- # 设置日志
- os.makedirs(os.path.dirname(LOG_FILE), exist_ok=True)
- logging.basicConfig(
- level=logging.INFO,
- format='%(asctime)s [%(levelname)s] %(message)s',
- handlers=[
- logging.FileHandler(LOG_FILE),
- logging.StreamHandler()
- ]
- )
- logger = logging.getLogger(__name__)
- _SUBSCRIPT_TRANSLATION = str.maketrans("₀₁₂₃₄₅₆₇₈₉₊₋", "0123456789+-")
- _GREEK_REPLACEMENTS = {
- "π": "pi",
- "ϕ": "phi",
- "φ": "phi",
- "α": "alpha",
- "β": "beta",
- "γ": "gamma",
- }
- def acquire_lock() -> bool:
- """获取进程锁,防止重复运行"""
- if os.path.exists(PID_FILE):
- with open(PID_FILE, 'r') as f:
- old_pid = f.read().strip()
- # 检查进程是否还在运行
- try:
- os.kill(int(old_pid), 0)
- return False # 进程还在运行
- except (OSError, ValueError):
- pass # 进程已结束,可以继续
- # 写入当前 PID
- with open(PID_FILE, 'w') as f:
- f.write(str(os.getpid()))
- return True
- def release_lock():
- """释放进程锁"""
- if os.path.exists(PID_FILE):
- os.remove(PID_FILE)
- def wait_for_quota_reset(wait_seconds: Optional[int] = None):
- """等待配额重置或人工恢复后再继续。"""
- if wait_seconds is None:
- wait_seconds = QUOTA_WAIT_TIME
- wait_minutes = max(1, wait_seconds // 60)
- logger.info(f"⏳ 配额受限,等待 {wait_minutes} 分钟...")
- time.sleep(wait_seconds)
- def detect_limit_error(output: str) -> Optional[str]:
- """识别限额/限速错误类型"""
- text = output.lower()
- if 'rate limit' in text or 'too many requests' in text:
- return 'RATE_LIMIT'
- if 'hit your limit' in text or 'usage limit' in text or 'resets' in text:
- return 'QUOTA_LIMIT'
- return None
- def parse_reset_wait_seconds(message: str) -> Optional[int]:
- """
- 解析 "resets 9pm (Asia/Shanghai)" 等提示,计算等待秒数
- """
- match = re.search(
- r'resets\s+(\d{1,2})(?::(\d{2}))?\s*(am|pm)?(?:\s*\(([^)]+)\))?',
- message,
- re.IGNORECASE
- )
- if not match:
- return None
- hour = int(match.group(1))
- minute = int(match.group(2) or 0)
- ampm = (match.group(3) or '').lower()
- tz_name = match.group(4) or 'Asia/Shanghai'
- if ampm == 'pm' and hour < 12:
- hour += 12
- if ampm == 'am' and hour == 12:
- hour = 0
- try:
- tz = ZoneInfo(tz_name)
- except Exception:
- return None
- now = datetime.now(tz)
- target = now.replace(hour=hour, minute=minute, second=0, microsecond=0)
- if target <= now:
- target = target + timedelta(days=1)
- wait_seconds = int((target - now).total_seconds())
- return max(60, wait_seconds)
- def copy_zotero_db() -> str:
- """复制 Zotero 数据库以避免锁定"""
- tmp_db = str(temp_file_path("zotero_readonly.sqlite"))
- shutil.copy(ZOTERO_DB, tmp_db)
- return tmp_db
- def get_collection_id_and_path(db_path: str, collection_name: str) -> tuple[Optional[int], Optional[str]]:
- """根据分类名称获取 ID 和完整路径"""
- conn = sqlite3.connect(db_path)
- cursor = conn.cursor()
- cursor.execute("SELECT collectionID, collectionName, parentCollectionID FROM collections")
- collections = {row[0]: {'name': row[1], 'parent': row[2]} for row in cursor.fetchall()}
- def get_path(cid):
- path_parts = []
- current = cid
- while current:
- if current in collections:
- path_parts.insert(0, collections[current]['name'])
- current = collections[current]['parent']
- else:
- break
- return '/'.join(path_parts)
- for cid, info in collections.items():
- if info['name'].lower() == collection_name.lower():
- conn.close()
- return cid, get_path(cid)
- if collection_name.lower() in info['name'].lower():
- conn.close()
- return cid, get_path(cid)
- conn.close()
- return None, None
- def get_all_child_collections(db_path: str, collection_id: int) -> list[int]:
- """递归获取所有子分类ID(包含自身)"""
- conn = sqlite3.connect(db_path)
- cursor = conn.cursor()
- cursor.execute("SELECT collectionID, parentCollectionID FROM collections")
- all_collections = cursor.fetchall()
- conn.close()
- children_map = {}
- for cid, parent_id in all_collections:
- if parent_id not in children_map:
- children_map[parent_id] = []
- children_map[parent_id].append(cid)
- result = [collection_id]
- def collect_children(cid):
- if cid in children_map:
- for child_id in children_map[cid]:
- result.append(child_id)
- collect_children(child_id)
- collect_children(collection_id)
- return result
- def get_papers_in_collection(db_path: str, collection_id: int) -> list[dict]:
- """获取分类下的所有论文(递归包含子分类)"""
- conn = sqlite3.connect(db_path)
- cursor = conn.cursor()
- collection_ids = get_all_child_collections(db_path, collection_id)
- placeholders = ','.join('?' * len(collection_ids))
- query = f"""
- SELECT DISTINCT i.itemID, idv.value as title
- FROM items i
- JOIN collectionItems ci ON i.itemID = ci.itemID
- JOIN itemData id ON i.itemID = id.itemID
- JOIN itemDataValues idv ON id.valueID = idv.valueID
- JOIN fields f ON id.fieldID = f.fieldID
- WHERE ci.collectionID IN ({placeholders}) AND f.fieldName = 'title' AND i.itemTypeID != 14
- """
- cursor.execute(query, collection_ids)
- logger.info(f"递归查询,包含 {len(collection_ids)} 个分类")
- papers = [{'item_id': row[0], 'title': row[1]} for row in cursor.fetchall()]
- conn.close()
- return papers
- def get_pdf_path(db_path: str, item_id: int) -> Optional[str]:
- """获取论文的 PDF 路径"""
- conn = sqlite3.connect(db_path)
- cursor = conn.cursor()
- cursor.execute("""
- SELECT ia.path, items.key
- FROM itemAttachments ia
- JOIN items ON ia.itemID = items.itemID
- WHERE ia.parentItemID = ? AND ia.contentType = 'application/pdf'
- """, (item_id,))
- row = cursor.fetchone()
- conn.close()
- if row:
- path, key = row
- if path and path.startswith('storage:'):
- filename = path.replace('storage:', '')
- return os.path.join(ZOTERO_STORAGE, key, filename)
- return None
- def get_paper_online_source(db_path: str, item_id: int) -> Optional[dict]:
- """
- 获取论文的在线来源信息(arXiv ID、DOI、URL)
- 用于处理没有 PDF 的论文
- """
- conn = sqlite3.connect(db_path)
- cursor = conn.cursor()
- # 获取论文的各种字段
- cursor.execute("""
- SELECT f.fieldName, idv.value
- FROM itemData id
- JOIN fields f ON id.fieldID = f.fieldID
- JOIN itemDataValues idv ON id.valueID = idv.valueID
- WHERE id.itemID = ?
- """, (item_id,))
- fields = {row[0]: row[1] for row in cursor.fetchall()}
- conn.close()
- result = {}
- # 检查 arXiv ID (可能在 extra 字段或 archiveID)
- extra = fields.get('extra', '')
- if 'arXiv:' in extra:
- # 格式: arXiv:2401.12345
- match = re.search(r'arXiv[:\s]+(\d{4}\.\d{4,5})', extra, re.IGNORECASE)
- if match:
- result['arxiv_id'] = match.group(1)
- # 检查 DOI
- doi = fields.get('DOI', '')
- if doi:
- result['doi'] = doi
- # 检查 URL
- url = fields.get('url', '')
- if url:
- result['url'] = url
- # 尝试从 URL 提取 arXiv ID
- if 'arxiv.org' in url and 'arxiv_id' not in result:
- match = re.search(r'arxiv\.org/(?:abs|pdf)/(\d{4}\.\d{4,5})', url)
- if match:
- result['arxiv_id'] = match.group(1)
- return result if result else None
- def get_existing_notes() -> dict[str, str]:
- """获取 Obsidian 中已有的笔记(返回 {方法名: 文件路径})"""
- existing = {}
- notes_dir = Path(PAPER_NOTES_ROOT)
- if notes_dir.exists():
- for md_file in notes_dir.rglob("*.md"):
- name = md_file.stem
- relative_parts = md_file.relative_to(notes_dir).parts
- # 跳过 _待整理, _概念 等特殊目录和目录页
- if any(part.startswith("_") for part in relative_parts):
- continue
- if md_file.parent.name == name:
- continue
- for method_name in _extract_note_method_names(name):
- existing[method_name] = str(md_file)
- return existing
- def title_matches_note(title: str, existing_notes: dict[str, str]) -> bool:
- """
- 检查论文标题是否与已有笔记匹配
- 只有精确匹配方法名时才返回 True
- """
- if not title:
- return False
- normalized_candidates = {
- _normalize_method_name(title.strip()),
- _normalize_method_name(title.split(':', 1)[0].strip()),
- }
- for method_normalized in normalized_candidates:
- if not method_normalized:
- continue
- for note_method in existing_notes.keys():
- # 完全相等
- if note_method == method_normalized:
- return True
- # 笔记方法名完全包含在标题方法名中(且长度相近)
- if note_method in method_normalized and len(note_method) > 3:
- # 确保不是太短的匹配(避免 "gs" 匹配 "3dgs")
- if len(note_method) >= len(method_normalized) * 0.5:
- return True
- return False
- def _normalize_method_name(value: str) -> str:
- normalized = value.strip().lower().translate(_SUBSCRIPT_TRANSLATION)
- for source, target in _GREEK_REPLACEMENTS.items():
- normalized = normalized.replace(source, target)
- normalized = normalized.replace("&", "and")
- return re.sub(r"[^a-z0-9]+", "", normalized)
- def _extract_note_method_names(stem: str) -> set[str]:
- candidates = {stem}
- match = re.match(r"^(?:19|20)\d{2}_(.+)$", stem)
- if match:
- candidates.add(match.group(1))
- return {
- normalized
- for candidate in candidates
- if (normalized := _normalize_method_name(candidate))
- }
- def load_progress() -> dict:
- """加载进度"""
- if os.path.exists(PROGRESS_FILE):
- with open(PROGRESS_FILE, 'r') as f:
- return json.load(f)
- return {'completed': [], 'failed': [], 'current': None, 'started_at': None}
- def save_progress(progress: dict):
- """保存进度"""
- os.makedirs(os.path.dirname(PROGRESS_FILE), exist_ok=True)
- with open(PROGRESS_FILE, 'w') as f:
- json.dump(progress, f, indent=2, ensure_ascii=False)
- def call_claude_code(paper_source: dict, collection_path: str, item_id: int) -> tuple[bool, str]:
- """
- 调用 Claude Code 处理论文
- paper_source 可以包含:
- - pdf_path: 本地 PDF 路径
- - arxiv_id: arXiv ID (如 2401.12345)
- - doi: DOI
- - url: 论文 URL
- - title: 论文标题 (用于搜索)
- """
- arxiv_id = paper_source.get('arxiv_id', '')
- notes_root = PAPER_NOTES_ROOT
- concepts_root = CONCEPTS_ROOT
- # 构建来源信息
- source_lines = []
- if paper_source.get('pdf_path'):
- source_lines.append(f"PDF 路径: {paper_source['pdf_path']}")
- if arxiv_id:
- source_lines.append(f"arXiv ID: {arxiv_id}")
- source_lines.append(f"arXiv 页面: https://arxiv.org/abs/{arxiv_id}")
- source_lines.append(f"arXiv PDF: https://arxiv.org/pdf/{arxiv_id}.pdf")
- source_lines.append(f"arXiv HTML (图片): https://arxiv.org/html/{arxiv_id}")
- if paper_source.get('doi'):
- source_lines.append(f"DOI: {paper_source['doi']}")
- source_lines.append(f"DOI 链接: https://doi.org/{paper_source['doi']}")
- if paper_source.get('url'):
- source_lines.append(f"URL: {paper_source['url']}")
- if paper_source.get('title'):
- source_lines.append(f"论文标题: {paper_source['title']}")
- source_info = '\n'.join(source_lines)
- # 如果没有 PDF,添加特殊说明
- no_pdf_instruction = ""
- if not paper_source.get('pdf_path'):
- fallback_steps = []
- if arxiv_id:
- fallback_steps.extend(
- [
- f"1. **arXiv HTML 版本**(推荐): 用 WebFetch 读取 https://arxiv.org/html/{arxiv_id},可直接获取图片 URL",
- f"2. **arXiv 摘要页**: 用 WebFetch 读取 https://arxiv.org/abs/{arxiv_id}",
- f"3. **arXiv PDF**: 下载 https://arxiv.org/pdf/{arxiv_id}.pdf 到本地后用 Read 读取",
- ]
- )
- if paper_source.get('doi'):
- fallback_steps.append(f"{len(fallback_steps) + 1}. **DOI 页面**: 跳转到 https://doi.org/{paper_source['doi']} 读取")
- if paper_source.get('url'):
- fallback_steps.append(f"{len(fallback_steps) + 1}. **原始 URL**: 读取 {paper_source['url']}")
- if not fallback_steps:
- fallback_steps.append("1. 根据标题搜索在线来源,再优先读取可直接获取图片的 HTML 版本")
- no_pdf_instruction = f"""
- ## 无本地 PDF - 在线获取(重要)
- 这篇论文没有本地 PDF,请按以下优先级获取内容:
- {chr(10).join(fallback_steps)}
- 优先使用 HTML 版本,因为可以直接获取在线图片链接!
- """
- prompt = f"""请使用 paper-reader skill 读取并分析这篇论文,生成完整的结构化笔记。
- {source_info}
- Zotero 分类路径: {collection_path}
- Zotero ItemID: {item_id}
- {no_pdf_instruction}
- ## 质量要求(重要)
- 参考高质量笔记风格,必须包含:
- 1. **元信息表格**: 机构、日期、项目主页、对比基线
- 2. **内联概念链接**: 在正文中使用 `[[Flow Matching]]`、`[[DiT]]` 链接概念,不只是在文末
- 3. **公式格式**: 每个公式包含 "含义" + "符号说明" 小节
- 4. **图片格式**: `### Figure X: 英文标题 / 中文标题` + 在线URL + `**说明**:`
- 5. **独立锐评**: 遵循 paper-reader 的锐评要求,完整锐评放在笔记标题后第一节,最终答复也以简短锐评开头;给出新意、最强证据、关键缺口或边界和明确判决,关键判断附来源,不把未核实当作缺失
- 6. **关联笔记分类**: 分为 "基于"、"对比"、"方法相关"、"硬件/数据相关"
- 7. **速查卡片**: ASCII 框格式的快速参考
- ## 处理规则
- 1. **图片优先在线链接**:先检查 arXiv HTML 版本 (arxiv.org/html/xxx),有则用在线图片 URL
- ## 概念库更新(必须执行)
- **每篇论文处理完后,必须为新遇到的技术概念创建笔记!**
- ### 概念库位置
- {concepts_root}
- ### 需要创建概念笔记的情况
- 1. 论文中首次遇到的技术术语(如 Flow Matching、Action Chunking、DiT)
- 2. 论文提出的新方法名(如果是通用概念)
- 3. 在笔记中使用了 [[概念]] 链接但该概念笔记不存在
- ### 概念笔记格式
- ```markdown
- ---
- type: concept
- aliases: [别名1, 别名2]
- ---
- # 概念名称
- ## 定义
- 一句话定义
- ## 数学形式(如有)
- $$公式$$
- ## 核心要点
- 1. 要点1
- 2. 要点2
- ## 代表工作
- - [[论文1]]: 说明
- - [[论文2]]: 说明
- ## 相关概念
- - [[相关概念1]]
- ```
- ### 概念目录结构(已存在的分类)
- - 1-生成模型/: Diffusion Model, DiT, VAE, Flow Matching, EDM, Latent Diffusion 等
- - 2-强化学习/: MDP, Policy, Value Function, PPO, GAIL, World Model 等
- - 3-机器人策略/: Action Chunking, Inverse Dynamics Model, Sim-to-Real 等
- - 4-足式运动/: CPG, Curriculum Learning, Privileged Learning 等
- - 5-导航与定位/: VLN 等
- - 如果是新领域,创建新的子目录(如 6-3D视觉/)
- ### 执行步骤
- 1. 分析完论文后,列出笔记中所有 [[概念]] 链接
- 2. 检查每个概念是否已存在:查看 `{concepts_root}` 下已有概念笔记
- 3. 对于不存在的概念,创建概念笔记文件
- 4. 使用 Write 工具写入概念笔记
- ## 自动分类与 Zotero 同步(重要)
- **不要依赖关键词匹配!** 你需要真正理解论文后自主判断分类。
- ### 分类判断原则
- 1. 理解论文的**核心贡献**是什么
- 2. 问自己:如果我要找这篇论文,我会去哪个分类找?
- 3. 按**主要贡献**分类,而不是使用的技术
- - 例:用 Diffusion 做机器人控制 → VLA,不是 Diffusion Model
- - 例:用 3DGS 做 SLAM → SLAM,不是 3DGS
- ### 分类操作
- 使用 zotero_helper.py 脚本:
- - collections: 列出所有分类
- - find-collection "名称": 查找分类ID
- - move <item_id> <collection_id>: 移动论文
- ### 何时必须移动
- - 当前在 "2025"、"杂项"、"feifeili" 等临时分类 → 必须移动
- - 分类与论文内容明显不符 → 移动
- ## 保存位置
- 根据你对论文的理解,保存到对应的 Obsidian 目录:
- - 基本结构:{notes_root}/对应分类路径/
- - 不确定时:{notes_root}/_待整理/
- 请直接开始处理,不需要确认。提取所有公式、图片和表格。"""
- try:
- result = subprocess.run(
- ['claude', '-p', prompt, '--model', 'opus', '--permission-mode', 'acceptEdits', '--dangerously-skip-permissions'],
- Note: Starts a coding agent with its permission prompts off
- Line 575 on GitHub
- capture_output=True,
- text=True,
- timeout=900 # 15分钟超时(因为要提取图片)
- )
- output = result.stdout + result.stderr
- limit_type = detect_limit_error(output)
- if limit_type == 'RATE_LIMIT':
- return False, 'RATE_LIMIT'
- if limit_type == 'QUOTA_LIMIT':
- return False, f'QUOTA_LIMIT|{output[:200]}'
- if result.returncode == 0:
- return True, ''
- else:
- return False, output[:500]
- except subprocess.TimeoutExpired:
- return False, 'TIMEOUT'
- except Exception as e:
- return False, str(e)
- def process_collection(collection_name: str, resume: bool = True):
- """处理整个分类的论文"""
- logger.info(f"=== 开始处理分类: {collection_name} ===")
- db_path = copy_zotero_db()
- collection_id, collection_path = get_collection_id_and_path(db_path, collection_name)
- if not collection_id:
- logger.error(f"找不到分类: {collection_name}")
- return
- logger.info(f"分类路径: {collection_path} (ID: {collection_id})")
- papers = get_papers_in_collection(db_path, collection_id)
- logger.info(f"分类下共有 {len(papers)} 篇论文")
- progress = load_progress() if resume else {'completed': [], 'failed': [], 'current': None, 'started_at': None}
- if not progress['started_at']:
- progress['started_at'] = datetime.now().isoformat()
- # 获取已有笔记
- existing_notes = get_existing_notes()
- logger.info(f"Obsidian 中已有 {len(existing_notes)} 篇笔记")
- # 过滤待处理论文
- pending = []
- skipped_existing = 0
- for paper in papers:
- item_id = paper['item_id']
- title = paper['title']
- if item_id in progress['completed']:
- continue
- # 检查是否已有笔记
- if title_matches_note(title, existing_notes):
- logger.info(f"跳过 (已有笔记): {title[:50]}")
- skipped_existing += 1
- progress['completed'].append(item_id) # 标记为已完成
- continue
- pdf_path = get_pdf_path(db_path, item_id)
- paper_source = {'title': title}
- if pdf_path and os.path.exists(pdf_path):
- paper_source['pdf_path'] = pdf_path
- else:
- # 尝试获取在线来源
- online_source = get_paper_online_source(db_path, item_id)
- if online_source:
- paper_source.update(online_source)
- logger.info(f"无本地 PDF,使用在线来源: {list(online_source.keys())}")
- else:
- logger.warning(f"跳过 (无PDF且无在线来源): {title[:50]}")
- continue
- pending.append({**paper, 'source': paper_source})
- if skipped_existing > 0:
- logger.info(f"跳过已有笔记: {skipped_existing} 篇")
- save_progress(progress)
- logger.info(f"待处理: {len(pending)} 篇")
- wait_time = INITIAL_WAIT
- for i, paper in enumerate(pending):
- item_id = paper['item_id']
- title = paper['title']
- paper_source = paper['source']
- source_type = "PDF" if paper_source.get('pdf_path') else "在线"
- logger.info(f"\n[{i+1}/{len(pending)}] 处理 ({source_type}): {title[:60]}...")
- progress['current'] = {'item_id': item_id, 'title': title}
- save_progress(progress)
- success, error = call_claude_code(paper_source, collection_path, item_id)
- if success:
- logger.info(f"✓ 完成: {title[:50]}")
- progress['completed'].append(item_id)
- progress['current'] = None
- save_progress(progress)
- wait_time = INITIAL_WAIT
- if i < len(pending) - 1:
- time.sleep(BETWEEN_PAPERS_WAIT)
- elif error == 'RATE_LIMIT':
- logger.warning(f"⏳ Rate limit, 等待 {wait_time} 秒...")
- time.sleep(wait_time)
- wait_time = min(wait_time * WAIT_MULTIPLIER, MAX_WAIT)
- pending.insert(i + 1, paper) # 重新加入队列
- elif error.startswith('QUOTA_LIMIT'):
- reset_wait = parse_reset_wait_seconds(error)
- if reset_wait:
- logger.warning(f"⏳ 用量上限,等待到重置(约 {reset_wait // 60} 分钟)...")
- time.sleep(reset_wait)
- else:
- wait_for_quota_reset()
- pending.insert(i + 1, paper) # 重新加入队列
- elif error == 'TIMEOUT':
- logger.error(f"✗ 超时: {title[:50]}")
- progress['failed'].append({'item_id': item_id, 'title': title, 'error': 'TIMEOUT'})
- save_progress(progress)
- else:
- logger.error(f"✗ 失败: {title[:50]} - {error[:100]}")
- progress['failed'].append({'item_id': item_id, 'title': title, 'error': error[:200]})
- save_progress(progress)
- progress['current'] = None
- progress['finished_at'] = datetime.now().isoformat()
- save_progress(progress)
- logger.info("\n=== 处理完成 ===")
- logger.info(f"成功: {len(progress['completed'])} 篇")
- logger.info(f"失败: {len(progress['failed'])} 篇")
- def show_status():
- """显示当前进度"""
- progress = load_progress()
- print("\n=== Paper Daemon 状态 ===")
- print(f"开始时间: {progress.get('started_at', 'N/A')}")
- print(f"完成时间: {progress.get('finished_at', '进行中...')}")
- print(f"已完成: {len(progress.get('completed', []))} 篇")
- print(f"失败: {len(progress.get('failed', []))} 篇")
- current = progress.get('current')
- if current:
- print(f"当前处理: {current.get('title', 'N/A')[:60]}")
- if progress.get('failed'):
- print("\n失败的论文:")
- for item in progress['failed'][:5]:
- print(f" - {item['title'][:50]}: {item['error'][:50]}")
- def main():
- parser = argparse.ArgumentParser(description='Paper Reading Daemon')
- parser.add_argument('--collection', '-c', type=str, help='Zotero 分类名称')
- parser.add_argument('--status', '-s', action='store_true', help='显示当前状态')
- parser.add_argument('--no-resume', action='store_true', help='不恢复之前的进度')
- parser.add_argument('--list', '-l', action='store_true', help='列出所有 Zotero 分类')
- args = parser.parse_args()
- if args.status:
- show_status()
- return
- if args.list:
- db_path = copy_zotero_db()
- conn = sqlite3.connect(db_path)
- cursor = conn.cursor()
- cursor.execute("""
- SELECT c.collectionName, COUNT(ci.itemID) as count
- FROM collections c
- LEFT JOIN collectionItems ci ON c.collectionID = ci.collectionID
- GROUP BY c.collectionID
- HAVING count > 0
- ORDER BY c.collectionName
- """)
- print("\n=== Zotero 分类 ===")
- for name, count in cursor.fetchall():
- print(f" {name}: {count} 篇")
- conn.close()
- return
- if not args.collection:
- parser.print_help()
- return
- # 检查是否已有进程在运行
- if not acquire_lock():
- logger.error("另一个 paper_daemon 进程正在运行!请先停止它或删除 ~/.claude/paper_daemon.pid")
- return
- try:
- process_collection(args.collection, resume=not args.no_resume)
- finally:
- release_lock()
- if __name__ == '__main__':
- main()
Ratings and comments
Sign in to rate this skill.
Sign inFree to use. If it’s helped, pass it on.