langextract
A Python library for extracting structured information from unstructured text using LLMs with precise source grounding and interactive visualization.
Safety scan
A static text scan, not a guarantee. Select the badge to see what was scanned and every finding.
Badge for your README

Markdown
[](/listings/google--langextract)HTML
<a href="/listings/google--langextract"><img src="/api/listings/google--langextract/badge.svg" alt="findsafeskills safety rating" /></a>Install
Install instructions from the README
As written by the repo's author. findsafeskills has not verified these steps.
> **Note:** Using cloud-hosted models like Gemini requires an API key. See the [API Key Setup](#api-key-setup-for-cloud-models) section for instructions on how to get and configure your key.
Extract structured information with just a few lines of code.
1. Define Your Extraction Task
First, create a prompt that clearly describes what you want to extract. Then, provide a high-quality example to guide the model.
import langextract as lx
import textwrap

# 1. Define the prompt and extraction rules
prompt = textwrap.dedent("""\
    Extract characters, emotions, and relationships in order of appearance.
    Use exact text for extractions. Do not paraphrase or overlap entities.
    Provide meaningful attributes for each entity to add context.""")

# 2. Provide a high-quality example to guide the model
examples = [
    lx.data.ExampleData(
        text="ROMEO. But soft! What light through yonder window breaks? It is the east, and Juliet is the sun.",
        extractions=[
            lx.data.Extraction(
                extraction_class="character",
                extraction_text="ROMEO",
                attributes={"emotional_state": "wonder"}
            ),
            lx.data.Extraction(
                extraction_class="emotion",
                extraction_text="But soft!",
                attributes={"feeling": "gentle awe"}
            ),
            lx.data.Extraction(
                extraction_class="relationship",
                extraction_text="Juliet is the sun",
                attributes={"type": "metaphor"}
            ),
        ]
    )
]> **Note:** Examples drive model behavior. Each `extraction_text` should ideally be verbatim from the example's `text` (no paraphrasing), listed in order of appearance. LangExtract raises `Prompt alignment` warnings by default if examples don't follow this pattern—resolve these for best results. > > **Grounding:** LLMs may occasionally extract content from few-shot examples rather than the input text. LangExtract automatically detects this: extractions that cannot be located in the source text will have `char_interval = None`. Filter these out with `[e for e in result.extractions if e.char_interval]` to keep only grounded results.
2. Run the Extraction
Provide your input text and the prompt materials to the `lx.extract` function.
# The input text to be processed
input_text = "Lady Juliet gazed longingly at the stars, her heart aching for Romeo"

# Run the extraction
result = lx.extract(
    text_or_documents=input_text,
    prompt_description=prompt,
    examples=examples,
    model_id="gemini-3.5-flash",
)For advanced constraints beyond examples, such as enum values on extraction attributes, Gemini and OpenAI support `output_schema` with or without few-shot examples. See [Custom output schemas](docs/examples/output_schema.md).
> **Model Selection**: `gemini-3.5-flash` is the recommended default, offering strong extraction quality for LangExtract's schema-constrained workflows. For high-volume or cost-sensitive workloads, consider the current stable Flash-Lite model, `gemini-3.1-flash-lite`; for highly complex tasks requiring deeper reasoning, evaluate a current Gemini Pro model from the official model documentation. For large-scale or production use, a paid Gemini tier is suggested to increase throughput and avoid rate limits. See the [rate-limit documentation](https://ai.google.dev/gemini-api/docs/rate-limits#usage-tiers) for details. > > **Model Lifecycle**: Note that Gemini models have a lifecycle with defined retirement dates. Users should consult the [official model version documentation](https://cloud.google.com/vertex-ai/generative-ai/docs/learn/model-versions) to stay informed about the latest stable and legacy versions.
3. Visualize the Results
What was scanned
The files the safety scan read, as written by the repository's author and shown as plain text. Lines with a finding are marked.
README.md · README · 545 lines
View this file on GitHub (read at the repository's current version: the scan did not record which commit it read)
- <p align="center">
- <a href="https://github.com/google/langextract">
- <img src="https://raw.githubusercontent.com/google/langextract/main/docs/_static/logo.svg" alt="LangExtract Logo" width="128" />
- </a>
- </p>
- # LangExtract
- [](https://pypi.org/project/langextract/)
- [](https://github.com/google/langextract)
- 
- [](https://doi.org/10.5281/zenodo.17015089)
- [](https://google-langextract.hf.space/)
- ## Table of Contents
- - [Introduction](#introduction)
- - [Why LangExtract?](#why-langextract)
- - [Quick Start](#quick-start)
- - [Installation](#installation)
- - [API Key Setup for Cloud Models](#api-key-setup-for-cloud-models)
- - [Adding Custom Model Providers](#adding-custom-model-providers)
- - [Using OpenAI Models](#using-openai-models)
- - [Using Local LLMs with Ollama](#using-local-llms-with-ollama)
- - [More Examples](#more-examples)
- - [*Romeo and Juliet* Full Text Extraction](#romeo-and-juliet-full-text-extraction)
- - [Medication Extraction](#medication-extraction)
- - [Radiology Report Structuring: RadExtract](#radiology-report-structuring-radextract)
- - [Community Providers](#community-providers)
- - [Contributing](#contributing)
- - [Testing](#testing)
- - [How to Cite](#how-to-cite)
- - [Disclaimer](#disclaimer)
- ## Introduction
- LangExtract is a Python library that uses LLMs to extract structured information from unstructured text documents based on user-defined instructions. It processes materials such as clinical notes or reports, identifying and organizing key details while ensuring the extracted data corresponds to the source text.
- <p align="center">
- <picture>
- <source media="(prefers-reduced-motion: reduce)" srcset="https://raw.githubusercontent.com/google/langextract/main/docs/_static/langextract_concept_still.png" />
- <img src="https://raw.githubusercontent.com/google/langextract/main/docs/_static/langextract_concept.gif" alt="LangExtract end to end: unstructured text is chunked, extracted in parallel by an LLM, and every extracted value is grounded back to its exact character span in the source" width="880" />
- </picture>
- </p>
- <p align="center">
- <b><a href="https://google-langextract.hf.space/">Try the live demo →</a></b><br>
- <sub>Run grounded extraction on <i>Romeo and Juliet</i> in your browser, no install required.</sub>
- </p>
- ## Why LangExtract?
- 1. **Precise Source Grounding:** Maps every extraction to its exact location in the source text, enabling visual highlighting for easy traceability and verification.
- 2. **Reliable Structured Outputs:** Enforces a consistent output schema based on your few-shot examples, leveraging controlled generation in supported models like Gemini to guarantee robust, structured results.
- 3. **Optimized for Long Documents:** Overcomes the "needle-in-a-haystack" challenge of large document extraction by using an optimized strategy of text chunking, parallel processing, and multiple passes for higher recall.
- 4. **Interactive Visualization:** Instantly generates a self-contained, interactive HTML file to visualize and review thousands of extracted entities in their original context.
- 5. **Flexible LLM Support:** Supports your preferred models, from cloud-based LLMs like the Google Gemini family to local open-source models via the built-in Ollama interface.
- 6. **Adaptable to Any Domain:** Define extraction tasks for any domain using just a few examples. LangExtract adapts to your needs without requiring any model fine-tuning.
- 7. **Leverages LLM World Knowledge:** Utilize precise prompt wording and few-shot examples to influence how the extraction task may utilize LLM knowledge. The accuracy of any inferred information and its adherence to the task specification are contingent upon the selected LLM, the complexity of the task, the clarity of the prompt instructions, and the nature of the prompt examples.
- ## Quick Start
- > **Note:** Using cloud-hosted models like Gemini requires an API key. See the [API Key Setup](#api-key-setup-for-cloud-models) section for instructions on how to get and configure your key.
- Extract structured information with just a few lines of code.
- ### 1. Define Your Extraction Task
- First, create a prompt that clearly describes what you want to extract. Then, provide a high-quality example to guide the model.
- ```python
- import langextract as lx
- import textwrap
- # 1. Define the prompt and extraction rules
- prompt = textwrap.dedent("""\
- Extract characters, emotions, and relationships in order of appearance.
- Use exact text for extractions. Do not paraphrase or overlap entities.
- Provide meaningful attributes for each entity to add context.""")
- # 2. Provide a high-quality example to guide the model
- examples = [
- lx.data.ExampleData(
- text="ROMEO. But soft! What light through yonder window breaks? It is the east, and Juliet is the sun.",
- extractions=[
- lx.data.Extraction(
- extraction_class="character",
- extraction_text="ROMEO",
- attributes={"emotional_state": "wonder"}
- ),
- lx.data.Extraction(
- extraction_class="emotion",
- extraction_text="But soft!",
- attributes={"feeling": "gentle awe"}
- ),
- lx.data.Extraction(
- extraction_class="relationship",
- extraction_text="Juliet is the sun",
- attributes={"type": "metaphor"}
- ),
- ]
- )
- ]
- ```
- > **Note:** Examples drive model behavior. Each `extraction_text` should ideally be verbatim from the example's `text` (no paraphrasing), listed in order of appearance. LangExtract raises `Prompt alignment` warnings by default if examples don't follow this pattern—resolve these for best results.
- >
- > **Grounding:** LLMs may occasionally extract content from few-shot examples rather than the input text. LangExtract automatically detects this: extractions that cannot be located in the source text will have `char_interval = None`. Filter these out with `[e for e in result.extractions if e.char_interval]` to keep only grounded results.
- ### 2. Run the Extraction
- Provide your input text and the prompt materials to the `lx.extract` function.
- ```python
- # The input text to be processed
- input_text = "Lady Juliet gazed longingly at the stars, her heart aching for Romeo"
- # Run the extraction
- result = lx.extract(
- text_or_documents=input_text,
- prompt_description=prompt,
- examples=examples,
- model_id="gemini-3.5-flash",
- )
- ```
- For advanced constraints beyond examples, such as enum values on extraction
- attributes, Gemini and OpenAI support `output_schema` with or without
- few-shot examples. See
- [Custom output schemas](docs/examples/output_schema.md).
- > **Model Selection**: `gemini-3.5-flash` is the recommended default, offering strong extraction quality for LangExtract's schema-constrained workflows. For high-volume or cost-sensitive workloads, consider the current stable Flash-Lite model, `gemini-3.1-flash-lite`; for highly complex tasks requiring deeper reasoning, evaluate a current Gemini Pro model from the official model documentation. For large-scale or production use, a paid Gemini tier is suggested to increase throughput and avoid rate limits. See the [rate-limit documentation](https://ai.google.dev/gemini-api/docs/rate-limits#usage-tiers) for details.
- >
- > **Model Lifecycle**: Note that Gemini models have a lifecycle with defined retirement dates. Users should consult the [official model version documentation](https://cloud.google.com/vertex-ai/generative-ai/docs/learn/model-versions) to stay informed about the latest stable and legacy versions.
- ### 3. Visualize the Results
- The extractions can be saved to a `.jsonl` file, a popular format for working with language model data. LangExtract can then generate an interactive HTML visualization from this file to review the entities in context.
- ```python
- # Save the results to a JSONL file
- lx.io.save_annotated_documents([result], output_name="extraction_results.jsonl", output_dir=".")
- # Generate the visualization from the file
- html_content = lx.visualize("extraction_results.jsonl")
- with open("visualization.html", "w", encoding="utf-8") as f:
- if hasattr(html_content, 'data'):
- f.write(html_content.data) # For Jupyter/Colab
- else:
- f.write(html_content)
- ```
- This creates an animated and interactive HTML file:
- 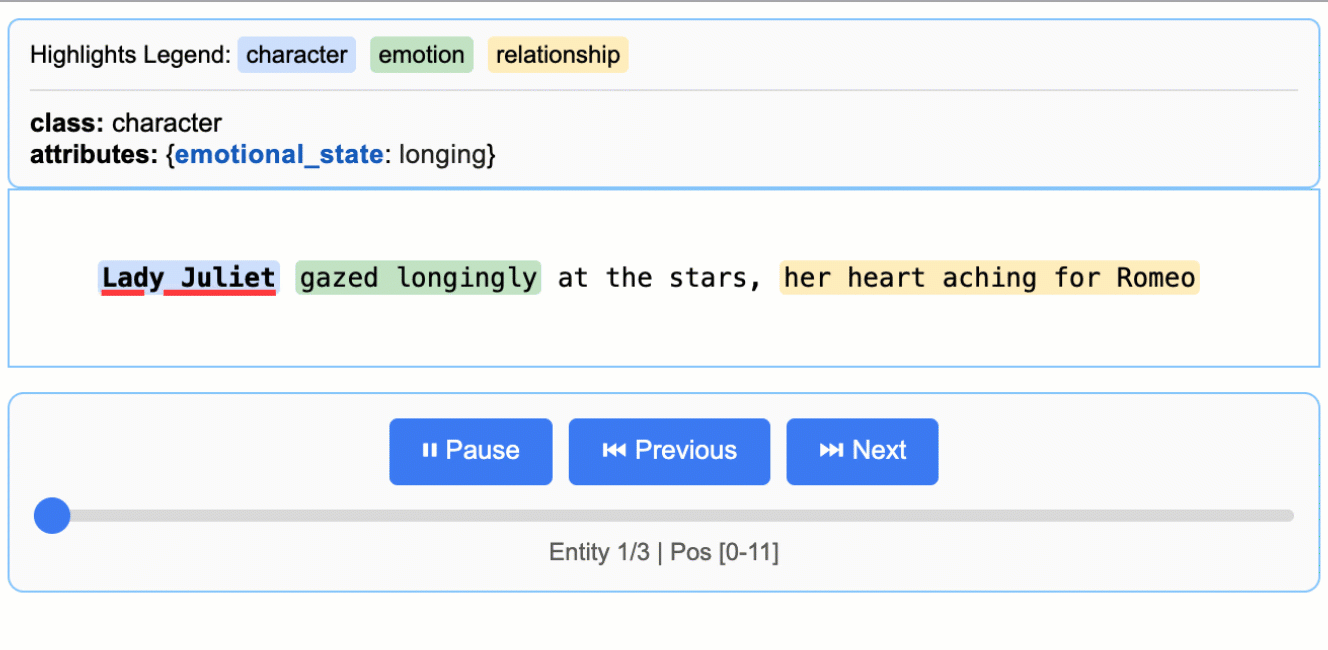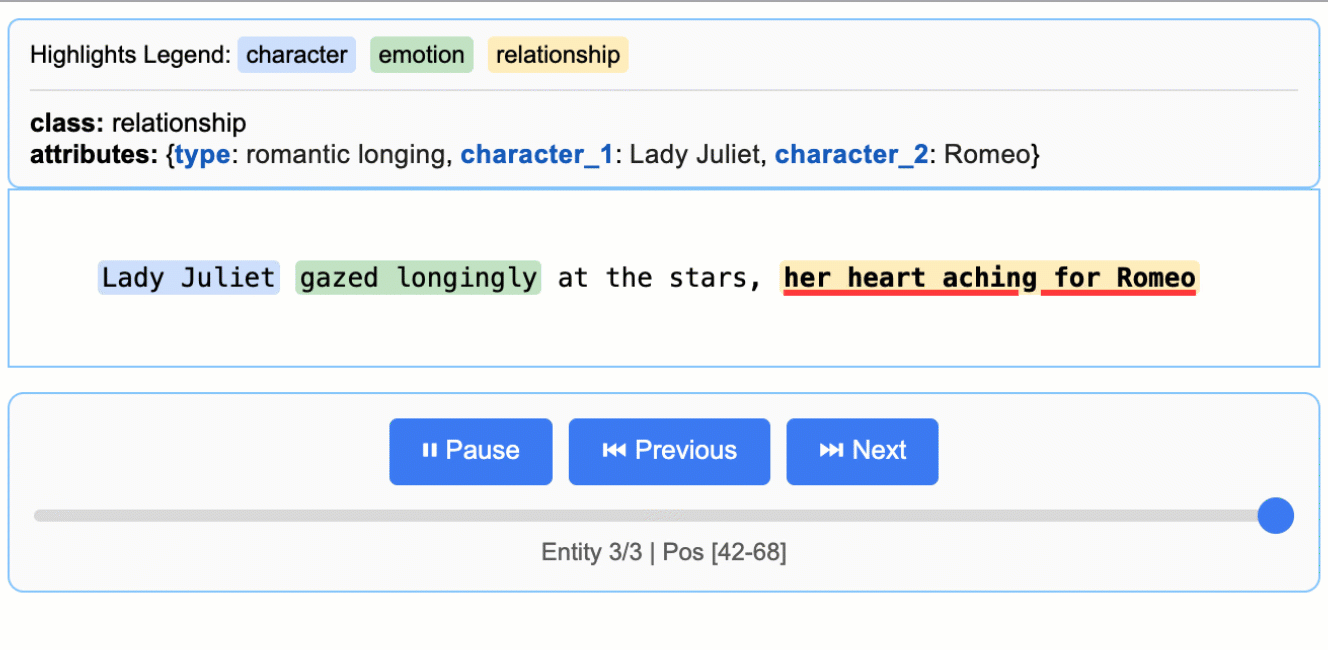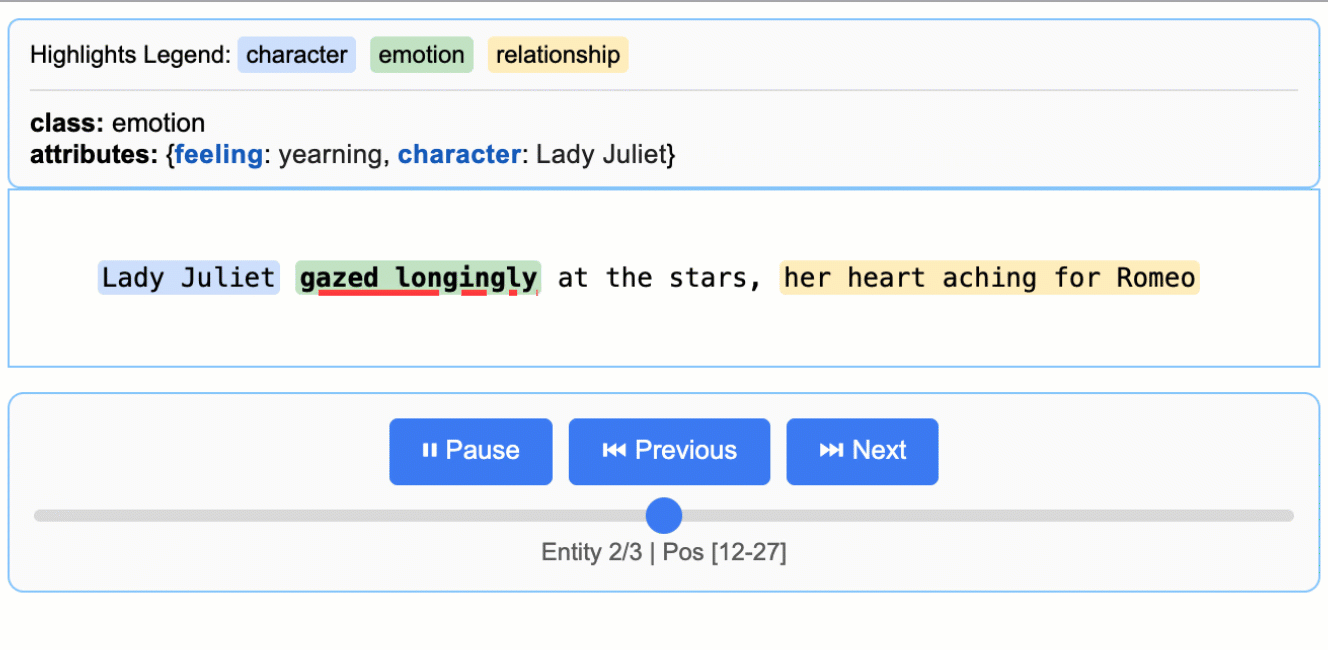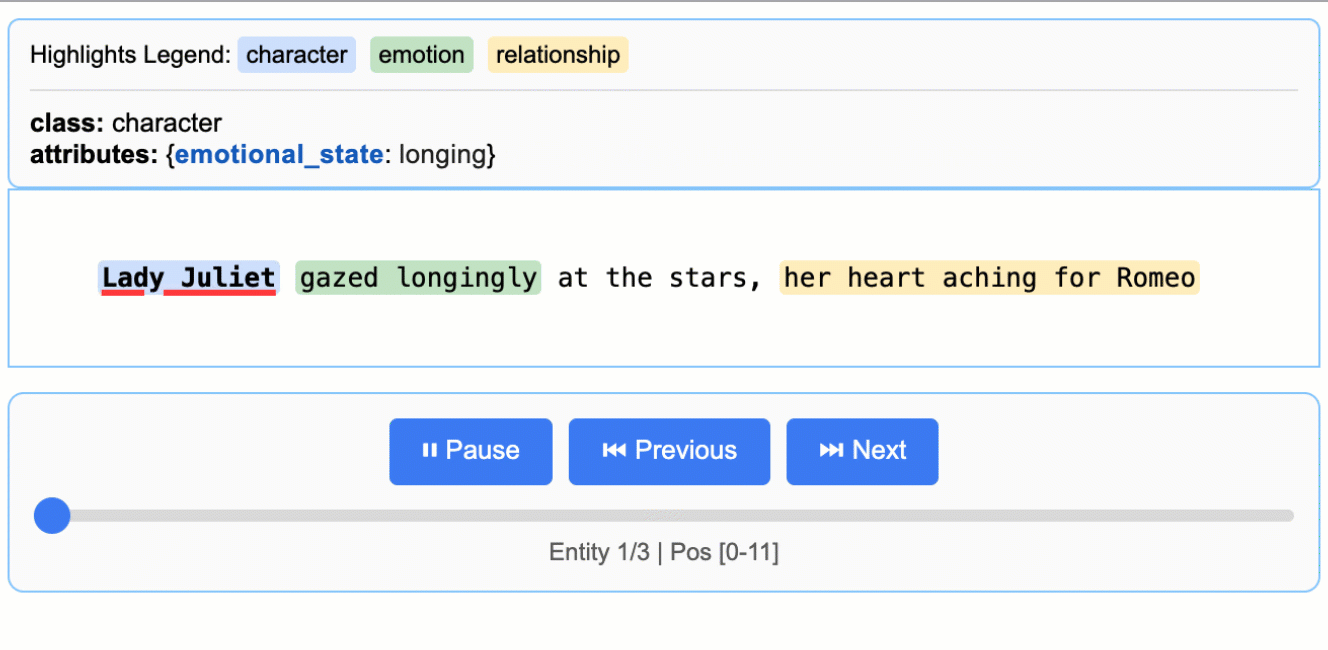
- > **Note on LLM Knowledge Utilization:** This example demonstrates extractions that stay close to the text evidence - extracting "longing" for Lady Juliet's emotional state and identifying "yearning" from "gazed longingly at the stars." The task could be modified to generate attributes that draw more heavily from the LLM's world knowledge (e.g., adding `"identity": "Capulet family daughter"` or `"literary_context": "tragic heroine"`). The balance between text-evidence and knowledge-inference is controlled by your prompt instructions and example attributes.
- ### Scaling to Longer Documents
- For larger texts, you can process entire documents directly from URLs with parallel processing and enhanced sensitivity:
- ```python
- # Process Romeo & Juliet directly from Project Gutenberg
- result = lx.extract(
- text_or_documents="https://www.gutenberg.org/files/1513/1513-0.txt",
- fetch_urls=True,
- prompt_description=prompt,
- examples=examples,
- model_id="gemini-3.5-flash",
- extraction_passes=3, # Improves recall through multiple passes
- max_workers=20, # Parallel processing for speed
- max_char_buffer=1000 # Smaller contexts for better accuracy
- )
- ```
- This approach can extract hundreds of entities from full novels while maintaining high accuracy. The interactive visualization seamlessly handles large result sets, making it easy to explore hundreds of entities from the output JSONL file. **[See the full *Romeo and Juliet* extraction example →](https://github.com/google/langextract/blob/main/docs/examples/longer_text_example.md)** for detailed results and performance insights.
- ### Vertex AI Batch Processing
- Save costs on large-scale tasks by enabling Vertex AI Batch API with
- `language_model_params` that include `vertexai=True`, `project`, `location`,
- and a `batch` config.
- See an example of the Vertex AI Batch API usage in [this example](docs/examples/batch_api_example.md).
- ## Installation
- ### From PyPI
- ```bash
- pip install langextract
- ```
- *Recommended for most users. For isolated environments, consider using a virtual environment:*
- ```bash
- python -m venv langextract_env
- source langextract_env/bin/activate # On Windows: langextract_env\Scripts\activate
- pip install langextract
- ```
- ### From Source
- LangExtract uses modern Python packaging with `pyproject.toml` for dependency management:
- *Installing with `-e` puts the package in development mode, allowing you to modify the code without reinstalling.*
- ```bash
- git clone https://github.com/google/langextract.git
- cd langextract
- # For basic installation:
- pip install -e .
- # For development (includes linting tools):
- pip install -e ".[dev]"
- # For testing (includes pytest):
- pip install -e ".[test]"
- ```
- ### Docker
- ```bash
- docker build -t langextract .
- docker run --rm -e LANGEXTRACT_API_KEY="your-api-key" langextract python your_script.py
- ```
- ## API Key Setup for Cloud Models
- When using LangExtract with cloud-hosted models (like Gemini or OpenAI), you'll need to
- set up an API key. On-device models don't require an API key. For developers
- using local LLMs, LangExtract offers built-in support for Ollama and can be
- extended to other third-party APIs by updating the inference endpoints.
- ### API Key Sources
- Get API keys from:
- * [AI Studio](https://aistudio.google.com/app/apikey) for Gemini models
- * [Vertex AI](https://cloud.google.com/vertex-ai/generative-ai/docs/sdks/overview) for enterprise use
- * [OpenAI Platform](https://platform.openai.com/api-keys) for OpenAI models
- ### Setting up API key in your environment
- **Option 1: Environment Variable**
- ```bash
- export LANGEXTRACT_API_KEY="your-api-key-here"
- ```
- **Option 2: .env File (Recommended)**
- Add your API key to a `.env` file:
- ```bash
- # Add API key to .env file
- cat >> .env << 'EOF'
- LANGEXTRACT_API_KEY=your-api-key-here
- EOF
- # Keep your API key secure
- echo '.env' >> .gitignore
- ```
- In your Python code:
- ```python
- import langextract as lx
- result = lx.extract(
- text_or_documents=input_text,
- prompt_description="Extract information...",
- examples=[...],
- model_id="gemini-3.5-flash"
- )
- ```
- **Option 3: Direct API Key (Not Recommended for Production)**
- You can also provide the API key directly in your code, though this is not recommended for production use:
- ```python
- result = lx.extract(
- text_or_documents=input_text,
- prompt_description="Extract information...",
- examples=[...],
- model_id="gemini-3.5-flash",
- api_key="your-api-key-here" # Only use this for testing/development
- )
- ```
- **Option 4: Vertex AI (Service Accounts)**
- Use [Vertex AI](https://cloud.google.com/vertex-ai/docs/start/introduction-unified-platform) for authentication with service accounts:
- ```python
- result = lx.extract(
- text_or_documents=input_text,
- prompt_description="Extract information...",
- examples=[...],
- model_id="gemini-3.5-flash",
- language_model_params={
- "vertexai": True,
- "project": "your-project-id",
- "location": "global" # or regional endpoint
- }
- )
- ```
- ## Adding Custom Model Providers
- LangExtract supports custom LLM providers via a lightweight plugin system. You can add support for new models without changing core code.
- - Add new model support independently of the core library
- - Distribute your provider as a separate Python package
- - Keep custom dependencies isolated
- - Override or extend built-in providers via priority-based resolution
- See the detailed guide in [Provider System Documentation](langextract/providers/README.md) to learn how to:
- - Register a provider with `@router.register(...)` from `langextract.providers`
- - Publish an entry point for discovery
- - Optionally provide a schema with `get_schema_class()` for structured output
- - Integrate with the factory via `create_model(...)`
- ## Using OpenAI Models
- LangExtract supports OpenAI models (requires optional dependency: `pip install langextract[openai]`):
- ```python
- import langextract as lx
- # OPENAI_API_KEY in the environment is picked up automatically; pass
- # api_key=... explicitly only if you need to override it.
- result = lx.extract(
- text_or_documents=input_text,
- prompt_description=prompt,
- examples=examples,
- model_id="gpt-4o", # Automatically selects OpenAI provider
- )
- ```
- The OpenAI provider uses structured outputs or JSON mode and auto-determines
- fence behavior — leave `fence_output` and `use_schema_constraints` unset.
- `output_schema` is also supported for OpenAI models that support structured
- outputs; provide a LangExtract output-envelope JSON schema, preferably with the
- `lx.schema` helpers.
- For large, non-latency-sensitive OpenAI workloads, enable the OpenAI Batch API
- with `language_model_params`. Batch mode is opt-in and falls back to realtime
- calls when the prompt count is below the configured threshold.
- ```python
- result = lx.extract(
- text_or_documents=documents,
- prompt_description=prompt,
- examples=examples,
- model_id="gpt-4o-mini",
- language_model_params={
- "batch": {
- "enabled": True,
- "threshold": 50,
- "poll_interval": 10,
- }
- },
- )
- ```
- For OpenAI-compatible endpoints or non-GPT model IDs (which skip auto-routing), use `ModelConfig` with an explicit provider:
- ```python
- from langextract.factory import ModelConfig
- result = lx.extract(
- text_or_documents=input_text,
- prompt_description=prompt,
- examples=examples,
- config=ModelConfig(
- model_id="my-openai-compatible-model",
- provider="openai",
- provider_kwargs={"api_key": "sk-...", "base_url": "https://..."},
- ),
- )
- ```
- ## Using Local LLMs with Ollama
- LangExtract supports local inference using Ollama, allowing you to run models without API keys:
- ```python
- import langextract as lx
- result = lx.extract(
- text_or_documents=input_text,
- prompt_description=prompt,
- examples=examples,
- model_id="gemma2:2b", # Automatically selects Ollama provider
- model_url="http://localhost:11434",
- )
- ```
- The Ollama provider exposes `FormatModeSchema` for JSON mode. Leave `fence_output`
- and `use_schema_constraints` unset so the factory auto-configures from the provider's
- schema. Ollama does not currently support `output_schema`.
- **Quick setup:** Install Ollama from [ollama.com](https://ollama.com/), run `ollama pull gemma2:2b`, then `ollama serve`.
- For detailed installation, Docker setup, and examples, see [`examples/ollama/`](examples/ollama/).
- ## More Examples
- Additional examples of LangExtract in action:
- ### *Romeo and Juliet* Full Text Extraction
- LangExtract can process complete documents directly from URLs. This example demonstrates extraction from the full text of *Romeo and Juliet* from Project Gutenberg (147,843 characters), showing parallel processing, sequential extraction passes, and performance optimization for long document processing.
- **[View *Romeo and Juliet* Full Text Example →](https://github.com/google/langextract/blob/main/docs/examples/longer_text_example.md)**
- ### Medication Extraction
- > **Disclaimer:** This demonstration is for illustrative purposes of LangExtract's baseline capability only. It does not represent a finished or approved product, is not intended to diagnose or suggest treatment of any disease or condition, and should not be used for medical advice.
- LangExtract excels at extracting structured medical information from clinical text. These examples demonstrate both basic entity recognition (medication names, dosages, routes) and relationship extraction (connecting medications to their attributes), showing LangExtract's effectiveness for healthcare applications.
- **[View Medication Examples →](https://github.com/google/langextract/blob/main/docs/examples/medication_examples.md)**
- ### Radiology Report Structuring: RadExtract
- Explore RadExtract, a live interactive demo on HuggingFace Spaces that shows how LangExtract can automatically structure radiology reports. Try it directly in your browser with no setup required.
- **[View RadExtract Demo →](https://google-radextract.hf.space/)**
- ## Community Providers
- Extend LangExtract with custom model providers! Check out our [Community Provider Plugins](COMMUNITY_PROVIDERS.md) registry to discover providers created by the community or add your own.
- For detailed instructions on creating a provider plugin, see the [Custom Provider Plugin Example](examples/custom_provider_plugin/).
- ## Contributing
- Contributions are welcome! See [CONTRIBUTING.md](https://github.com/google/langextract/blob/main/CONTRIBUTING.md) to get started
- with development, testing, and pull requests. You must sign a
- [Contributor License Agreement](https://cla.developers.google.com/about)
- before submitting patches.
- Thanks to everyone who has [contributed](https://github.com/google/langextract/graphs/contributors).
- ## Testing
- To run tests locally from the source:
- ```bash
- # Clone the repository
- git clone https://github.com/google/langextract.git
- cd langextract
- # Install with test dependencies
- pip install -e ".[test]"
- # Run all tests
- pytest tests
- ```
- Or reproduce the full CI matrix locally with tox:
- ```bash
- tox # runs pylint + pytest on Python 3.10 and 3.11
- ```
- ### Ollama Integration Testing
- If you have Ollama installed locally, you can run integration tests:
- ```bash
- # Test Ollama integration (requires Ollama running with gemma2:2b model)
- tox -e ollama-integration
- ```
- This test will automatically detect if Ollama is available and run real inference tests.
- ## Development
- ### Code Formatting
- This project uses automated formatting tools to maintain consistent code style:
- ```bash
- # Auto-format all code
- ./autoformat.sh
- # Or run formatters separately
- isort langextract tests --profile google --line-length 80
- pyink langextract tests --config pyproject.toml
- ```
- ### Pre-commit Hooks
- For automatic formatting checks:
- ```bash
- pre-commit install # One-time setup
- pre-commit run --all-files # Manual run
- ```
- ### Linting
- Run linting before submitting PRs:
- ```bash
- pylint --rcfile=.pylintrc langextract tests
- ```
- See [CONTRIBUTING.md](CONTRIBUTING.md) for full development guidelines.
- ## How to Cite
- If you use LangExtract in your research, please cite it:
- ```bibtex
- @software{goel_langextract,
- author = {Goel, Akshay},
- title = {{LangExtract}},
- year = {2026},
- version = {1.6.0},
- doi = {10.5281/zenodo.21126643},
- url = {https://github.com/google/langextract}
- }
- ```
- Cite the version you used — each release has its own DOI on
- [Zenodo](https://doi.org/10.5281/zenodo.17015089). If your style rejects
- `@software`, use `@misc`.
- ## Disclaimer
- This is not an officially supported Google product. If you use
- LangExtract in production or publications, please cite accordingly and
- acknowledge usage. Use is subject to the [Apache 2.0 License](https://github.com/google/langextract/blob/main/LICENSE).
- For health-related applications, use of LangExtract is also subject to the
- [Health AI Developer Foundations Terms of Use](https://developers.google.com/health-ai-developer-foundations/terms).
- ---
- **Happy Extracting!**
Ratings and comments
Sign in to rate this skill.
Sign inFree to use. If it’s helped, pass it on.