gemini-cli-mcp-server
A production-ready Model Context Protocol (MCP) server that bridges Google's Gemini CLI with MCP-compatible clients like Claude Code and Claude Desktop. This enterprise-grade Gemini MCP server…
Safety scan
A static text scan, not a guarantee. Select the badge to see what was scanned and every finding.
Badge for your README

Markdown
[](/listings/centminmod--gemini-cli-mcp-server)HTML
<a href="/listings/centminmod--gemini-cli-mcp-server"><img src="/api/listings/centminmod--gemini-cli-mcp-server/badge.svg" alt="findsafeskills safety rating" /></a>Install
Install instructions from the README
As written by the repo's author. findsafeskills has not verified these steps.
These steps run a script from the network that findsafeskills does not scan.
Prerequisites
- **Python 3.10+** - Required for MCP SDK compatibility - **Gemini CLI** - Google's command-line tool for Gemini AI - **uv** (recommended) or pip for package management
Linux Setup
# Install uv (recommended package manager)
curl -LsSf https://astral.sh/uv/install.sh | sh

# Clone the repository
git clone https://github.com/centminmod/gemini-cli-mcp-server.git
cd gemini-cli-mcp-server

# Create and activate virtual environment
uv venv
source .venv/bin/activate

# Install dependencies
uv pip install -r requirements.txt

# Install and configure Gemini CLI
npm install -g @google-ai/gemini-cli
gemini config set api_key YOUR_GEMINI_API_KEY

# Verify installation
gemini --version
python mcp_server.py --help
macOS Setup
# Install uv via Homebrew (or use curl installer above)
brew install uv

# Clone the repository
git clone https://github.com/centminmod/gemini-cli-mcp-server.git
cd gemini-cli-mcp-server

# Create and activate virtual environment
uv venv
source .venv/bin/activate

# Install dependencies
uv pip install -r requirements.txt

# Install Gemini CLI (if not already installed)
npm install -g @google-ai/gemini-cli
# Or via Homebrew: brew install gemini-cli

# Configure Gemini CLI
gemini config set api_key YOUR_GEMINI_API_KEY

# Verify installation
gemini --version
python mcp_server.py --help
Alternative Installation (pip)
# Using standard Python tools
python -m venv venv
source venv/bin/activate  # On Windows: venv\Scripts\activate
pip install -r requirements.txt

# Configure Gemini CLI
gemini config set api_key YOUR_GEMINI_API_KEY
What was scanned
The files the safety scan read, as written by the repository's author and shown as plain text. Lines with a finding are marked.
README.md · README · 1,734 lines
View this file on GitHub (read at the repository's current version: the scan did not record which commit it read)
- [](https://github.com/centminmod/gemini-cli-mcp-server/stargazers) [](https://github.com/centminmod/gemini-cli-mcp-server/network) [](https://github.com/centminmod/gemini-cli-mcp-server/issues)
- # Gemini CLI MCP Server
- A production-ready Model Context Protocol (MCP) server that bridges Google's Gemini CLI with MCP-compatible clients like Claude Code and Claude Desktop. This enterprise-grade Gemini MCP server features OpenRouter AI API integration for access to 400+ AI models and provides 33 specialized tools for seamless multi-AI workflows between Claude, Gemini, and 400+ additional models.
- On Claude Desktop:
- 
- 
- **Example 1:** Claude Code calling one of the 33 MCP tools, `gemini_prompt`:
- ```bash
- @gemini_prompt("Analyse @mcp_server.py codebase and modules explaining what this code does, think deeply before responding")
- ```
- 
- **Example 2:** Claude Code Custom Slash Command Prompt + Claude & Gemini CLI MCP Server Teamwork
- Setup Claude Code custom slash command prompt `/test-gemini-prompt-analyse-teamwork` within Git repo project at `.claude/commands/test-mcp/test-gemini-prompt-analyse-teamwork.md`. When you invoke this command, Claude Code Sonnet 4 first performs a deep analysis of the Gemini CLI MCP server code. It then delegates the same codebase to Google Gemini 2.5 Flash via the MCP tool’s `@gemini_prompt()` (note that Flash may be rate-limited on free tiers). Finally, Claude Code Sonnet 4 synthesizes both sets of insights into a single, consolidated report.
- Click `View Screenshots` to see example.
- <details>
- <summary>View Screenshots: Claude & Gemini Teamwork Analysis</summary>
- 
- 
- 
- 
- </details>
- **Example 3:** Claude Code Custom Slash Command Prompt + Claude & Gemini CLI MCP Server Comphrensive Review
- Setup Claude Code custom slash command prompt `.claude/commands/workflow-orchestrators/comprehensive-review.md` within Git repo project at `.claude/commands/workflow-orchestrators/comprehensive-review.md`. When you invoke this command, Claude Code Sonnet 4 first performs a comphrensive review of the Gemini CLI MCP server code and writes a report. It then asks Google Gemini 2.5 Flash via the MCP tool’s `@gemini_prompt()` (note that Flash may be rate-limited on free tiers) to verify and evaluate the generated report and add it's findings to the report.
- Click `View Screenshots` to see example.
- <details>
- <summary>View Screenshots: Comprehensive Review Workflow</summary>
- 
- 
- 
- 
- </details>
- **Example 4:** Extended: Claude Code Custom Slash Command Prompt + Claude & Gemini CLI MCP Server Comphrensive Review + Claude Response To Gemini Analysis.
- Setup Claude Code custom slash command prompt `.claude/commands/workflow-orchestrators/comprehensive-review.md` within Git repo project at `.claude/commands/workflow-orchestrators/comprehensive-review.md`. When you invoke this command, Claude Code Sonnet 4 first performs a comphrensive review of the Gemini CLI MCP server code and writes a report. It then asks Google Gemini 2.5 Flash via the MCP tool’s `@gemini_prompt()` (note that Flash may be rate-limited on free tiers) to verify and evaluate the generated report and add it's findings to the report. Then finally ask Claude to respond to Gemini CLI MCP server's analysis.
- Click `View Screenshots` to see example.
- <details>
- <summary>View Screenshots: Extended Analysis with Claude Response</summary>
- 
- 
- 
- 
- </details>
- **Example 5:** Claude Code with Gemini CLI MCP Server With OpenRouter API support
- Extended Gemini CLI MCP server with Openrouter API support to access 400+ LLM models. Click `View Screenshots` to see example of Claude Code chatting with Openai GP4 4.1-nano, Mistral AI devstral-small and DeepSeek R1 0528.
- <details>
- <summary>View Screenshots: Claude Code with Gemini CLI MCP Server With OpenRouter API support</summary>
- 
- 
- </details>
- **Example 6:** Claude Code with Gemini CLI MCP Server AI Collaboration
- The Gemini CLI MCP server includes OpenRouter API support for accessing 400+ LLM models. The `@gemini_ai_collaboration` MCP tool enables multiple AI models to engage in structured conversations, collaborations, or debates. This allows Gemini 2.5 models (via Gemini CLI) to collaborate with OpenRouter-based models like OpenAI GPT-4, Anthropic Claude, and others.
- In the example below, Gemini 2.5 Flash debates with OpenAI GPT-4.1-mini through Claude Code. Claude Code (Sonnet 4) orchestrates the debate and has full access to the conversation context, enabling sophisticated multi-AI workflows.
- ~~~bash
- @gemini_ai_collaboration(
- collaboration_mode="debate",
- content="Should we use microservices or monolith?",
- models="gemini-2.5-flash,openai/gpt-4.1-mini",
- rounds=4,
- debate_style="constructive"
- )
- ~~~
- 
- Using Gemini CLI MCP in Claude Desktop with same MCP tool:
- 
- 
- Or `validation` mode with Gemini 2.5 Flash, OpenAI GPT-4.1-mini and Anthropic Claude 3 Haiku.
- ~~~bash
- @gemini_ai_collaboration(
- collaboration_mode="validation",
- content="@mcp_server.py", # or multiple files
- models="gemini-2.5-flash,openai/gpt-4.1-mini,anthropic/cla
- ude-3-haiku",
- validation_criteria="code_quality,performance,security,mai
- ntainability,best_practices,documentation",
- confidence_threshold=0.8,
- consensus_method="weighted_majority",
- conflict_resolution="detailed_analysis",
- context="Code review for production deployment",
- budget_limit=5.00
- )
- ~~~
- 
- **Example 7:** Claude Code natural language prompt calling Gemini CLI MCP server's Openrouter LLM model, OpenAI GPT 4.1-nano.
- Claude Code natural language prompt calling Gemini CLI MCP server's Openrouter LLM model, OpenAI GPT 4.1-nano.
- Click `View Screenshots` to see example.
- <details>
- <summary>View Screenshots: Extended Analysis with Claude Response</summary>
- Seems there is a bug in that it says it gets `4o-mini` but I wanted/d`o get 4.1-nano` model as asked.
- 
- 
- OpenRouter Usage Activity for OpenAI GPT 4.1-nano
- 
- Gemini CLI MCP server uses Cloudflare AI Gateway proxies for Gemini CLI itself and also for OpenRouter integration. But AI Gateway records it as 4.1-mini and not 4.1-nano.
- 
- 
- </details>
- ## 🚀 Key Features
- - **33 Specialized MCP Tools** - Complete toolset for multi-AI integration across 6 tool categories
- - **400+ AI Models** - Access to OpenAI, Anthropic, Meta, Google, and 20+ providers via OpenRouter integration
- - **Enterprise Architecture** - Refactored modular design with 83 Python files organized across multiple specialized modules
- - **Conversation History** - Stateful multi-turn conversations with Redis-backed storage and cross-platform support
- - **Dynamic Token Limits** - Tool-specific limits from 100K-800K characters with model-aware scaling
- - **Multi-AI Workflows** - Purpose-built tools for plan evaluation, code review, and cross-platform collaboration
- - **@filename Support** - Direct file reading with intelligent large file handling strategies for 32 tools
- - **Enterprise Security** - 22 critical security fixes with multi-layer defense and real-time protection
- - **Production Ready** - 2,500+ test cases, enterprise monitoring with OpenTelemetry + Prometheus
- - **High Concurrency** - Async architecture supporting 1,000-10,000+ concurrent requests with 10-100x improvement
- ## 📋 Table of Contents
- - [Architecture Overview](#%EF%B8%8F-architecture-overview)
- - [Tool Suite](#%EF%B8%8F-tool-suite)
- - [Core Gemini Tools](#core-gemini-tools-6)
- - [System Tools](#system-tools-3)
- - [Analysis Tools](#analysis-tools-5)
- - [Conversation Tools](#conversation-tools-5)
- - [Specialized Code Review Tools](#specialized-code-review-tools-3)
- - [Content Comparison Tools](#content-comparison-tools-1)
- - [AI Collaboration Tools](#ai-collaboration-tools-1)
- - [OpenRouter Tools](#openrouter-tools-6)
- - [Installation](#-installation)
- - [MCP Client Configuration](#%EF%B8%8F-mcp-client-configuration)
- - [Usage Examples](#-usage-examples)
- - [Advanced Features](#-advanced-features)
- - [Configuration](#%EF%B8%8F-configuration)
- - [Performance](#-performance)
- - [Testing](#-testing)
- - [Troubleshooting](#-troubleshooting)
- ## 🏗️ Architecture Overview
- The Gemini CLI MCP Server features a modular, enterprise-grade architecture designed for reliability, performance, and maintainability. Built on proven architectural patterns and production-ready design decisions.
- ```text
- ┌─────────────────┐ ┌──────────────────┐ ┌─────────────────┐
- │ Claude Code │ ← → │ MCP Protocol │ ← → │ Gemini CLI │
- │ MCP Client │ │ (JSON-RPC 2.0) │ │ Integration │
- └─────────────────┘ └──────────────────┘ └─────────────────┘
- ↑ ↑ ↑
- ┌─────────┐ ┌─────────────┐ ┌─────────────┐
- │ 33 MCP │ │ FastMCP │ │ Google │
- │ Tools │ │ Server │ │ Gemini AI │
- └─────────┘ └─────────────┘ └─────────────┘
- ```
- ### Core Components
- **🔧 Refactored Modular Architecture (83 Python files across multiple specialized modules)**:
- **Core Server Layer (6 modules):**
- - **`mcp_server.py`** - Streamlined main coordinator with tool registration pattern (741 lines, 83.5% reduction from 4,502 lines)
- - **`modules/core/mcp_core_tools.py`** - Pure MCP tool implementations for core Gemini CLI tools (487 lines)
- - **`modules/core/mcp_collaboration_engine.py`** - AI collaboration system with advanced workflow modes (1,103 lines)
- - **`modules/core/mcp_service_implementations.py`** - System and service tools coordination layer (1,228 lines)
- - **`modules/core/mcp_code_review_tools.py`** - Specialized code review and analysis tools (386 lines)
- - **`modules/core/mcp_content_comparison_tools.py`** - Multi-source content comparison capabilities (299 lines)
- **Configuration & Infrastructure (7 modules):**
- - **`modules/config/gemini_config.py`** - Main configuration interface with modular imports (1,835 lines)
- - **`modules/config/environment_config.py`** - Environment variable parsing and validation (NEW)
- - **`modules/config/model_config.py`** - Gemini model definitions and scaling configuration (NEW)
- - **`modules/config/feature_config.py`** - Feature flags, OpenRouter, monitoring, and conversations (NEW)
- - **`modules/utils/gemini_utils.py`** - Core utilities and helper functions (3,996 lines)
- - **`modules/services/conversation_manager.py`** - Stateful conversation management with Redis support (1,048 lines)
- - **`modules/services/monitoring.py`** - OpenTelemetry, Prometheus, and health check integration (1,534 lines)
- **Integration Modules (2 modules):**
- - **`modules/services/openrouter_client.py`** - OpenRouter API client for 400+ AI models (881 lines)
- - **`modules/services/redis_cache.py`** - Redis caching with graceful memory fallback (914 lines)
- **Template System (17 modules):**
- - **`prompts/`** - Template module with TTL caching and integrity verification
- - Core templates: template_loader.py, base_template.py, eval_template.py, review_template.py, verify_template.py, summarize_template.py
- - Collaboration templates: debate_template.py, sequential_template.py, validation_template.py
- - Code review templates: code_review_template.py, extract_structured_template.py, git_diff_review_template.py (NEW)
- - Content analysis templates: content_comparison_template.py (NEW)
- - Plus interface and supporting files
- **Security Framework (6 modules):**
- - **`security/`** - Enterprise security framework with 22 critical security fixes
- - Includes: api_key_manager.py, credential_sanitizer.py, pattern_detector.py, security_monitor.py, security_validator.py, jsonrpc_validator.py
- **Rate Limiting & Utility Scripts (5 modules):**
- - **Rate Limiting Framework** (3 modules): per_model_rate_limiter.py, rate_limit_config.py, rate_limit_integration.py
- - **Utility Scripts** (2 modules): rotate_openrouter_key.py, security_audit.py
- **📝 Template System Architecture**:
- ```text
- prompts/
- ├── __init__.py # Module exports and imports
- ├── template_loader.py # Template loading with 30-min TTL caching
- ├── base_template.py # Common components and utilities
- ├── summarize_template.py # Content summarization templates
- ├── review_template.py # Code review templates
- ├── eval_template.py # Plan evaluation templates
- └── verify_template.py # Solution verification templates
- ```
- **Key Template Features**:
- - **Template Extraction**: Large prompt templates separated from function logic for maintainability
- - **TTL Caching**: 30-minute cache for template loading with performance optimization
- - **Modular Design**: Each dual-AI workflow tool has dedicated template files
- - **Function Size Reduction**: ~70% average reduction in function complexity
- - **Performance**: Cached templates improve response times for repeated operations
- **⚡ Enterprise Features**:
- - **10-100x Concurrency Improvement**: Lock-free cache operations with atomic get-or-set patterns
- - **Advanced Caching System**: TTL-based caching with template integrity verification using SHA-256 hashing
- - **Process Pooling**: Configurable ProcessPoolExecutor reducing 100-500ms subprocess creation overhead
- - **Automatic Model Fallback**: gemini-2.5-pro → gemini-2.5-flash with intelligent quota management
- - **Enterprise Monitoring**: OpenTelemetry tracing + Prometheus metrics with graceful degradation
- - **90% Rate Limiting Optimization**: Deque-based O(1) algorithms with memory leak protection
- **🛡️ Security & Reliability**:
- - **22 Critical Security Fixes**: Session-based rate limiting, template integrity validation, enhanced credential sanitization, JSON-RPC validation, subprocess injection protection
- - **Multi-layer Defense**: 25+ attack categories with compiled regex patterns for real-time protection
- - **Security Pattern Detection**: Protection against command injection, path traversal, XSS, prompt injection, information disclosure
- - **Memory-Safe Operations**: Bounded caches with automatic cleanup and O(1) operations
- - **JSON-RPC Security Middleware**: Protocol-level validation with request size limits and nesting depth protection
- - **Structured Error Handling**: Comprehensive error taxonomy with sanitized client responses
- - **Enterprise Compliance**: OWASP Top 10 aligned with NIST security guidelines
- ### Key Architectural Decisions
- **🏛️ Design Philosophy**:
- - **FastMCP Framework**: Official MCP Python SDK with JSON-RPC 2.0 compliance
- - **Dual Input Support**: Both string and list command inputs for security and compatibility
- - **Direct Subprocess Execution**: Avoids shell injection vulnerabilities
- - **Structured Error Classification**: 11 error codes with machine-readable responses
- - **Multi-Tier TTL Caching**: Different cache durations optimized for each use case
- - **Full Async/Await**: High-concurrency architecture supporting 1,000-10,000+ requests
- - **Configurable Fallback**: Environment-driven behavior for empty command handling
- - **Exponential Backoff Retry**: Intelligent retry logic with jitter for transient errors
- - **Input Validation**: Multi-layer validation with length limits and sanitization
- - **Information Disclosure Prevention**: Sanitized client responses with detailed server logging
- ## 🛠️ Tool Suite
- The server provides 33 specialized MCP tools organized into six categories:
- ### Core Gemini Tools (6)
- #### `gemini_cli`
- Execute any Gemini CLI command directly with comprehensive error handling.
- ```python
- gemini_cli(command="--prompt 'Hello world'")
- gemini_cli(command="--model gemini-2.5-pro --prompt 'Explain AI'")
- ```
- #### `gemini_help`
- Get cached Gemini CLI help information (30-minute TTL).
- ```python
- gemini_help()
- ```
- #### `gemini_version`
- Get cached Gemini CLI version information (30-minute TTL).
- ```python
- gemini_version()
- ```
- #### `gemini_prompt`
- Send prompts with structured parameters and validation (100,000 char limit).
- ```python
- gemini_prompt(
- prompt="Explain quantum computing",
- model="gemini-2.5-flash",
- sandbox=False,
- debug=False
- )
- ```
- #### `gemini_models`
- List all available Gemini AI models.
- ```python
- gemini_models()
- ```
- #### `gemini_metrics`
- Get comprehensive server performance metrics and statistics.
- ```python
- gemini_metrics()
- ```
- ### System Tools (3)
- #### `gemini_sandbox`
- Execute prompts in sandbox mode for code execution (200,000 char limit).
- ```python
- gemini_sandbox(
- prompt="Write and run a Python script to analyze data",
- model="gemini-2.5-pro",
- sandbox_image="python:3.11-slim" # optional
- )
- ```
- #### `gemini_cache_stats`
- Get cache statistics for all cache backends.
- ```python
- gemini_cache_stats()
- ```
- #### `gemini_rate_limiting_stats`
- Get comprehensive rate limiting and quota statistics.
- ```python
- gemini_rate_limiting_stats()
- ```
- ### Analysis Tools (5)
- #### `gemini_summarize`
- Summarize content with focus-specific analysis (400,000 char limit).
- ```python
- gemini_summarize(
- content="Your code or text content here",
- focus="architecture and design patterns",
- model="gemini-2.5-pro"
- )
- ```
- #### `gemini_summarize_files`
- File-based summarization optimized for @filename syntax (800,000 char limit).
- **Key Advantages over `gemini_summarize`**:
- - **2x Higher Limit**: 800K vs 400K characters for large codebases
- - **@filename Optimized**: Purpose-built for direct file reading
- - **Token Efficiency**: 50-70% improvement with lightweight prompts
- - **Enterprise Scale**: Handles massive multi-directory projects
- ```python
- gemini_summarize_files(
- files="@src/ @docs/ @tests/", # @filename syntax
- focus="complete system analysis", # optional
- model="gemini-2.5-pro" # optional
- )
- ```
- #### `gemini_eval_plan`
- Evaluate Claude Code implementation plans (500,000 char limit).
- ```python
- gemini_eval_plan(
- plan="Implementation plan from Claude Code",
- context="Node.js REST API with MongoDB",
- requirements="Must support 10,000 concurrent users",
- model="gemini-2.5-pro"
- )
- ```
- #### `gemini_review_code`
- Review specific code suggestions with detailed analysis (300,000 char limit).
- ```python
- gemini_review_code(
- code="Code snippet or @filename to review",
- purpose="Security review of authentication",
- context="Express.js REST API",
- language="javascript",
- model="gemini-2.5-pro"
- )
- ```
- #### `gemini_verify_solution`
- Comprehensive verification of complete solutions (800,000 char limit).
- ```python
- gemini_verify_solution(
- solution="Complete implementation including code, tests, docs",
- requirements="Original requirements specification",
- test_criteria="Performance and security criteria",
- context="Production deployment environment",
- model="gemini-2.5-pro"
- )
- ```
- ### Conversation Tools (5)
- #### `gemini_start_conversation`
- Start a new conversation with ID for stateful interactions.
- ```python
- gemini_start_conversation(
- title="Python Development Help",
- description="Ongoing assistance with Python project",
- tags="python,development",
- expiration_hours=24
- )
- ```
- #### `gemini_continue_conversation`
- Continue an existing conversation with context history.
- ```python
- gemini_continue_conversation(
- conversation_id="conv_12345",
- prompt="How do I optimize this function?",
- model="gemini-2.5-flash"
- )
- ```
- #### `gemini_list_conversations`
- List active conversations with metadata.
- ```python
- gemini_list_conversations(
- limit=20,
- status_filter="active"
- )
- ```
- #### `gemini_clear_conversation`
- Clear/delete a specific conversation.
- ```python
- gemini_clear_conversation(conversation_id="conv_12345")
- ```
- #### `gemini_conversation_stats`
- Get conversation system statistics and health.
- ```python
- gemini_conversation_stats()
- ```
- ### Specialized Code Review Tools (3)
- #### `gemini_code_review`
- Comprehensive code analysis with structured output (NEW).
- ```python
- gemini_code_review(
- code="Your code to review",
- language="python", # optional, auto-detected
- focus_areas="security,performance,quality,best_practices", # optional
- severity_threshold="info", # optional: info, warning, error, critical
- output_format="structured" # optional: structured, markdown, json
- )
- ```
- #### `gemini_extract_structured`
- Extract structured data using JSON schemas (NEW).
- ```python
- # Define a schema for code analysis
- schema = {
- "type": "object",
- "properties": {
- "functions": {"type": "array"},
- "classes": {"type": "array"},
- "issues": {"type": "array"}
- }
- }
- gemini_extract_structured(
- content="Code or text to analyze",
- schema=json.dumps(schema),
- examples="Optional examples of expected output", # optional
- strict_mode=True, # optional
- model="gemini-2.5-flash" # optional
- )
- ```
- #### `gemini_git_diff_review`
- Analyze git diffs with contextual feedback (NEW).
- ```python
- gemini_git_diff_review(
- diff="Git diff content or patch",
- context_lines=3, # optional
- review_type="comprehensive", # optional: comprehensive, security_only, performance_only, quick
- base_branch="main", # optional
- commit_message="Fix authentication bug" # optional
- )
- ```
- ### Content Comparison Tools (1)
- #### `gemini_content_comparison`
- Advanced multi-source content comparison and analysis (NEW).
- ```python
- # Compare documentation versions
- gemini_content_comparison(
- sources='["@README.md", "@docs/README.md", "https://github.com/user/repo/README.md"]',
- comparison_type="semantic", # semantic, textual, structural, factual, code
- output_format="structured", # structured, matrix, summary, detailed, json
- include_metrics=True, # optional, include similarity scores
- focus_areas="completeness,accuracy,structure" # optional, what to focus on
- )
- # Code version analysis
- gemini_content_comparison(
- sources='["@src/auth_v1.py", "@src/auth_v2.py"]',
- comparison_type="code",
- output_format="detailed",
- focus_areas="differences,security,performance"
- )
- ```
- ### AI Collaboration Tools (1)
- #### `gemini_ai_collaboration`
- Enhanced multi-platform AI collaboration with cross-platform capabilities.
- ```python
- # Sequential analysis pipeline
- gemini_ai_collaboration(
- collaboration_mode="sequential",
- content="Your task or code to analyze",
- models="gemini-2.5-flash,openai/gpt-4.1-nano,anthropic/claude-3-haiku",
- pipeline_stages="analysis,security_review,optimization,final_validation"
- )
- # Multi-round AI debate
- gemini_ai_collaboration(
- collaboration_mode="debate",
- content="Should we use microservices or monolith?",
- models="gemini-2.5-flash,openai/gpt-4.1-mini,anthropic/claude-3-haiku",
- rounds=4,
- debate_style="constructive"
- )
- ```
- #### Complete Parameter Reference for `gemini_ai_collaboration`
- **Available Collaboration Modes:**
- - **`sequential`** - Progressive refinement through ordered analysis pipeline
- - **`debate`** - Multi-round discussions with consensus building
- - **`validation`** - Cross-platform validation with conflict resolution
- **Available Debate Styles (for debate mode):**
- - **`constructive`** (default) - Focus on building understanding rather than winning arguments
- - **`adversarial`** - Challenge assumptions and arguments rigorously
- - **`collaborative`** - Work together to explore topics comprehensively
- - **`socratic`** - Use questioning to explore underlying assumptions
- - **`devil_advocate`** - Deliberately argue for challenging positions
- **Universal Parameters:**
- - **`collaboration_mode`** (required): `sequential` | `debate` | `validation`
- - **`content`** (required): Content to be analyzed/processed
- - **`models`** (optional): Comma-separated list of AI models (auto-selected if not provided)
- - **`context`** (optional): Additional context for collaboration
- - **`conversation_id`** (optional): For stateful conversation history
- - **`budget_limit`** (optional): USD cost limit for OpenRouter models
- **Sequential Mode Parameters:**
- - **`pipeline_stages`** (optional): Comma-separated stages (auto-generated if not provided)
- - **`handoff_criteria`** (optional): `completion_of_stage` | `quality_threshold` | `consensus_reached` | `time_based`
- - **`quality_gates`** (optional): `none` | `basic` | `standard` | `strict` | `comprehensive`
- - **`focus`** (optional): Focus area (default: "progressive refinement")
- **Debate Mode Parameters:**
- - **`rounds`** (optional): Number of debate rounds (1-10, default: 3)
- - **`debate_style`** (optional): See debate styles above (default: "constructive")
- - **`convergence_criteria`** (optional): `substantial_agreement` | `consensus` | `majority_view` | `all_viewpoints`
- - **`focus`** (optional): Focus area (default: "comprehensive analysis")
- **Validation Mode Parameters:**
- - **`validation_criteria`** (optional): Comma-separated criteria (auto-generated if not provided)
- - **`confidence_threshold`** (optional): 0.0-1.0 (default: 0.7)
- - **`consensus_method`** (optional): `simple_majority` | `weighted_majority` | `unanimous` | `supermajority` | `expert_panel`
- - **`conflict_resolution`** (optional): `ignore` | `flag_only` | `detailed_analysis` | `additional_validation` | `expert_arbitration`
- #### Advanced Usage Examples
- **Different Debate Styles:**
- ```python
- # Adversarial debate for critical analysis
- gemini_ai_collaboration(
- collaboration_mode="debate",
- content="Should our startup use microservices architecture?",
- models="gemini-2.5-flash,openai/gpt-4.1-mini",
- rounds=3,
- debate_style="adversarial",
- convergence_criteria="majority_view"
- )
- # Socratic questioning for deep exploration
- gemini_ai_collaboration(
- collaboration_mode="debate",
- content="What makes code maintainable?",
- models="gemini-2.5-flash,anthropic/claude-3-haiku",
- rounds=4,
- debate_style="socratic",
- focus="fundamental principles"
- )
- # Devil's advocate for stress testing ideas
- gemini_ai_collaboration(
- collaboration_mode="debate",
- content="Our new feature implementation plan",
- models="gemini-2.5-flash,openai/gpt-4.1-mini,anthropic/claude-3-haiku",
- rounds=2,
- debate_style="devil_advocate",
- focus="identifying potential failures"
- )
- ```
- **Sequential Pipeline Examples:**
- ```python
- # Quality-gated sequential analysis
- gemini_ai_collaboration(
- collaboration_mode="sequential",
- content="@src/authentication.py",
- models="gemini-2.5-flash,openai/gpt-4.1-mini,anthropic/claude-3-haiku",
- pipeline_stages="code_review,security_analysis,performance_optimization,documentation",
- quality_gates="strict",
- handoff_criteria="quality_threshold"
- )
- # Time-based handoffs for rapid iteration
- gemini_ai_collaboration(
- collaboration_mode="sequential",
- content="Product requirements analysis",
- models="gemini-2.5-flash,openai/gpt-4.1-nano",
- pipeline_stages="initial_analysis,stakeholder_review,final_recommendations",
- handoff_criteria="time_based",
- focus="user experience"
- )
- ```
- **Validation Examples:**
- ```python
- # High-confidence consensus validation
- gemini_ai_collaboration(
- collaboration_mode="validation",
- content="Critical system design decisions",
- models="gemini-2.5-flash,openai/gpt-4.1-mini,anthropic/claude-3-haiku",
- validation_criteria="scalability,security,maintainability,cost_efficiency",
- confidence_threshold=0.9,
- consensus_method="unanimous",
- conflict_resolution="expert_arbitration"
- )
- # Supermajority validation with detailed conflict analysis
- gemini_ai_collaboration(
- collaboration_mode="validation",
- content="API design specification",
- models="gemini-2.5-flash,openai/gpt-4.1-mini,anthropic/claude-3-haiku",
- validation_criteria="usability,performance,consistency,documentation",
- consensus_method="supermajority",
- conflict_resolution="detailed_analysis"
- )
- ```
- **Auto-Selection Behavior:**
- When `models` parameter is not provided, the function automatically selects appropriate models:
- - **Sequential**: `"gemini-2.5-flash,openai/gpt-4.1-nano,anthropic/claude-3-haiku"`
- - **Debate**: `"gemini-2.5-flash,openai/gpt-4.1-mini,anthropic/claude-3-haiku"`
- - **Validation**: `"gemini-2.5-flash,openai/gpt-4.1-nano,anthropic/claude-3-haiku"`
- ### OpenRouter Tools (6)
- #### `gemini_test_openrouter`
- Test OpenRouter connectivity and client functionality.
- ```python
- gemini_test_openrouter()
- ```
- #### `gemini_openrouter_opinion`
- Get responses from any of 400+ AI models via OpenRouter with @filename support.
- ```python
- gemini_openrouter_opinion(
- prompt="Analyze @config.yaml for security issues",
- model="anthropic/claude-3-haiku",
- temperature=0.7,
- max_tokens=2000,
- file_handling_strategy="auto"
- )
- ```
- #### `gemini_openrouter_models`
- List all available OpenRouter models (400+) with advanced filtering and output options.
- ```python
- gemini_openrouter_models(
- category="programming",
- provider_filter="openai",
- sort_by="usage",
- include_pricing=True
- )
- ```
- #### `gemini_cross_model_comparison`
- Compare responses across Gemini CLI and OpenRouter models with @filename support.
- ```python
- gemini_cross_model_comparison(
- prompt="Design a REST API for user authentication",
- models="gemini-2.5-flash,openai/gpt-4.1-mini,anthropic/claude-3-haiku"
- )
- ```
- #### `gemini_openrouter_usage_stats`
- Get OpenRouter usage statistics and costs for the current session.
- ```python
- gemini_openrouter_usage_stats()
- ```
- #### `gemini_cross_model_comparison`
- Compare responses across Gemini CLI and OpenRouter models with @filename support.
- ```python
- gemini_cross_model_comparison(
- prompt="Design a REST API for user authentication",
- models="gemini-2.5-flash,openai/gpt-4.1-mini,anthropic/claude-3-haiku"
- )
- ```
- ## 📦 Installation
- ### Prerequisites
- - **Python 3.10+** - Required for MCP SDK compatibility
- - **Gemini CLI** - Google's command-line tool for Gemini AI
- - **uv** (recommended) or pip for package management
- ### Linux Setup
- ```bash
- # Install uv (recommended package manager)
- curl -LsSf https://astral.sh/uv/install.sh | sh
- # Clone the repository
- git clone https://github.com/centminmod/gemini-cli-mcp-server.git
- cd gemini-cli-mcp-server
- # Create and activate virtual environment
- uv venv
- source .venv/bin/activate
- # Install dependencies
- uv pip install -r requirements.txt
- # Install and configure Gemini CLI
- npm install -g @google-ai/gemini-cli
- gemini config set api_key YOUR_GEMINI_API_KEY
- # Verify installation
- gemini --version
- python mcp_server.py --help
- ```
- ### macOS Setup
- ```bash
- # Install uv via Homebrew (or use curl installer above)
- brew install uv
- # Clone the repository
- git clone https://github.com/centminmod/gemini-cli-mcp-server.git
- cd gemini-cli-mcp-server
- # Create and activate virtual environment
- uv venv
- source .venv/bin/activate
- # Install dependencies
- uv pip install -r requirements.txt
- # Install Gemini CLI (if not already installed)
- npm install -g @google-ai/gemini-cli
- # Or via Homebrew: brew install gemini-cli
- # Configure Gemini CLI
- gemini config set api_key YOUR_GEMINI_API_KEY
- # Verify installation
- gemini --version
- python mcp_server.py --help
- ```
- ### Alternative Installation (pip)
- ```bash
- # Using standard Python tools
- python -m venv venv
- source venv/bin/activate # On Windows: venv\Scripts\activate
- pip install -r requirements.txt
- # Configure Gemini CLI
- gemini config set api_key YOUR_GEMINI_API_KEY
- ```
- ## ⚙️ MCP Client Configuration
- ### Claude Code
- Add the server using the Claude Code MCP command for `user` scope:
- ```bash
- claude mcp add gemini-cli /absolute/path/to/.venv/bin/python /absolute/path/to/mcp_server.py -s user -e GEMINI_API_KEY='YOUR_GEMINI_API_KEY'
- ```
- Use the `-s` or `--scope` flag to specify where the configuration is stored:
- * `local` (default): Available only to you in the current project (was called `project` in older versions)
- * `project`: Shared with everyone in the project via `.mcp.json` file
- * `user`: Available to you across all projects (was called `global` in older versions)
- ### Claude Desktop
- Add the following to your Claude Desktop settings file:
- **Location**:
- - macOS: `~/Library/Application Support/Claude/claude_desktop_config.json`
- - Windows: `%APPDATA%\Claude\claude_desktop_config.json`
- - Linux: `~/.config/claude/claude_desktop_config.json`
- **Configuration**:
- ```json
- {
- "mcpServers": {
- "gemini-cli": {
- "command": "/absolute/path/to/.venv/bin/python",
- "args": ["/absolute/path/to/mcp_server.py"]
- }
- }
- }
- ```
- **Important**: Use absolute paths for both the Python executable and the `mcp_server.py` script.
- ### Other MCP Clients
- For other MCP-compatible clients, use the stdio transport with:
- - **Command**: Path to Python executable in virtual environment
- - **Arguments**: Path to `mcp_server.py`
- - **Transport**: stdio (standard input/output)
- ## 🎯 Usage Examples
- ### Basic Operations
- **Simple Q&A**:
- ```python
- # Quick question with fast model
- gemini_prompt(
- prompt="What is machine learning?",
- model="gemini-2.5-flash"
- )
- # Complex analysis with advanced model
- gemini_prompt(
- prompt="Analyze the trade-offs between REST and GraphQL APIs",
- model="gemini-2.5-pro"
- )
- ```
- **File Analysis**:
- ```python
- # Review code file directly
- gemini_review_code(
- code="@src/auth.py",
- purpose="Security vulnerability assessment",
- language="python"
- )
- # Summarize multiple files (standard approach)
- gemini_summarize(
- content="@src/ @tests/ @docs/",
- focus="architecture and design patterns"
- )
- # Large-scale file analysis (optimized approach)
- gemini_summarize_files(
- files="@src/ @lib/ @components/ @tests/ @docs/",
- focus="complete system architecture and dependencies"
- )
- ```
- **Code Execution**:
- ```python
- # Interactive development
- gemini_sandbox(
- prompt="Create a data visualization of sales trends",
- model="gemini-2.5-pro"
- )
- # Custom environment
- gemini_sandbox(
- prompt="Test this Node.js API endpoint",
- sandbox_image="node:18-alpine"
- )
- ```
- ### Dual-AI Workflow Examples
- The dual-AI workflow enables powerful collaboration between Claude Code and Gemini AI:
- #### 1. Plan Evaluation
- ```python
- # Claude Code generates an implementation plan
- plan = """
- 1. Create JWT authentication middleware
- 2. Implement rate limiting with Redis
- 3. Add input validation with Joi
- 4. Set up comprehensive error handling
- 5. Create user registration/login endpoints
- """
- # Gemini AI evaluates the plan
- gemini_eval_plan(
- plan=plan,
- context="Express.js REST API for e-commerce platform",
- requirements="Must support 50,000 concurrent users, GDPR compliant",
- model="gemini-2.5-pro"
- )
- ```
- #### 2. Code Review During Development
- ```python
- # Claude Code suggests implementation
- code = """
- const jwt = require('jsonwebtoken');
- const authMiddleware = (req, res, next) => {
- const token = req.header('Authorization')?.replace('Bearer ', '');
- if (!token) {
- return res.status(401).json({ error: 'Access denied' });
- }
- try {
- const decoded = jwt.verify(token, process.env.JWT_SECRET);
- req.user = decoded;
- next();
- } catch (error) {
- res.status(401).json({ error: 'Invalid token' });
- }
- };
- """
- # Gemini AI reviews the code
- gemini_review_code(
- code=code,
- purpose="JWT authentication middleware for Express.js",
- context="E-commerce API with high security requirements",
- language="javascript",
- model="gemini-2.5-pro"
- )
- ```
- #### 3. Complete Solution Verification
- ```python
- # Complete implementation ready for deployment
- solution = """
- [Complete implementation including:]
- - Authentication system with JWT and refresh tokens
- - Rate limiting middleware with Redis
- - Input validation with comprehensive schemas
- - Error handling with structured responses
- - User management endpoints
- - Security headers and CORS configuration
- - Comprehensive test suite
- - API documentation
- - Deployment configuration
- """
- # Final verification before deployment
- gemini_verify_solution(
- solution=solution,
- requirements="Secure authentication system with rate limiting",
- test_criteria="Handle 50k concurrent users, 99.9% uptime, sub-200ms response",
- context="Production deployment on AWS ECS with Redis ElastiCache",
- model="gemini-2.5-pro"
- )
- ```
- ### Advanced Usage Patterns
- **Large Codebase Analysis**:
- ```python
- # Enterprise-scale project analysis (recommended)
- gemini_summarize_files(
- files="@src/ @lib/ @components/ @utils/ @tests/ @docs/",
- focus="architectural patterns and dependencies",
- model="gemini-2.5-pro"
- )
- # Alternative for smaller projects
- gemini_summarize(
- content="@src/ @lib/ @components/ @utils/ @tests/",
- focus="architectural patterns and dependencies",
- model="gemini-2.5-pro"
- )
- ```
- **Performance Analysis**:
- ```python
- # Review code for performance issues
- gemini_review_code(
- code="@src/api/handlers/ @src/database/",
- purpose="Performance optimization and bottleneck identification",
- context="High-traffic API serving 1M requests/day",
- model="gemini-2.5-pro"
- )
- ```
- **Security Assessment**:
- ```python
- # Comprehensive security review
- gemini_review_code(
- code="@auth/ @middleware/ @validators/",
- purpose="Security vulnerability assessment",
- context="Financial services application with PCI compliance requirements",
- model="gemini-2.5-pro"
- )
- ```
- ### Specialized Code Review Examples (NEW)
- **Structured Code Analysis**:
- ```python
- # Comprehensive code review with structured output
- gemini_code_review(
- code="@src/api/handlers/",
- language="python",
- focus_areas="security,performance,maintainability",
- severity_threshold="warning",
- output_format="structured"
- )
- ```
- **Schema-Based Data Extraction**:
- ```python
- # Extract API endpoints from codebase
- schema = {
- "type": "object",
- "properties": {
- "endpoints": {
- "type": "array",
- "items": {
- "type": "object",
- "properties": {
- "path": {"type": "string"},
- "method": {"type": "string"},
- "authentication": {"type": "boolean"}
- }
- }
- }
- }
- }
- gemini_extract_structured(
- content="@src/routes/",
- schema=json.dumps(schema),
- strict_mode=True
- )
- ```
- **Git Diff Analysis**:
- ```python
- # Review pull request changes
- gemini_git_diff_review(
- diff="@pull_request.diff",
- review_type="comprehensive",
- base_branch="main",
- commit_message="Add user authentication feature"
- )
- ```
- **Multi-Source Content Comparison**:
- ```python
- # Compare API documentation versions
- gemini_content_comparison(
- sources='["@docs/api_v1.md", "@docs/api_v2.md", "https://api.example.com/docs"]',
- comparison_type="semantic",
- output_format="matrix",
- focus_areas="breaking_changes,new_features,deprecations"
- )
- ```
- ## ⚡ Advanced Features
- ### Dynamic Token Limits
- Each tool has optimized character limits based on typical use cases:
- | Tool | Limit | Use Case |
- |------|-------|----------|
- | `gemini_prompt` | 100K chars | General purpose interactions |
- | `gemini_sandbox` | 200K chars | Code execution & development |
- | `gemini_eval_plan` | 500K chars | Architecture evaluation |
- | `gemini_review_code` | 300K chars | Code review & analysis |
- | `gemini_verify_solution` | 800K chars | Complete solution verification |
- | `gemini_summarize` | 400K chars | Large content summarization |
- | `gemini_summarize_files` | 800K chars | File-based analysis with @filename syntax |
- | `gemini_ai_collaboration` | 500K chars | Multi-AI workflow collaboration |
- | `gemini_openrouter_opinion` | 150K chars | OpenRouter model interactions |
- | `gemini_code_review` | 300K chars | Structured code analysis (NEW) |
- | `gemini_extract_structured` | 200K chars | Schema-based data extraction (NEW) |
- | `gemini_git_diff_review` | 150K chars | Git diff analysis (NEW) |
- | `gemini_content_comparison` | 400K chars | Multi-source content comparison (NEW) |
- | **Conversation Tools** | Variable | Context-aware with token management |
- ### Model-Aware Scaling
- Limits automatically scale based on the selected model's capabilities:
- - **gemini-2.5-pro**: 100% of limits (best quality)
- - **gemini-2.5-flash**: 100% of limits (speed optimized)
- - **gemini-1.5-pro**: 80% of limits (stable performance)
- - **gemini-1.5-flash**: 60% of limits (speed focused)
- - **gemini-1.0-pro**: 40% of limits (legacy compatibility)
- ### Automatic Model Fallback
- When quota limits are exceeded, the server automatically falls back from premium to standard models:
- ```
- gemini-2.5-pro (quota exceeded) → gemini-2.5-flash (automatic retry)
- ```
- This ensures continuous operation during high-usage periods without user intervention.
- ### OpenRouter Multi-Model Integration
- Access to 400+ AI models from 20+ providers including OpenAI, Anthropic, Meta, Google, and more:
- **Key Benefits:**
- - **Model Variants**: Optimization options (:free, :nitro, :floor, :online) for cost, speed, and capabilities
- - **Cost Management**: Built-in usage tracking with daily limits and warnings
- - **Cross-Platform Comparison**: Compare responses between Gemini CLI and OpenRouter models
- - **Enhanced @filename Support**: Intelligent large file handling for 200K+ token support
- **Popular Models Available:**
- - **OpenAI**: gpt-4.1-nano, gpt-4.1-mini, gpt-4.1,gpt-4o, gpt-4o-mini, gpt-3.5-turbo
- - **Anthropic**: claude-sonnet-4, claude-3-haiku, claude-opus-4
- - **Meta**: llama-3.2-11b-vision-instruct, llama-3.1-405b-instruct
- - **Google**: gemini-2.5-pro, gemini-2.5-flash (via OpenRouter)
- - **Free Options**: Multiple free model variants available
- ### Conversation History Management
- Stateful multi-turn conversations with persistent context:
- **Key Features:**
- - **Redis-Backed Storage**: Scalable conversation storage with graceful memory fallback
- - **Cross-Platform Support**: Works seamlessly with both Gemini CLI and OpenRouter models
- - **Automatic Context Building**: Intelligent context assembly respecting token limits
- - **Conversation Pruning**: Automatic message and token limit management
- - **Configurable Expiration**: Automatic cleanup with customizable retention periods
- ### Advanced Caching
- **TTL-Based Caching**:
- - Help/version commands: 30 minutes
- - Prompt results: 5 minutes
- - Template loading: 30 minutes
- **Cache Features**:
- - Atomic operations prevent race conditions
- - Memory limits prevent unbounded growth
- - Automatic cleanup and expiration
- - Cache hit/miss metrics tracking
- ### @filename Syntax Support
- 32 of the 33 tools support Gemini CLI's native @filename syntax for optimal token efficiency. OpenRouter tools include enhanced large file handling:
- ```python
- # Single file
- gemini_prompt(prompt="Analyze @config.py")
- # Multiple files
- gemini_review_code(code="@src/auth.py @src/middleware.py")
- # Directories and wildcards
- gemini_summarize(content="@src/ @tests/ @**/*.js")
- # OpenRouter with intelligent file processing
- gemini_openrouter_opinion(
- prompt="Review @large_codebase/ for security",
- model="anthropic/claude-3-haiku",
- file_handling_strategy="auto" # auto, full, chunk, summarize
- )
- # Mixed content
- gemini_eval_plan(plan="Based on @requirements.md, implement @design.py")
- ```
- **Benefits**:
- - 50-70% token efficiency improvement for Gemini CLI tools
- - Direct file reading by Gemini CLI
- - Intelligent large file handling for OpenRouter (200K+ token support)
- - Multiple processing strategies: full, chunk, summarize, auto
- - No intermediate processing overhead
- - Preserves full context window utilization
- ### Template System Benefits
- The modular template system provides significant advantages for enterprise deployments:
- **📈 Maintainability**:
- - **Function Size Reduction**: ~70% average reduction in function complexity
- - **Separation of Concerns**: Template content isolated from business logic
- - **Single Responsibility**: Each template serves a specific AI workflow purpose
- - **Version Control**: Template changes tracked independently
- **⚡ Performance**:
- - **TTL Caching**: 30-minute cache for template loading reduces I/O overhead
- - **Memory Efficiency**: Templates loaded once and reused across requests
- - **Response Time**: Faster tool execution with cached template access
- - **Resource Optimization**: Reduced filesystem access for repeated operations
- **🔧 Development Experience**:
- - **Modular Architecture**: Each dual-AI workflow tool has dedicated templates
- - **Easy Customization**: Templates can be modified without touching core logic
- - **Testing**: Templates can be unit tested independently
- - **Documentation**: Self-documenting template structure with clear organization
- ## ⚙️ Configuration
- ### Environment Variables
- The server supports extensive configuration through environment variables:
- #### Core Configuration
- ```bash
- export GEMINI_TIMEOUT=300 # Command timeout (10-3600 seconds)
- export GEMINI_LOG_LEVEL=INFO # Logging level (DEBUG, INFO, WARNING, ERROR)
- export GEMINI_COMMAND_PATH=gemini # Path to Gemini CLI executable
- export GEMINI_OUTPUT_FORMAT=json # Response format (json, text)
- ```
- #### Retry Configuration
- ```bash
- export RETRY_MAX_ATTEMPTS=3 # Maximum retry attempts (1-10)
- export RETRY_BASE_DELAY=1.0 # Base delay for exponential backoff (0.1-10.0)
- export RETRY_MAX_DELAY=30.0 # Maximum delay between retries (5.0-300.0)
- ```
- #### Tool-Specific Limits
- ```bash
- export GEMINI_PROMPT_LIMIT=100000 # gemini_prompt character limit
- export GEMINI_SANDBOX_LIMIT=200000 # gemini_sandbox character limit
- export GEMINI_EVAL_LIMIT=500000 # gemini_eval_plan character limit
- export GEMINI_REVIEW_LIMIT=300000 # gemini_review_code character limit
- export GEMINI_VERIFY_LIMIT=800000 # gemini_verify_solution character limit
- export GEMINI_SUMMARIZE_LIMIT=400000 # gemini_summarize character limit
- export GEMINI_SUMMARIZE_FILES_LIMIT=800000 # gemini_summarize_files character limit
- ```
- #### Model Fallback
- ```bash
- export GEMINI_ENABLE_FALLBACK=true # Enable automatic model fallback
- ```
- #### Rate Limiting
- ```bash
- export GEMINI_RATE_LIMIT_REQUESTS=100 # Requests per time window
- export GEMINI_RATE_LIMIT_WINDOW=60 # Time window in seconds
- ```
- #### OpenRouter Configuration
- ```bash
- export OPENROUTER_API_KEY="sk-or-v1-your-api-key" # OpenRouter API key for 400+ models
- export OPENROUTER_DEFAULT_MODEL="openai/gpt-4.1-nano" # Default OpenRouter model
- export OPENROUTER_COST_LIMIT_PER_DAY="10.0" # Daily cost limit in USD
- export OPENROUTER_ENABLE_STREAMING="true" # Enable streaming responses
- export OPENROUTER_MAX_FILE_TOKENS="50000" # Per-file token limit for @filename
- export OPENROUTER_MAX_TOTAL_TOKENS="150000" # Total prompt token limit
- ```
- #### Conversation Management
- ```bash
- export GEMINI_CONVERSATION_ENABLED="true" # Enable conversation history
- export GEMINI_CONVERSATION_STORAGE="redis" # Storage backend (redis, memory, auto)
- export GEMINI_CONVERSATION_EXPIRATION_HOURS="24" # Auto-cleanup time
- export GEMINI_CONVERSATION_MAX_MESSAGES="10" # Message history limit
- export GEMINI_CONVERSATION_MAX_TOKENS="20000" # Token history limit
- export GEMINI_REDIS_HOST="localhost" # Redis host for conversation storage
- export GEMINI_REDIS_PORT="6479" # Redis port (custom to avoid conflicts)
- ```
- #### Cloudflare AI Gateway Integration (Optional)
- ```bash
- # Route OpenRouter requests through Cloudflare AI Gateway for enhanced performance
- export CLOUDFLARE_AI_GATEWAY_ENABLED="true" # Enable Cloudflare AI Gateway
- export CLOUDFLARE_ACCOUNT_ID="your-account-id" # Cloudflare Account ID
- export CLOUDFLARE_GATEWAY_ID="your-gateway-id" # Cloudflare Gateway ID
- export CLOUDFLARE_AI_GATEWAY_TIMEOUT="300" # Gateway timeout in seconds
- export CLOUDFLARE_AI_GATEWAY_MAX_RETRIES="3" # Maximum retry attempts
- ```
- #### Enterprise Monitoring (Optional)
- ```bash
- export ENABLE_MONITORING=true # Master control for all monitoring features
- export ENABLE_OPENTELEMETRY=true # Enable OpenTelemetry distributed tracing
- export ENABLE_PROMETHEUS=true # Enable Prometheus metrics collection
- export ENABLE_HEALTH_CHECKS=true # Enable health check system
- export PROMETHEUS_PORT=8000 # Prometheus metrics endpoint port
- export OPENTELEMETRY_ENDPOINT="https://otel-collector:4317" # OpenTelemetry endpoint
- export OPENTELEMETRY_SERVICE_NAME="gemini-cli-mcp-server" # Service name for tracing
- ```
- #### Security Configuration (Advanced)
- ```bash
- export JSONRPC_MAX_REQUEST_SIZE=1048576 # Max JSON-RPC request size (1MB default)
- export JSONRPC_MAX_NESTING_DEPTH=10 # Max object/array nesting depth
- export JSONRPC_STRICT_MODE=true # Enable strict JSON-RPC validation
- export GEMINI_SUBPROCESS_MAX_CPU_TIME=300 # Subprocess CPU time limit (seconds)
- export GEMINI_SUBPROCESS_MAX_MEMORY_MB=512 # Subprocess memory limit (MB)
- ```
- ### Configuration Examples
- **Standard Development**:
- ```bash
- # Use defaults - no configuration needed
- ```
- **With OpenRouter (400+ Models)**:
- ```bash
- export OPENROUTER_API_KEY="sk-or-v1-your-api-key"
- export OPENROUTER_COST_LIMIT_PER_DAY="10.0"
- export OPENROUTER_DEFAULT_MODEL="anthropic/claude-3-haiku"
- ```
- **Full Enterprise Setup**:
- ```bash
- # Core configuration
- export GEMINI_TIMEOUT=600
- export GEMINI_EVAL_LIMIT=750000
- export GEMINI_REVIEW_LIMIT=600000
- export GEMINI_VERIFY_LIMIT=1200000
- export RETRY_MAX_ATTEMPTS=5
- # OpenRouter integration
- export OPENROUTER_API_KEY="sk-or-v1-your-api-key"
- export OPENROUTER_COST_LIMIT_PER_DAY="25.0"
- export OPENROUTER_DEFAULT_MODEL="openai/gpt-4.1-mini"
- # Cloudflare AI Gateway (optional)
- export CLOUDFLARE_AI_GATEWAY_ENABLED="true"
- export CLOUDFLARE_ACCOUNT_ID="your-account-id"
- export CLOUDFLARE_GATEWAY_ID="your-gateway-id"
- # Conversation history with Redis
- export GEMINI_CONVERSATION_ENABLED="true"
- export GEMINI_CONVERSATION_STORAGE="redis"
- export GEMINI_REDIS_PORT="6479"
- # Enterprise monitoring
- export ENABLE_MONITORING="true"
- export ENABLE_PROMETHEUS="true"
- export PROMETHEUS_PORT="8000"
- ```
- **High-Performance Setup**:
- ```bash
- export GEMINI_LOG_LEVEL=WARNING
- export RETRY_BASE_DELAY=0.5
- export RETRY_MAX_DELAY=10.0
- export GEMINI_RATE_LIMIT_REQUESTS=500
- export OPENROUTER_ENABLE_STREAMING="true"
- ```
- **Debug Configuration**:
- ```bash
- export GEMINI_LOG_LEVEL=DEBUG
- export GEMINI_OUTPUT_FORMAT=json
- export GEMINI_TIMEOUT=120
- export ENABLE_STDIN_DEBUG="1"
- ```
- ### Response Formats
- #### JSON Format (Default)
- ```json
- {
- "status": "success",
- "return_code": 0,
- "stdout": "Response from Gemini AI",
- "stderr": ""
- }
- ```
- #### Text Format
- ```
- Response from Gemini AI
- ```
- ## 🚀 Performance
- ### Performance Characteristics
- **Operation Times**:
- - Fast operations (help, version, metrics): < 2 seconds
- - Medium operations (simple prompts): 2-10 seconds
- - Complex operations (file analysis, code review): 10-60 seconds
- - Large analysis (enterprise codebases): 1-5 minutes
- - OpenRouter requests: 2-15 seconds (varies by model)
- - Conversation context loading: < 1 second (with Redis)
- **Concurrency**:
- - Async architecture supports 1,000-10,000+ concurrent requests
- - 10-100x concurrency improvement with lock-free cache operations
- - Memory-efficient single-threaded design
- - Non-blocking I/O operations across all 33 tools
- **Memory Usage**:
- - Base server: 15-30MB (optimized for enterprise features)
- - Per operation: 2-8MB average (varies by tool complexity)
- - Bounded caches prevent memory leaks with automatic cleanup
- - O(1) rate limiting algorithms with memory leak protection
- - Redis-backed conversation storage scales independently
- **Total Lines of Code**: ~15,000+ lines across 83 modules
- **Cache Effectiveness**:
- - Help/version commands: 95-99% hit rate
- - Prompt results: 60-80% hit rate for repeated operations
- - Template loading: 90-95% hit rate (30-minute TTL)
- - OpenRouter model discovery: 98% hit rate
- - Conversation context: 85-95% hit rate with Redis
- ### Performance Optimization
- **For High-Throughput Scenarios**:
- ```bash
- export GEMINI_LOG_LEVEL=WARNING # Reduce logging overhead
- export RETRY_BASE_DELAY=0.5 # Faster retry cycles
- export GEMINI_RATE_LIMIT_REQUESTS=1000 # Higher rate limits
- ```
- **For Large Content Processing**:
- ```bash
- export GEMINI_TIMEOUT=1800 # Extended timeout (30 minutes)
- export GEMINI_EVAL_LIMIT=1500000 # Maximum evaluation capacity
- export GEMINI_VERIFY_LIMIT=2000000 # Maximum verification capacity
- ```
- **For Development Speed**:
- ```bash
- export GEMINI_OUTPUT_FORMAT=text # Faster response parsing
- export RETRY_MAX_ATTEMPTS=1 # Fail fast for debugging
- ```
- ### Monitoring
- Use the `gemini_metrics` tool to monitor server performance:
- ```python
- gemini_metrics()
- ```
- **Key Metrics**:
- - Commands executed and success rate across all 33 tools
- - Average latency and throughput per tool category
- - Cache hit rates and effectiveness (4 cache types)
- - Error rates and types with detailed classification
- - Model usage and fallback statistics (Gemini + OpenRouter)
- - Memory usage and resource utilization
- - OpenRouter cost tracking and usage statistics
- - Conversation system performance and storage metrics
- - Security pattern detection and rate limiting effectiveness
- ## 🧪 Testing
- ### Quick Validation
- **Test Server Import**:
- ```bash
- python -c "from mcp_server import mcp; print('✅ Server imports successfully')"
- ```
- **Test Gemini CLI Integration**:
- ```bash
- python -c "
- import asyncio
- from gemini_utils import validate_gemini_setup
- print('✅ Gemini CLI setup valid' if validate_gemini_setup() else '❌ Gemini CLI setup invalid')
- "
- ```
- ### MCP Inspector Testing
- Test the server with the official MCP development tools:
- ```bash
- # Install MCP development tools
- uv pip install "mcp[dev]"
- # Test server with MCP inspector
- mcp dev mcp_server.py
- ```
- This opens an interactive interface to test all MCP tools directly.
- ### Manual Testing
- **Test Basic Functionality**:
- ```python
- # In Python REPL or script
- import asyncio
- from mcp_server import gemini_help, gemini_version, gemini_models
- async def test_basic():
- print("Testing basic functionality...")
- # Test cached operations
- help_result = await gemini_help()
- print(f"Help: {len(help_result)} characters")
- version_result = await gemini_version()
- print(f"Version: {version_result[:50]}...")
- models_result = await gemini_models()
- print(f"Models: {models_result[:100]}...")
- print("✅ Basic tests passed")
- asyncio.run(test_basic())
- ```
- **Test Prompt Functionality**:
- ```python
- import asyncio
- from mcp_server import gemini_prompt
- async def test_prompts():
- print("Testing prompt functionality...")
- result = await gemini_prompt(
- prompt="Say hello and confirm you're working",
- model="gemini-2.5-flash"
- )
- print(f"Prompt result: {result[:200]}...")
- print("✅ Prompt tests passed")
- asyncio.run(test_prompts())
- ```
- ### Production Readiness
- The server has been comprehensively tested with:
- - **2,500+ test cases** across 6 specialized test files with descriptive naming
- - **Complete security validation** covering all 22 critical security fixes with attack simulation
- - **Performance benchmarking** with concurrency stress testing and memory leak detection
- - **Monitoring integration testing** with graceful degradation validation
- - **@filename syntax validation** with real files across 32 of 33 tools
- - **OpenRouter integration testing** with 400+ model compatibility validation
- - **AI Collaboration testing** with 92.9% success rate and production enhancements
- - **Conversation system testing** with Redis storage and context management
- - **Specialized code review testing** for new analysis tools
- - **Error handling and edge cases** for enterprise deployment scenarios
- ## 🔧 Troubleshooting
- ### Common Issues
- #### "Tool 'gemini_cli' not found"
- **Cause**: MCP client can't connect to server or server isn't running.
- **Solutions**:
- 1. Verify absolute paths in MCP client configuration
- 2. Check that virtual environment is activated
- 3. Test server manually: `python mcp_server.py`
- 4. Check client logs for connection errors
- #### "Gemini CLI not found"
- **Cause**: Gemini CLI not installed or not in PATH.
- **Solutions**:
- 1. Install Gemini CLI: `npm install -g @google-ai/gemini-cli`
- 2. Verify installation: `gemini --version`
- 3. Set custom path: `export GEMINI_COMMAND_PATH=/path/to/gemini`
- #### Authentication Errors
- **Cause**: Gemini API key not configured or invalid.
- **Solutions**:
- 1. Configure API key: `gemini config set api_key YOUR_API_KEY`
- 2. Verify key validity: `gemini --version`
- 3. Check API quota and billing status
- #### Rate Limit Exceeded
- **Cause**: Too many requests in short time period.
- **Solutions**:
- 1. Wait for rate limit window to reset
- 2. Increase limits: `export GEMINI_RATE_LIMIT_REQUESTS=500`
- 3. Use faster model: Switch to `gemini-2.5-flash`
- #### Large Content Failures
- **Cause**: Content exceeds tool-specific character limits.
- **Solutions**:
- 1. Check content size: `wc -c your_file.txt`
- 2. Increase limits: `export GEMINI_EVAL_LIMIT=1000000`
- 3. Use chunking strategy for very large content
- 4. Use `gemini_summarize_files` for file-based analysis
- #### Server Won't Start
- **Diagnostic Steps**:
- 1. Check Python version: `python --version` (must be 3.10+)
- 2. Verify dependencies: `pip list | grep mcp`
- 3. Test imports: `python -c "import mcp"`
- 4. Check logs: `GEMINI_LOG_LEVEL=DEBUG python mcp_server.py`
- #### Performance Issues
- **Optimization Steps**:
- 1. Monitor metrics: Use `gemini_metrics()` tool
- 2. Check cache hit rates (should be >80% for repeated operations)
- 3. Reduce logging: `export GEMINI_LOG_LEVEL=WARNING`
- 4. Optimize timeouts: `export GEMINI_TIMEOUT=120`
- ### Debug Mode
- Enable comprehensive debugging:
- ```bash
- export GEMINI_LOG_LEVEL=DEBUG
- export GEMINI_OUTPUT_FORMAT=json
- python mcp_server.py
- ```
- This provides detailed information about:
- - Command execution and arguments
- - Cache operations and hit rates
- - Error details and stack traces
- - Performance metrics and timing
- - Model fallback behavior
- ### Getting Help
- If you encounter issues not covered here:
- 1. **Check server logs** for detailed error messages
- 2. **Verify Gemini CLI** works independently: `gemini --help`
- 3. **Test with simple commands** first: `gemini_version()`
- 4. **Monitor metrics** for performance insights: `gemini_metrics()`
- 5. **Check environment variables** for correct configuration
- ## 📄 Requirements
- ### System Requirements
- - **Python**: 3.10 or higher
- - **Operating System**: Linux, macOS, or Windows
- - **Memory**: 512MB minimum, 2GB recommended
- - **Disk Space**: 100MB for installation
- - **Network**: Internet connection for Gemini API access
- ### Python Dependencies
- ```
- mcp>=0.3.0
- httpx>=0.24.0
- cachetools>=5.3.0
- ```
- ### Optional Dependencies
- ```
- pytest>=7.0.0 # For development and testing
- pytest-mock>=3.10.0 # For mocking in tests
- uvicorn[standard]>=0.20.0 # For alternative server deployment
- ```
- ### External Dependencies
- - **Gemini CLI**: Google's command-line interface for Gemini AI
- - **Node.js**: Required for Gemini CLI installation (if using npm)
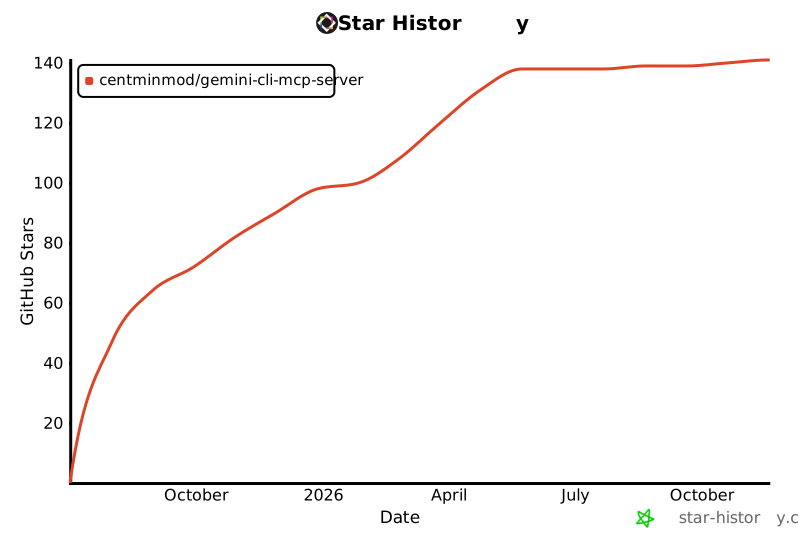
- ## Star History
- [](https://www.star-history.com/#centminmod/gemini-cli-mcp-server&Date)
Ratings and comments
Sign in to rate this skill.
Sign inFree to use. If it’s helped, pass it on.