news-aggregator-skill
"Comprehensive news aggregator that fetches, filters, and deeply analyzes real-time content from 44+ sources including Hacker News, Lobsters, Dev.to, GitHub, arXiv, Hugging Face Papers, AIHOT, TLDR AI, Import AI, BBC, The Guardian, Al Jazeera, France 24, Reuters fallback, AI Newsletters, WallStreetCN, Weibo, 少数派, InfoQ 中文, Podcasts, and user-defined OPML feeds. Use when user requests 'daily scans', 'tech news', 'finance updates', 'AI briefings', 'international news', 'deep analysis', or says '如意如意' to open the interactive menu."
Safety scan
A static text scan, not a guarantee. Select the badge to see what was scanned and every finding.
Badge for your README

Markdown
[](/listings/cclank-news-aggregator-skill)HTML
<a href="/listings/cclank-news-aggregator-skill"><img src="/api/listings/cclank-news-aggregator-skill/badge.svg" alt="findsafeskills safety rating" /></a>Install
What was scanned
The files the safety scan read, as written by the repository's author and shown as plain text. Lines with a finding are marked.
SKILL.md · Manifest · 197 lines
View this file on GitHub (read at the repository's current version: the scan did not record which commit it read)
- ---
- name: news-aggregator-skill
- description: "Comprehensive news aggregator that fetches, filters, and deeply analyzes real-time content from 44+ sources including Hacker News, Lobsters, Dev.to, GitHub, arXiv, Hugging Face Papers, AIHOT, TLDR AI, Import AI, BBC, The Guardian, Al Jazeera, France 24, Reuters fallback, AI Newsletters, WallStreetCN, Weibo, 少数派, InfoQ 中文, Podcasts, and user-defined OPML feeds. Use when user requests 'daily scans', 'tech news', 'finance updates', 'AI briefings', 'international news', 'deep analysis', or says '如意如意' to open the interactive menu."
- ---
- # News Aggregator Skill
- Fetch real-time hot news from 44+ sources (including international news + AI curated aggregators + user-defined OPML feeds), generate deep analysis reports in Chinese.
- ---
- ## 🔄 Universal Workflow (3 Steps)
- **Every** news request follows the same workflow, regardless of source or combination:
- ### Step 1: Fetch Data
- ```bash
- # Single source
- python3 scripts/fetch_news.py --source <source_key> --no-save
- # Multiple sources (comma-separated)
- python3 scripts/fetch_news.py --source hackernews,github,wallstreetcn --no-save
- # All sources (broad scan)
- python3 scripts/fetch_news.py --source all --limit 15 --deep --no-save
- # With keyword filter (auto-expand: "AI" → "AI,LLM,GPT,Claude,Agent,RAG")
- python3 scripts/fetch_news.py --source hackernews --keyword "AI,LLM,GPT" --deep --no-save
- ```
- ### Step 2: Generate Report
- Read the output JSON and format **every** item using the **Unified Report Template** below. Translate all content to **Simplified Chinese**.
- ### Step 3: Save & Present
- Save the report to `reports/YYYY-MM-DD/<source>_report.md`, then display the full content to the user.
- ---
- ## 📰 Unified Report Template
- **All sources use this single template.** Show/hide optional fields based on data availability.
- ```markdown
- #### N. [标题 (中文翻译)](https://original-url.com)
- - **Source**: 源名 | **Time**: 时间 | **Heat**: 🔥 热度值
- - **Links**: [Discussion](hn_url) | [GitHub](gh_url) ← 仅在数据存在时显示
- - **Summary**: 一句话中文摘要。
- - **Deep Dive**: 💡 **Insight**: 深度分析(背景、影响、技术价值)。
- ```
- ### Source-Specific Adaptations
- Only the **differences** from the universal template:
- | Source | Adaptation |
- |---|---|
- | **Hacker News** | **MUST** include `[Discussion](hn_url)` link |
- | **GitHub** | Use `🌟 Stars` for Heat, add `Lang` field, add `#Tags` in Deep Dive |
- | **Hugging Face** | Use `🔥 +N` upvotes for Heat, include `[GitHub](url)` if present, write **深度解读** (not just translate abstract) |
- | **Weibo** | Preserve exact heat text (e.g. "108万") |
- | **AIHOT** | `summary` 已是中文编辑稿,**直接引用**不要再翻译;Heat 字段为空也别造数据;保留 `推荐理由` 风格的一句话点评 |
- | **TLDR AI** | 单条标题往往是多主题混合(`Topic A 💻, Topic B ⚡, Topic C ⛪`),**拆成 bullet 列出每个主题**;`summary` 是 HTML 段落,需要拆出每个主题对应的一两句概述 |
- | **Import AI** | 周刊长文,标题形如 `Import AI 458: 主题1; 主题2; 主题3`。**建议默认配 `--deep`**,否则 RSS summary 只是开头几句;Deep Dive 直接提炼 Jack Clark 的核心观点而非平铺事实 |
- | **International News** | **MUST** use the Unified Report Template for every item;只使用最近 24h RSS 条目,不用更早新闻 Smart Fill;英文标题与摘要翻译成简体中文,保留原始媒体名与链接;同一事件多家媒体重复时可合并观点但不能合并链接 |
- | **Reuters** | `reuters` 使用 Google News RSS 的 `site:reuters.com` fallback;报告里保留 `Reuters (Google News fallback)` source,不要写成官方公开 RSS |
- ---
- ## 🛠️ Tools
- ### fetch_news.py
- | Arg | Description | Default |
- |---|---|---|
- | `--source` | Source key(s), comma-separated. See table below. | `all` |
- | `--limit` | Max items per source | `15` |
- | `--keyword` | Comma-separated keyword filter | None |
- | `--deep` | Download article text for richer analysis | Off |
- | `--save` | Force save to reports dir | Auto for single source |
- | `--outdir` | Custom output directory | `reports/YYYY-MM-DD/` |
- ### Available Sources (44+ with user OPML)
- | Category | Key | Name |
- |---|---|---|
- | **Global News** | `hackernews` | Hacker News |
- | | `36kr` | 36氪 |
- | | `wallstreetcn` | 华尔街见闻 |
- | | `tencent` | 腾讯新闻 |
- | | `weibo` | 微博热搜 |
- | | `v2ex` | V2EX |
- | | `producthunt` | Product Hunt |
- | | `github` | GitHub Trending |
- | **Tech Community** (v2) | `lobsters` | Lobsters |
- | | `devto` | Dev.to |
- | **AI/Tech** | `huggingface` | HF Daily Papers |
- | | `arxiv` | arXiv (cs.AI/cs.CL/cs.LG, v2) |
- | | `ai_newsletters` | All AI Newsletters (aggregate) |
- | | `bensbites` | Ben's Bites |
- | | `interconnects` | Interconnects (Nathan Lambert) |
- | | `oneusefulthing` | One Useful Thing (Ethan Mollick) |
- | | `chinai` | ChinAI (Jeffrey Ding) |
- | | `memia` | Memia |
- | | `aitoroi` | AI to ROI |
- | | `kdnuggets` | KDnuggets |
- | **Chinese** (v2) | `sspai` | 少数派 |
- | | `infoq_cn` | InfoQ 中文站(RSS 只给标题,**推荐配 `--deep`** 拿正文) |
- | **AI Curated** (v3) | `aihot` | AIHOT 中文 AI 精选(跨源 + 中文编辑稿)|
- | | `tldr_ai` | TLDR AI 英文日刊 |
- | | `import_ai` | Import AI by Jack Clark 周刊(**推荐 `--deep`**)|
- | **International News** | `international` | 最近 24h 国际新闻聚合(BBC / Guardian / Al Jazeera / France 24 / Reuters fallback)|
- | | `bbc_top` | BBC Top News (24h) |
- | | `bbc_world` | BBC World (24h) |
- | | `bbc_chinese` | BBC 中文 (24h) |
- | | `guardian_world` | The Guardian World (24h) |
- | | `aljazeera` | Al Jazeera (24h) |
- | | `france24` | France 24 (24h) |
- | | `reuters` | Reuters via Google News RSS fallback (24h) |
- | **Podcasts** | `podcasts` | All Podcasts (aggregate) |
- | | `lexfridman` | Lex Fridman |
- | | `80000hours` | 80,000 Hours |
- | | `latentspace` | Latent Space |
- | **Essays** | `essays` | All Essays (aggregate) |
- | | `paulgraham` | Paul Graham |
- | | `waitbutwhy` | Wait But Why |
- | | `jamesclear` | James Clear |
- | | `farnamstreet` | Farnam Street |
- | | `scottyoung` | Scott Young |
- | | `dankoe` | Dan Koe |
- | **Custom** (v2) | `user` | Your OPML feeds (see below) |
- ### 自定义订阅源 (User OPML)
- 把你常看的 RSS/Atom 源写进 OPML,`--source user` 即可统一抓取。
- **1. 放置 OPML 文件**(按优先级查找):
- - `~/.config/news-aggregator/user_sources.opml`(推荐,跨 skill 复用)
- - `<skill_root>/user_sources.opml`(本仓库内)
- **2. 文件格式**:标准 OPML 2.0,可直接从 Feedly / Inoreader / NetNewsWire 导出。参考 `user_sources.opml.example`:
- ```xml
- <outline type="rss" text="Simon Willison" title="Simon Willison"
- xmlUrl="https://simonwillison.net/atom/everything/" />
- ```
- 只 `xmlUrl` 必填,其它可选。
- **3. 运行**:`python3 scripts/fetch_news.py --source user --limit 15`
- ### daily_briefing.py (Morning Routines)
- Pre-configured multi-source profiles:
- ```bash
- python3 scripts/daily_briefing.py --profile <profile>
- ```
- | Profile | Sources | Instruction File |
- |---|---|---|
- | `general` | HN, 36Kr, GitHub, Weibo, PH, WallStreetCN | `instructions/briefing_general.md` |
- | `finance` | WallStreetCN, 36Kr, Tencent | `instructions/briefing_finance.md` |
- | `tech` | GitHub, HN, Product Hunt | `instructions/briefing_tech.md` |
- | `social` | Weibo, V2EX, Tencent | `instructions/briefing_social.md` |
- | `ai_daily` | HF Papers, AI Newsletters | `instructions/briefing_ai_daily.md` |
- | `reading_list` | Essays, Podcasts | (Use universal template) |
- **Workflow**: Execute script → Read corresponding instruction file → Generate report following both the instruction file AND the universal template.
- ---
- ## ⚠️ Rules (Strict)
- 1. **Language**: ALL output in **Simplified Chinese (简体中文)**. Keep well-known English proper nouns (ChatGPT, Python, etc.).
- 2. **Time**: **MANDATORY** field. Never skip. If missing in JSON, mark as "Unknown Time". Preserve "Real-time" / "Today" / "Hot" as-is.
- 3. **Anti-Hallucination**: Only use data from the JSON. Never invent news items. Use simple SVO sentences. Do not fabricate causal relationships.
- 4. **Smart Keyword Expansion**: When user says "AI" → auto-expand to `"AI,LLM,GPT,Claude,Agent,RAG,DeepSeek"`. Similar expansions for other domains.
- 5. **Smart Fill**: If results < 5 items in a time window, supplement with high-value items from wider range. Mark supplementary items with ⚠️. **Exception**: International News sources are a hard 24h window; do not supplement with older items.
- 6. **Save**: Always save report to `reports/YYYY-MM-DD/` before displaying.
- ---
- ## 📋 Interactive Menu
- When the user says **"如意如意"** or asks for "menu/help":
- 1. Read `templates.md`
- 2. Display the menu
- 3. Execute the user's selection using the **Universal Workflow** above
- ---
- ## Requirements
- - Python 3.8+, `pip install -r requirements.txt`
- - Playwright (for HF Papers & Ben's Bites): `playwright install chromium`
README.md · README · 137 lines
View this file on GitHub (read at the repository's current version: the scan did not record which commit it read)
- # 🗞️ News Aggregator Skill
- [](https://www.python.org/downloads/)
- [](https://opensource.org/licenses/MIT)
- [](https://github.com/cclank/news-aggregator-skill)
- [](https://github.com/cclank/news-aggregator-skill/network)
- **全网科技/金融/AI深度新闻聚合助手,专为智能 Agent 打造的高效信息引擎。**
- ---
- ## ✨ 核心特性
- - **🌍 全网多源聚合**:一站式覆盖跨越硅谷科技、中国创投、开源社区、金融市场、国际新闻以及顶级 AI 播客/硬核推文的 **44+ 个高价值信源**。
- - **🔧 OPML 自定义订阅**:内置 44+ 源覆盖不全时,在 `user_sources.opml` 里新增一条带 `xmlUrl` 的 RSS/Atom 订阅项即可接入,兼容 Feedly / Inoreader 等 RSS 阅读器导出格式。未内置的媒体、机构博客和个人订阅源(如 NYT 中文)都可走这条路,详见 `user_sources.opml.example`。
- - **🚀 完美支持 OpenClaw**:专为原生大模型 Agent 平台(如 OpenClaw、Code Agent)深度定制,即插即用,沉浸式体验信息流。
- - **🆓 开箱即用 (Zero-Config)**:纯净抓取,**无需配置任何第三方 API Key**,告别繁琐的环境变量和额度焦虑。
- - **🧠 AI 智能深度阅读 (Deep Fetch)**:智能穿透防爬虫机制(内置 Playwright 绕过 Cloudflare),抓取完整正文内容交给大模型过滤、提炼与总结。
- - **📰 场景化早报 (Daily Briefings)**:内置多套场景预设(综合早报、财经早报、科技早报、吃瓜早报、AI深度日报),一键生成杂志级排版的 Markdown 中文报告。
- - **🪄 魔法交互菜单**:支持通过专属口令唤醒全局交互式菜单,告别繁琐长难句,只需输入序号即可指哪打哪。
- ---
- ## 📚 聚合信源图谱
- 系统现已覆盖全球 **44+** 个主流高价值信息渠道,随取随用:
- ### 🎯 核心新闻源
- - **全球科技**:🦄 Hacker News (`hackernews`), 🐱 Product Hunt (`producthunt`)
- - **开源进展**:🐙 GitHub Trending (`github`), 🤓 V2EX (`v2ex`)
- - **国内风控**:🚀 36Kr (`36kr`), 🐧 腾讯科技 (`tencent`)
- - **社会金融**:🔴 微博热搜 (`weibo`), 📈 华尔街见闻 (`wallstreetcn`)
- - **AI 论文**:🤗 Hugging Face Papers (`huggingface`)
- ### 🆕 扩展源 (v2)
- - **技术社区**:🦞 Lobsters (`lobsters`), 👩💻 Dev.to (`devto`)
- - **学术原文**:📜 arXiv (`arxiv`) —— cs.AI/CL/LG 最新提交
- - **中文深度**:📕 少数派 (`sspai`), 💻 InfoQ 中文 (`infoq_cn`)
- ### 🎯 AI 精选聚合 (v3) —— 单源信息密度顶 5-10 个原始源
- - **中文 AI 跨源精选**:🔥 AIHOT (`aihot`) —— 跨 X / IT 之家 / DeepMind / Anthropic / 各 AI 公司 newsroom 的中文编辑稿日更
- - **英文日刊**:📨 TLDR AI (`tldr_ai`) —— 每日 5-10 主题摘要
- - **英文周刊深度**:📜 Import AI (`import_ai`) —— Jack Clark(前 OpenAI/Anthropic 联创)独立思考
- ### 🌍 国际新闻源
- - **国际聚合**:🌍 International (`international`) —— BBC / Guardian / Al Jazeera / France 24 / Reuters fallback 最近 24h 混合扫描
- - **BBC**:BBC Top News (`bbc_top`), BBC World (`bbc_world`), BBC 中文 (`bbc_chinese`) —— 最近 24h
- - **全球媒体**:The Guardian World (`guardian_world`), Al Jazeera (`aljazeera`), France 24 (`france24`) —— 最近 24h
- - **Reuters fallback**:Reuters (`reuters`) —— 使用 Google News RSS 的 `site:reuters.com` 最近 24h 检索结果,适合无 Reuters Connect 账号时轻量追踪
- ### 🔧 自定义订阅
- - 通用 OPML (`user`) —— 在 OPML 里添加带 `xmlUrl` 的 RSS/Atom 订阅项即可接入
- ### 📧 AI 行业内参 (Newsletters & Creators)
- - **🧪 Latent Space AINews** (`latentspace_ainews`) - *(近期新增)*
- - **ChinAI (Jeffrey Ding)** (`chinai`)
- - **Memia (Ben Reid)** (`memia`)
- - **Ben's Bites** (`bensbites`)
- - **One Useful Thing (Ethan Mollick)** (`oneusefulthing`)
- - **Interconnects (Nathan Lambert)** (`interconnects`)
- - **AI to ROI & KDnuggets** 等...
- ### ✍️ 深度思考 & 播客
- - **行业泰斗专栏**: Paul Graham, James Clear, Wait But Why, Scott Young...
- - **顶级硬核播客**: Lex Fridman Podcast, Latent Space (swyx), 80,000 Hours...
- ---
- ## 📥 安装指南
- ### 第一步:安装到 Code Agent
- 选择以下任一方式将 Skill 添加到您的 Agent:
- #### 方法 A:使用 Openskills CLI (推荐)
- 会自动处理路径依赖和配置同步。
- ```bash
- # 安装 skill
- openskills install git@github.com:cclank/news-aggregator-skill.git
- # 同步配置到 Agent
- openskills sync
- ```
- #### 方法 B:使用 NPX
- 直接从远程仓库添加。
- ```bash
- npx skills add https://github.com/cclank/news-aggregator-skill
- ```
- #### 方法 C:手动集成
- ```bash
- git clone git@github.com:cclank/news-aggregator-skill.git YourProject/.claude/skills/news-aggregator-skill
- ```
- ### 第二步:安装 Python 依赖
- 进入已安装的 Skill 目录,执行依赖安装(如果您的 Agent 足够聪明,可要求其自动配置):
- ```bash
- cd YourProject/.claude/skills/news-aggregator-skill
- pip install -r requirements.txt
- playwright install chromium
- ```
- ---
- ## 🚀 如何使用
- ### 1. 🔮 唤醒交互菜单 (推荐)
- 最简单、最迷人的使用方式,来自专属交互彩蛋,直接召唤智能指令菜单:
- > **"news-aggregator-skill 如意如意"**
- 系统将立即为您展示多达 53 个功能选项的精美列表,直接回复数字序号即可生成完美排版的今日大盘!
- ### 2. 🗣️ 自然语言触发
- 您也可以直接通过对话指定需求:
- - **场景日报**:"帮我跑一份 💰财经早报,看看今天华市有什么动静。"
- - **深度穿透**:"抓取 5 条最新的 GitHub 趋势,记得开启 Deep Fetch 深入阅读下他们的 README。"
- - **硬核科研**:"看看今天 HuggingFace 有什么新发的神仙论文?"
- - **国际新闻**:"抓取 BBC、Reuters 和 Al Jazeera 的今日国际新闻。"
- - **自由组合**:"帮我把 Hacker News, 华尔街见闻 和 微博热搜 今天的前十条揉在一起生成一个早报。"
- - **自定义订阅**:拷一份 `user_sources.opml.example` 到 `user_sources.opml`(或 `~/.config/news-aggregator/user_sources.opml`),加自己想看的 RSS,运行 `python scripts/fetch_news.py --source user --limit 15`
- ---
- ## 💡 开发与扩展
- 欢迎提交 PR 为框架接入新的全球优质信源。我们期望共建一个**最纯净、最高效、抗干扰**的防降智信息获取舱。
- ## ⭐ Star History
- [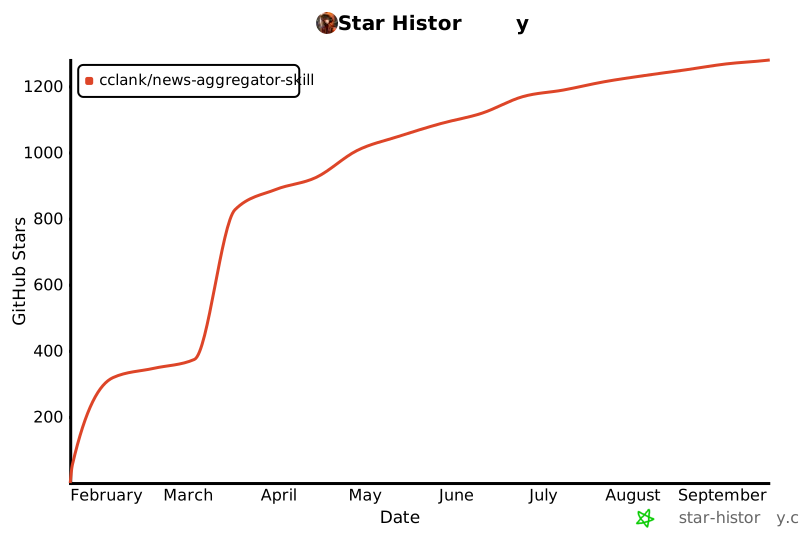](https://www.star-history.com/#cclank/news-aggregator-skill&Date)
- 📝 **License**: MIT License
Ratings and comments
Sign in to rate this skill.
Sign inFree to use. If it’s helped, pass it on.