schemagate
Text-to-SQL access control: schema selection that gives the LLM only the tables the caller is allowed to read. Row-level-security-aware table pruning for LangChain, MCP and any SQL agent. Postgres, Oracle, MySQL, SQL Server. 75% fewer prompt tokens.
Safety scan
A static text scan, not a guarantee. Select the badge to see what was scanned and every finding.
Check it deeper on your machine
It has changed since its scan on 11 Nov 2026.
As a Claude Code plugin, install it and then ask Claude Code:
/plugin marketplace add keithmackay/mackayi/plugin install scanskillsafety@mackayiDo a deep scan of https://github.com/ashishsinha1602/schemagate with scanskillsafety
Or from a terminal, clone it and run it:
git clone https://github.com/keithmackay/scanskillsafety-skill ~/.claude/skills/scanskillsafetynode ~/.claude/skills/scanskillsafety/cli.cjs --deep 'https://github.com/ashishsinha1602/schemagate'
It checks the exact commit: every file, its packages against OSV (api.osv.dev), how it compares with this page's scan (findsafeskills.com receives the repository's address), and, if you agree, Claude reading every file with your own Claude subscription. It never runs the code.
Badge for your README

Markdown
[](/listings/ashishsinha1602--schemagate)HTML
<a href="/listings/ashishsinha1602--schemagate"><img src="/api/listings/ashishsinha1602--schemagate/badge.svg" alt="findsafeskills safety rating" /></a>Install
Install instructions from the README
As written by the repo's author. findsafeskills has not verified these steps.
pip install schemagate
That's the whole thing. One dependency (SQLAlchemy), no API key, no model download. The default embedder is a hashed n-gram vectoriser that runs offline and gives byte-identical results on every machine.
Extras, all optional:
pip install 'schemagate[postgres]'     'schemagate[oracle]'
pip install 'schemagate[mssql]'        'schemagate[mysql]'
pip install 'schemagate[anthropic]'    'schemagate[openai]'      'schemagate[gemini]'
pip install 'schemagate[huggingface]'
`huggingface` is the no-key, nothing-leaves-the-machine path, and it is the one extra that is heavy: about 2 GB of wheels plus a 3.1 GB model download the first time you use it. It is deliberately kept out of `schemagate[all]`. [docs/local-models.md](docs/local-models.md) has the whole story — the downloads, the load you wait through once, what it is good at and where it is worse than a hosted model.
**Every release is signed.** The wheels carry [PEP 740](https://peps.python.org/pep-0740/) attestations — a signature from GitHub naming the workflow, repository and commit that built that exact file. Nothing is uploaded by hand and there is no API token to steal. Check one yourself with `gh attestation verify <wheel> --repo ashishsinha1602/schemagate`.
What was scanned
The files the safety scan read, as written by the repository's author and shown as plain text. Lines with a finding are marked.
.claude-plugin/marketplace.json · Manifest · 20 lines
View this file on GitHub (read at the repository's current version: the scan did not record which commit it read)
This file has changed since it was scanned, so this is not exactly the text that was scanned, and no line is marked. The findings are listed with the safety scan above.
- {
- "$schema": "https://anthropic.com/claude-code/marketplace.schema.json",
- "name": "schemagate",
- "owner": {
- "name": "Ashish Sinha",
- "url": "https://github.com/ashishsinha1602"
- },
- "metadata": {
- "description": "schemagate for Claude Code: text-to-SQL with only the tables a question needs"
- },
- "plugins": [
- {
- "name": "schemagate",
- "description": "Text-to-SQL with ~91% fewer schema tokens: Claude sees only the tables a question needs, and only the ones the caller may read. #1 on BIRD Mini-Dev.",
- "source": "./plugins/schemagate",
- "category": "database",
- "homepage": "https://github.com/ashishsinha1602/schemagate"
- }
- ]
- }
README.md · README · 1,500 lines
View this file on GitHub (read at the repository's current version: the scan did not record which commit it read)
This file has changed since it was scanned, so this is not exactly the text that was scanned, and no line is marked. The findings are listed with the safety scan above.
- # schemagate — fewer tokens for text-to-SQL, and only the tables the caller may read
- [](https://pypi.org/project/schemagate/)
- [](https://pypi.org/project/schemagate/)
- [](https://github.com/ashishsinha1602/schemagate/actions/workflows/ci.yml)
- [](LICENSE)
- [](#status)
- [](https://bird-bench.github.io/)
- [](benchmarks/results/uniql_oracle/README.md)
- [](https://www.bestpractices.dev/projects/15353)
- [](https://scorecard.dev/viewer/?uri=github.com/ashishsinha1602/schemagate)
- [](https://api.reuse.software/info/github.com/ashishsinha1602/schemagate)
- [](https://pepy.tech/projects/schemagate)
- [](https://registry.modelcontextprotocol.io/v0/servers?search=io.github.ashishsinha1602/schemagate)
- [](https://ashishsinha1602.github.io/schemagate/)
- Most text-to-SQL prompts carry the whole schema, and on a big database that is most of the prompt, on every question. schemagate sends the model only the tables the question needs: **91.1% fewer schema tokens (median) on databases with 50+ tables** ([benchmark](BENCHMARKS.md)). It filters by the caller's grants first, so restricted tables are absent from the prompt rather than ranked low. Works with LangChain, LlamaIndex, MCP, or any SQL agent, on Postgres, Oracle, MySQL, SQL Server and SQLite.
- 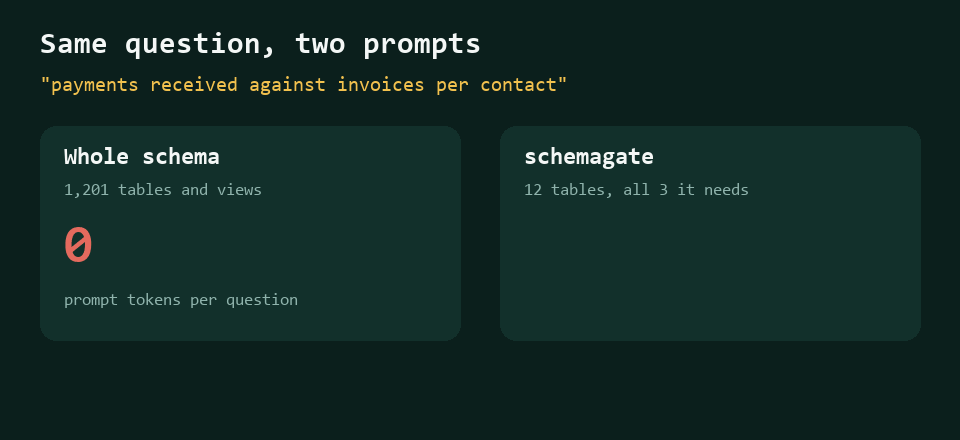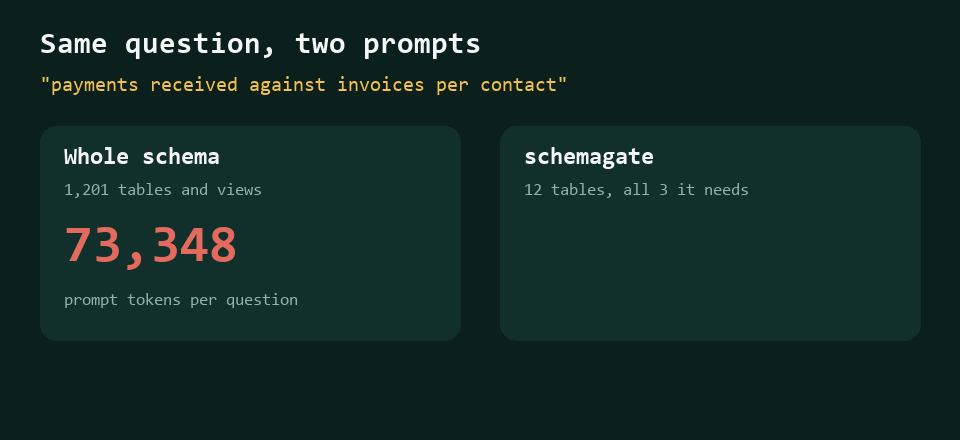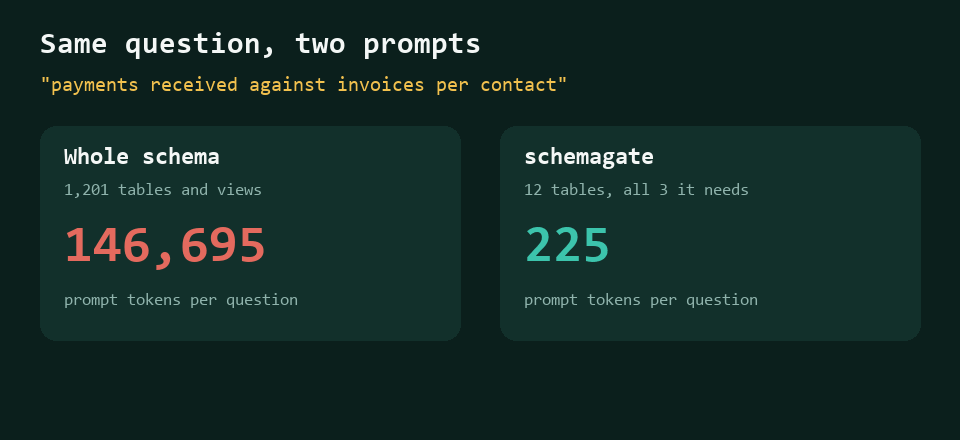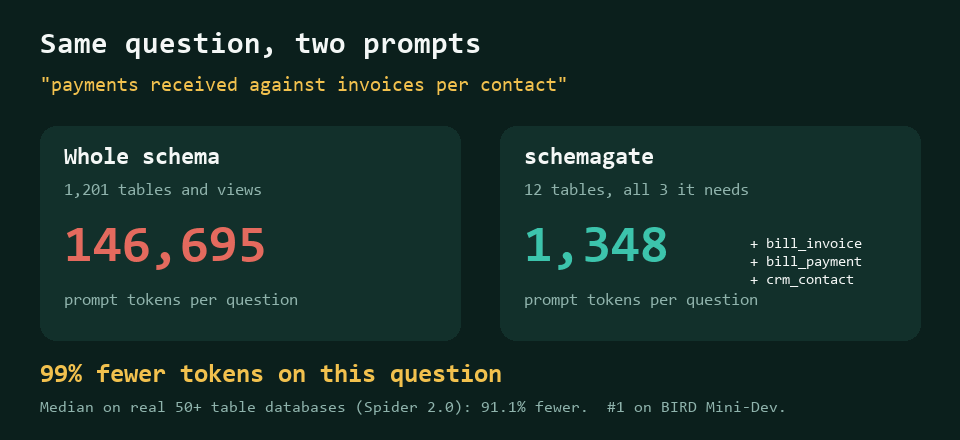
- <sub>Measured, not drawn: `python docs/media/make_token_gif.py` rebuilds it from the seeded 1,201-object fixture, counting with tiktoken's cl100k_base.</sub>
- **#1 on BIRD's Mini-Dev leaderboard in all three dialects**: SQLite 81.0, PostgreSQL 72.6, MySQL 72.4 execution accuracy, with Claude Opus 5.5 and one model call per question ([leaderboard](https://bird-bench.github.io/), [run files](benchmarks/results/bird_minidev/README.md)). Smaller prompts, no accuracy given up.
- If it cut your prompt, a ⭐ helps other people building SQL agents find it.
- 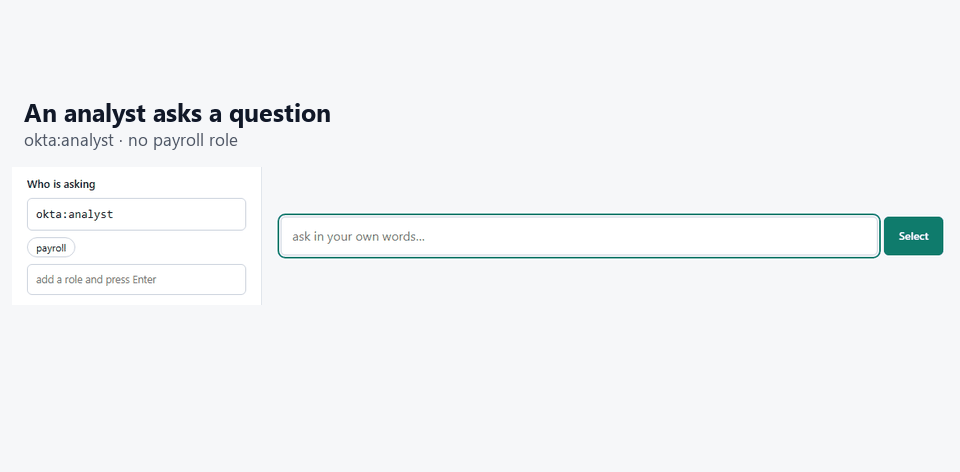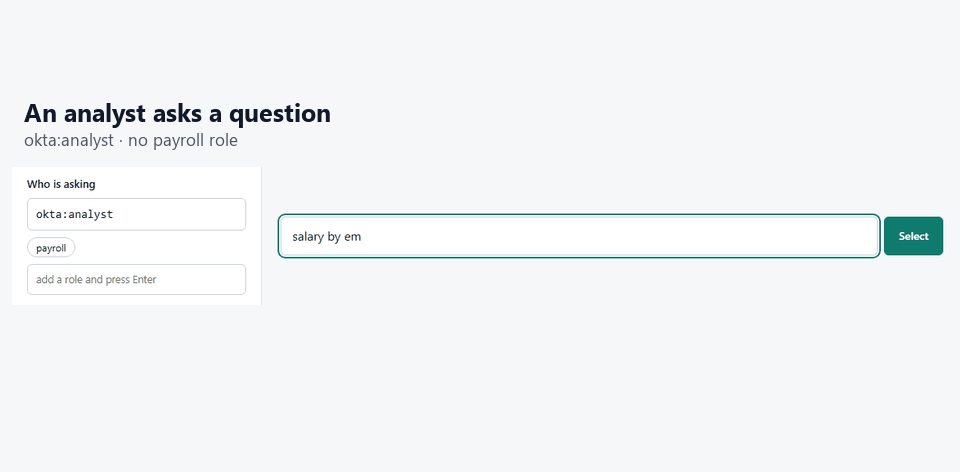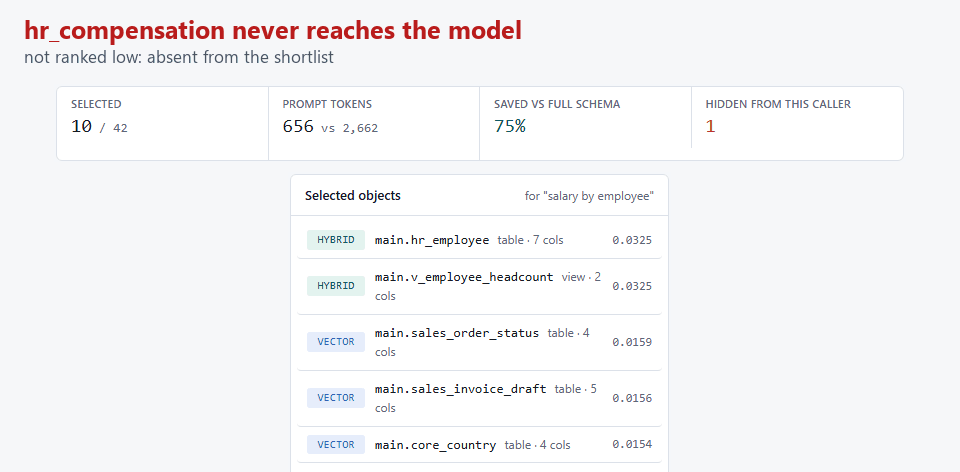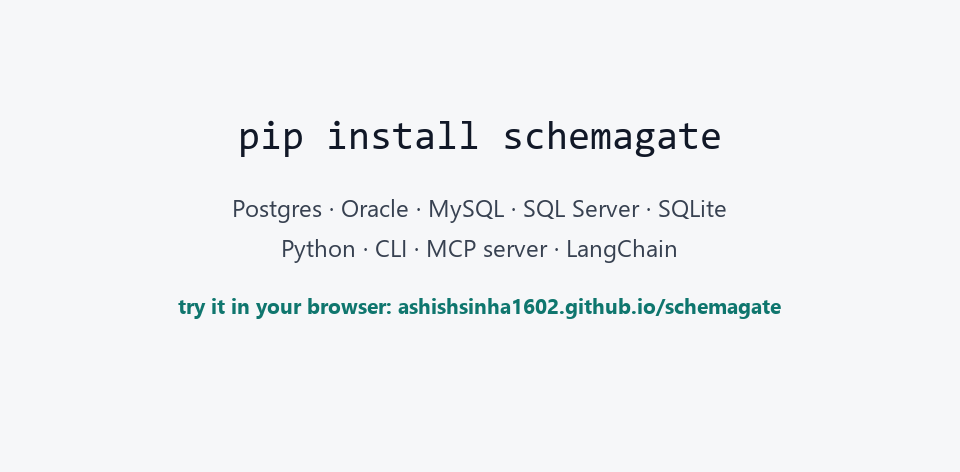
- With row-level security alone the failure is quiet: the model writes valid SQL against a table the caller cannot read, RLS strips every row, and the user is told "no records found" — indistinguishable from "this data does not exist."
- [Demo](https://ashishsinha1602.github.io/schemagate/) · [Install](https://ashishsinha1602.github.io/schemagate/install/) · [Benchmarks](https://ashishsinha1602.github.io/schemagate/benchmarks/) · [Local models](https://ashishsinha1602.github.io/schemagate/local-models/) · [What it costs](https://ashishsinha1602.github.io/schemagate/cost/) · [Coming from Vanna](https://ashishsinha1602.github.io/schemagate/vanna-alternative/)
- Same question, two callers, no database and no key:
- ```bash
- schemagate demo "salary by employee" # hr_compensation absent
- schemagate demo "salary by employee" --principal okta:hr --role payroll # now it is first
- ```
- Absent, not ranked low. A table the caller may not read never enters the
- prompt, so no rewording of the question reaches it and there is nothing to
- filter out of the answer afterwards.
- *[Try it in the browser](https://ashishsinha1602.github.io/schemagate/) — no
- install, no database, no model call.*
- ## And it answers
- The selection is a prompt, so the rest follows:
- ```bash
- pip install schemagate
- schemagate demo "which customers owe us money" --answer --provider <provider> --model <model-id>
- ```
- ```
- main.crm_customer main.crm_contact main.v_customer_balance (+5)
- 8 of 42 objects · ~383 prompt tokens instead of ~2,036
- -- SQL written by <provider> / <model-id>, from 8 tables
- SELECT c.id, p.display_name, v.account_number, v.invoiced, v.paid,
- (v.invoiced - v.paid) AS balance_due
- FROM v_customer_balance v
- JOIN crm_customer c ON c.id = v.id_customer
- JOIN core_party p ON p.id = c.id_party
- WHERE v.invoiced > v.paid
- id display_name account_number invoiced paid balance_due
- -- ----------------- -------------- -------- ------- -----------
- 1 Northwind Trading ACC-1001 33960.0 22080.0 11880.0
- 2 Kellner GmbH ACC-1002 8760.0 3000.0 5760.0
- ```
- Rows, from a question, with no database to set up — that runs against a
- bundled 42-object schema. `<provider>` is the model service you choose:
- `openai`, `anthropic`, `gemini`, `oci`, `local` (no key at all), or `auto`
- (whichever key is set). Point it at your own database with `--url`:
- ```bash
- schemagate select "which customers owe us money" \
- --url "postgresql+psycopg://user:pw@host/db" --answer --provider <provider> --model <model-id>
- ```
- No key? Drop `--provider` and it prints a prompt to paste into any chat, then
- run the SQL it gives you back with `--sql "SELECT ..."`.
- More of the bundled schema, with the questions people actually type:
- ```bash
- schemagate demo "which customers owe us money"
- schemagate demo "late shipments by carrier" --prompt # the DDL the model gets
- ```
- Against your own database it's the same shape:
- ```bash
- schemagate select "revenue by month" --url postgresql://localhost/app --principal okta:jdoe --role finance
- schemagate studio --url postgresql://localhost/app # the same thing, as a page
- ```
- `schemagate studio` opens a local page where you type questions, switch the caller's
- roles, edit hints, and watch what reaches the prompt and what doesn't. The same
- page runs publicly at **https://ashishsinha1602.github.io/schemagate/** on the six
- bundled schemas, in your browser, with no server behind it. The selector on that page is a JavaScript
- port of this library, and a test runs both against 1,789 cases and requires
- identical rankings.
- If you're coming from Vanna (archived March 2026), `docs/migrating-from-vanna.md`
- is the short version: Vanna applied identity when the SQL *ran*; schemagate applies
- it before the model sees the schema. Your `User` maps to a `Principal` in one
- line.
- ## What it saves
- Every text-to-SQL call pays for the schema in the prompt. Dump the whole thing
- and you pay for every table on every question; hand the model six tables and
- you pay for six. Measured on the test schemas, average over their golden
- questions, same built-in estimator as `tests/bench.py`:
- | schema | objects | full schema, every call | schemagate, average | reduction |
- |---|---:|---:|---:|---:|
- | Commerce | 42 | 2,483 tokens | 604 | 76% |
- | Clinical claims | 27 | 1,568 | 543 | 65% |
- | Claims warehouse (star) | 51 | 3,312 | 880 | 73% |
- | Bank ledger and trading | 39 | 2,255 | 637 | 72% |
- | IoT telemetry | 40 | 2,125 | 448 | 79% |
- | Hostile (4 schemas, copies of everything) | 260 | 16,095 | 444 | **97%** |
- The last row is the one that matters: the selection stays around six tables
- no matter how big the schema is, so the saving grows with the schema. Real
- databases are the last row, not the first.
- The same count on public schemas nobody here wrote (no model called;
- [BENCHMARKS.md](BENCHMARKS.md#prompt-tokens-on-public-schemas-the-saving-grows-with-the-schema)
- has the script). On Spider 2.0's real BigQuery and Snowflake warehouses, the
- median database with 50 or more tables went from its full schema to a
- selection **91.1% smaller** (24 databases). On BIRD, whose databases have a median of seven
- tables, the median saving was 8.8%: there was little to cut. The price of
- cutting is that a needed table can be left out. On the warehouses, every
- table the gold query reads was in the selection for 86.7% of questions.
- Against the retrievers other tools use, at the same number of tables and no
- model calls, schemagate selected every needed table for 85.3% of warehouse
- questions where BM25 managed 78.7% and embedding search 78.2%, and 98.7% of
- BIRD questions against 81.0% and 89.4%
- ([head-to-head](BENCHMARKS.md#head-to-head-schemagate-against-the-retrievers-other-tools-use)).
- On Snowflake's SQL-Schema-Retrieval benchmark (table level, recall@10) the
- hashed embedder scores Spider 100.0, BIRD 99.2, BEAVER 65.9, LiveSQLBench 95.3
- and LiveSQLBench-Large 64.9 (73.9 with all-MiniLM-L6-v2), above the paper's best
- model on four of the five and below Qwen3-Embedding-4B (75.8) on the fifth
- ([details](BENCHMARKS.md#schema-retrieval-scored-by-snowflakes-benchmark)).
- Worked example, with a price you should replace with your own: a 260-object
- schema, 5,000 questions a day, an input price of $3 per million tokens. Full
- schema: 16,095 × 5,000 × 30 = 2.4 billion tokens a month, about $7,200. With
- schemagate: 444 × 5,000 × 30 = 67 million, about $200. The
- [browser demo](https://ashishsinha1602.github.io/schemagate/) has these two
- numbers as editable fields under the stats, so you can put in your own volume
- and price and watch it recompute against whatever question you ask.
- Two more things that cost nothing here and money elsewhere: the selector
- itself never calls a model (BM25 plus a hashed embedder, offline,
- milliseconds), and the optional descriptions can be written by any chat window
- you already pay for instead of an API key — see
- [Without an API key](#without-an-api-key).
- ## The problem this solves
- Two things go wrong when you point an LLM at a database schema.
- The first is cost. Most systems paste the whole schema into the prompt on every
- question. That's fine for twenty tables and ruinous for two thousand.
- The second is worse, and it's the reason I wrote this. Schema selection happens
- *before* the query runs, so it happens before row-level security can do
- anything. If your selection step isn't identity-aware, the model gets handed a
- table the caller can't read. It writes perfectly good SQL. RLS or VPD filters
- every row out. The user sees "no records found" and believes it.
- That's not an access-denied message. It's a wrong answer with a confident tone,
- and the user has no way to tell the difference. Filtering the catalog by
- identity first is the only way I know to avoid it.
- ```python
- from schemagate import Catalog, Principal
- cat = Catalog().bootstrap("postgresql://localhost/app") # or: from schemagate.demo_schema import demo_catalog; cat = demo_catalog()
- cat.hint("invoice_draft", "pre-issue drafts only, not real revenue")
- cat.restrict("hr_compensation", ["payroll"])
- sel = cat.select("revenue by month", top_k=6,
- principal=Principal("okta:jdoe", roles={"finance"}))
- sel.prompt_fragment() # compact DDL, ready for the system prompt
- sel.object_list # [{'owner': ..., 'name': ...}]
- sel.explain() # why each object was picked
- ```
- `hr_compensation` is not in that result and its name does not appear anywhere
- in the prompt text.
- ## Install
- ```bash
- pip install schemagate
- ```
- That's the whole thing. One dependency (SQLAlchemy), no API key, no model
- download. The default embedder is a hashed n-gram vectoriser that runs offline
- and gives byte-identical results on every machine.
- Extras, all optional:
- ```bash
- pip install 'schemagate[postgres]' 'schemagate[oracle]'
- pip install 'schemagate[mssql]' 'schemagate[mysql]'
- pip install 'schemagate[anthropic]' 'schemagate[openai]' 'schemagate[gemini]'
- pip install 'schemagate[huggingface]'
- ```
- `huggingface` is the no-key, nothing-leaves-the-machine path, and it is the
- one extra that is heavy: about 2 GB of wheels plus a 3.1 GB model download the
- first time you use it. It is deliberately kept out of `schemagate[all]`.
- [docs/local-models.md](docs/local-models.md) has the whole story — the
- downloads, the load you wait through once, what it is good at and where it is worse
- than a hosted model.
- **Every release is signed.** The wheels carry [PEP 740](https://peps.python.org/pep-0740/)
- attestations — a signature from GitHub naming the workflow, repository and
- commit that built that exact file. Nothing is uploaded by hand and there is no
- API token to steal. Check one yourself with
- `gh attestation verify <wheel> --repo ashishsinha1602/schemagate`.
- ## Quick start
- ```bash
- pip install schemagate # add an extra for your driver, below
- schemagate # opens http://127.0.0.1:8770 on the 42-object demo
- ```
- Every wheel on PyPI carries a signed provenance attestation naming the commit that built it:
- `gh attestation verify <wheel> --repo ashishsinha1602/schemagate`.
- Or without installing anything, with every driver already in the image:
- ```bash
- docker run -p 8770:8770 -e SCHEMAGATE_DATABASE_URL=postgresql://… ghcr.io/ashishsinha1602/schemagate
- ```
- Leave the URL off and it opens on a 42-object sample schema with data in it,
- so there is something to ask questions of before you point it at your own.
- Then, in the page:
- 1. **Connect.** Paste a URL — `postgres://…`, `postgresql://…`, `mysql://…`,
- `oracle://…` and a JDBC string all work, as does the wallet form for an
- Autonomous Database. Tick **Save this connection** and give it a name and
- the next start reconnects on its own.
- 2. **Catalogue.** *Settings → Model* → pick a provider, paste a key, **Save
- model** (it is saved, so a restart does not ask again). Then **Catalogue
- this database** in the rail. One sentence per object, cached to disk, so a
- second run costs nothing.
- 3. **Ask.** Type a question in your own words. You get the objects that answer
- it, the DDL a model would receive, the SQL, and the rows.
- Drivers come as extras — `schemagate[postgres]`, `[oracle]`, `[mysql]`,
- `[mssql]`, or `schemagate[all]` for the lot:
- ```bash
- pip install 'schemagate[postgres]'
- ```
- ### When a question picks the wrong table
- Two levers, both per database and both applied on every reconnect:
- * **Hints** (rail → Hints): one object, in your words. *"MyConvo campaigns:
- personal-inbox sends from a user's own mailbox."*
- * **Glossary** (`POST /api/glossary`): one *word*, everywhere. A term here is
- fed to the cataloguing prompt, so every description uses your vocabulary,
- and expanded into questions that mention it.
- A hint beats a generated description everywhere, and neither needs
- re-cataloguing.
- ## Commands
- Every subcommand, and what it is for. `schemagate <command> --help` prints the
- same thing.
- ```
- schemagate demo [question] run against the bundled 42-object schema
- schemagate select --url URL [question] select against your own database
- schemagate studio [--url URL] the Studio page, served locally
- schemagate describe --url URL write AI descriptions for your objects
- schemagate certify URL end-to-end check on a real engine
- ```
- ### `demo` and `select`
- `select` is `demo` pointed at a real database; they take the same flags.
- ```bash
- schemagate demo "who reports to whom"
- schemagate select --url postgresql+psycopg://user:pw@host/db "unpaid invoices"
- schemagate select --schema APP --url "oracle+oracledb://ADMIN:pw@/?dsn=(description=(address=(protocol=tcps)(port=1522)(host=adb.us-phoenix-1.oraclecloud.com))(connect_data=(service_name=abc123_mydb_low.adb.oraclecloud.com)))" "unpaid invoices" # Autonomous Database
- ```
- | flag | what it does |
- |---|---|
- | `--top-k N` | how many objects to select (default 6) |
- | `--principal SOURCE:ID` | who is asking, e.g. `okta:jdoe`, `db:APPUSER`. Must be namespaced |
- | `--memory PATH\|1` | remember question → SQL pairs that ran and use them next time (pins + worked examples). `1` for `~/.schemagate/memory/`. Off by default |
- | `--role ROLE` | a role the caller holds; repeatable |
- | `--prompt` | print the prompt instead of the selection |
- | `--explain` | show why each object was picked, and what was withheld |
- | `--answer` | write the SQL and run it (needs a provider) |
- | `--provider NAME` / `--model ID` | which model to use |
- | `--limit N` | row cap for `--answer` |
- | `--restrict-from-grants` | take visibility from the database's own GRANTs |
- | `--rerank` | let the model reorder the shortlist the maths produced (pooled Spider 80.3% -> 96.5%, BIRD 88.6% -> 96.7% of questions with every gold table in the top 5; [BENCHMARKS.md](BENCHMARKS.md)) |
- | `--values` | sample short, non-personal column values |
- | `--include` / `--exclude PATTERN` | narrow what is reflected (`select` only) |
- | `--schema NAME`, `--no-fk`, `--config JSON`, `--sql SELECT` | `select` only |
- ### `studio`
- ```bash
- schemagate # the demo, or your remembered connection
- schemagate studio # empty, connect from the page
- schemagate studio --demo # the bundled sample schema
- schemagate studio --url postgresql://localhost/app
- schemagate studio --remember # save the connection, reconnect next time
- schemagate studio --forget # delete the saved connection and exit
- ```
- | flag | what it does |
- |---|---|
- | `--url URL` | connect at startup instead of from the page |
- | `--host` / `--port` | default `127.0.0.1:8770` |
- | `--no-browser` | do not open a browser |
- | `--demo` | open on the bundled sample schema |
- | `--remember` | save this connection to `~/.schemagate/connection.json` (`0600`) and replay it on the next start. Includes the database and wallet passwords, so it is off unless asked for |
- | `--forget` | delete that file and exit |
- | `--allow-connect` / `--no-connect` | whether the page may open a database itself. On by default on loopback, off when bound anywhere else |
- | `--restrict-from-grants` | derive visibility from GRANTs at startup |
- | `--values` | sample column values while reflecting |
- | `--include` / `--exclude` / `--config` | as for `select` |
- In the page: **Catalogue this database** describes what has no description yet,
- **Re-catalogue all** rewrites every one, and **Resync schema** re-reflects the
- database while keeping the descriptions you already have.
- ### `describe`
- ```bash
- # with a key
- schemagate describe --url postgresql://localhost/app --provider anthropic --model claude-sonnet-5
- # without one: write the prompt out, paste it into any chat, apply the reply
- schemagate describe --url postgresql://localhost/app --out prompt.txt
- schemagate describe --url postgresql://localhost/app --apply reply.json
- ```
- | flag | what it does |
- |---|---|
- | `--out FILE` | write the prompt instead of calling a model |
- | `--apply REPLY.json` | apply a reply produced that way |
- | `--all` | re-describe everything, not only what is missing |
- | `--cache FILE` | where to keep generated descriptions; re-runs are then free |
- | `--provider` / `--model` | which model to use |
- | `--include` / `--exclude` / `--schema` / `--config` | as for `select` |
- ### `certify`
- ```bash
- schemagate certify "postgresql+psycopg://user:pw@host/db"
- ```
- Reflects, selects, and reports what a real engine actually did — the check to
- run before trusting a new database or driver.
- ```bash
- schemagate certify "postgresql+psycopg://user:pw@host/db" --golden --save golden.jsonl
- ```
- `--golden` certifies *your* schema instead of the engine: one question per table
- written from the table's own words (its comment, or its name, and its most
- distinctive columns), one per foreign key, one per view, each with the answer known
- by construction, run through `select()`. Nothing is created and no model is called.
- What it prints that matters is the list of tables not found even by their own
- description, because no question will reach those; the fix is a comment or a hint.
- `--save` writes the set as JSONL (`{"question": ..., "tables": [...]}`) so you can
- edit the questions into real ones and rerun with `--golden golden.jsonl`;
- `--provider ... --model ...` has a model rewrite each question the way a person
- would ask it, which is the harder test. Exit status is 1 when a table is unreachable.
- ### Environment
- | variable | what it does |
- |---|---|
- | `SCHEMAGATE_CONNECT_ARGS` | JSON passed to `create_engine(connect_args=...)`, for connections a URL cannot express (an Autonomous Database wallet) |
- | `SCHEMAGATE_REMEMBER=1` | save the connection without passing `--remember` |
- | `SCHEMAGATE_HOME` | where `connection.json` lives (default `~/.schemagate`) |
- | `ANTHROPIC_API_KEY`, `OPENAI_API_KEY`, `GEMINI_API_KEY` / `GOOGLE_API_KEY`, `OCI_COMPARTMENT_ID` | picked up automatically by `--provider` |
- | `SCHEMAGATE_STUDIO_LOG=1` | log Studio requests |
- | `SCHEMAGATE_STUDIO_ALLOWED_HOSTS` | comma-separated host names the Studio answers to, besides IP addresses and `localhost` (for a Studio reached by a DNS name) |
- | `SCHEMAGATE_VALUES=1` | MCP server: read column values at startup, like `--values` (`SCHEMAGATE_VALUES_BUDGET` = seconds, default 30) |
- | `SCHEMAGATE_RESTRICT_FROM_GRANTS=1` | MCP server: take visibility from the database's GRANTs, like `--restrict-from-grants` (PostgreSQL, MySQL, Oracle) |
- | `SCHEMAGATE_CATALOG_MAX_AGE` | MCP server: seconds a catalogue may be used before it is re-read; if the re-read fails, the scoping tools refuse until one succeeds (see below) |
- | `SCHEMAGATE_REREAD_TIMEOUT` | MCP server: seconds a call waits for that re-read before it is refused as stale (default 30); the re-read keeps running and is served if it returns |
- | `SCHEMAGATE_MCP_RERANK=1` | MCP server: `select_schema` lets the server's model (`SCHEMAGATE_MCP_PROVIDER` + `SCHEMAGATE_MCP_MODEL`) reorder the top 20, like `--rerank`; one model call per question; set without a model, the server will not start |
- ## How it picks
- 1. Reflect the schema through SQLAlchemy. No vendor SQL anywhere.
- 2. Index names, columns, comments, hints, and view definitions. That last one
- matters more than it sounds: a view exposes only its output columns, so
- `v_stock_shortfall` looks like it's about "shortfall" when the thing you'd
- search for, `reorder_point`, is buried in its SELECT.
- 3. Retrieve with reciprocal-rank fusion over BM25 and vector similarity.
- Neither alone is good enough. Vectors miss exact identifiers; BM25 misses
- "owe us money" → `balance`.
- 4. Walk foreign keys to pull in join tables the question never mentions. In my
- experience this is the single biggest cause of generated SQL that parses
- but won't run.
- 5. Apply the caller's identity at every step above.
- ## Numbers
- **On access control, scored by someone else's benchmark.** The RBAC Text-to-SQL benchmark
- (SIGMOD'27) gives each question a role and a column-level policy and scores answering versus
- refusing with its authors' own evaluator. With claude-sonnet-4-5, five trials:
- | | AC-F1 | violations | SQL that read forbidden data |
- |---|---|---|---|
- | BIRD, schemagate | **90.1** | **5.4%** | **0** |
- | BIRD, paper's best (same model, policy in the prompt) | 88.1 | 7.4% | not reported |
- | Spider, schemagate | 93.0 | 5.1% | **0** |
- | Spider, paper with the same model | 93.0 | 4.6% | not reported |
- | Spider, paper's best (DeepSeek V3.2-Reasoning) | 95.9 | 2.0% | not reported |
- The model never sees the restricted part of the schema. Caveats and every column are in
- [BENCHMARKS.md](BENCHMARKS.md#access-control-scored-by-someone-else-the-rbac-text-to-sql-benchmark).
- **And on a second one.** Spider-ACL (EACL 2026) labels each of 19,624 question-and-role pairs with what
- PostgreSQL itself allowed. With claude-sonnet-5-5, all 19,624:
- | | refusal F1 | false permits | queries that read data the role was not granted |
- |---|---|---|---|
- | schemagate | **0.984** | **1.8%** | **0 of 8,128 answered** |
- | paper's best (LoRA-tuned Mistral-7B) | 0.933 | -- | not reported |
- The paper's systems are 2024-25 models; details and limits in
- [BENCHMARKS.md](BENCHMARKS.md#access-control-a-second-benchmark-spider-acl), and both results in one
- [technical report (PDF)](docs/papers/schemagate_access_control.pdf), [DOI 10.5281/zenodo.23446210](https://doi.org/10.5281/zenodo.23446210).
- **On execution accuracy, scored by the benchmarks' own evaluators.** One model
- call per question, about 2,100 prompt tokens, no candidates, no voting, no agent loop:
- | | Model | EX | Best published, 2026-10-19 |
- |---|---|---|---|
- | BIRD dev, all 1,534 questions | Claude Opus 5.5 | **77.12** | hidden test set, scored by BIRD: 72.11 for this setup; 74.34 with 4 training examples per prompt (dev 84.03) |
- | BIRD Mini-Dev, SQLite / PostgreSQL / MySQL | Claude Opus 5.5 | **81.0 / 72.6 / 72.4**, #1 on all three | next best on BIRD's board, 2026-10-31: 75.6 / 69.0 / 49.2 |
- | UniQL, Oracle dialect, first try, re-audited 2026-11-12 release | Gemini 3.8 Flash | **63.69** | 49.61 (Claude Sonnet 4.5, scored before the re-audit) |
- | Spider 2.0-lite, the 135 SQLite questions only | Claude Sonnet 5.5 | **71.9** | 57.78 Pass@1 (FlexSQL agent, gpt-oss-120b) |
- | Spider 2.0-lite, the 205 BigQuery questions | Claude Sonnet 5.5 | **45.9** | no BigQuery-only row published |
- Opus varies about ±1 run to run. The Mini-Dev rows are on BIRD's own leaderboard
- ([PR #251](https://github.com/bird-bench/bird-bench.github.io/pull/251), merged 2026-10-25). Files and commands:
- [`benchmarks/results/`](benchmarks/results/); the context is in
- [BENCHMARKS.md](BENCHMARKS.md#execution-accuracy-scored-by-each-benchmarks-own-evaluator).
- **On public benchmarks, so you can check them without trusting me:**
- [BENCHMARKS.md](BENCHMARKS.md) has schemagate on Spider and BIRD, with the
- scripts in [`benchmarks/`](benchmarks/) and the data downloaded from the
- original sources. The headline is the pooled setting — every Spider database
- merged into one 876-table catalog, no hint about which one to look in:
- | Spider dev, 876 tables pooled | `pip install schemagate` | `[huggingface]` | `[huggingface]` + `--rerank` |
- |---|---|---|---|
- | top_k=5 | 76.7% | 80.3% | **96.5%** |
- | top_k=10 | 86.1% | 90.7% | |
- | top_k=20 | 94.2% | 97.0% | |
- BIRD dev, 1,534 questions: 96.7% per-database at top_k=5, 91.3% pooled at
- top_k=10; pooled at top_k=5, 83.8% hashed, 88.6% with `[huggingface]`, 96.7% with `--rerank`.
- Re-measured on 1.5.2; reranked with claude-haiku-5-5, one call per question.
- And **Spider 2.0-lite**, the benchmark built for real warehouses — 162
- databases, 8,255 tables, a median of 16 per database and a maximum of 785:
- **79.8% at top_k=10** over all 247 usable questions, none excluded (84.5% on
- the 233 whose gold tables resolve), no pooling needed because the databases
- are already big. An earlier version of this page said 82.9%; that number was
- measured while Windows had silently made thousands of the schema files
- unreadable, and a second re-run was owed after the loader was found to be
- reading the benchmark's per-column descriptions as one table description.
- Both re-runs are done and [BENCHMARKS.md](BENCHMARKS.md) keeps the
- corrections rather than deleting them.
- **End to end, on the metric those boards actually score:** schemagate plus
- Claude Opus 5.5 gets **77.12% execution accuracy on all 1,534 BIRD dev
- questions**, one model call per question (table above). The BIRD Mini-Dev
- rows are on BIRD's own leaderboard. A main-board placing needs the held-out
- test set, which only the BIRD team runs: 72.11 execution accuracy for this
- setup, and 74.34 for the second configuration, which adds the four closest
- BIRD training questions to each prompt.
- Everything below is measured on schemas I invented, which is worth less and
- is why the public numbers come first.
- Six test schemas ship with the library. Run `python tests/bench.py` and you
- get all of this printed back. `TESTING.md` is the full record of what was
- tested, what broke, and what was found to be the database rather than schemagate.
- Every number below is printed by that run, and the run fails if any of them
- stops matching — `bench.py` reads this table back and compares.
- **recall@6** here is the share of *gold tables* retrieved in the top six,
- micro-averaged over questions. The **literal** column asks questions that
- reuse the schema's own vocabulary; the **business words** column asks for the
- same things the way a person does, with no vocabulary overlap. Both matter and
- they disagree, which is the point of showing both.
- | schema | objects | recall@6, literal | recall@6, business words |
- |---|---|---|---|
- | commerce | 42 | 100% | 50.0% |
- | clinical claims | 27 | 100% | 46.7% |
- | claims warehouse (star) | 51 | 100% | 58.3% |
- | bank ledger and trading | 39 | 100% | 64.3% |
- | IoT telemetry | 40 | 100% | 60.0% |
- | hostile (4 schemas, copies of everything) | 260 | 100% | 85.7% |
- | | |
- |---|---|
- | real table beats its backup/staging copy, 19 cases across schemas | 19/19 |
- | recall without foreign-key expansion | 100% |
- | prompt tokens, full schema every call | 2,812 |
- | prompt tokens, schemagate average | 757 (−73.1%) |
- Measured with the **hashed embedder** — what `pip install schemagate` gives
- you, no extras. `schemagate[huggingface]` swaps in sentence-transformers and
- the business-word numbers move a long way: on the held-out paraphrase set
- `tests/run_paraphrase_eval.py` reports 58.6% overall hashed and 82.8% with
- MiniLM. That harness counts a question as hit if *any* gold table is
- retrieved, which is a looser predicate than this table's, so its figures are
- not comparable with these — it prints which embedder it used for the same
- reason.
- Token counts come from an estimator built into the benchmark so the number is
- reproducible with no network and no extra install. `pip install tiktoken` and
- the same script switches to exact `cl100k_base` counts. The ratio holds either
- way.
- Six schemas rather than one because a single schema whose questions happen to
- share vocabulary with its own table names will flatter any retriever. The
- second is a different domain entirely. The third is 260 objects of deliberate
- sabotage: an `_archive` and `_stg` copy of every table, the same table name in
- three schemas, an 8-deep foreign-key chain, a reference cycle, composite keys,
- a 320-column table, 100-character identifiers, and names in Spanish and
- Japanese. The fourth is a claims warehouse star schema built so that several
- tables are plausible for every question and one is right: the same fact at
- four grains, a slowly-changing member dimension with a history table, one date
- dimension joined five different ways, bridge tables, and fifteen `_bkp`,
- `_old`, `_v2`, `_tmp` and `stg_` copies of the important ones. The fifth is a
- bank: a ledger at three grains, trades versus positions versus settlements,
- FX both as a daily table and an as-of view, lending, and the KYC and AML
- tables most callers must never see. The sixth is an IoT fleet: readings at
- raw, one-minute and hourly grains, six monthly partition tables, an alarm
- lifecycle spread across three tables. All six are invented. No real schema
- from anywhere is in this repo.
- That 50% row is the honest one. Read it before you adopt this.
- ## The 50% row, and what to do about it
- The default embedder matches subwords, not meaning. Ask it for "things we're
- running out of" and it will not find `v_stock_shortfall`, because those two
- strings have nothing in common. Ask it about `stock_shortfall` and it's
- excellent.
- If your users type identifier-shaped questions, you're done, and you never need
- an API key. If they type like people, give the catalog descriptions. There are
- two ways, and neither is required.
- **With an API key in the environment, you get them without asking.** Every path
- that answers a question — `schemagate select`, `--answer`, the MCP server, the
- Studio's connect — describes the catalogue first, caches the result per
- connection under `~/.schemagate/descriptions/`, and re-describes an object only
- when its structure changes. A hint you wrote, or a database comment that says
- something, is never overwritten; a comment that only restates the object's
- name in the schema's own boilerplate is replaced, because it was diluting
- every word it contained. Measured on a 1,200-object schema, that is the
- difference between six and eight of eight complex questions producing SQL that
- runs. `SCHEMAGATE_AUTO_DESCRIBE=0` turns it off; with no key present nothing
- is called and nothing changes.
- ### Without an API key
- Any chat window you already have — ChatGPT, Gemini, Copilot, a
- local model — can write the descriptions. schemagate gives you the prompt and
- takes the reply:
- ```bash
- schemagate describe --url postgresql://localhost/app --out prompt.txt
- # paste prompt.txt into a chat; save its JSON reply as reply.json
- schemagate describe --url postgresql://localhost/app --apply reply.json --config catalog.json
- schemagate select --url postgresql://localhost/app "things we're running out of" --config catalog.json
- ```
- The prompt is metadata only — names, types, comments, foreign keys, never rows
- — and one paste covers every undescribed object. The reply lands in the
- `describe` block of `catalog.json`, next to your `restrict` and `hint` blocks,
- and `select`, `studio` and the MCP server (`SCHEMAGATE_CATALOG_CONFIG`) all
- read it. From Python it's the same idea: `cat.describe_prompt()` and
- `cat.describe({"v_stock_shortfall": "Items below their reorder level."})`.
- ### With a local model, and no key at all
- ```bash
- pip install 'schemagate[huggingface]'
- schemagate describe --url postgresql://localhost/app --provider local --model Qwen/Qwen2.5-1.5B-Instruct --cache .schemagate-cache.json
- ```
- or, in the Studio, *Settings → Model* → **Local (transformers)**. No key
- field appears, because there is no key.
- ```python
- from schemagate.ai import SchemaDescriber, LocalProvider
- cat.describe(SchemaDescriber(LocalProvider(), cache_path=".schemagate-cache.json"))
- ```
- Writing one sentence per table is a small enough job that a 1.5B model does it
- acceptably. Writing multi-table SQL is not, and the Studio uses the same
- provider for both — so if you have a key, catalogue locally but answer with
- the key. Read [docs/local-models.md](docs/local-models.md) before you turn it
- on: it covers the two downloads, the load you wait through once, the ~3 GB of RAM, the
- caching that makes the second run free, and why a weak model's bad description
- can no longer bury the object it describes.
- ### With your own key
- ```python
- from schemagate.ai import SchemaDescriber, AnthropicProvider
- cat.describe(SchemaDescriber(AnthropicProvider(model="claude-sonnet-4-5"),
- cache_path=".schemagate-cache.json"))
- ```
- One sentence per table, written by the model, indexed like any other schema
- text. On the bundled schema that takes the business-words row from 50% to 100%
- with no change to the identifier-style questions.
- Anthropic, OpenAI and Gemini are supported. Anything else goes through
- `CallableProvider`, which is also your escape hatch when a vendor changes their
- SDK and you don't want to wait for a release from me.
- ```python
- from schemagate.ai import (AnthropicProvider, OpenAIProvider, GeminiProvider,
- CallableProvider, auto_provider, available_providers)
- AnthropicProvider(model="claude-sonnet-4-5") # ANTHROPIC_API_KEY
- OpenAIProvider(model="gpt-4.1-mini") # OPENAI_API_KEY
- GeminiProvider(model="gemini-2.5-flash") # GEMINI_API_KEY
- OpenAIProvider(model="…", base_url="http://localhost:11434/v1") # anything local
- CallableProvider(lambda system, prompt: my_llm(system, prompt))
- available_providers() # ['AnthropicProvider'] — names, never key values
- auto_provider(model="…") # picks whichever key is set
- ```
- `model` is required. I'm not shipping a default model ID, because model IDs
- change every few months and a hardcoded one eventually 404s for everybody who
- installed the version before the fix.
- Three things worth knowing before you turn this on:
- **What leaves your network.** Table names, column names, types, nullability,
- existing comments, foreign keys. Not one row of data — `ObjectDoc` has no field
- that could hold one, and there are tests asserting both halves of that. Nothing
- is sent unless you call `describe()`.
- **What it costs.** One short call per undescribed object, once. Objects that
- already have a database comment or a hint are skipped by default. Results cache
- by content, so re-running is free and only changed tables get re-described. Ask
- before you pay:
- ```python
- describer.estimate_calls(docs) # calls describe() would actually bill for
- describer.preview(doc) # the exact text that would be sent
- ```
- **What happens when it fails.** The object is skipped, cataloging continues, and
- `describer.failures` lists what was missed. Pass `strict=True` if you'd rather
- it raise. A `hint()` you wrote by hand always beats a generated description, so
- fixing a bad one costs nothing.
- ### The embedder picks itself
- `pip install schemagate` uses the hashed n-gram vectoriser: offline, instant,
- byte-identical on every machine. Install `schemagate[huggingface]` and a
- sentence model is used automatically instead -- no flag, no benchmark, no
- decision for you. Measured across the six bundled schemas, 98 questions, no
- descriptions:
- | | recall@6 |
- |---|---|
- | hashed n-gram (base install) | 90/98 |
- | all-MiniLM-L6-v2 (`[huggingface]`) | 93/98 |
- The gain is concentrated exactly where the hashed embedder is documented to be
- weak -- questions phrased the way people speak. On the commerce schema, which
- carries that set, it goes 15/18 to 18/18.
- It is not the base default because that would trade one dependency for torch,
- and the guarantee that the same text gives the same vector everywhere.
- `SCHEMAGATE_AUTO_EMBEDDER=0` keeps the hashed one if you need to reproduce an
- older index.
- You can swap in a hosted embedder too, though on identifier-heavy schema text
- the offline ones are often just as good and cost nothing per query.
- ```python
- from schemagate.ai import APIEmbedder, OpenAIProvider
- provider = OpenAIProvider(model="gpt-4.1-mini",
- embed_model="text-embedding-3-small")
- cat = Catalog(embedder=APIEmbedder(provider, dim=1536))
- ```
- ### Your organisation's words: a glossary
- Some questions share nothing with any identifier, and no description or model
- reliably bridges them: "money we gave back to shoppers" is `billing_credit_note`.
- State it once, in the same `catalog.json` as your access rules:
- ```json
- {"terms": {"gave back": "billing_credit_note",
- "revenue": ["billing_invoice", "v_monthly_revenue"]}}
- ```
- or `cat.term("gave back", "billing_credit_note")` in Python. A term matches as a
- phrase, plurals folded, and only the most specific term counts ("take things
- offline" beats "offline"). It is applied when the question is asked, so nothing
- is re-indexed, and it never widens access: a term for a table the caller may
- not read does nothing for that caller. A term naming an object that does not
- exist is an error, not a silent no-op.
- What it is for, measured on the 58 business-language questions across the six
- bundled schemas (`tests/run_terms_repair.py`): every question that missed was
- fixed by adding **one** short term taken from it, and no other question broke --
- 23 of 23 on the base embedder, 11 of 11 with MiniLM. What it is not: a glossary
- written in advance, from table names alone, barely moved the held-out questions
- (18/26 to 19/26 on the base embedder, 21/26 unchanged with MiniLM;
- `tests/run_terms_eval.py`), because people's words are hard to guess. Add terms
- for the questions you see missing.
- ### The full ontology: concepts, rules, a hierarchy
- A glossary term is the simplest concept. The full form says what a word means,
- precisely, so the model writes the right SQL rather than a plausible one:
- ```json
- {"ontology": {"concepts": {
- "revenue": {"synonyms": ["turnover", "sales"],
- "maps": ["billing_invoice.total_net"],
- "filter": "billing_invoice.status = 'issued'",
- "definition": "Issued invoices only; drafts and void excluded.",
- "broader": ["money in"]},
- "money in": {"maps": ["v_monthly_revenue"]}}}}
- ```
- A question that uses a concept's name or a synonym brings its objects in, and
- its meaning is written above the DDL:
- ```
- -- What the business terms in this question mean:
- -- revenue (also: turnover, sales): main.billing_invoice.total_net; only where billing_invoice.status = 'issued'. ...
- ```
- Concepts one step away (`broader`, or narrower) add a weaker signal. A meaning
- line is left out for any caller who may not see everything it names -- the mapped
- table and column, and any table or column its rule or definition mentions -- so a
- concept never puts a withheld name back into the prompt.
- Where a vocabulary comes from:
- ```bash
- schemagate ontology import semantic_manifest.json --from dbt --url ... --config catalog.json --save
- schemagate ontology import model.yaml --from snowflake --url ... --config catalog.json --save
- schemagate ontology import glossary.csv --from csv --url ... --config catalog.json --save
- schemagate ontology suggest history.jsonl --url ... --config catalog.json # review, then --save
- schemagate ontology check --url ... --config catalog.json
- ```
- `suggest` learns concepts from questions people asked and the SQL that answered
- them (`--memory` reads schemagate's own query memory). CSV headers from Collibra
- and Microsoft Purview exports work as they are.
- **Or pull them from the database, and get the schema as a property graph.** No file
- and no model call: `schemagate ontology pull --url ...` proposes concepts from table
- and column comments, view filters and computed view columns, for you to review.
- `schemagate graph --url ...` writes tables, columns, foreign keys, joins read from
- view SQL and concepts as JSON or GraphML, for one caller, so nothing they may not see
- is in it. `--query-log` adds the joins people's own queries declare, read from the
- engine's statement store with every value stripped first. On Oracle 23ai and later,
- `--format sql` writes `CREATE PROPERTY GRAPH` for you to review and run.
- `schemagate certify <url>` runs a golden set of questions with known answers through
- all of it on your engine. See [docs/property-graph.md](docs/property-graph.md).
- **What it does to accuracy, measured.**
- | | setting | without | with |
- |---|---|---|---|
- | Concepts learned from history (`benchmarks/learn_concepts.py`) | Spider dev, 166 databases pooled (876 tables), learned from half of each database's questions, scored on the other half: all gold tables in the top 5 | 73.3% | **82.8%** (+49 / −0, p<0.0001; MiniLM 79.1% → 85.9%) |
- | A complete glossary (`benchmarks/bird_ontology.py`, arm D) | BIRD dev, 201 held-out questions asked **without** their evidence, execution accuracy, Claude Sonnet 5 | 44.8% | **54.7%** (+28 / −8, p=0.001) |
- | Planted definitions (`benchmarks/planted_definitions.py`) | a seeded SQLite with 8 business terms whose obvious reading is wrong (revenue net of discounts, refunds and internal SKUs; "active" from recent orders, not a stale flag; churn with a 30-day grace), 21 questions with answers computed from the definitions, execution accuracy, Claude Sonnet 5 | 4.8% | 71.4% (+14 / −0, p=0.0001); **100%** once a definition brings the terms it cites (21/21, +6 / −0) |
- For scale on BIRD: pasting each question's own evidence into it (BIRD's usual
- setting) scores 61.2%, so the ontology delivers about 60% of that gain with no
- evidence typed per question; two identical runs without it differ by 18 answers.
- One result did not hold: concepts built from *other* questions' evidence gave
- 46.8% against 44.8% -- inside that noise -- because BIRD's evidence is mostly
- one-off formulas that rarely recur. An ontology helps with the definitions it
- actually holds.
- The planted-definition test (suggested in review) writes the definitions first
- and computes every expected answer from them, so it measures whether the SQL is
- *right*, not whether the tables were. A repeat run without the glossary changed
- no answers. The six questions the glossary first missed were one pattern: a
- term defined through another ("partner sales is revenue on partner orders")
- retrieved itself but not the term it leans on, so the model guessed what
- revenue means -- confidently, on four questions it had declined without the
- glossary. A matched concept now brings the concepts its definition or filter
- cites (`Ontology.with_cited`, followed three steps, visibility applied to each),
- and the same run scores 21/21. Compiling revenue into a view the dependent
- terms point at, with the gross columns still queryable, scored 19/21, and
- neither of its misses involved revenue: the gap was retrieval, not the model
- re-deriving a definition it had been given.
- Join-path completion through the schema graph was measured and not built:
- on Spider only 2 of 266 misses at top_k=5 are a missing bridge table, because
- foreign-key expansion already brings bridges in (`benchmarks/join_paths.py`).
- ## Connecting to what you actually have
- Most people do not have a SQLAlchemy URL. They have a wallet zip, a JDBC
- string out of a config file, or a host and a port. `schemagate.connect`
- turns any of those into the two things SQLAlchemy needs:
- ```python
- from sqlalchemy import create_engine
- from schemagate import Catalog
- from schemagate.connect import resolve
- url, connect_args = resolve("jdbc:oracle:thin:@//host:1521/ORCLPDB1")
- cat = Catalog().bootstrap(create_engine(url, connect_args=connect_args))
- ```
- `connect_args` is not optional. An Autonomous Database has no URL worth the
- name — the wallet directory, the wallet password and the TNS alias have
- nowhere to live in one — so the URL degenerates to `oracle+oracledb://@` and
- the connection travels beside it:
- ```python
- url, connect_args = resolve({
- "kind": "wallet",
- "wallet": "~/Downloads/Wallet_mydb.zip", # the zip as downloaded
- "alias": "mydb_high",
- "user": "ADMIN", "password": "...",
- })
- ```
- The zip is extracted next to itself, because the driver re-reads it on every
- reconnect — a temporary directory gives you a connection that works once.
- Same thing from the Studio, with a dropdown instead of a dict:
- ```bash
- pip install "schemagate[all]" # every driver, the model SDKs, MCP
- schemagate
- ```
- On Oracle Cloud, add the OCI SDK so cataloguing can go through OCI Generative
- AI with no API key at all:
- ```bash
- pip install "schemagate[all,oci]"
- ```
- It is a separate word because it is a separate size: the OCI SDK is 488 MB and
- 17,505 modules, against 217 MB for everything else together.
- | you have | pick |
- |---|---|
- | `postgresql+psycopg://...` | SQLAlchemy URL |
- | `jdbc:oracle:thin:@//host:1521/SVC` | JDBC URL |
- | `Wallet_mydb.zip` + `mydb_high` | Oracle wallet |
- | a host, a port and a database | the engine by name |
- Once connected, the Studio shows the command that reproduces it — the
- `schemagate select ... --url ...` line and the Python equivalent, with the
- password as `$DB_PASSWORD` rather than the real one. Try it in the page, then
- take the command.
- Connecting works out of the box on `localhost`, where the only person who can
- reach the page is already sitting at a shell on that machine. Serve the Studio
- on any other address and it takes `--allow-connect`, because there it becomes
- a URL box anyone on the network can use to make your server connect to hosts
- only it can see. `--no-connect` turns it off anywhere.
- Other web pages open in the same browser can reach `localhost` too, so the
- Studio only takes a request from the page it served: every POST must carry a
- random per-session token that is written into that page, a POST from any other
- origin is refused, and the Studio answers only to an IP address, `localhost`, or
- a name listed in `SCHEMAGATE_STUDIO_ALLOWED_HOSTS`, so a DNS-rebinding page
- cannot load it under its own name. A failed connection reports the
- exception type and nothing else, because driver errors quote the URL they
- were given and a URL carries a password.
- ## Restricting one column, and reading the ACL you already have
- An object-level rule cannot express the common case: the table is the right
- answer and one column in it is not.
- ```python
- from schemagate import Catalog, Principal
- cat = Catalog().bootstrap("postgresql+psycopg://user:pw@host/db")
- cat.restrict_column("employee", "salary", ["payroll"])
- cat.index()
- analyst = Principal("okta:jdoe")
- print(cat.select("who reports to whom", principal=analyst).prompt_fragment())
- ```
- `salary` is **absent** from that fragment — not `REDACTED`, not renamed. The
- name is itself the disclosure: a model that knows the column exists can ask
- about it, join on it, or mention it in an explanation. Any `-- FK` line naming
- a withheld column is dropped too, since it would put the identifier straight
- back.
- ### What was shown, and to whom
- ```python
- sel = cat.select("who reports to whom", principal=analyst)
- sel.to_dict()
- # {'question': 'who reports to whom',
- # 'principal': 'okta:jdoe', 'roles': [], 'total_objects': 219,
- # 'hits': [{'object': 'hr.employee', 'kind': 'TABLE', 'score': 0.031,
- # 'reason': 'hybrid', 'columns_shown': 3, 'columns_withheld': 1}]}
- ```
- The record an auditor asks for after the fact, and the one thing that cannot
- be reconstructed later — the catalog will have changed, roles will have
- changed, and the question is gone. It carries the **count** of withheld
- columns, never their names: a log that lists what it withheld has disclosed it
- to everyone who can read the log.
- ### Deriving visibility from GRANTs
- At forty tables a hand-written `restrict` map is fine. At four hundred it is a
- second copy of an ACL that already exists in the database, and two copies
- drift.
- ```bash
- schemagate select "what do we pay our doctors" \
- --url "postgresql+psycopg://user:pw@host/db" --restrict-from-grants
- ```
- ```python
- from schemagate.grants import restrict_from_grants
- report = restrict_from_grants(cat, engine, report=True)
- # then the half grants cannot see: objects under a row-level policy are
- # flagged in the prompt, probed per role on PostgreSQL, and the views that
- # bypass the policy are named -- docs/row-level-security.md
- from schemagate.rls import restrict_from_policies
- print(restrict_from_policies(cat, engine, report=True))
- print(report)
- # postgresql: 629 object(s) seen, 218 restricted, 1 public, 0 unmatched, 1 role(s) expanded
- ```
- PostgreSQL and Oracle. Nested roles are flattened transitively, so a user
- whose group maps to a role that inherits the granted one still reaches the
- object. An object with no grant row is **left untouched** and named in
- `report.objects_unmatched` — silence is not a denial, and restricting on
- absence would break a working catalog the first time a connection could not
- see everything.
- **It reads grants, so it does not see row-level policies.** Measured on Oracle
- 26ai: a caller whose Virtual Private Database policy admits zero rows still
- holds `SELECT` in `ALL_TAB_PRIVS`, still appears in `ALL_TABLES`, and is still
- put in front of the model with every column. Nothing leaks -- the database
- enforces the policy -- but the prompt names a table that caller cannot get a
- row out of. [docs/row-level-security.md](docs/row-level-security.md) has the
- measurement, what to do about it today, and the fix.
- ### Where the caller's roles come from
- Grants answer which roles may see an object. The other half — which roles
- *this caller* holds — used to be whatever the caller said, which is fine for
- a desktop client on its own database and no check at all for a hosted
- server. A `groups` block in the catalog config reads it from where it is
- already kept, and the roles a client sends are then **ignored**:
- ```json
- {"groups": {"sources": [
- {"type": "entra", "tenant": "contoso.onmicrosoft.com",
- "client_id": "…", "client_secret": "${ENTRA_CLIENT_SECRET}"},
- {"type": "native"}],
- "map": {"Payroll Team": "payroll"}}}
- ```
- Five sources: **`entra`** (Microsoft Entra ID through Graph, transitive
- group membership, ids and display names both), **`native`** (the database's
- own role graph — the same views `restrict_from_grants` reads, walked upward
- from the user, so a two-level `GRANT` chain resolves), **`sql`** (a
- membership table, one bound `:subject`), **`http`** (any endpoint returning
- groups as JSON), **`static`** (a mapping in the file). Each answers only for
- the subject namespaces it serves; results are a union; a `map` turns group
- ids into role names. Answers are cached for `ttl` seconds.
- A source that cannot answer is an error to that caller, not an anonymous
- selection: "no groups" and "could not ask" are different answers and only
- one is safe to act on. Verified live on PostgreSQL 16, MySQL 8.4 and Oracle
- Autonomous Database 26ai: the resolver and the grants-restricted catalog
- agree with `has_table_privilege` and with an actual `SELECT`.
- [docs/groups.md](docs/groups.md) has the block, every source, and what was
- tested.
- ## Databases
- Reflection uses only SQLAlchemy's dialect-agnostic Inspector. There's no
- hand-written SQL in `schemagate.introspect` and a test fails the build if any
- appears, so in principle any dialect SQLAlchemy supports will work.
- In principle isn't evidence, so there's a script:
- ```bash
- python scripts/certify_dialect.py 'postgresql+psycopg://user:pw@host/db'
- python scripts/certify_dialect.py 'oracle+oracledb://user:pw@host:1521/?service_name=FREEPDB1'
- python scripts/certify_dialect.py 'mssql+pyodbc://user:pw@host/db?driver=ODBC+Driver+18+for+SQL+Server'
- python scripts/certify_dialect.py 'mysql+pymysql://user:pw@host/db'
- ```
- It creates three `schemagate_cert_` tables, reflects them, runs selection and
- identity scoping end to end, drops them again, and exits non-zero if anything
- failed. Point it at a scratch schema.
- | | |
- |---|---|
- | SQLite | certified, 10/10, in CI |
- | PostgreSQL | certified, 10/10 on PostgreSQL 16, plus the full 260-object suite |
- | Oracle | certified live on Oracle AI Database 26ai (Autonomous Database), Sep 2026: certify script 10/10, the native `VECTOR(512, FLOAT32)` store conformance suite, and the dialect suite. Also stress-tested against a 127-object, 3-domain schema with ~7M rows |
- | SQL Server | certified live on SQL Server 2022 (16.0.4295.3), 10/10, **in CI on every push** against a service container, plus 13 live dialect tests covering alias types, `hierarchyid`/`sql_variant`, and `max_length` being bytes |
- | MySQL / MariaDB | certified live on MySQL 8.4.11, 10/10, **in CI on every push** against a service container, plus the GRANT reader suite: all three privilege levels, the role graph, and the role-only blind spot MySQL cannot report. MariaDB has not been run |
- | DuckDB | 9/10 locally, Oct 2026, on DuckDB 2.0.0 through `duckdb-engine` 0.17.0 (`pip install duckdb-engine`, URL `duckdb:///path/to/file.duckdb`). Tables, columns, foreign keys, selection and identity scoping pass; primary keys are not reported by the driver. Needs SQLAlchemy 2.0.44 or older: from 2.0.45, `duckdb-engine` cannot reflect columns at all ([duckdb_engine#1379](https://github.com/Mause/duckdb_engine/issues/1379)). Not in CI |
- Every row above has a real database behind it. The one thing still worth
- saying plainly: MariaDB is inferred from MySQL rather than run. Point the
- script at one and tell me what happens. DuckDB has no `SERIAL` type, so its
- run created the three test tables with `autoincrement=False` on their keys
- (the suite inserts no rows).
- The same checks run under pytest if you export a URL, which is how CI certifies
- a dialect for good:
- ```bash
- export SCHEMAGATE_POSTGRES_URL='postgresql+psycopg://…'
- export SCHEMAGATE_ORACLE_URL='oracle+oracledb://…'
- export SCHEMAGATE_MSSQL_URL='mssql+pyodbc://…'
- export SCHEMAGATE_MYSQL_URL='mysql+pymysql://…'
- pytest tests/test_dialects.py -v
- ```
- ## Using it from an agent
- > **The MCP server trusts the identity it is handed.** `principal` and `roles`
- > come from the client and are not authenticated -- there is no token and no
- > session. Anyone who can reach the transport can claim a role and read what
- > that role may read, and since `run_query` returns rows, that is data, not
- > just schema. Run it over stdio (the caller is your own desktop client), or
- > over HTTP behind something that authenticates the user and sets the
- > principal for them. It is a scoping mechanism, not a lock. With a
- > `groups` block in `SCHEMAGATE_CATALOG_CONFIG` the *roles* stop being the
- > client's to claim — they come from the directory or the database and the
- > ones in the request are ignored ([docs/groups.md](docs/groups.md)); the
- > subject is still whatever the transport hands over.
- >
- > **Or turn on OAuth and it is a lock.** Set `SCHEMAGATE_MCP_OAUTH_ISSUER`
- > and `SCHEMAGATE_MCP_OAUTH_AUDIENCE`, and over HTTP every request needs a
- > token signed by your identity provider (Entra ID, Okta, Auth0, Keycloak).
- > Who is asking and which roles they hold come from that token, never from
- > the client. No gateway needed ([docs/oauth.md](docs/oauth.md)).
- If you already have an agent that writes SQL, the fastest way in is to let it
- call schemagate as a tool rather than wiring the library into your code.
- **MCP.** Cursor, Windsurf, Zed, or anything else that speaks the
- Model Context Protocol:
- <!-- mcp-name: io.github.ashishsinha1602/schemagate -->
- One line, nothing to install first (needs [uv](https://docs.astral.sh/uv/)); `demo` is a
- bundled sample schema, so this works before you point it at anything:
- ```bash
- uvx --from "schemagate[mcp]" schemagate-mcp --url demo
- ```
- Claude Code:
- ```bash
- claude mcp add schemagate -- uvx --from "schemagate[mcp]" schemagate-mcp --url demo
- ```
- Any other client (Claude Desktop, Cursor, Windsurf, Zed), with your database. Add
- your database's driver extra next to `mcp`: `postgres`, `mysql`, `mssql` or `oracle`
- (SQLite needs none):
- ```json
- {"mcpServers": {"schemagate": {
- "command": "uvx", "args": ["--from", "schemagate[mcp,postgres]", "schemagate-mcp"],
- "env": {"SCHEMAGATE_DATABASE_URL": "postgresql+psycopg://user:password@localhost/app"}}}}
- ```
- Keep a URL with a password in `env`, as above, not in `--url`: command arguments are
- visible to every process on the machine. Without uv: `pip install 'schemagate[mcp,postgres]'`,
- then run `schemagate-mcp` (or `python -m schemagate.mcp_server`, which still works).
- Nine tools, all read-only: `select_schema` (the DDL for a question, scoped to
- the caller), `list_objects` (what this caller can see), `describe_object` (one
- object's full DDL), `run_query` (runs a single read, refused if it names
- anything the caller may not see), `semantic_query` (a read whose rows the
- server's model then filters or annotates by what a text column says),
- `answer`, `deep_answer` (like `answer`, but may explore in steps),
- `refresh_catalog` and `health`.
- They take `principal` and `roles`. If the client leaves them out, the caller
- is anonymous and sees only unrestricted objects. A restricted object and a
- missing one return the same error, so existence doesn't leak.
- **Every decision is recorded.** Each call to those tools, and to `run_query`
- and `answer`, writes one line: when, which principal with which roles, what
- they asked, what they were shown, how many objects and columns were held
- back, what SQL ran and how many rows came back, and whether the call was
- refused and why. Never row data, never the names of what was withheld, never
- the database URL. It stays in memory (the last 500, counted in `health`)
- unless `SCHEMAGATE_AUDIT_LOG=<path>` — or `=1` for `~/.schemagate/audit.jsonl`
- — turns the file on; a tool whose pitch is that it stores nothing does not
- start writing files on its own. The log is for the operator, from the file;
- it is deliberately not a tool, because "recent decisions" handed to any
- client is every caller's questions handed to every other caller.
- **And the record can be proven, years later.** Turn on signing and every
- record is chained to the one before it and signed with **ML-DSA-65, the NIST
- post-quantum signature standard (FIPS 204)**: editing a record, deleting one,
- inserting one or reordering them is caught by `schemagate audit verify`, which
- names the line and the reason. Post-quantum because audit logs are kept for
- years, long enough that today's RSA and ECDSA signatures may be forgeable by
- then. It answers the auditor's question "can you prove the model was never
- shown the salary table for this user?" with a check anyone holding the public
- key can run.
- ```bash
- pip install "schemagate[pq]" # PyCA cryptography >= 48 (OpenSSL)
- schemagate audit keygen --out ./keys # private key stays with the server
- SCHEMAGATE_AUDIT_LOG=1 SCHEMAGATE_AUDIT_SIGNING_KEY=./keys/audit-signing-key.pem \
- python -m schemagate.mcp_server
- schemagate audit verify ~/.schemagate/audit.jsonl --public-key ./keys/audit-signing-key.pub.pem
- # OK 1204 signed records (ML-DSA-65), seq 0..1203, no edits, gaps or reordering
- schemagate audit head ~/.schemagate/audit.jsonl # keep this SEQ:HASH elsewhere
- ```
- What it does not claim: someone who can write the file can still delete the
- *newest* records, because a shorter chain is still a valid chain. Keep the
- `head` somewhere else (a ticket, another system) and `verify --head SEQ:HASH`
- fails if the log no longer reaches it. Signing does not encrypt: the log is as
- readable as before, and still holds no rows and no names of what was withheld.
- It proves what schemagate decided, which is only as right as the roles it was
- given. One server process writes one log; a configured key that cannot be
- loaded stops the server at start-up rather than writing unsigned evidence.
- **It learns from SQL that ran.** When `answer` produces a query that
- executes, the question and the query are remembered -- never the rows. The
- next similar question gets the tables that query read pinned into its
- selection, and the pair shown to the model as a worked example between the
- DDL and the question. Neither can widen what a caller sees: a pin goes
- through the same visibility gate as any pin, and an example is shown only
- when every table it names is visible to that caller. Every stored query is
- re-checked read-only on the way in and the way out. Memory-only unless
- `SCHEMAGATE_MEMORY=<path>` (or `=1` for `~/.schemagate/memory/<db>.jsonl`);
- with nothing remembered the prompt is byte-identical to the one before this
- existed. The CLI has `--memory`, the Studio uses it at connect. Similarity is
- the catalog's own embedder -- deterministic, offline, and a weak notion of
- "similar": it matches wording, not meaning, which is acceptable because the
- examples are advisory and the pins are gated.
- `SCHEMAGATE_DATABASE_URL=demo` serves the bundled schema.
- `SCHEMAGATE_VALUES=1` is the server's `--values`: it reads the distinct values of
- short, non-personal columns at startup so the model writes `'CARD'`, not `'Card'`.
- It reads rows, so it stays off unless set; `SCHEMAGATE_VALUES_BUDGET` caps it in
- seconds (default 30 -- raise it for a large schema behind a wallet).
- To host it for a team rather than one desktop:
- ```bash
- SCHEMAGATE_MCP_TRANSPORT=streamable-http SCHEMAGATE_MCP_PORT=8765 python -m schemagate.mcp_server
- ```
- and put your identity provider in front of it, so each person's own token
- decides what they see:
- ```bash
- SCHEMAGATE_MCP_OAUTH_ISSUER=https://login.microsoftonline.com/<tenant>/v2.0 \
- SCHEMAGATE_MCP_OAUTH_AUDIENCE=api://schemagate \
- SCHEMAGATE_MCP_OAUTH_RESOURCE=https://schemagate.example.com/mcp \
- SCHEMAGATE_MCP_TRANSPORT=streamable-http SCHEMAGATE_MCP_HOST=0.0.0.0 python -m schemagate.mcp_server
- ```
- It's built not to die. The index lives in memory after startup, so the
- database going away does not take the server with it — `select_schema` keeps
- answering from the last good reflection, and `refresh_catalog` reports the
- failure instead of raising.
- **How old may the permissions be?** The server reads them when it builds its
- catalogue: restrictions from the config file and, with
- `SCHEMAGATE_RESTRICT_FROM_GRANTS=1`, the database's own GRANTs. By default that
- catalogue is used until `refresh_catalog` is called, so a REVOKE in the
- database reaches the server only then. Set `SCHEMAGATE_CATALOG_MAX_AGE=300` and
- a catalogue older than five minutes is re-read before it is used: a GRANT or a
- REVOKE takes effect **within** that window, not on the next call. If the
- re-read fails, the server does not keep answering from the old permissions:
- `select_schema`, `list_objects`, `describe_object`, `run_query` and `answer`
- refuse with "permissions are stale" until a re-read succeeds (retried at most
- every 5 seconds), and `health` shows `catalog_stale` and the reason. A re-read
- that neither fails nor returns, a database that took the connection and went
- quiet, is bounded too: callers wait at most `SCHEMAGATE_REREAD_TIMEOUT` seconds
- (default 30) and are then refused the same way, while the re-read runs on; if it
- returns, the next call is served from what it brought. Because callers are
- bounded, their latency won't show a re-read that never finishes; `health` does,
- in `reread_running_seconds`, which you can alert on. Caller
- roles from a `groups` resolver have their own bound, its `ttl`. Every tool catches everything and returns
- `{"error": ...}`; a bad request cannot end the session for other clients.
- `health` tells a load balancer what state it's in. A test throws 125 kinds of
- garbage at every tool and then checks the next good request still works, and
- another does the same through a real client over stdio. Works on MCP SDK 1.x
- and 2.x; the 2.0 rename broke a fresh install once and there's a shim and a
- test for it now.
- **LangChain.** A proper `BaseRetriever`, so it composes:
- ```bash
- pip install 'schemagate[langchain]'
- ```
- ```python
- from schemagate.integrations.langchain import SchemagateRetriever, prompt_fragment
- retriever = SchemagateRetriever(catalog=cat, top_k=6,
- principal=Principal("okta:jdoe", roles={"finance"}))
- chain = retriever | RunnableLambda(prompt_fragment) | your_sql_prompt | llm
- ```
- The principal is bound at construction on purpose. Build one retriever per
- caller; a chain can't forget to pass identity if the retriever already has it.
- **LlamaIndex.** The same retriever as a LlamaIndex `BaseRetriever`:
- ```bash
- pip install 'schemagate[llamaindex]'
- ```
- ```python
- from schemagate.integrations.llamaindex import SchemagateRetriever, prompt_fragment
- retriever = SchemagateRetriever(cat, top_k=6, principal=Principal("okta:jdoe", roles={"finance"}))
- ddl = prompt_fragment(retriever.retrieve("revenue by month"))
- ```
- See [docs/llamaindex.md](docs/llamaindex.md).
- **Pydantic AI.** A capability that gives the agent one tool, `select_schema(question)`. The tool takes a question and
- nothing else, so the model can't choose who it's asking as:
- ```bash
- pip install 'schemagate[pydantic-ai]'
- ```
- ```python
- from schemagate.integrations.pydantic_ai import SchemagateCapability
- agent = Agent("anthropic:claude-haiku-4-5", capabilities=[
- SchemagateCapability(cat, principal=lambda ctx: ctx.deps.user)])
- ```
- See [docs/pydantic-ai.md](docs/pydantic-ai.md).
- **jev4pg.** `schemagate.integrations.jev4pg.ScopedCatalog` wraps
- [jev4pg](https://github.com/Sheltercosmo/jev4pg)'s per-tenant catalogue so its
- planner, SQL validator and semantic operators see only what each caller may
- read. See [docs/jev4pg.md](docs/jev4pg.md).
- **Questions about what text says.** `semantic_query` (MCP, off by default) runs
- your SQL under the same scope check, then asks the model which rows' text meets
- a criterion, or for one short answer per row. See
- [docs/semantic-operators.md](docs/semantic-operators.md).
- **Looking at the data before answering.** `deep_answer` (MCP, off by default)
- lets the model run small exploring reads, for example to find that the column
- says `Praha`, not `Prague`, before it writes the final query. Every step goes
- through the same scope check and audit as `run_query`. In the default
- adaptive mode it explores only when the plain query fails, comes back empty
- or returns only zeros. On 220 BIRD questions with Gemini 2.5 Flash, plain
- scored 36.8 and adaptive 54.5. See [docs/deep-answer.md](docs/deep-answer.md).
- **Business rules.** "Fiscal year starts 1 July", "leave out the test tenant":
- knowledge the schema doesn't carry. Write it in a Markdown file or in Studio's
- *Business rules* box. Each rule can be tied to tables and kept from roles, and
- only the relevant ones reach the prompt. See
- [docs/business-rules.md](docs/business-rules.md).
- ## On Oracle Cloud
- Certified live on Oracle AI Database 26ai. Two ways in, neither of which needs
- an API key — cataloguing runs on OCI Generative AI under your own OCI identity,
- so the prompts (schema metadata only, never rows) stay in your tenancy.
- **From Cloud Shell, about a minute, no VM:**
- ```bash
- pip install --user 'schemagate[oracle,oci]'
- schemagate describe --url 'oracle+oracledb://@' --provider oci \
- --model google.gemini-2.5-pro --config catalog.json
- ```
- **Or one click, for an MCP endpoint that stays up for your team:**
- [](https://cloud.oracle.com/resourcemanager/stacks/create?zipUrl=https://github.com/ashishsinha1602/schemagate/releases/latest/download/schemagate-oci-stack.zip)
- That opens Resource Manager in your own tenancy with the stack loaded — an
- Always-Free-eligible VM running the MCP server against an Autonomous Database
- it creates, or one you already have. Details and the Terraform: [`oci/`](oci/).
- ### OCI Generative AI from your own machine
- Everything runs under your OCI identity and is billed to your tenancy. Nothing
- is installed in the database — no Select AI profile, no grants beyond `SELECT`.
- ```bash
- pip install 'schemagate[oracle,oci,mcp]'
- ```
- On Windows the OCI SDK has very long file paths: install into a short path
- (`python -m venv C:\sg`) or enable long paths, or pip fails part-way.
- **Sign-in** is the usual OCI one: `~/.oci/config` from an API key (Console ›
- Profile › API keys), or a resource / instance principal when running inside OCI.
- **Permission** is one policy, for your group — no dynamic group, nothing on the
- database:
- ```
- allow group <your-group> to use generative-ai-family in compartment <compartment>
- ```
- | variable | |
- |---|---|
- | `OCI_COMPARTMENT_ID` | turns OCI Generative AI on (it is the provider picked when no other key is set) |
- | `OCI_REGION` | the Generative AI region, e.g. `us-chicago-1`, `us-phoenix-1` |
- | `SCHEMAGATE_DESCRIBE_MODEL` | the model for automatic descriptions. **Required for OCI** — there is no default, because model ids differ by region |
- **Pick a model your region serves on demand.** The catalogue in a region lists
- models that are dedicated-cluster only; calling one fails with
- `404 Entity with key <model> not found`. Choose another (in `us-phoenix-1`,
- September 2026, `google.gemini-2.5-flash` was on demand; several listed Llama
- and Cohere models were not). The MCP server still starts when the model is
- wrong — it skips the descriptions — so check its log.
- **An MCP server on an Autonomous Database**, with values and descriptions:
- ```json
- {"mcpServers": {"schemagate": {
- "command": "python", "args": ["-m", "schemagate.mcp_server"],
- "env": {
- "SCHEMAGATE_DATABASE_URL": "oracle+oracledb://@",
- "SCHEMAGATE_CONNECT_ARGS": "{\"config_dir\": \"C:/wallet\", \"wallet_location\": \"C:/wallet\", \"wallet_password\": \"...\", \"user\": \"APP\", \"password\": \"...\", \"dsn\": \"mydb_high\"}",
- "SCHEMAGATE_VALUES": "1",
- "SCHEMAGATE_VALUES_BUDGET": "120",
- "OCI_COMPARTMENT_ID": "ocid1.compartment.oc1..…",
- "OCI_REGION": "us-phoenix-1",
- "SCHEMAGATE_DESCRIBE_MODEL": "google.gemini-2.5-flash"
- }}}}
- ```
- `SCHEMAGATE_VALUES_BUDGET` is seconds; the default 30 can cut value reading short
- on a large schema behind a wallet. Oracle-maintained schemas — including the
- `SH` and `SSB` samples every Autonomous Database ships — are left out, so the
- catalog is the schemas you own or were granted. From the CLI, `--answer
- --provider oci --model <id>` writes the SQL with the same model and runs it
- read-only over the same connection.
- ## Keeping the index in Oracle
- `MemoryStore` rebuilds on every process start. Fine for a few hundred objects,
- wrong for a long-lived service. `OracleStore` keeps vectors in Oracle 23ai's
- native `VECTOR` type so the nearest-neighbour search runs in the database:
- ```python
- from schemagate.stores.oracle import OracleStore
- store = OracleStore(dsn="user/pw@host:1521/FREEPDB1", dim=512)
- store.create_schema() # idempotent
- cat = Catalog(store=store).bootstrap("oracle+oracledb://…")
- ```
- Pass `connection=` instead of `dsn=` to reuse your app's pool. It won't close a
- connection it didn't open.
- Scoping is a predicate inside the scored subquery, not a filter applied after
- the rows come back. A row the caller can't see is never ranked and never leaves
- the database.
- Same caveat as above: 26 tests pin the SQL, the bind types and the scope
- predicate, and every statement is checked against an independent Oracle parser,
- but none of it has run against a live 23ai instance yet. To do that:
- ```bash
- export SCHEMAGATE_ORACLE_DSN='user/password@host:1521/FREEPDB1'
- pytest tests/test_store_conformance.py -v
- ```
- Oracle Cloud's Always Free ATP is enough.
- ## Things that will bite you
- **Archive and staging twins are handled, but know how.** If your warehouse has
- `orders`, `orders_bkp` and `stg_orders`, the copies carry the same name words in
- a shorter document, and cosine similarity likes short documents. Left alone,
- a three-column `_tmp` copy beats the twenty-five-column table it was copied
- from, even with a hint on the real one — I watched it happen. So an object
- whose name is a real object's name plus `_bkp`, `_old`, `_tmp`, `_v2`,
- `_archive` and so on, or `stg_`/`tmp_` in front, is ranked below the object it
- shadows. Only when that object exists: a lone `pricing_v2` with no `pricing`
- is left alone. Only in the same schema. And never when you name the copy
- outright — asking for `fact_claim_line_v2` gets you `fact_claim_line_v2`. The
- lists are `DEFAULT_SHADOW_SUFFIXES` and `DEFAULT_SHADOW_PREFIXES`; pass your
- own to `Catalog(...)`, or empty tuples to switch it off. `cat.shadows()` shows
- what was detected.
- **Identifier length.** PostgreSQL truncates names to 63 bytes at creation.
- That's the database doing it, not schemagate, and there's nothing to be done from
- this side.
- **Non-English schemas** work, including Chinese, Japanese and Korean, and
- accents fold both ways so a search for `facturacion` finds `facturación`. But a
- question in English will not find a table named in Spanish. Nothing lexical can
- bridge that. Descriptions can.
- **`top_k` is not a hard cap.** Foreign-key expansion runs after selection and
- adds join tables on top. That's deliberate — SQL that references a table you
- didn't include won't run — but size your prompt budget for it.
- ## Status
- v1.0. The public API is stable.
- The names this README documents -- `Catalog` and its methods, `Principal`,
- `Selection`, the `schemagate` CLI and its flags, the MCP tool names, the
- catalog config file and the LangChain retriever -- keep working without a
- breaking change until 2.0. Anything underscore-prefixed is internal and may
- move in any release.
- Two things are deliberately not covered by that promise. The rows below marked
- unfinished, until they say done. And the *ranking*: retrieval is tuned release
- to release, so the set of tables a question returns can change between 1.x
- versions. What does not change is the part that matters -- a table the caller
- may not read is never in it.
- | | |
- |---|---|
- | Reflection | certified on SQLite, PostgreSQL 16, Oracle 26ai, MySQL 8.4 and SQL Server 2022 |
- | `MemoryStore` | done |
- | AI cataloging | done, tested offline against fake providers |
- | CLI | done |
- | Studio (`schemagate studio`, and the hosted demo) | done, driven by a real browser in tests |
- | MCP server | done, tested through a real MCP client |
- | LangChain retriever | done, tested against langchain-core |
- | LlamaIndex retriever | done, tested against llama-index-core |
- | Pydantic AI capability | done, tested against pydantic-ai-slim |
- | `OracleStore` | written and statically verified, needs a live run |
- | pgvector store | not started |
- `import schemagate` never imports any provider SDK, and there's a test asserting it.
- Default embeddings are stable across processes, machines and Python versions,
- so cached or persisted vectors stay valid. That one is enforced by a test that
- runs the embedder in fresh subprocesses under different `PYTHONHASHSEED`
- values, because it was broken once and nothing else caught it.
- Apache-2.0. Ashish Sinha.
- Patent pending: US provisional application 64/183,987, filed 25 October 2026. Use of this code is
- licensed under Apache-2.0, including the patent licence in its section 3.
Ratings and comments
Sign in to rate this skill.
Sign inFree to use. If it’s helped, pass it on.